
Tencent, released 2026-04-23. Sparse MoE decoder, 295B total, 21B active, 256K context. Attention: GQA with QK-Norm.
Rare production-model release that shows an older MoE style with fewer, larger experts.
Key detail
Adds an always-on SwiGLU path that effectively behaves like a shared expert.Parameters
270B
Context
128K
KV / token
256 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
Use the ← and → keys to step through releases.
Tencent, released 2026-04-23. Sparse MoE decoder, 295B total, 21B active, 256K context. Attention: GQA with QK-Norm.
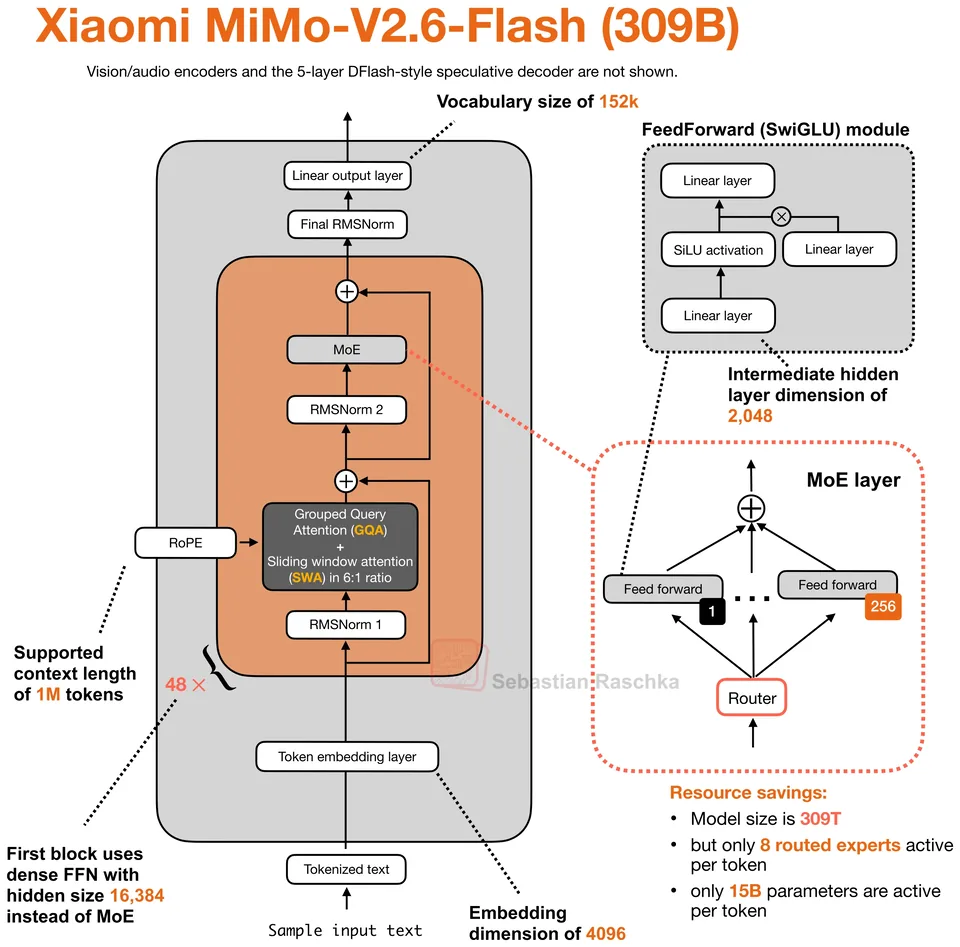
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
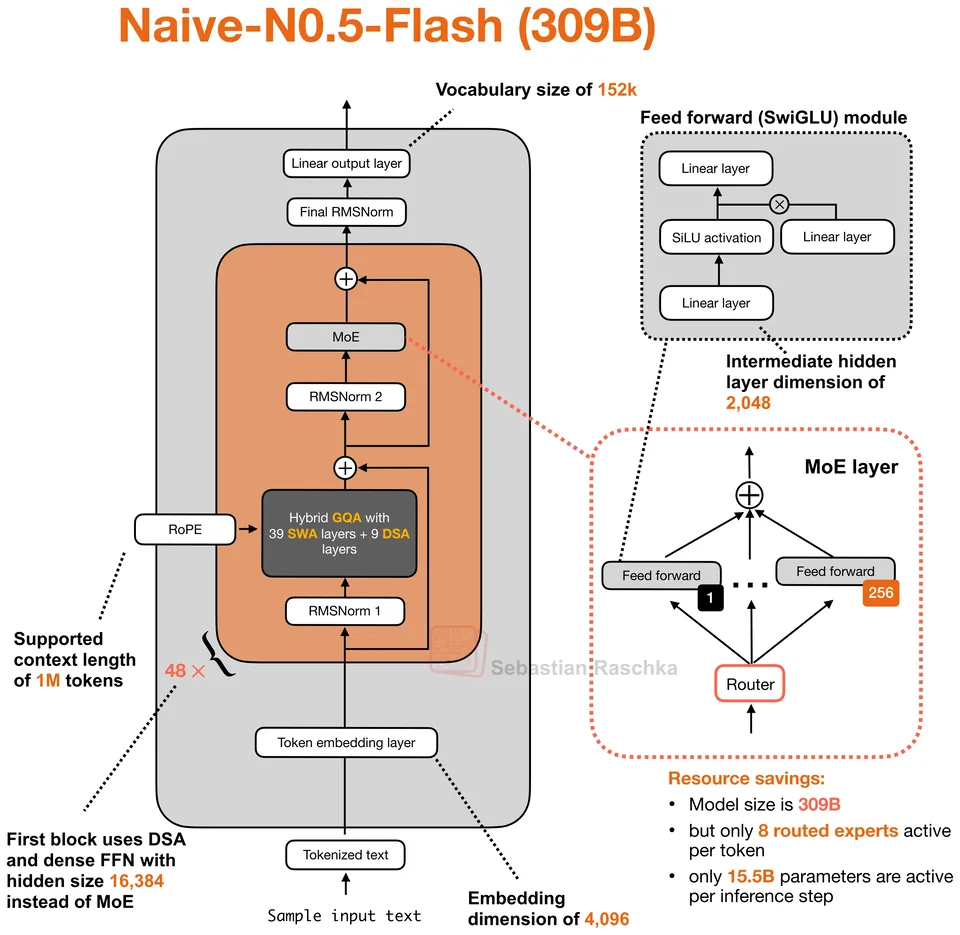
NaiveAI, released 2026-09-27. Sparse MoE decoder, 309B total, 16B active, 1M context. Attention: GQA with sliding-window attention and DeepSeek Sparse Attention.
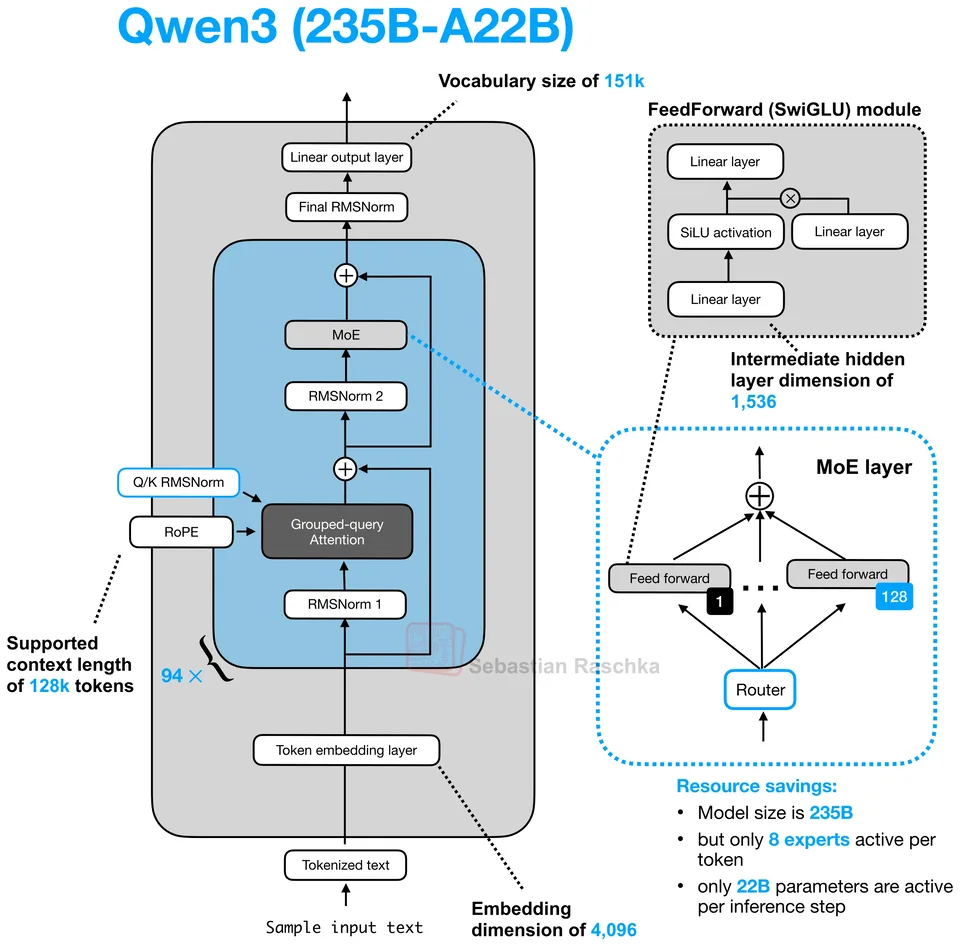
Alibaba Cloud, released 2025-04-28. Sparse MoE decoder, 235B total, 22B active, 128K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page