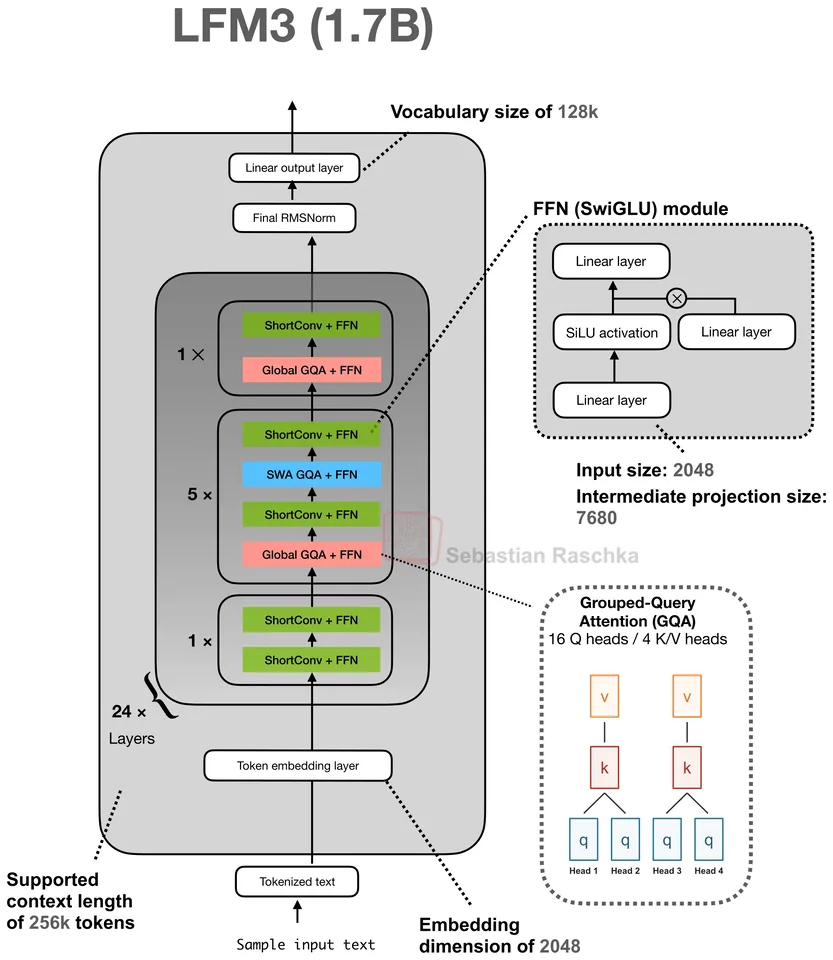
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
Attention · GQA
Several query heads share one key/value head, shrinking the KV cache with little quality loss.
GQA keeps many query heads but groups them so each group reads from a single shared key/value head. With 32 query heads and 8 KV heads, the cache is four times smaller than MHA.
Multi-query attention (MQA) is the extreme case with one KV head for everyone; GQA sits between MQA and MHA and became the default for dense open models from Llama 2 onwards.
It is simple to implement, plays well with existing kernels, and is often combined with sliding-window layers for further savings.
Models in the atlas using GQA, per half-year of release.
Often paired with
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
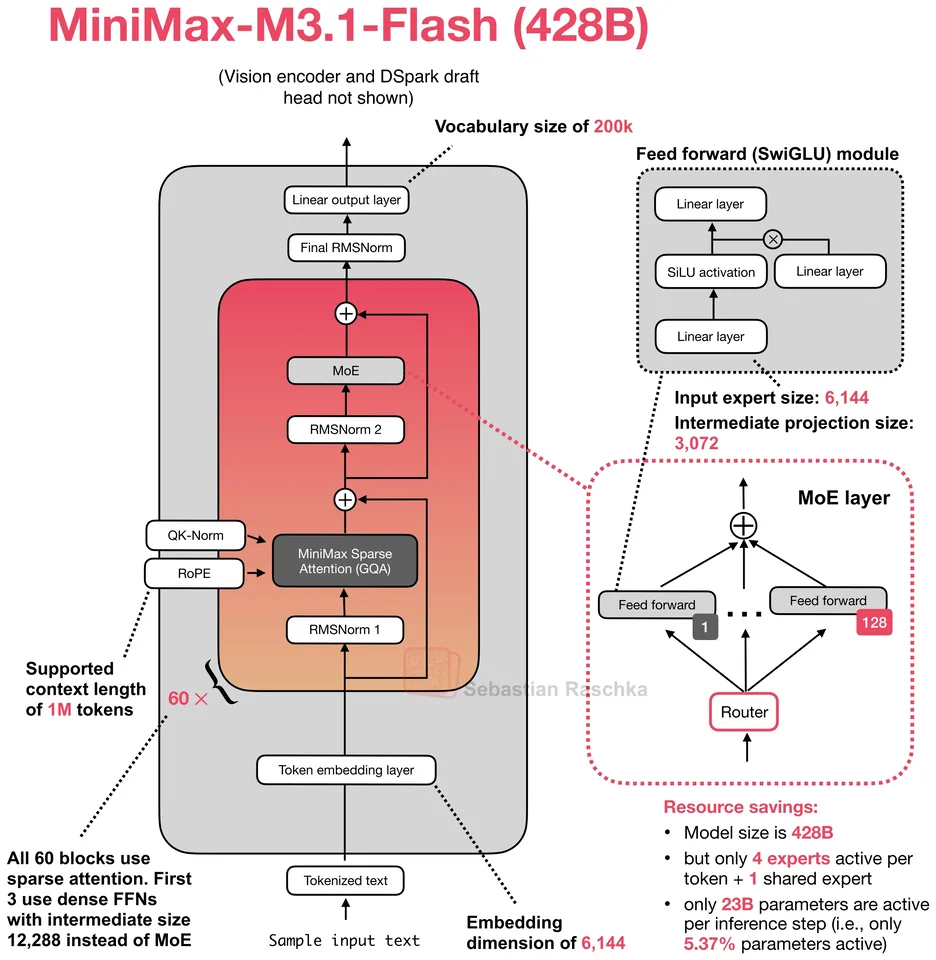
MiniMax, released 2026-10-19. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.
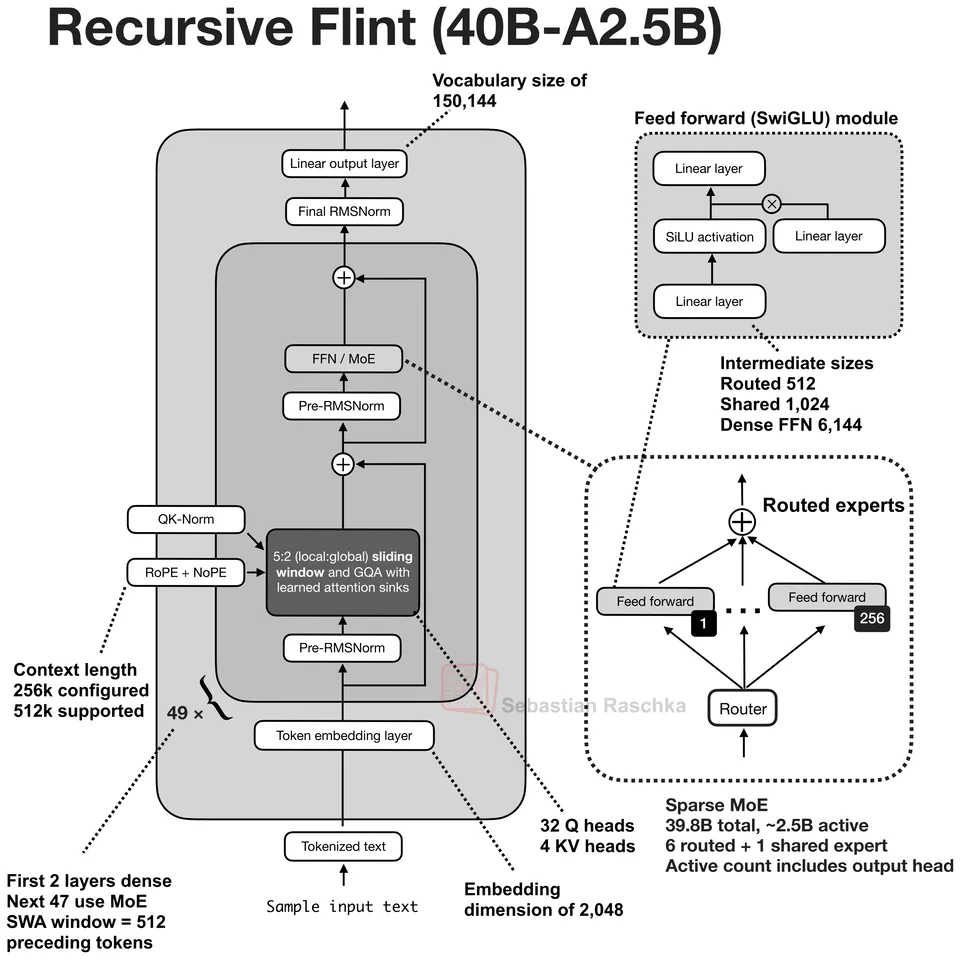
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
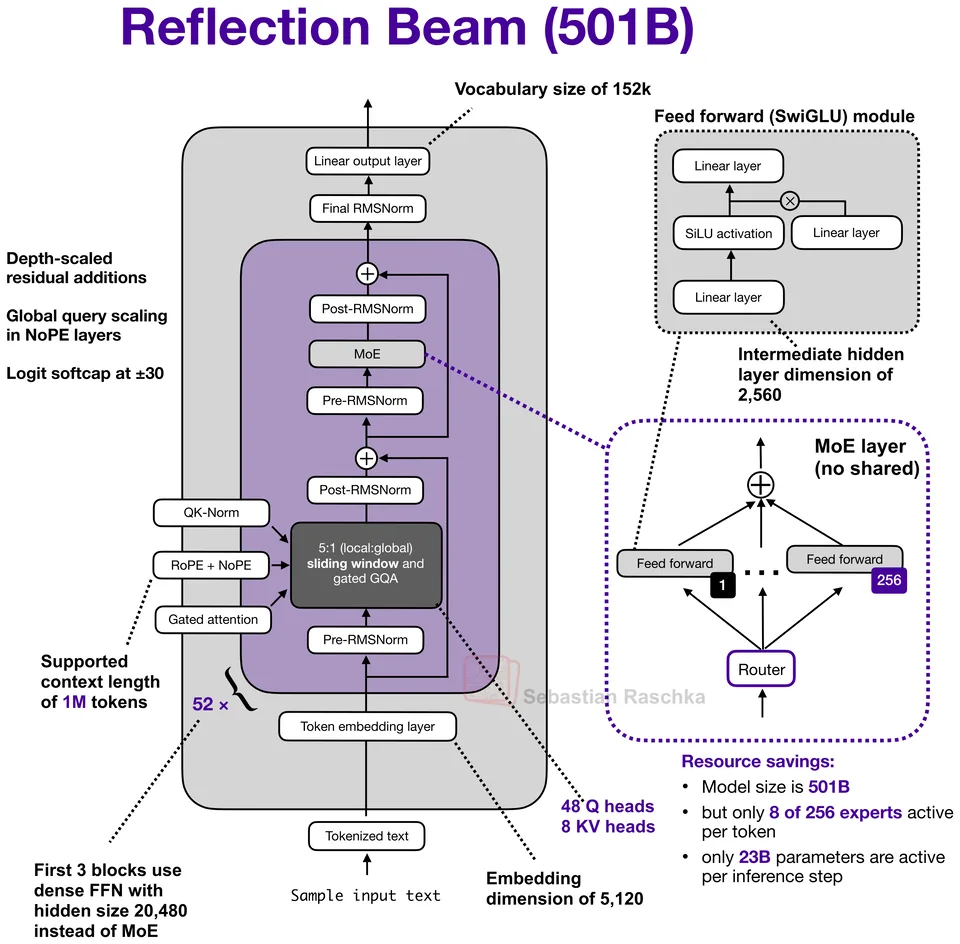
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
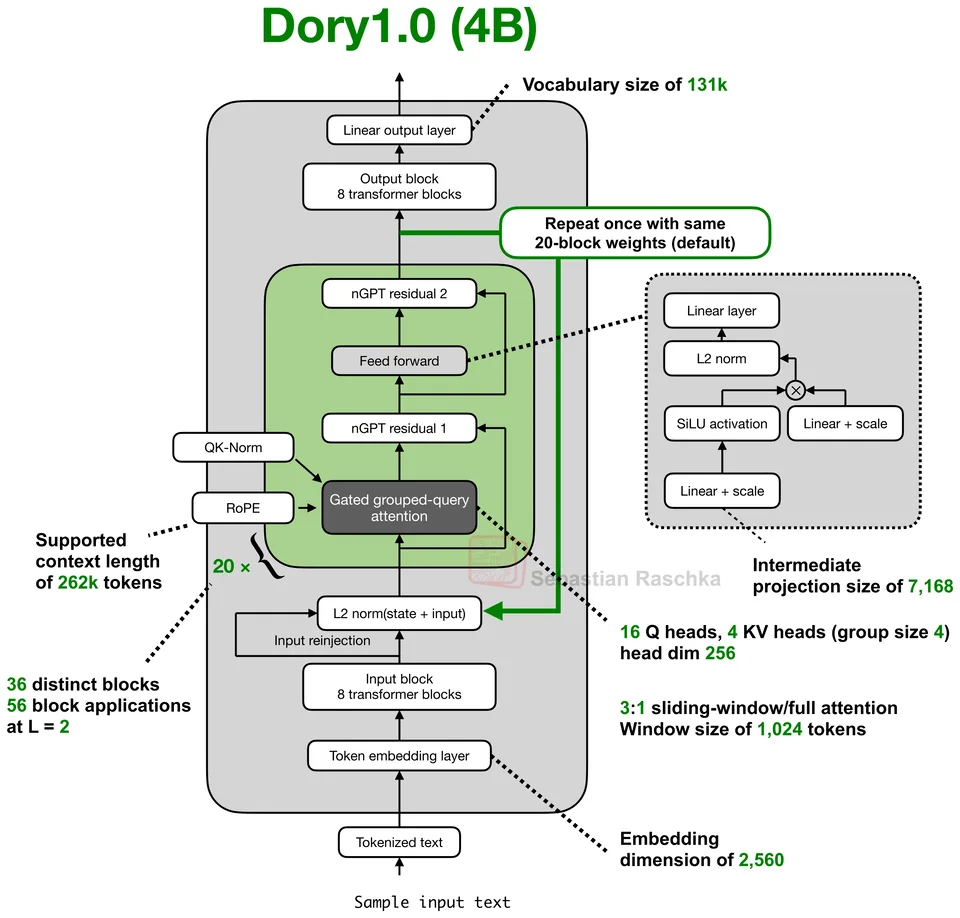
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.
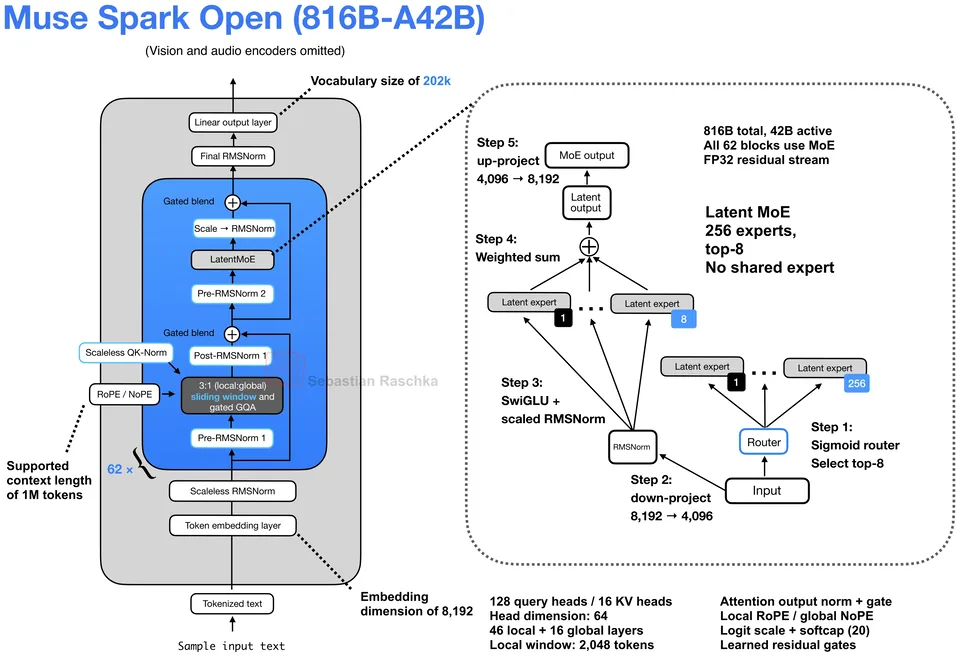
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
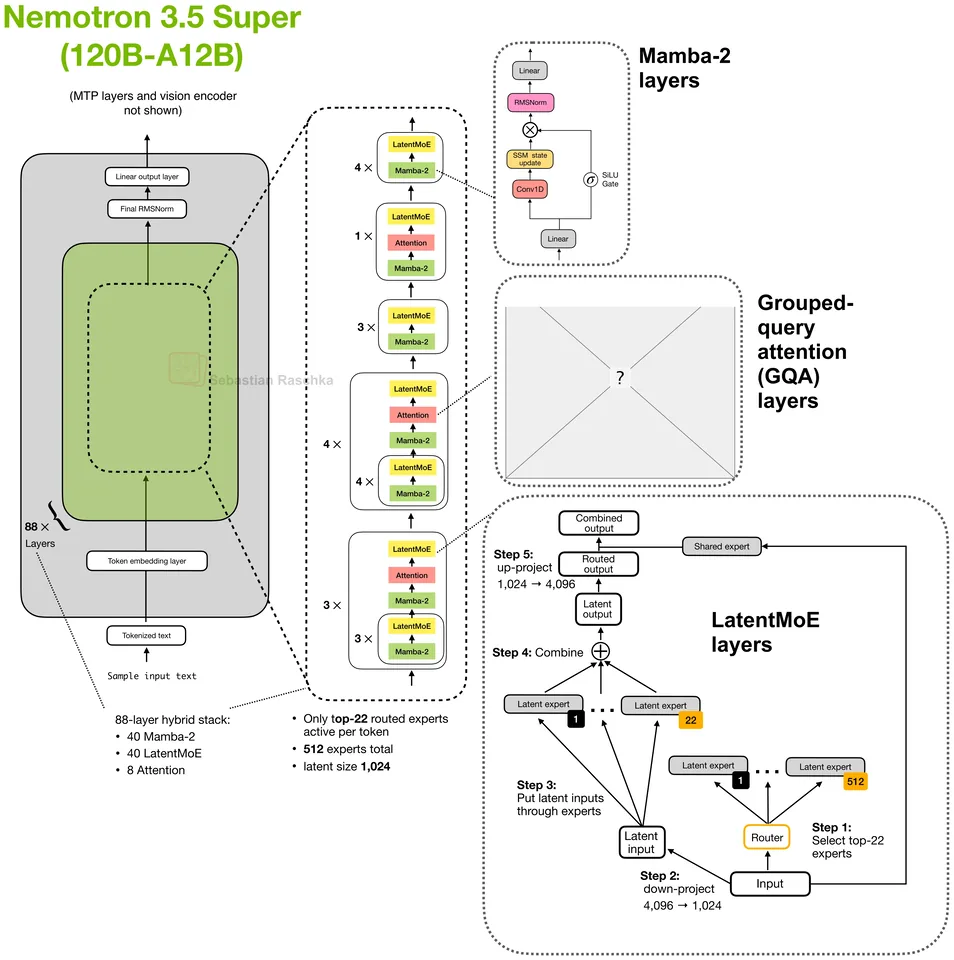
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
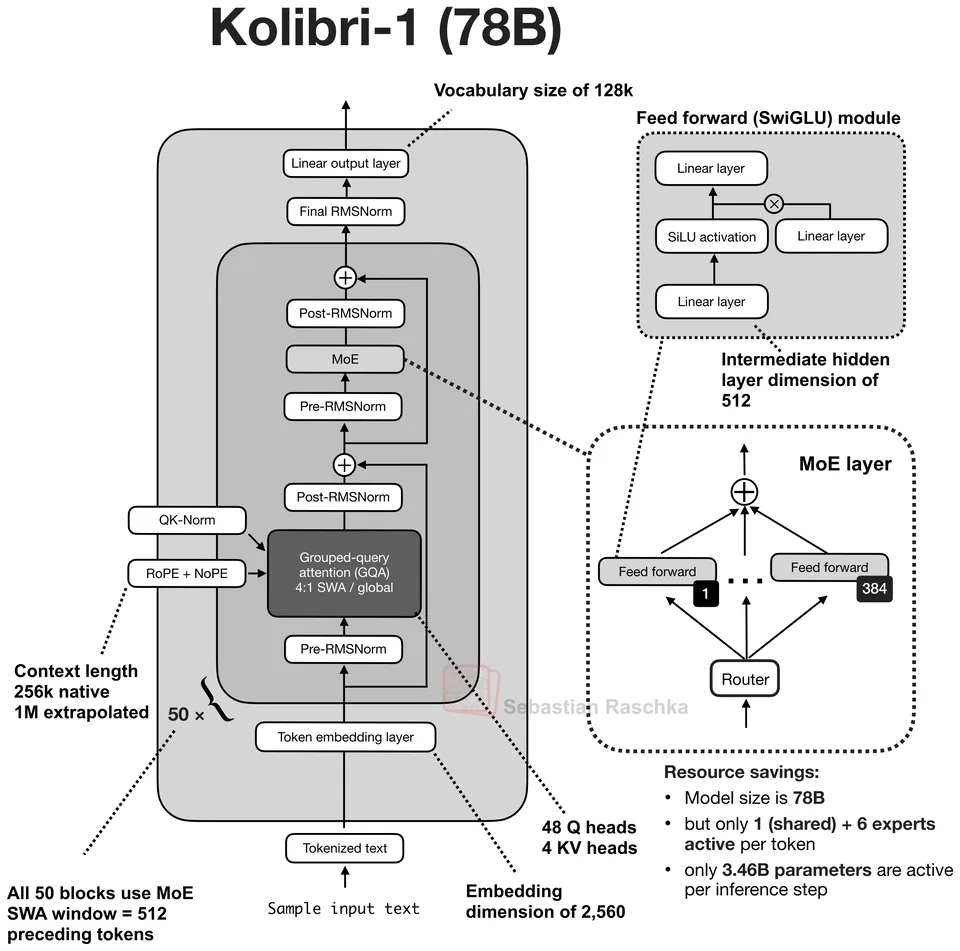
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.
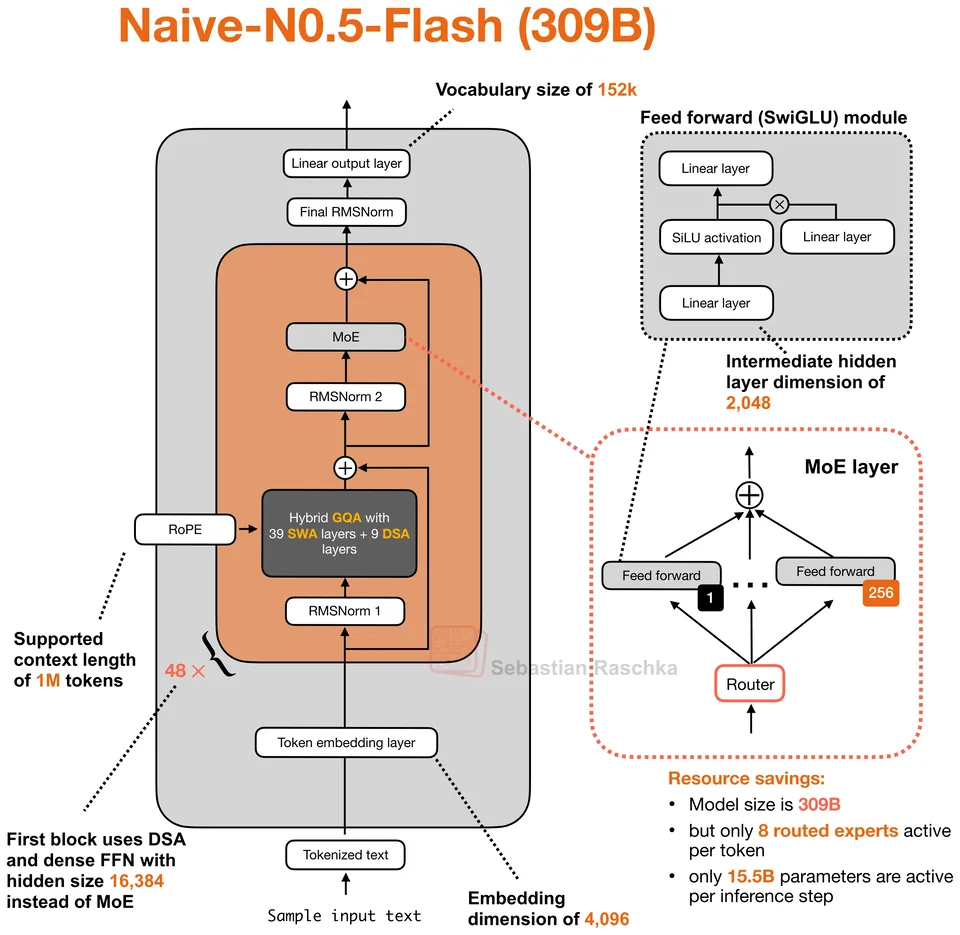
NaiveAI, released 2026-09-27. Sparse MoE decoder, 309B total, 16B active, 1M context. Attention: GQA with sliding-window attention and DeepSeek Sparse Attention.
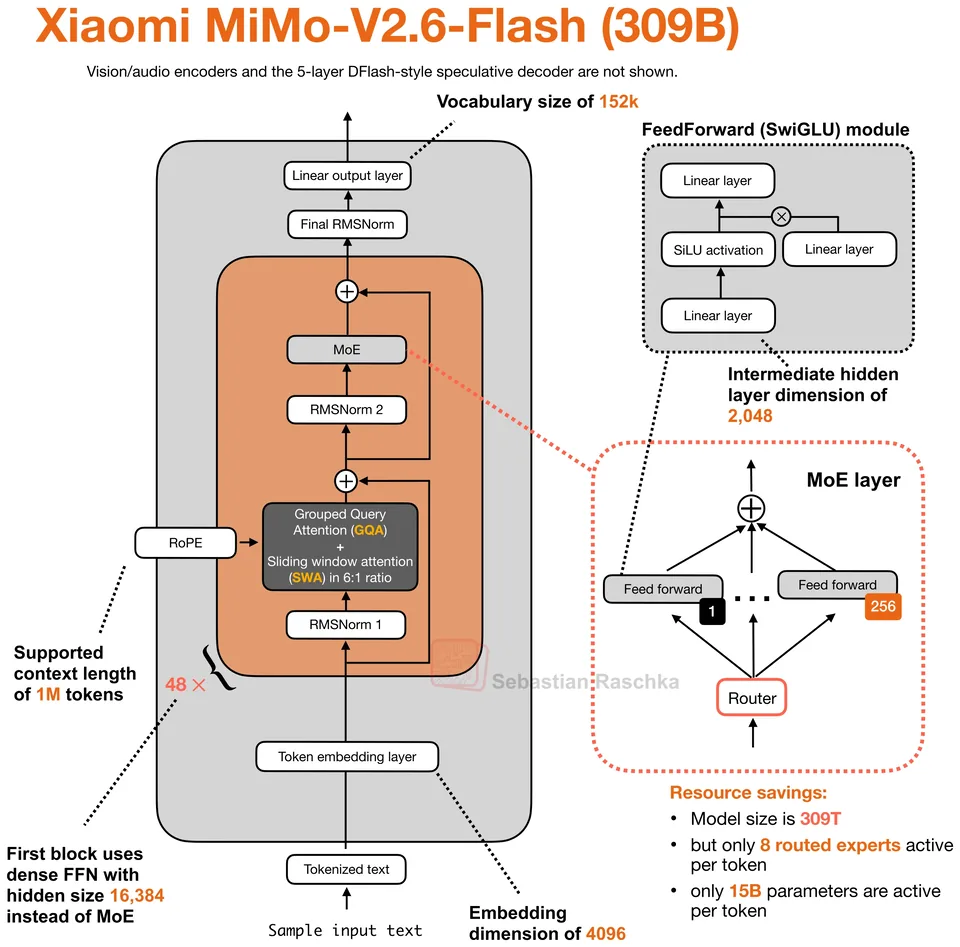
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
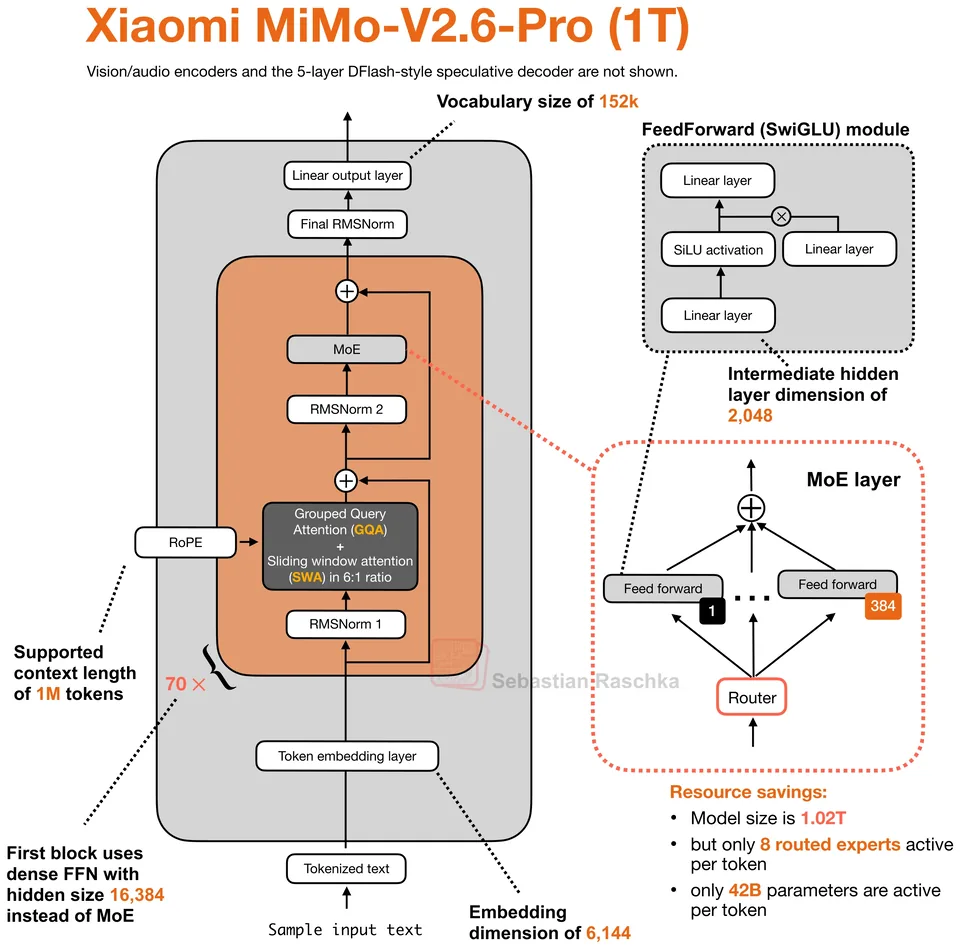
Xiaomi, released 2026-09-21. Sparse MoE decoder, 1.02T total, 42B active, 1M context. Attention: GQA with 6:1 sliding-window/global attention.
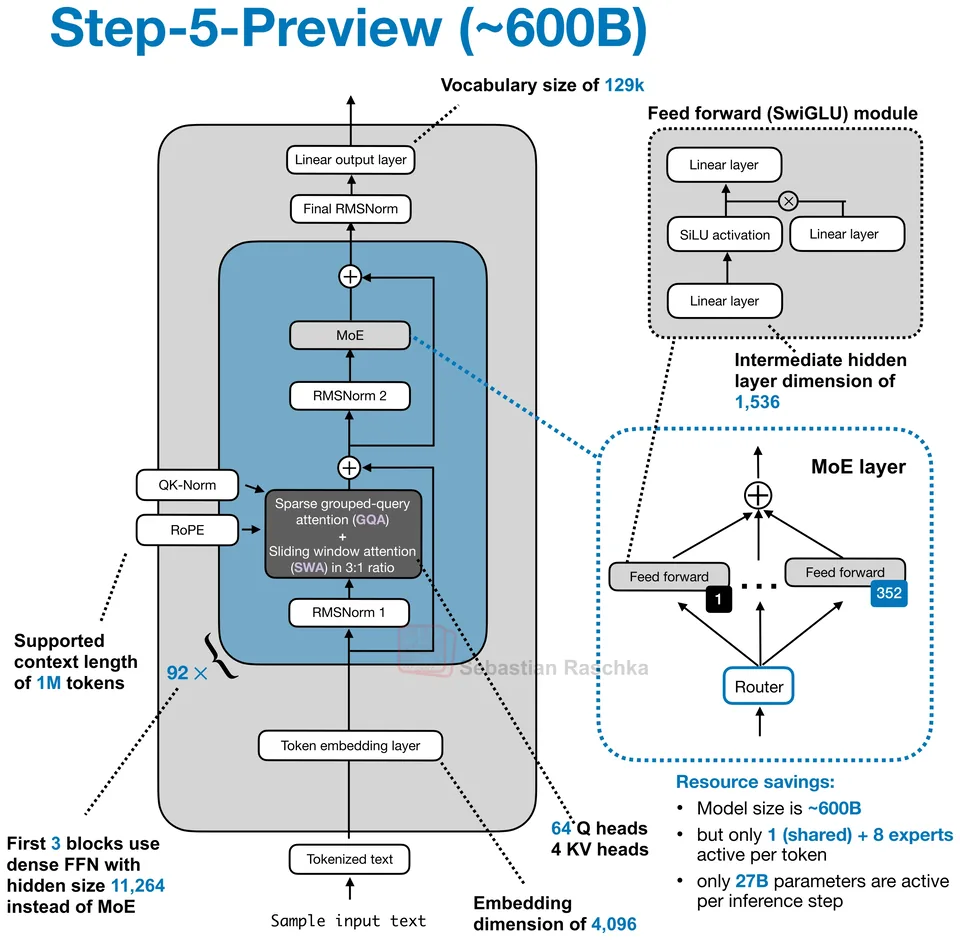
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
Jump to a model, concept or page