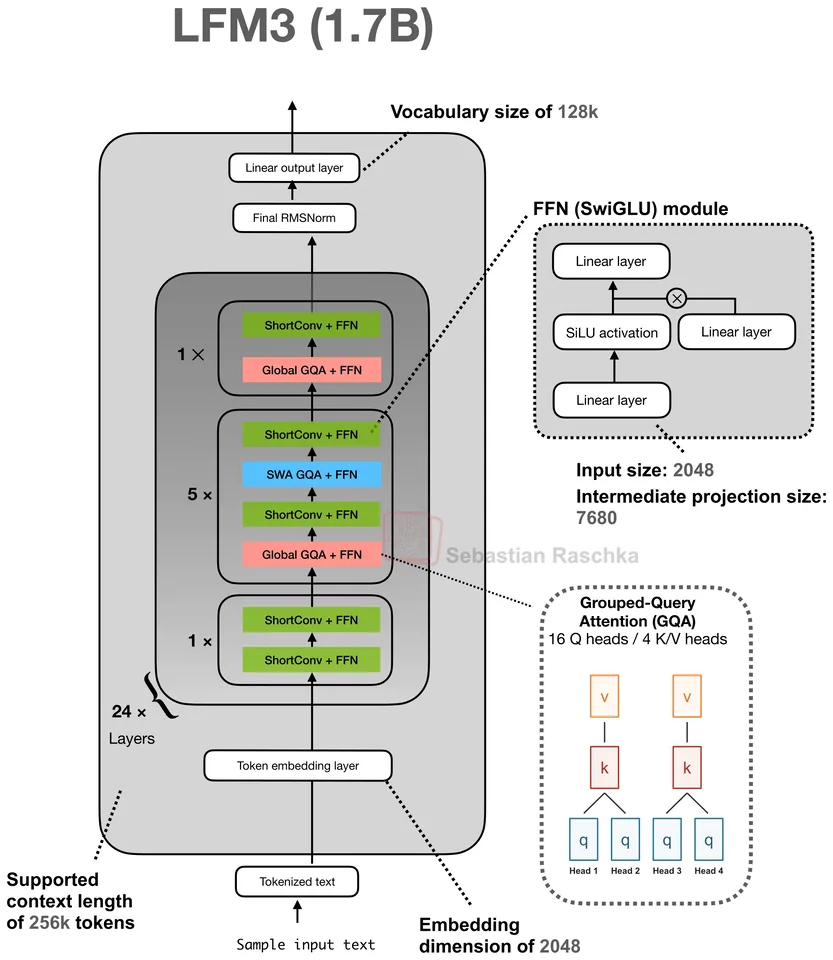
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
Attention · SWA
Some layers only attend to a local window of recent tokens instead of the whole context.
Local (sliding-window) layers restrict each token to the last N tokens, so their KV cache stops growing once the window is full. A few global layers are kept so information can still travel across the whole context.
Gemma 3 made the pattern famous with a 5:1 local-to-global ratio and a 1,024-token window. The ratio and window size are the main knobs, and it is very often paired with GQA.
Models in the atlas using SWA, per half-year of release.
Often paired with
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
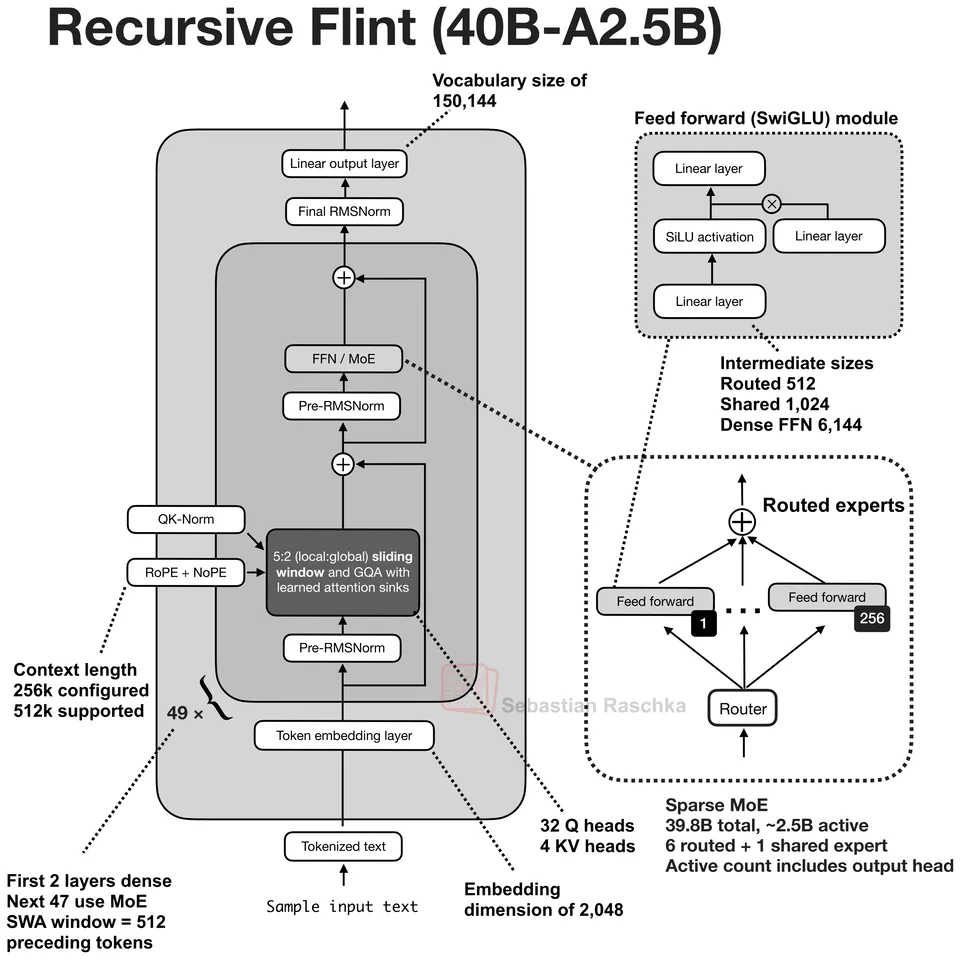
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
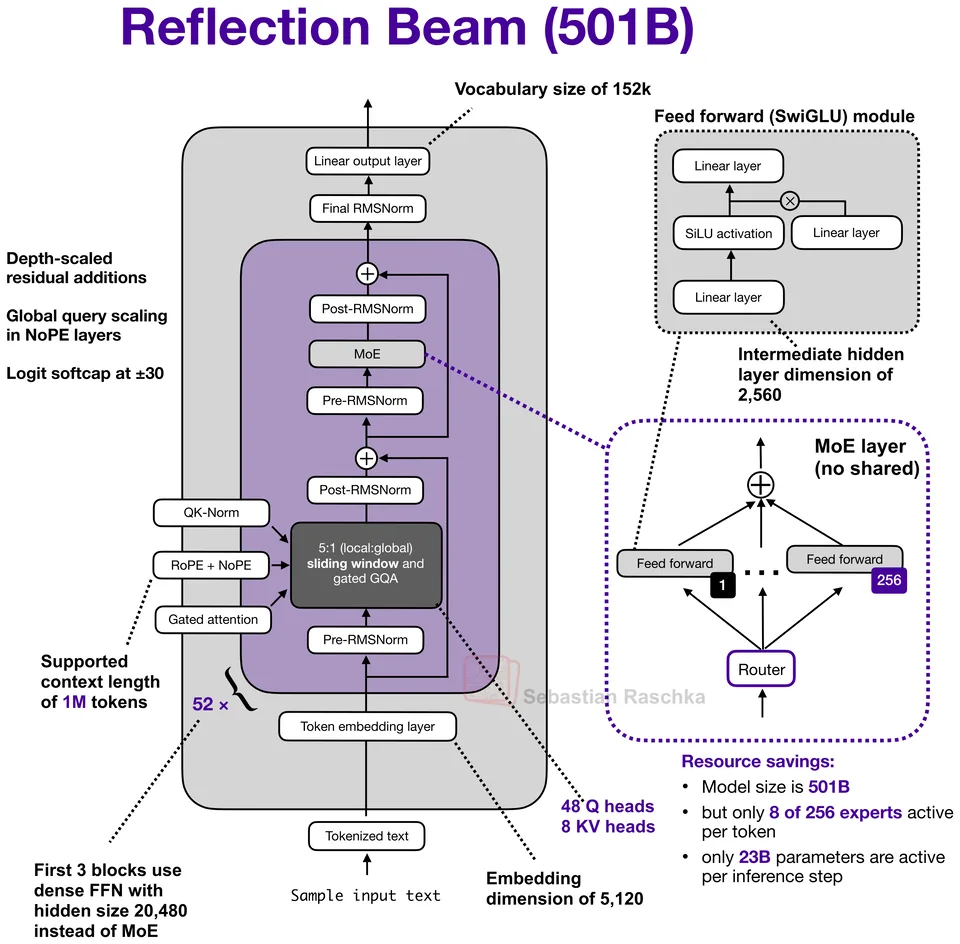
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
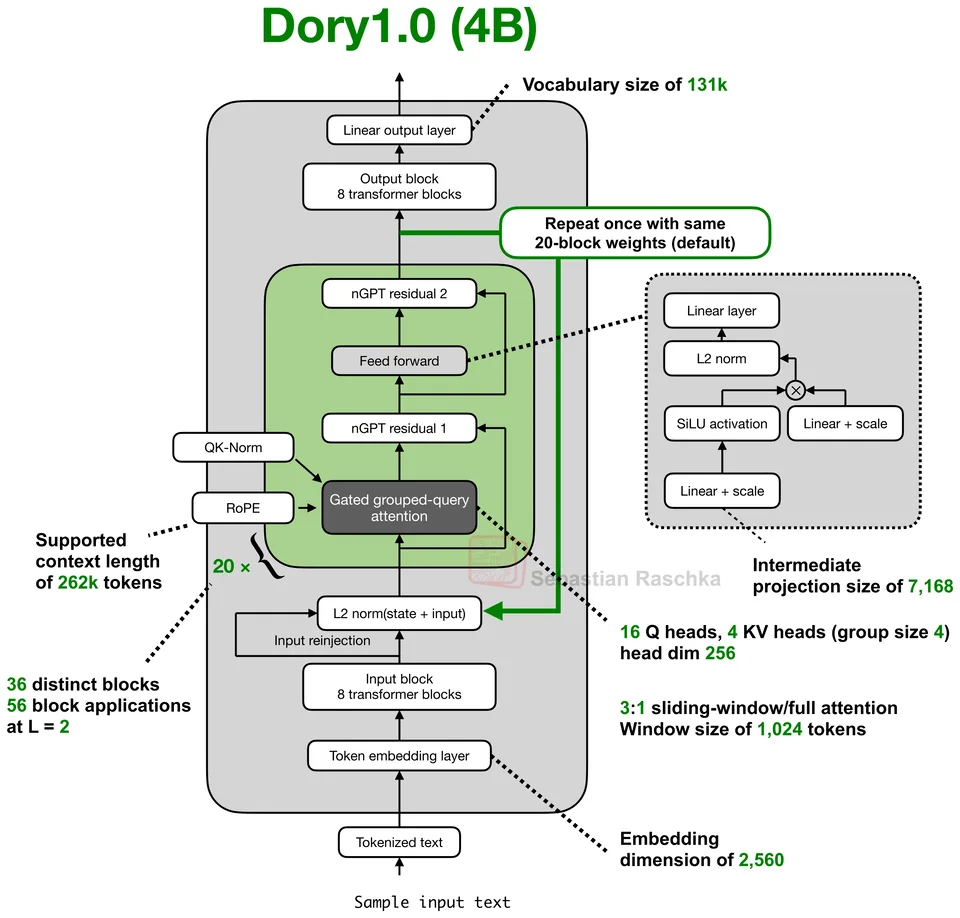
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.
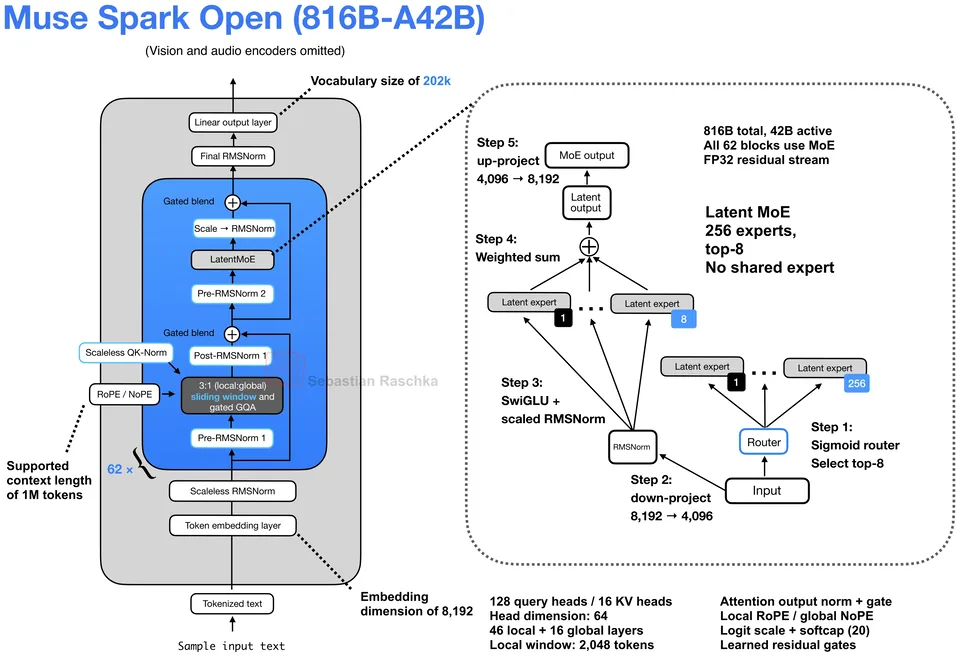
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
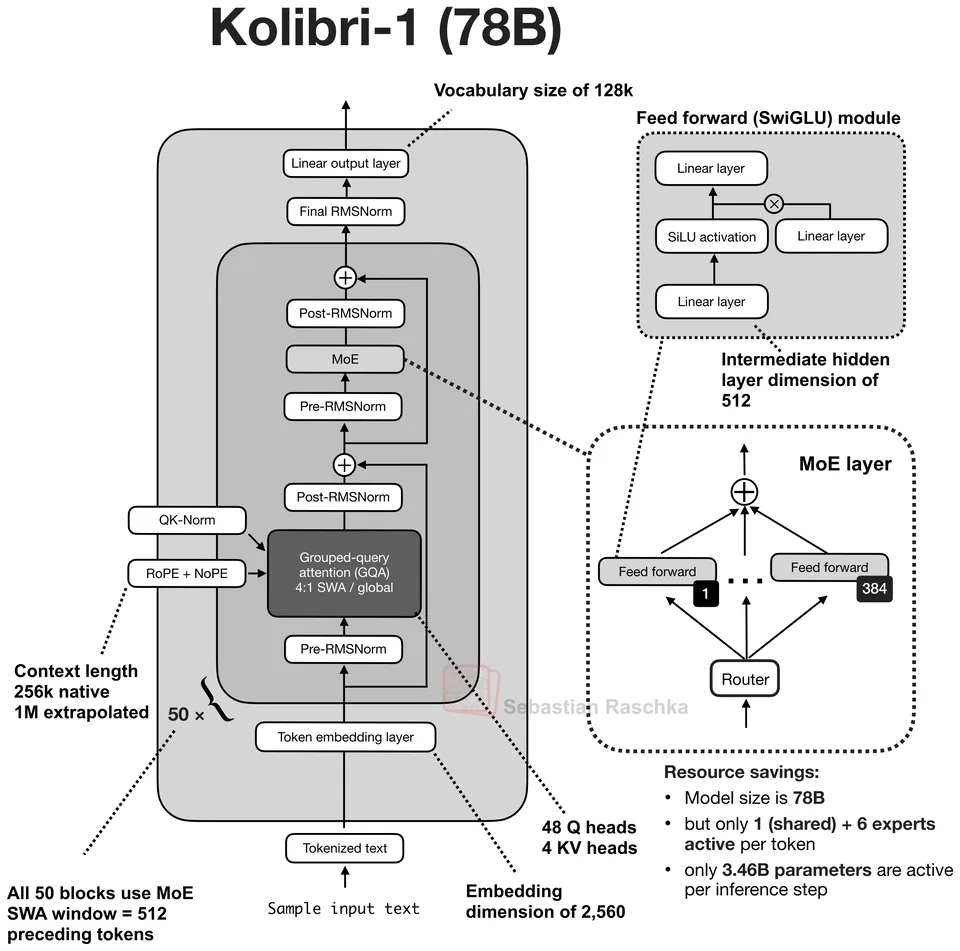
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.
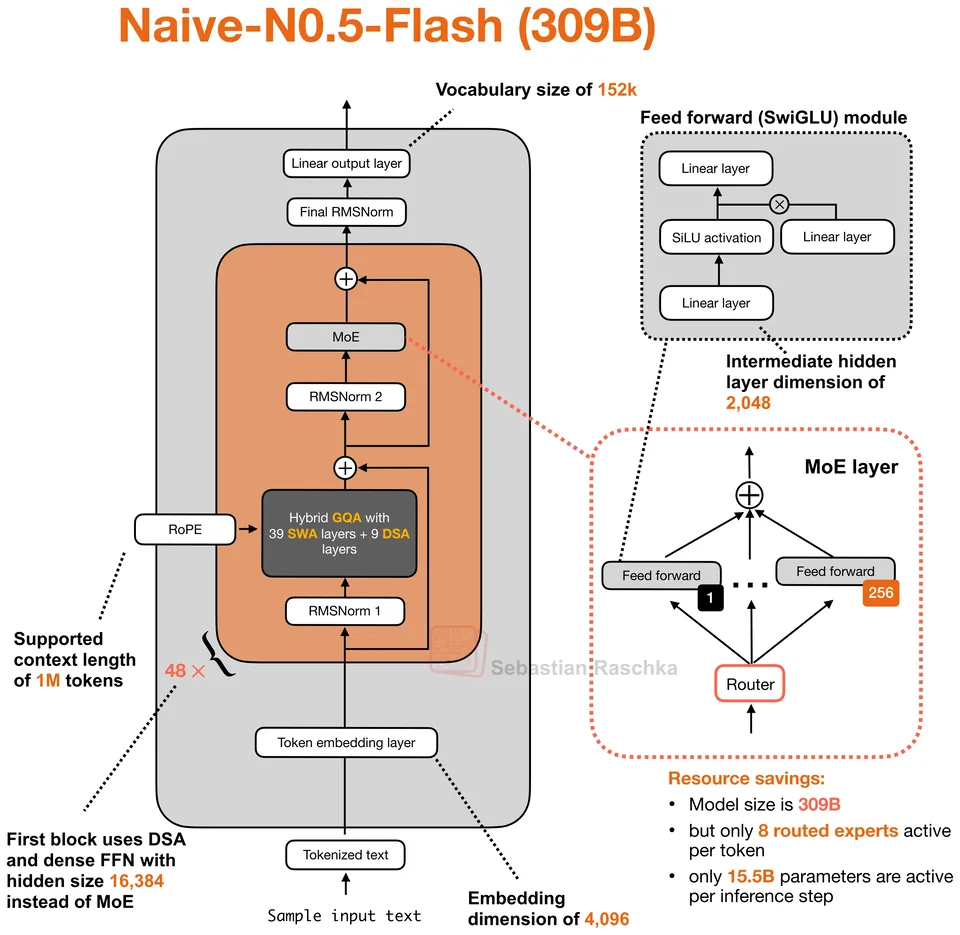
NaiveAI, released 2026-09-27. Sparse MoE decoder, 309B total, 16B active, 1M context. Attention: GQA with sliding-window attention and DeepSeek Sparse Attention.
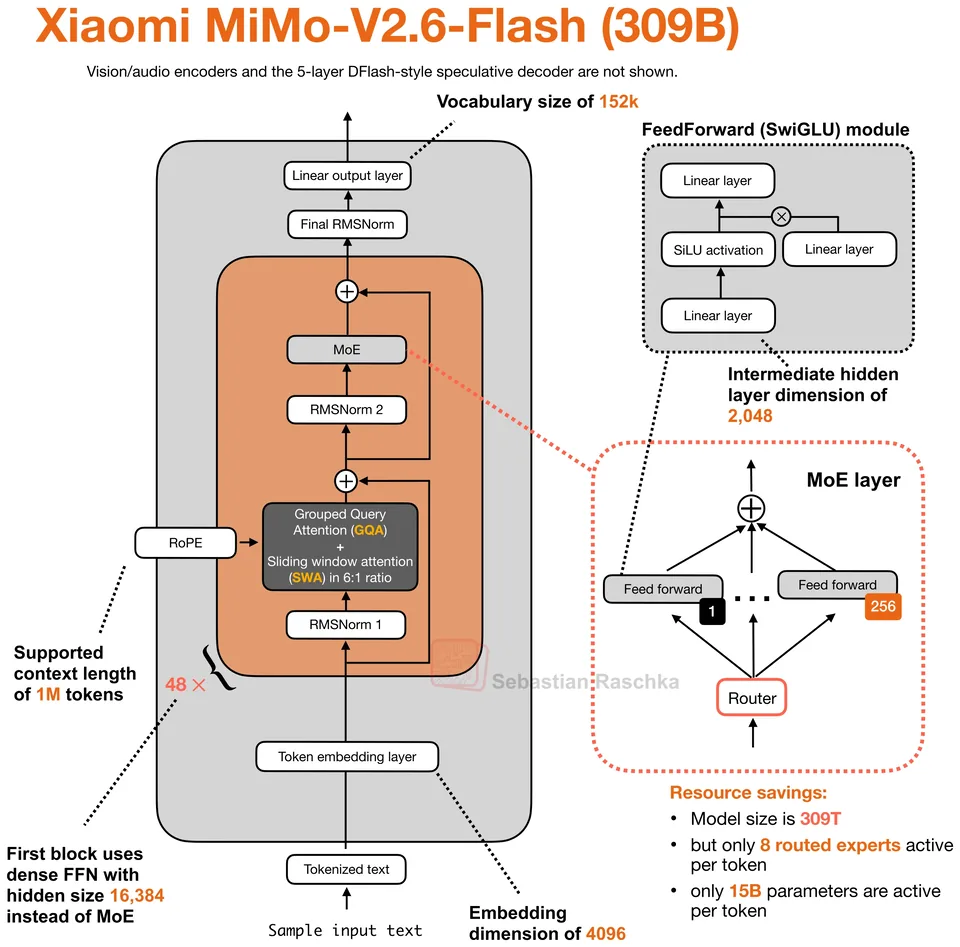
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
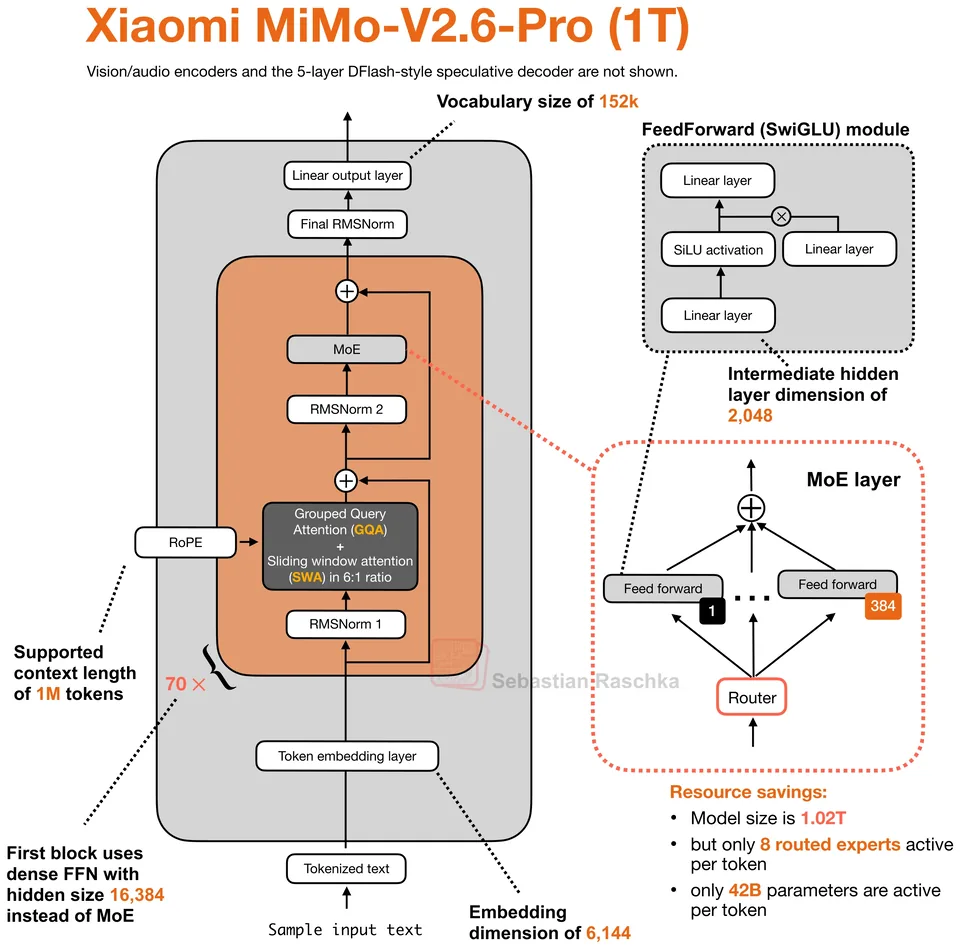
Xiaomi, released 2026-09-21. Sparse MoE decoder, 1.02T total, 42B active, 1M context. Attention: GQA with 6:1 sliding-window/global attention.
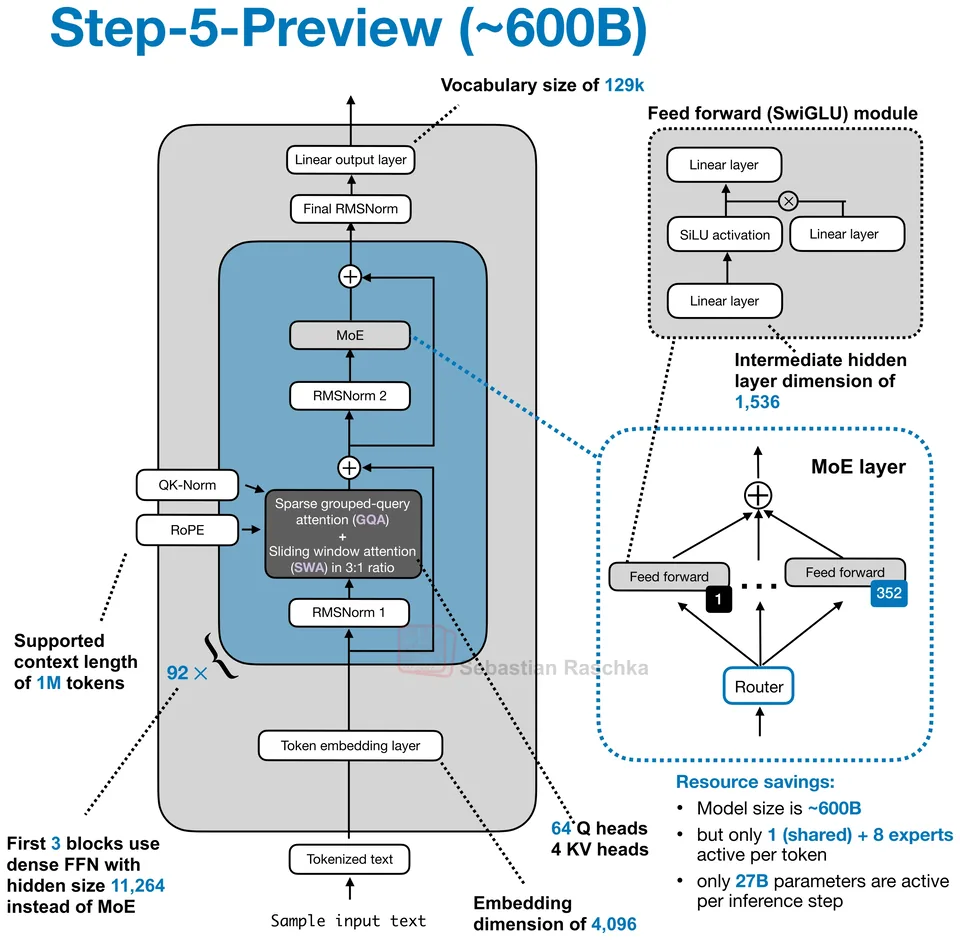
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
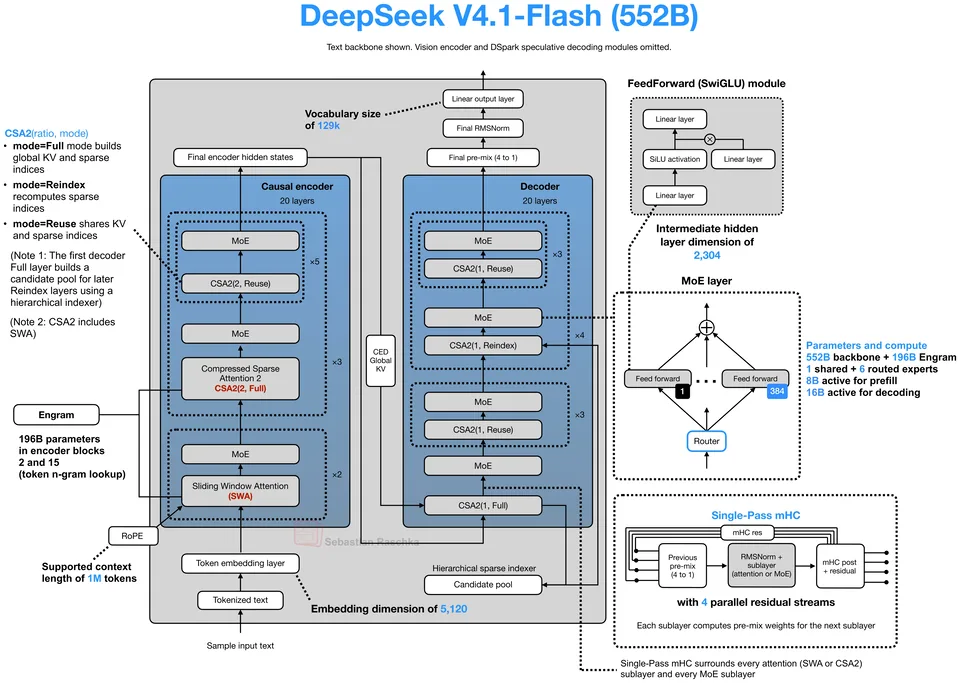
DeepSeek, released 2026-09-10. Sparse MoE decoder, 552B total, 8B active, 1M context. Attention: MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse.

Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
Jump to a model, concept or page