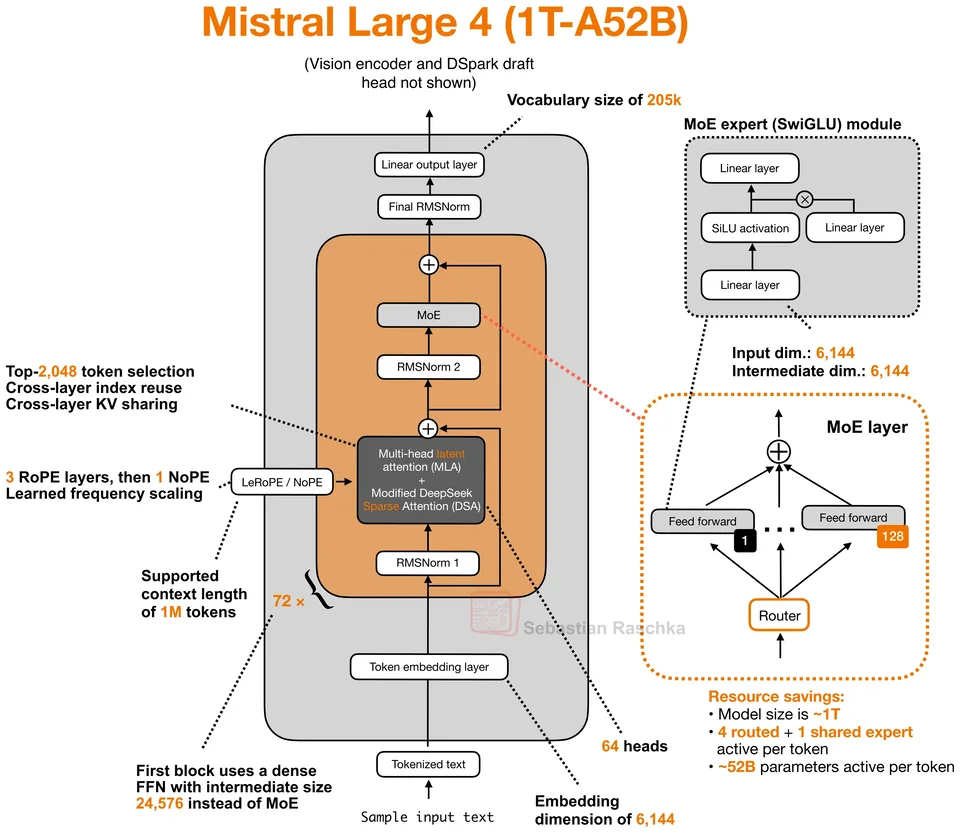
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
118 models from 44 labs
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
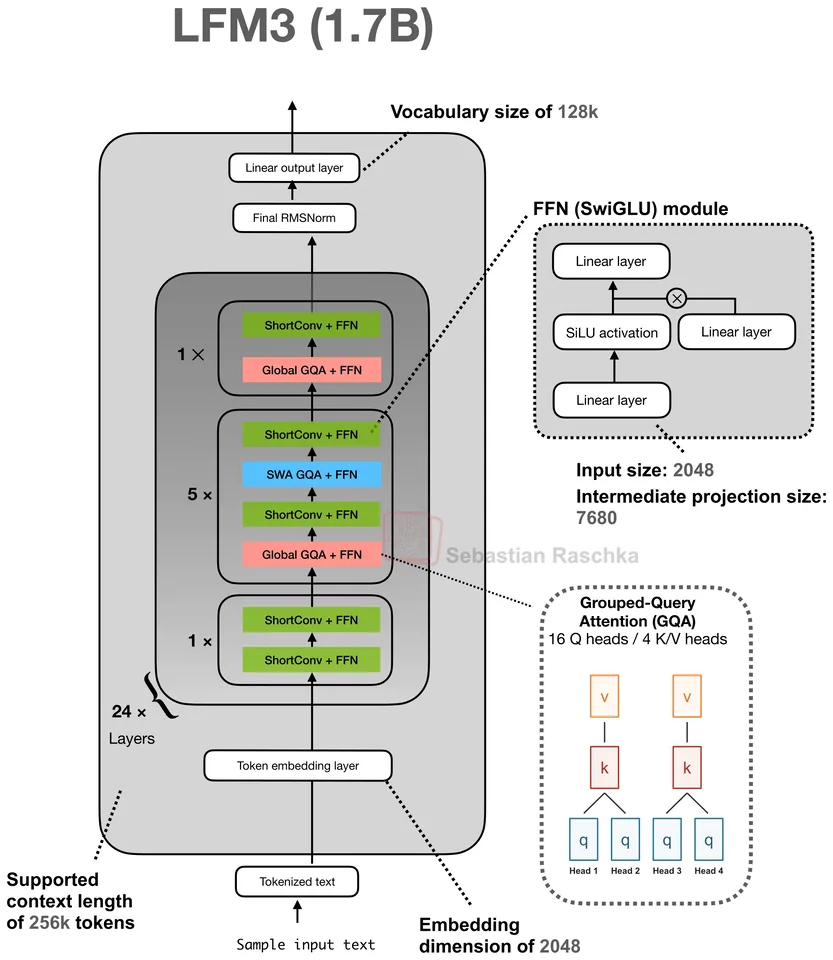
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
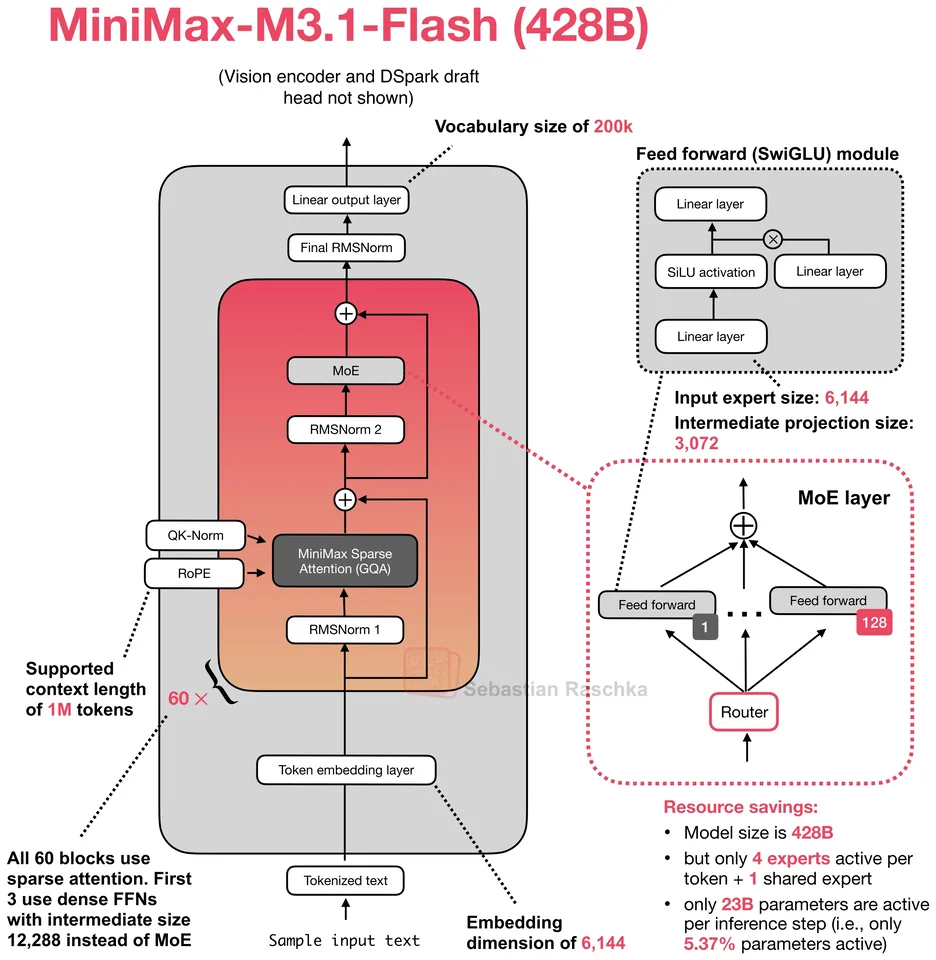
MiniMax, released 2026-10-19. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.
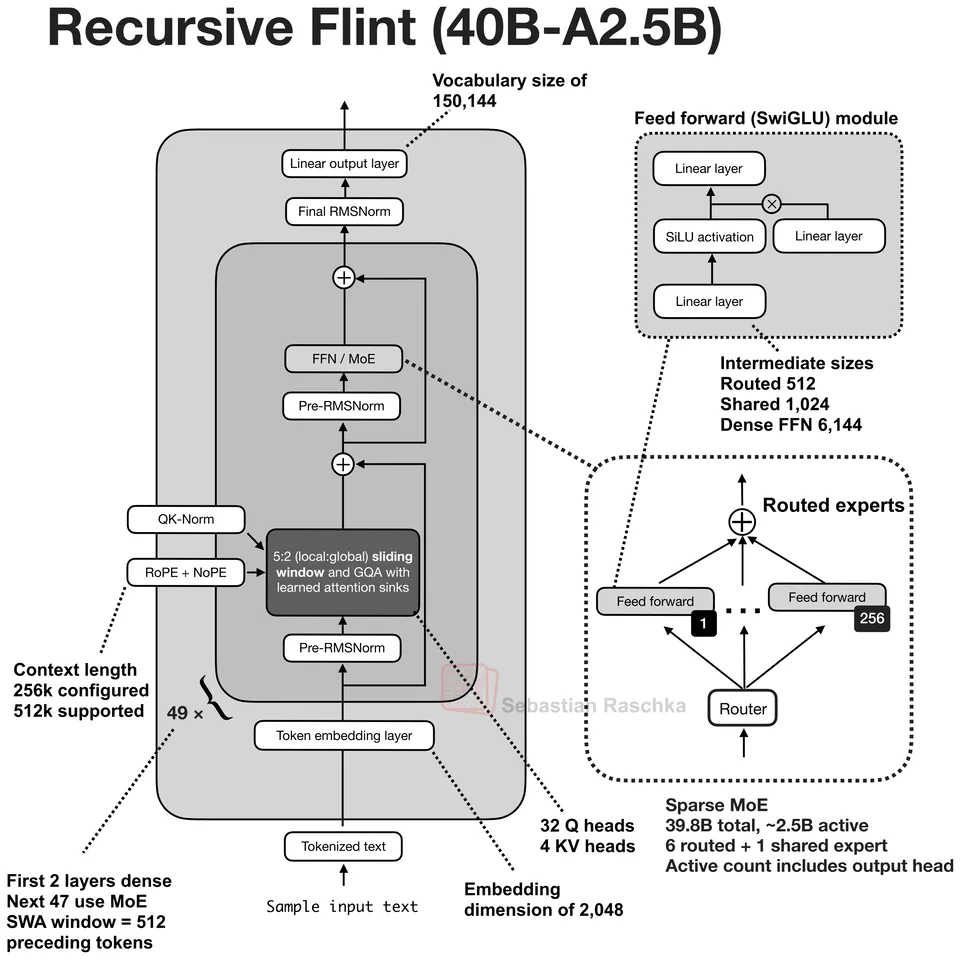
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
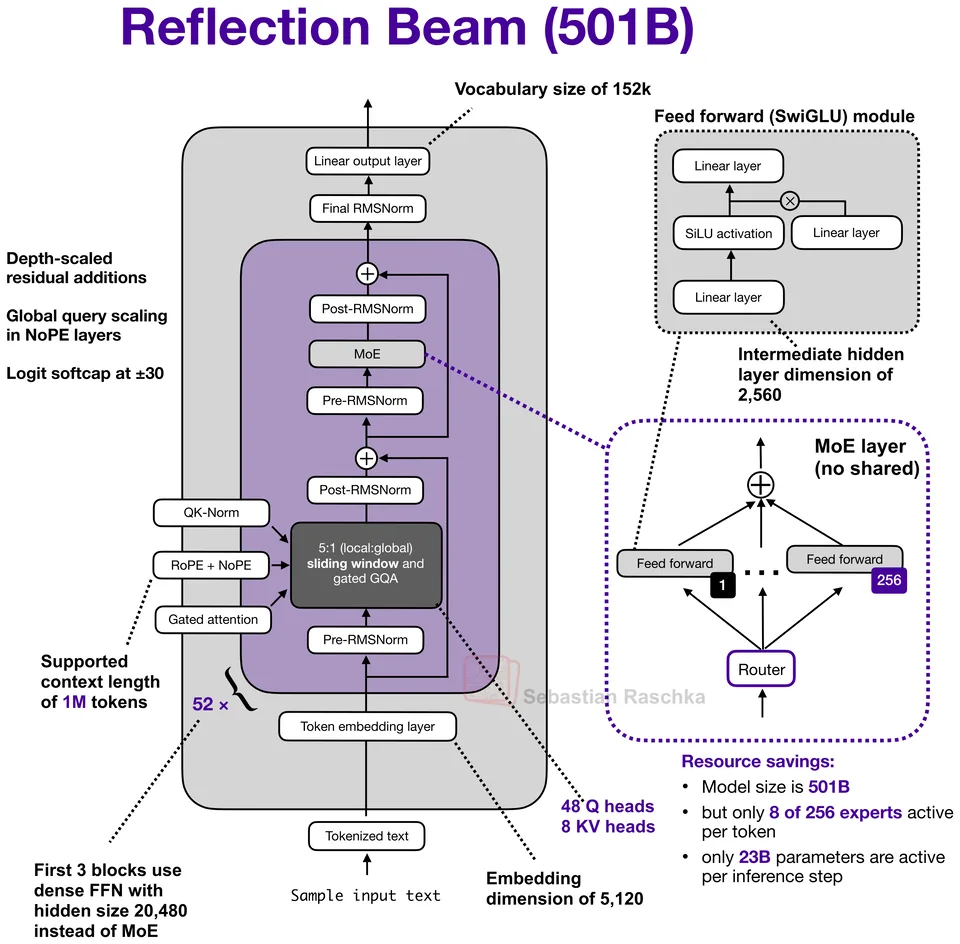
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
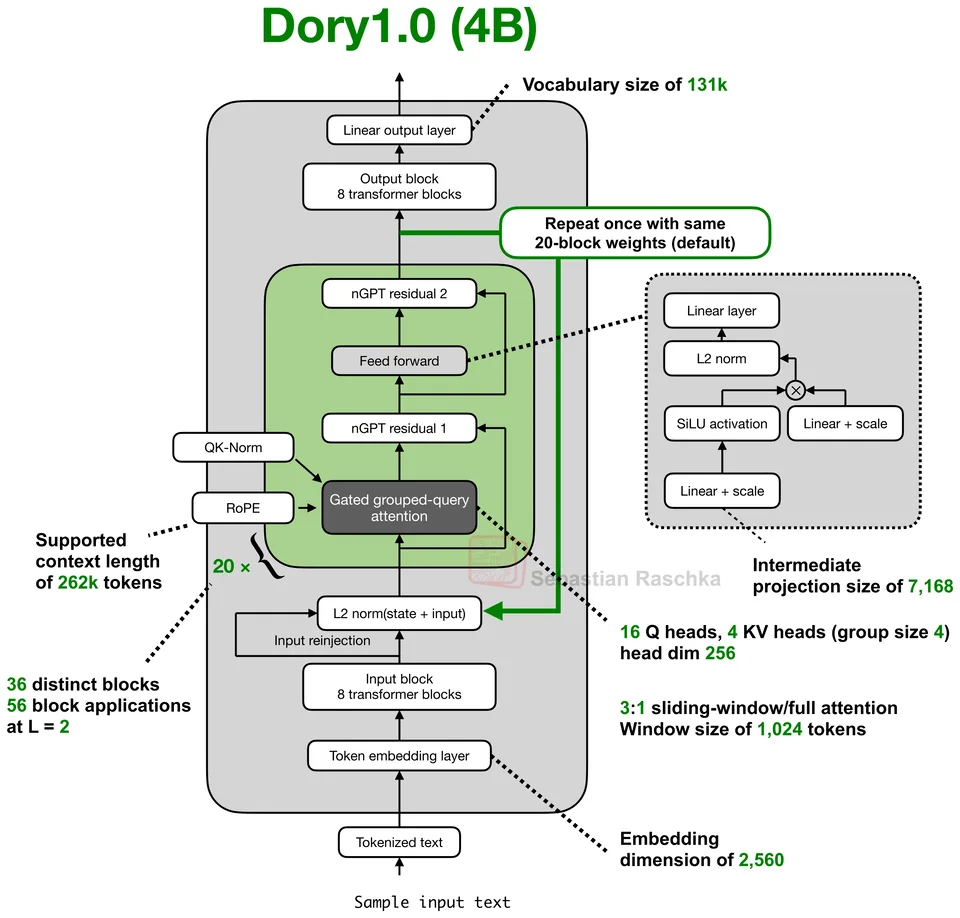
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.
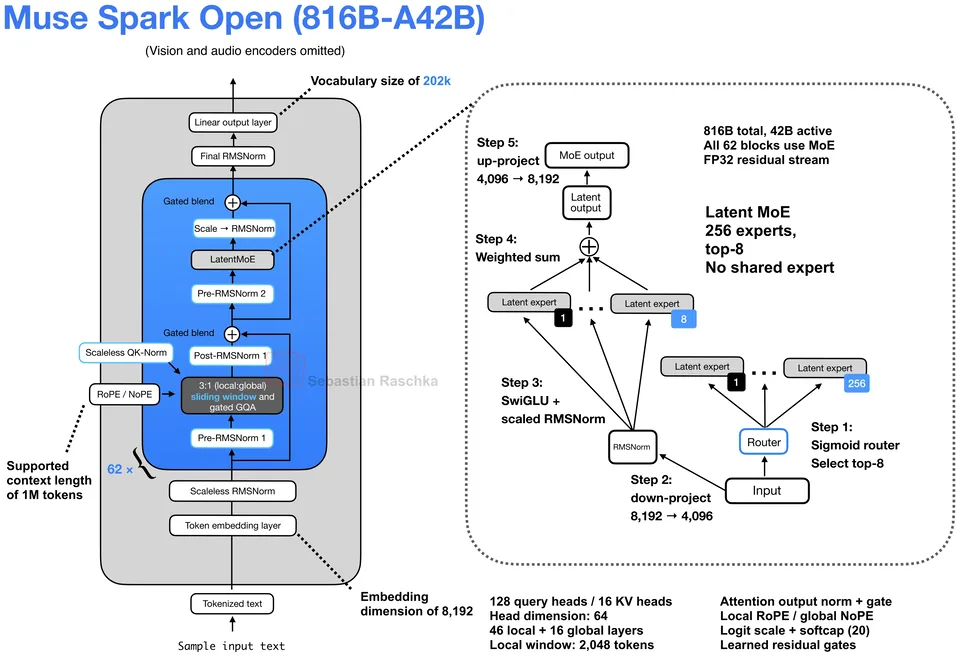
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
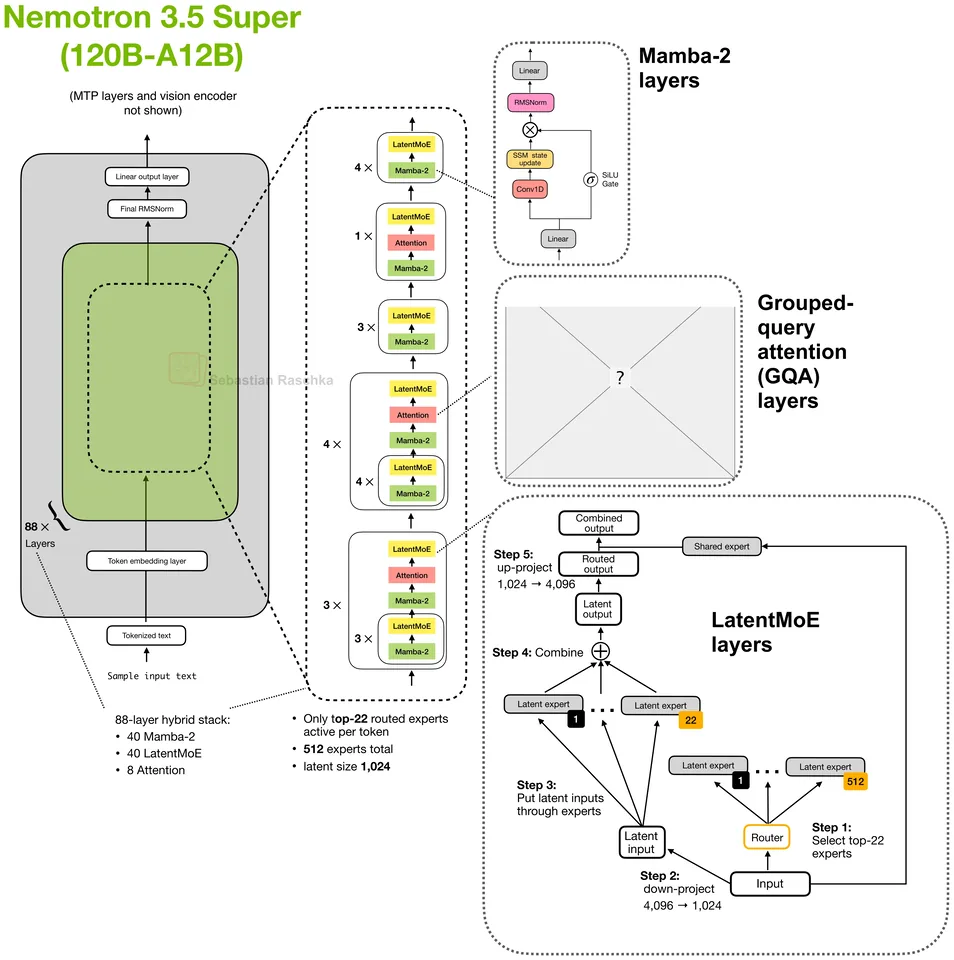
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
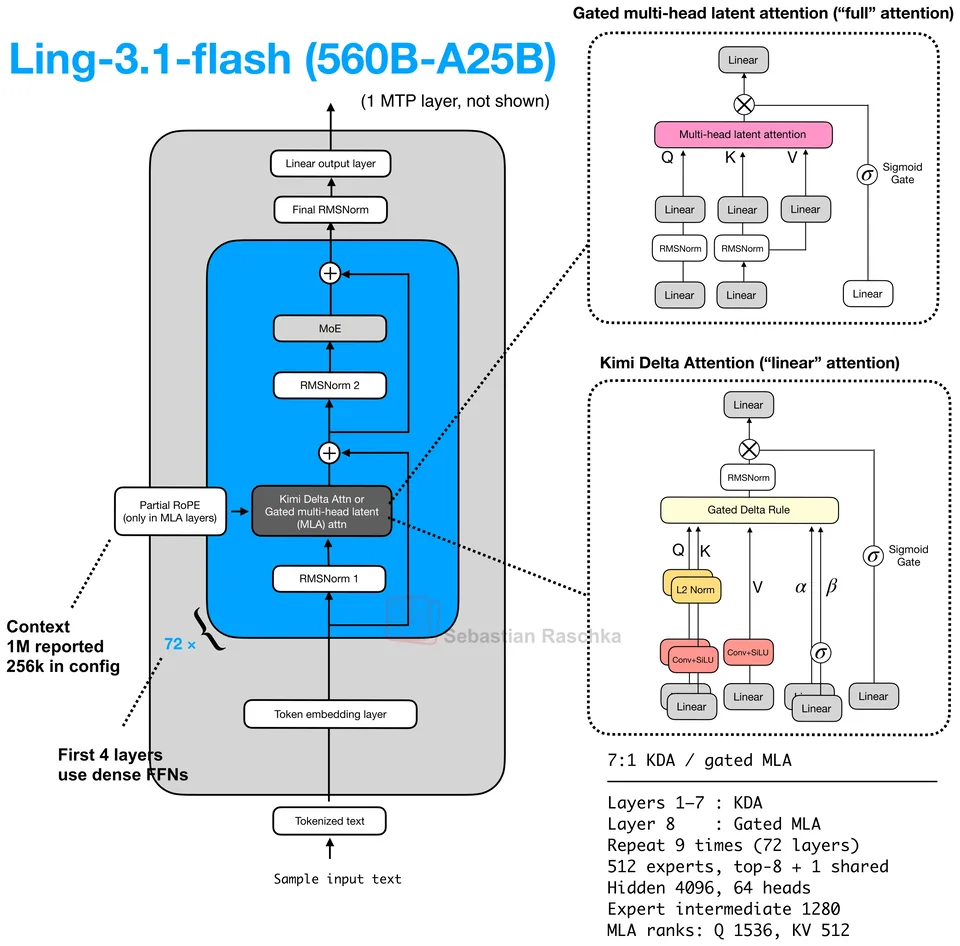
InclusionAI, released 2026-10-13. Hybrid MoE decoder, 560B total, 25B active, 1M context. Attention: 7:1 Kimi Delta Attention and gated MLA.
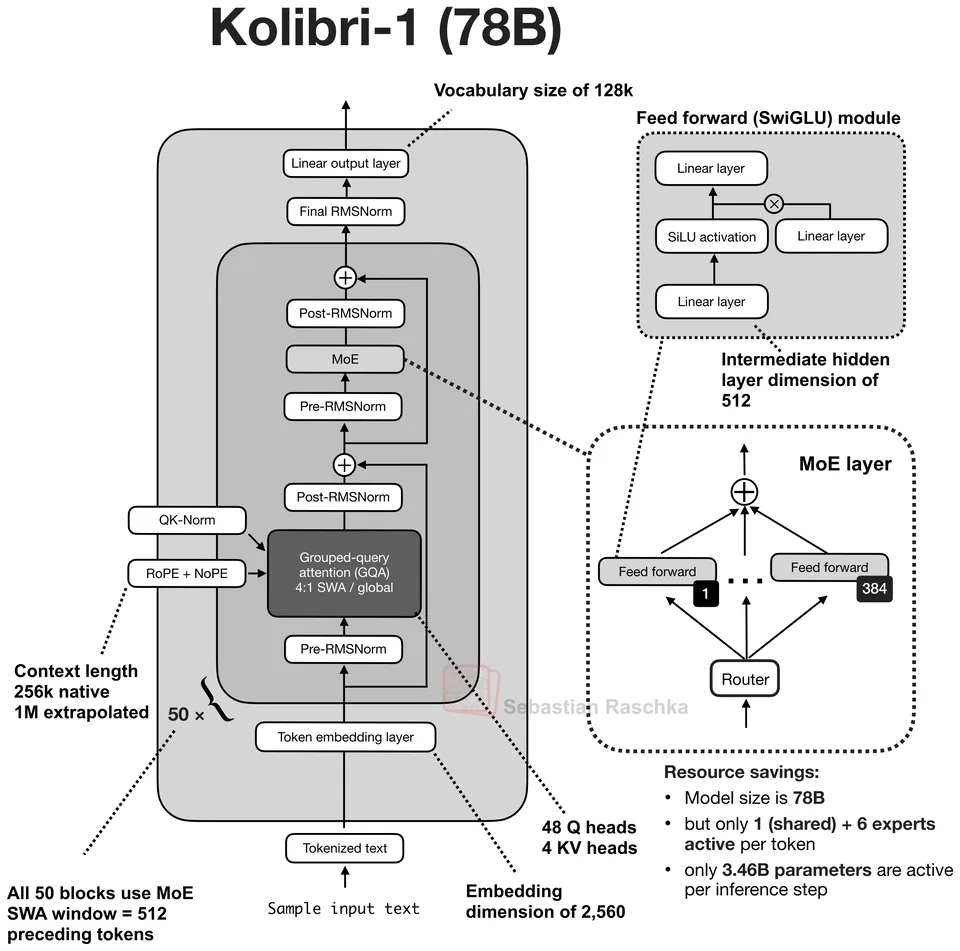
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.
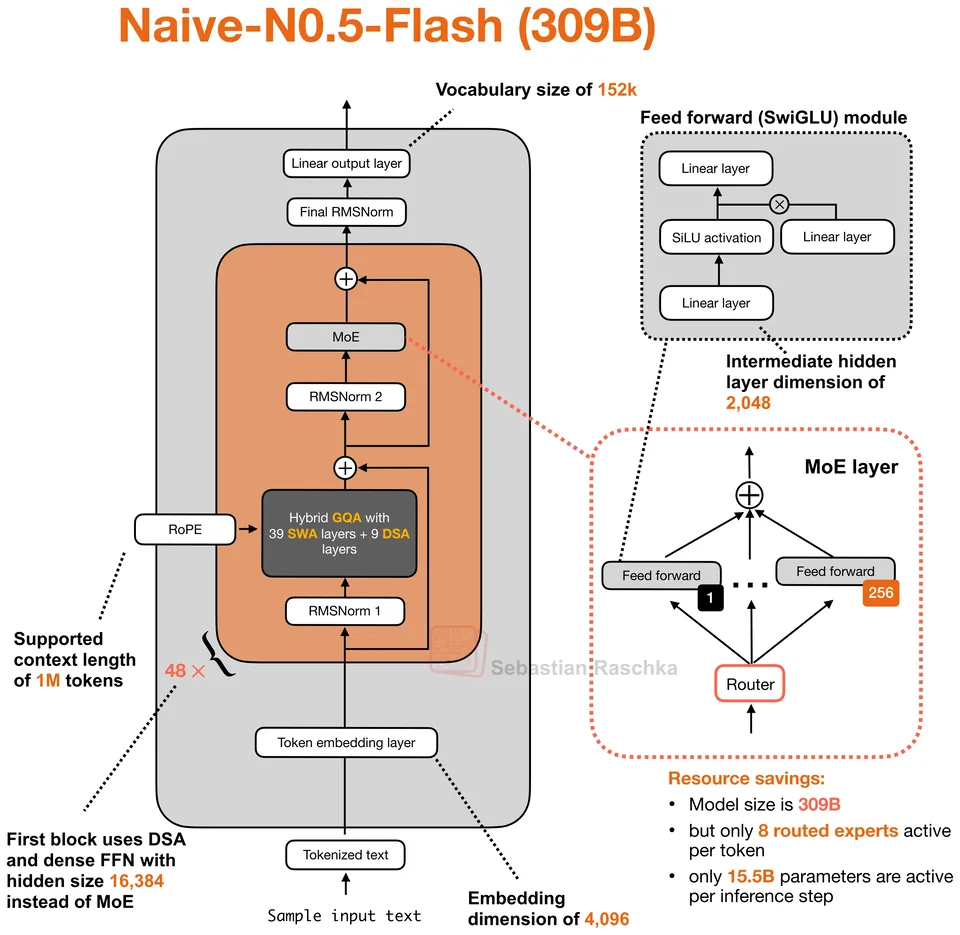
NaiveAI, released 2026-09-27. Sparse MoE decoder, 309B total, 16B active, 1M context. Attention: GQA with sliding-window attention and DeepSeek Sparse Attention.
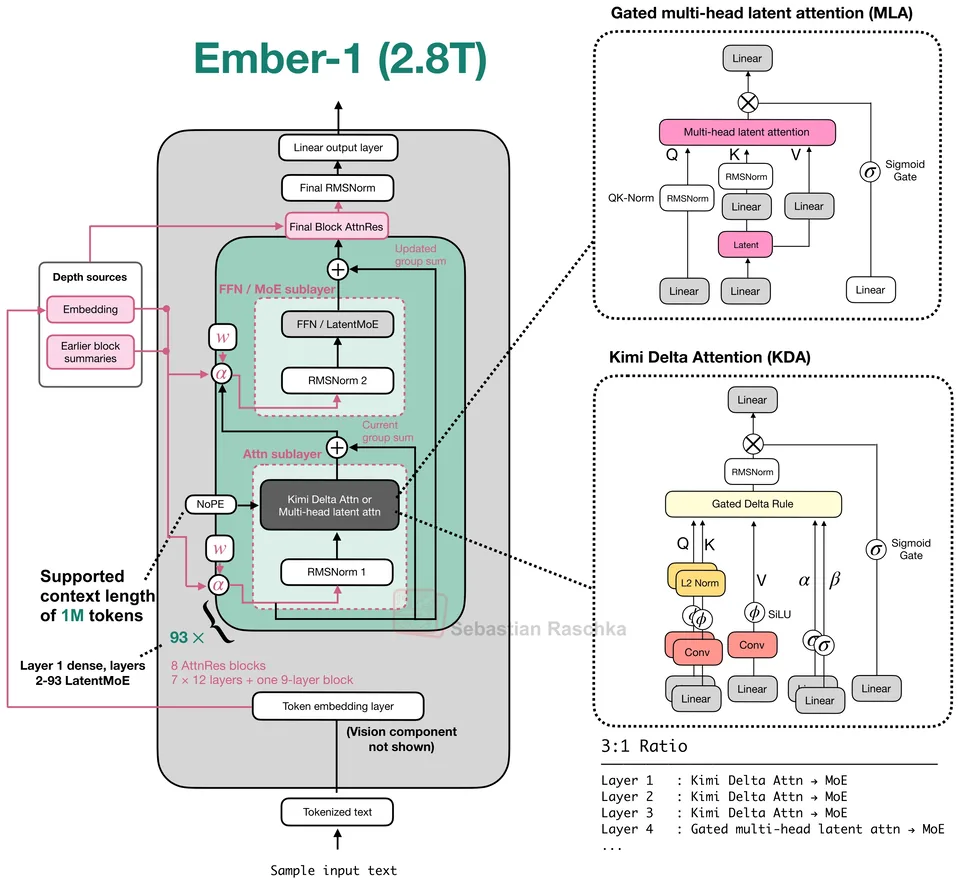
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
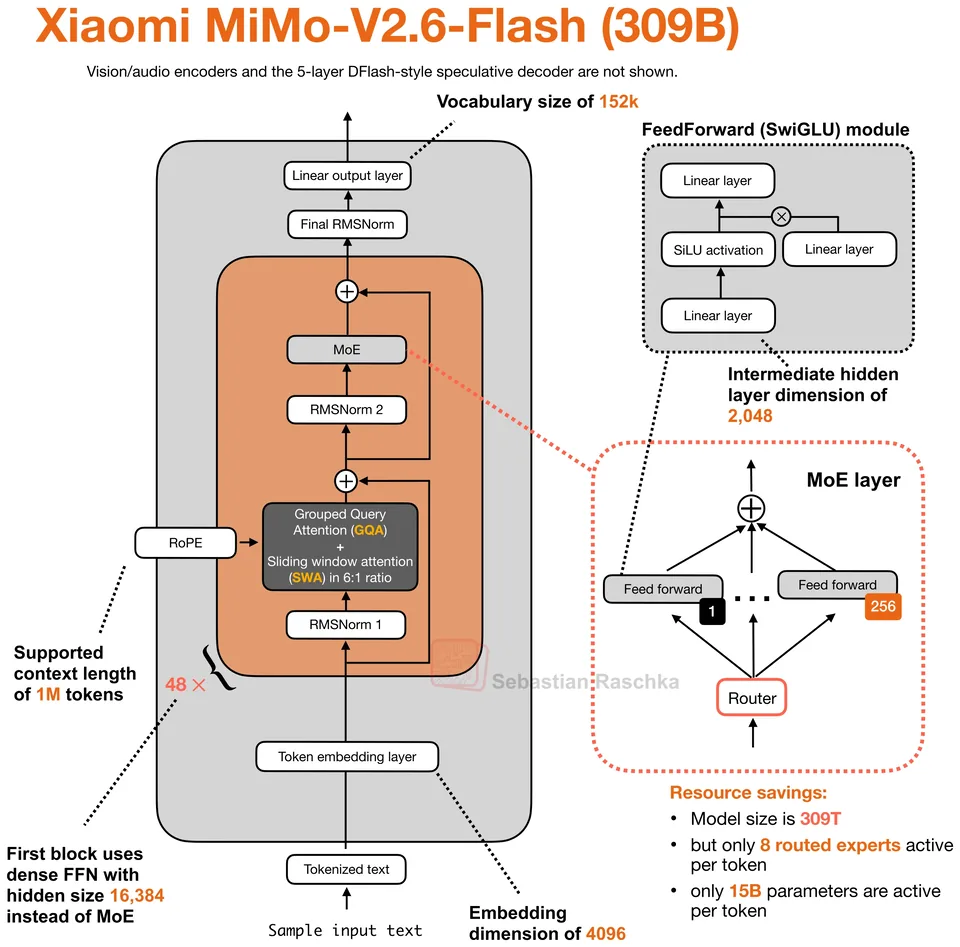
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
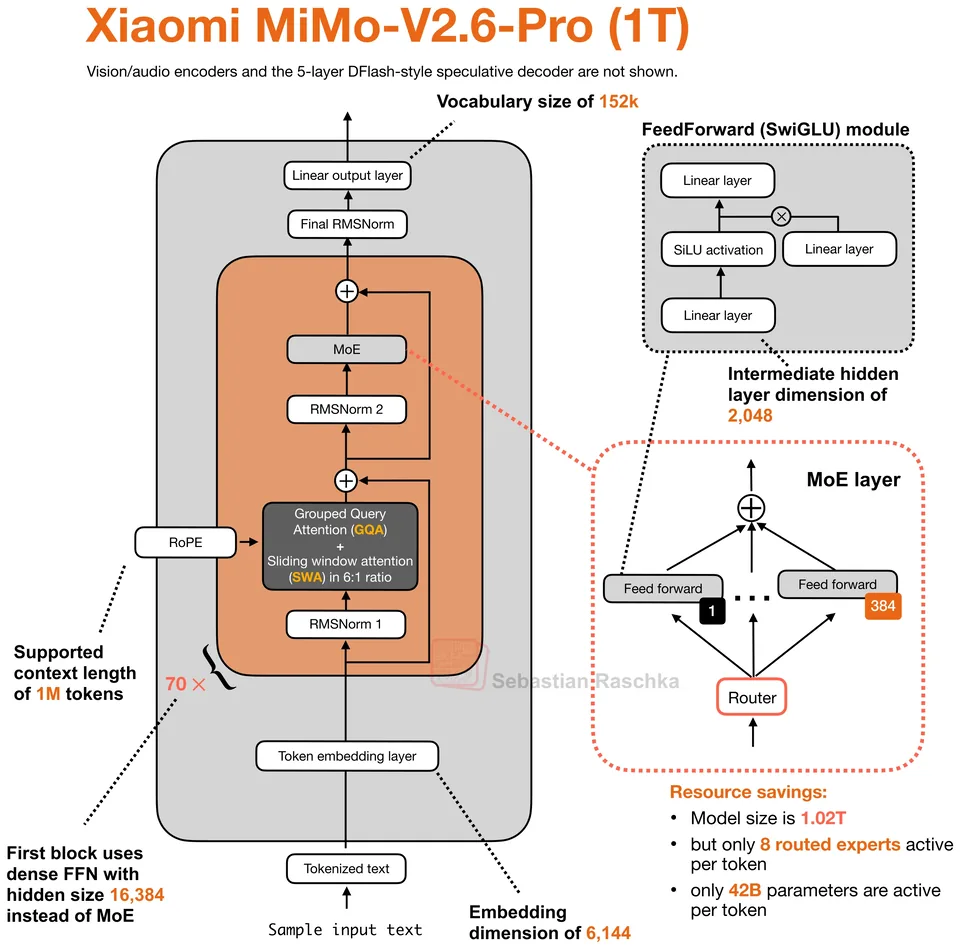
Xiaomi, released 2026-09-21. Sparse MoE decoder, 1.02T total, 42B active, 1M context. Attention: GQA with 6:1 sliding-window/global attention.
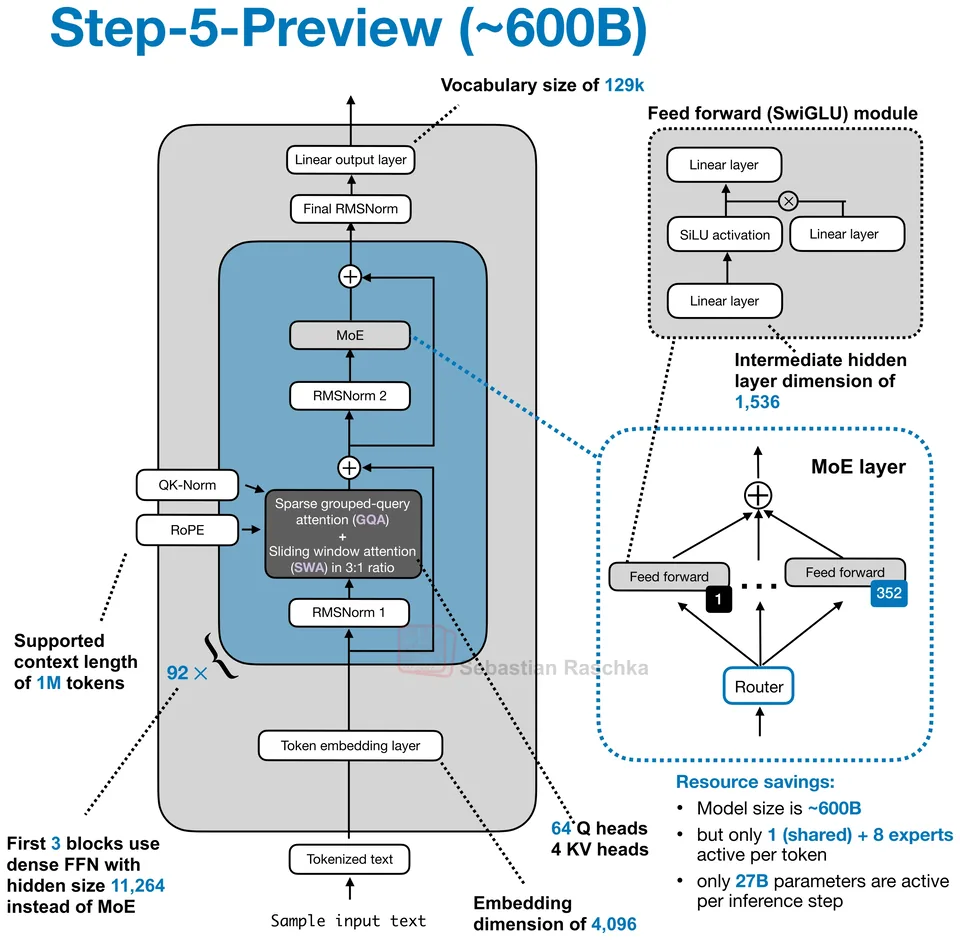
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
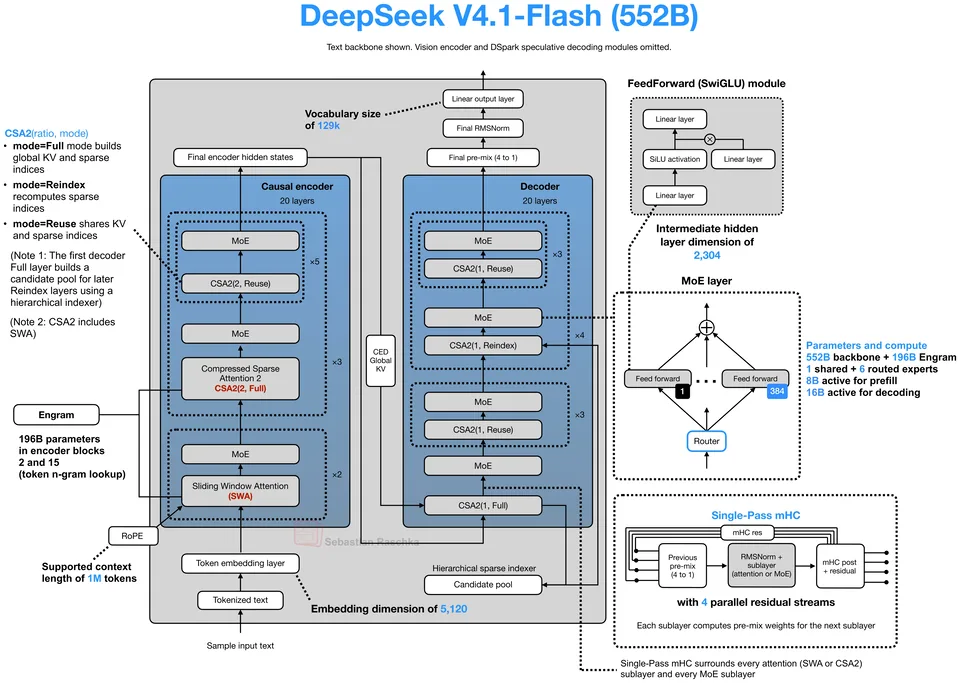
DeepSeek, released 2026-09-10. Sparse MoE decoder, 552B total, 8B active, 1M context. Attention: MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse.
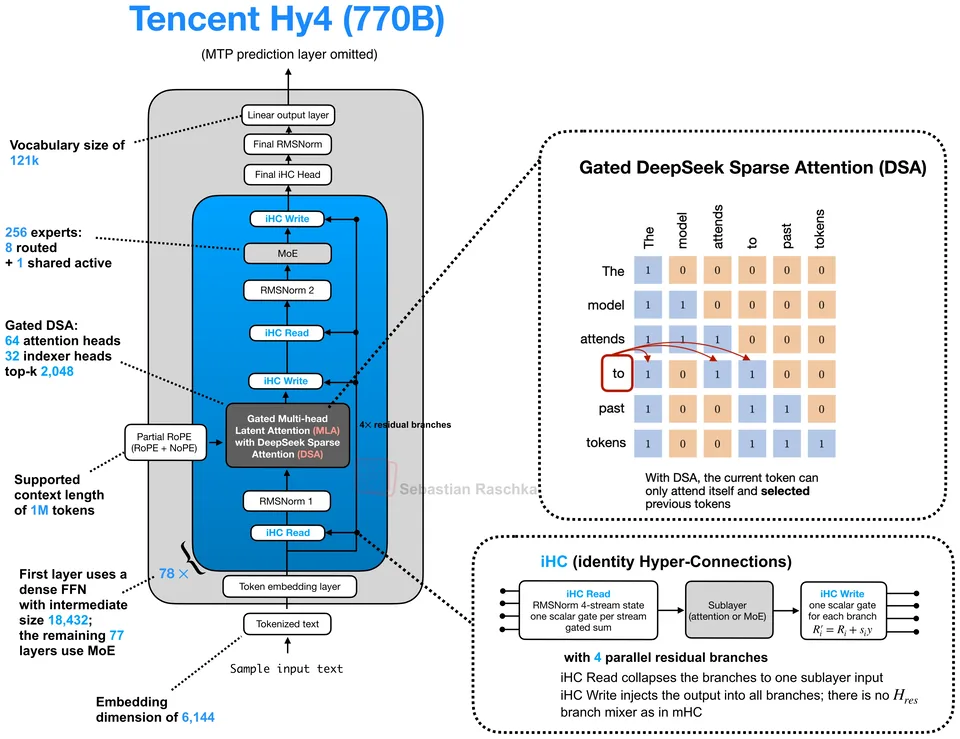
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
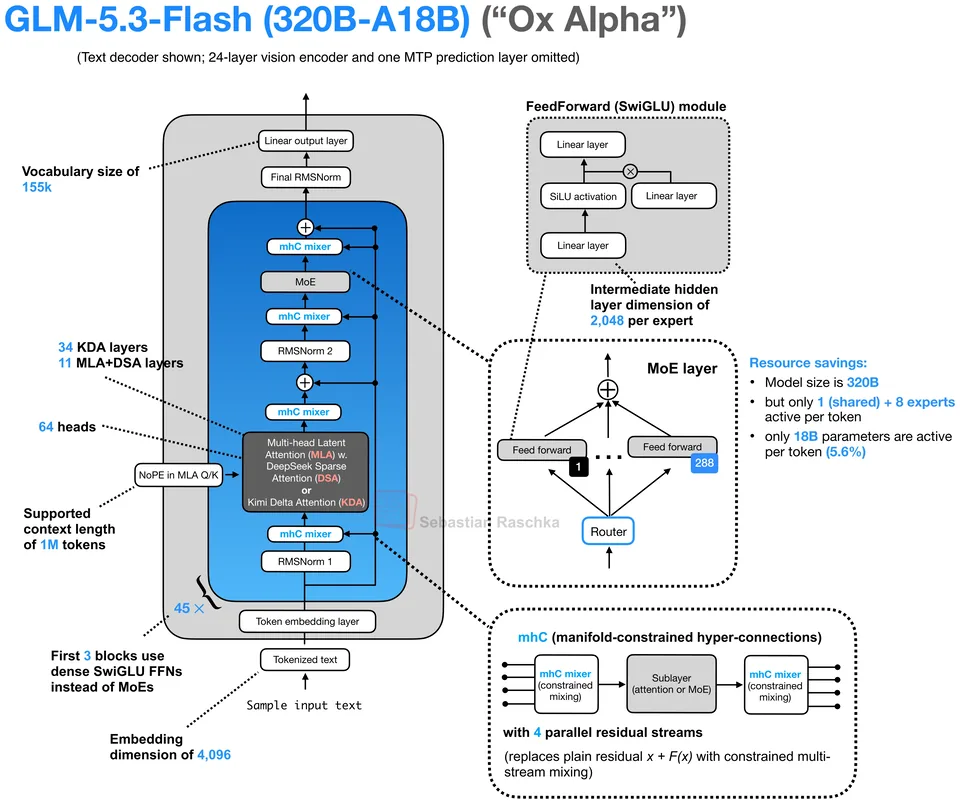
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
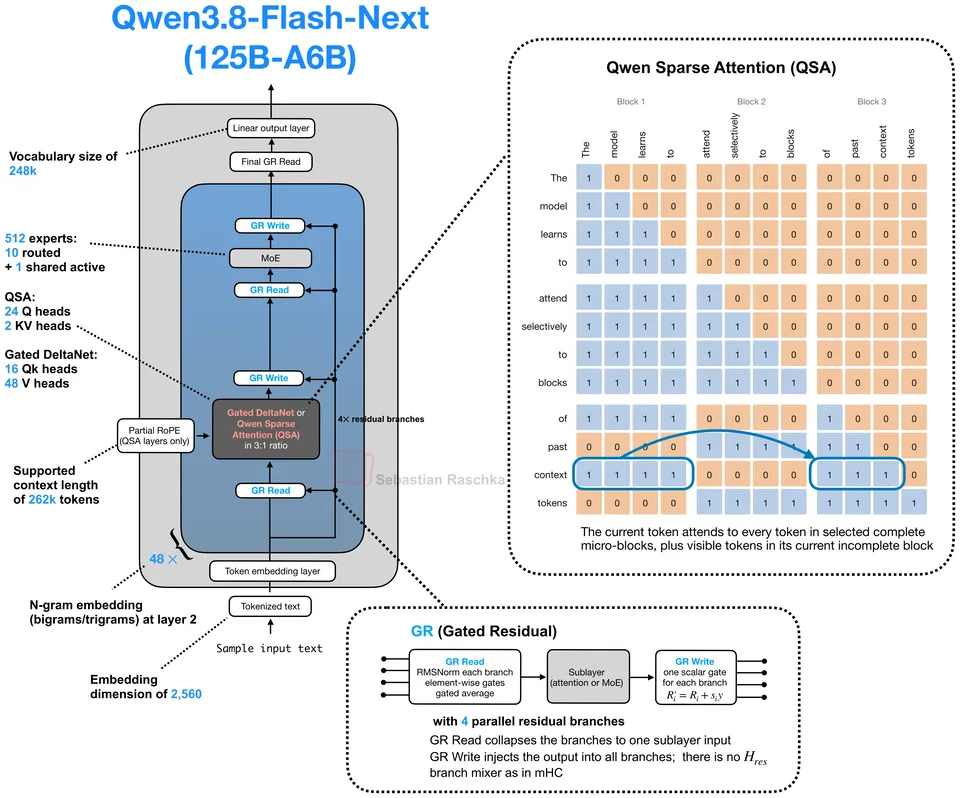
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
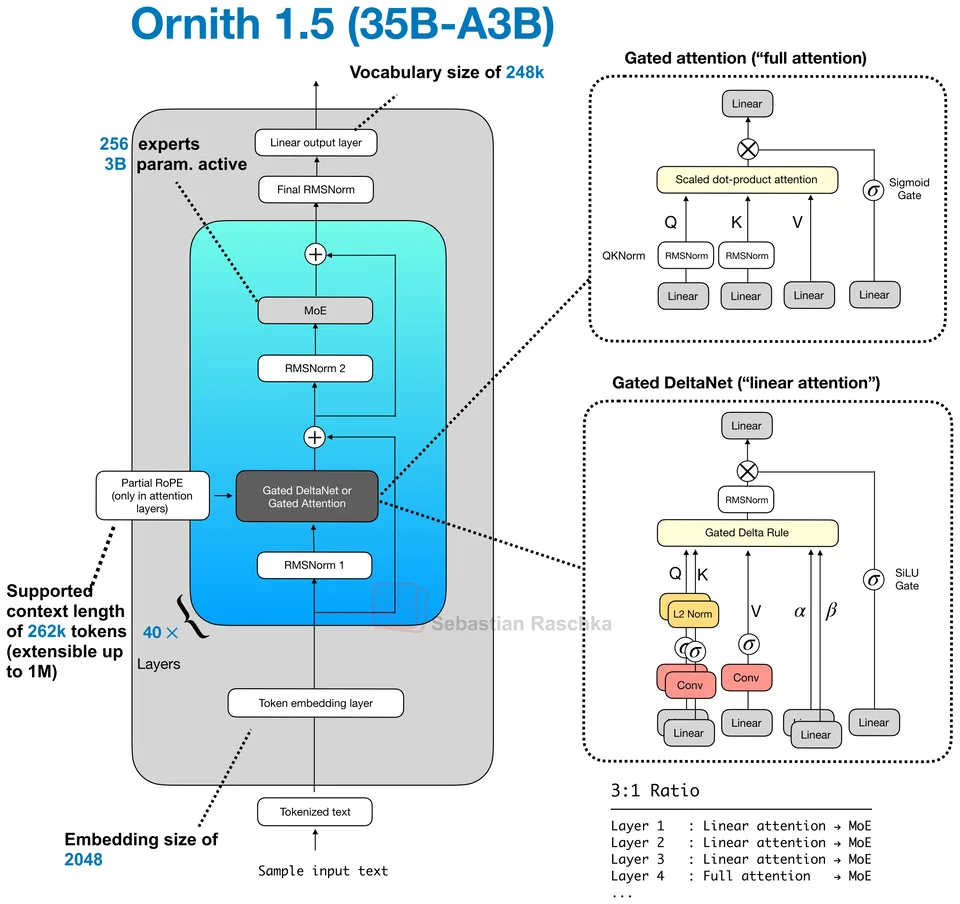
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
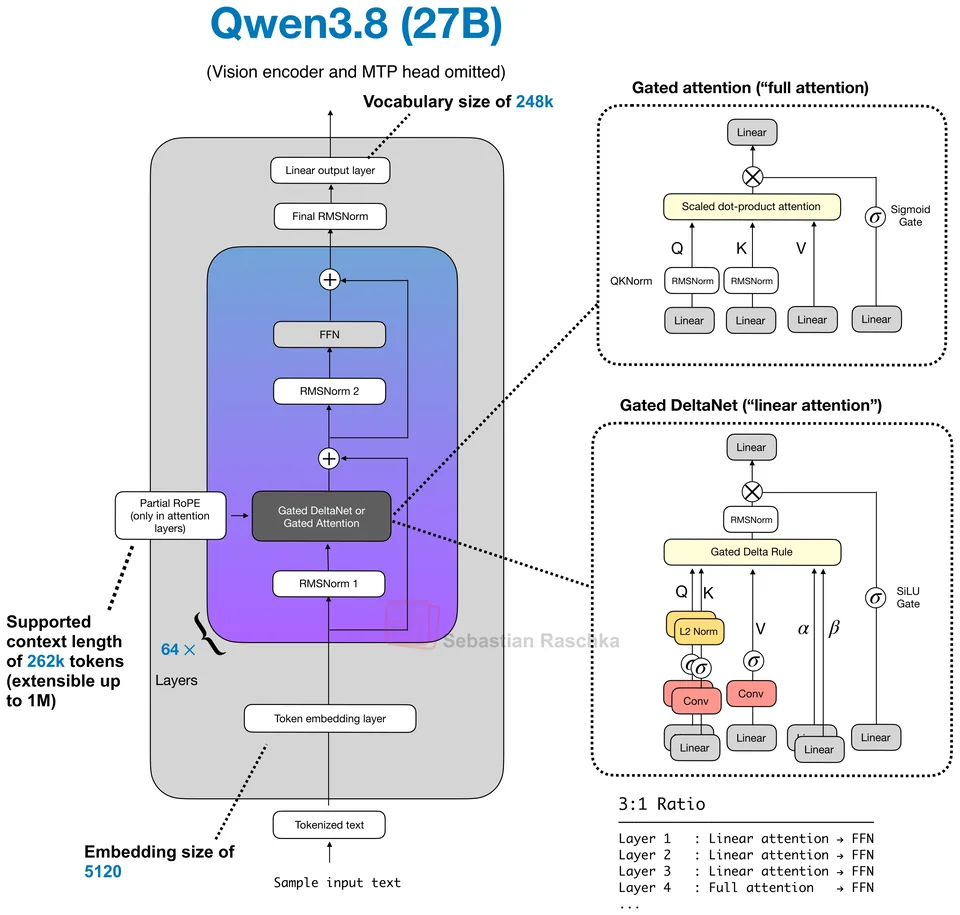
Alibaba Cloud, released 2026-08-14. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

NVIDIA, released 2026-08-11. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with six GQA layers.

Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
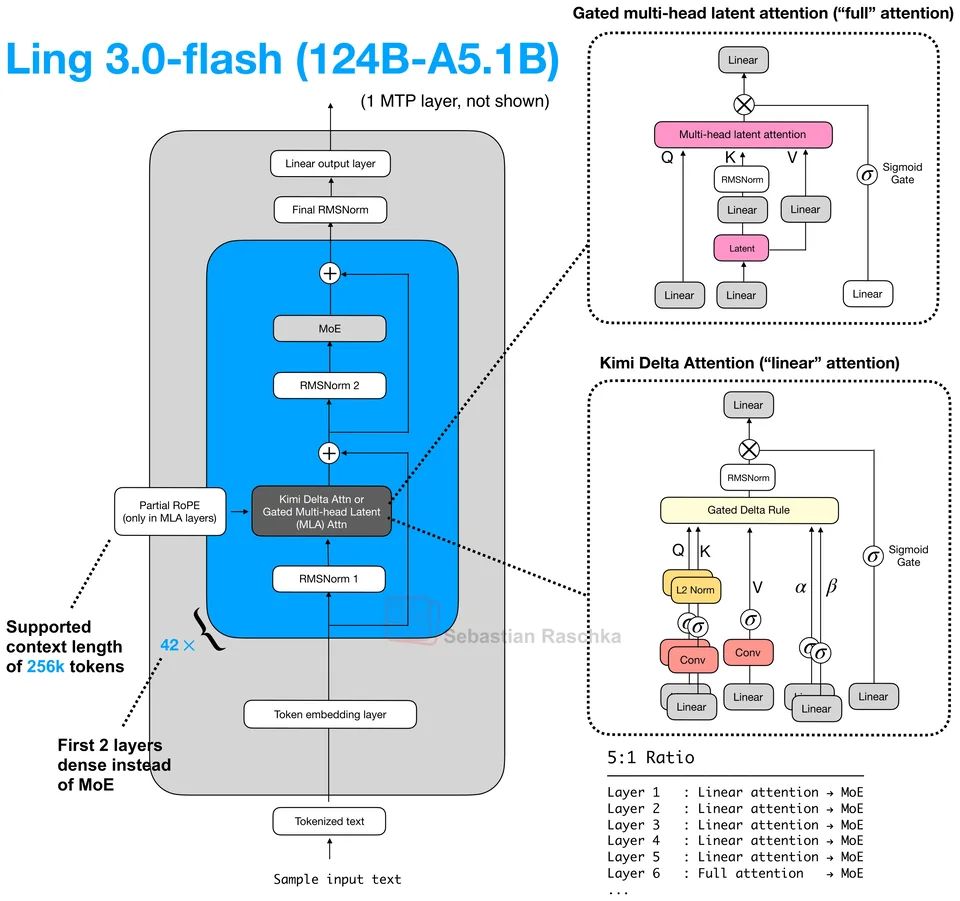
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
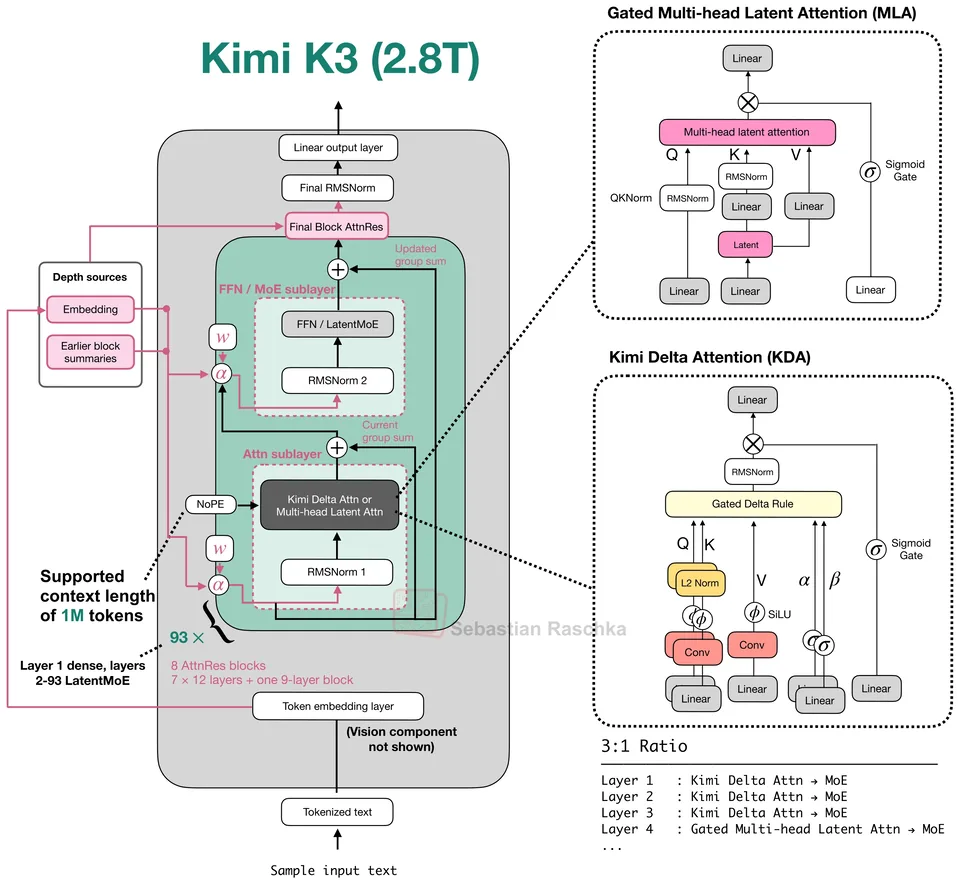
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Upstage, released 2026-07-22. Hybrid MoE decoder, 250B total, 15B active, 1M context. Attention: 3:1 Kimi Delta Attention and gated GQA with NoPE.
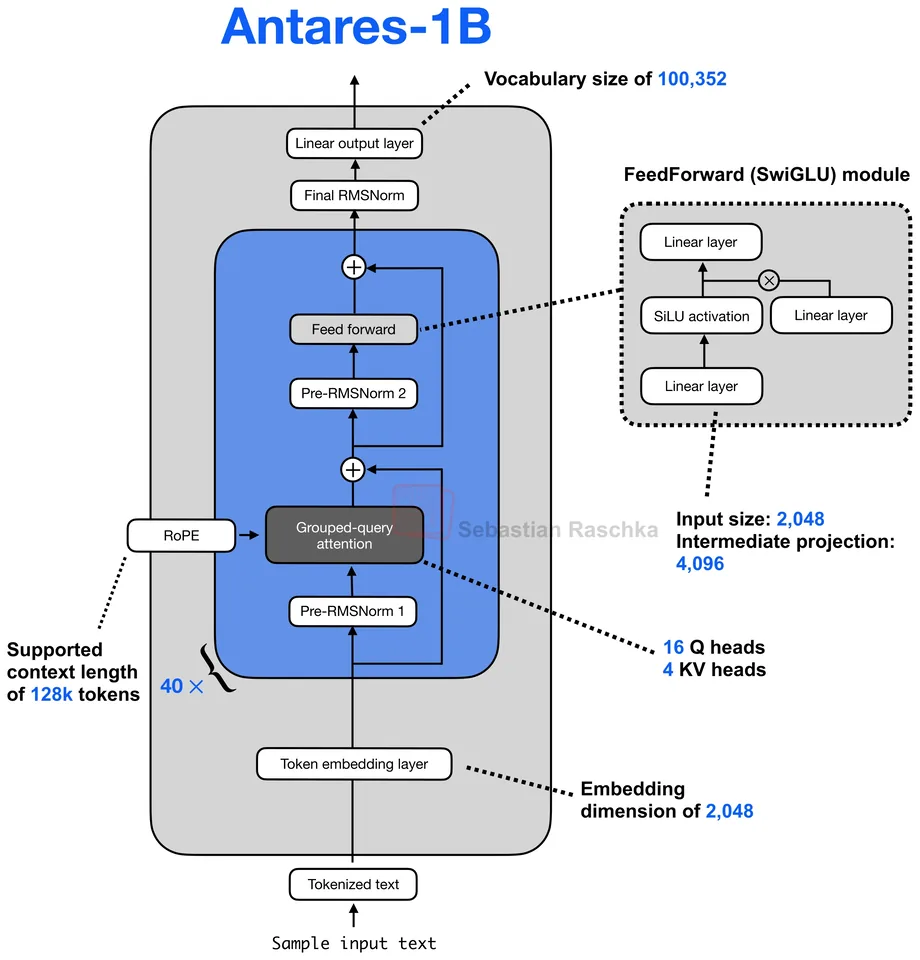
Cisco, released 2026-07-21. Dense decoder, 1B parameters, 128K context. Attention: GQA with RoPE.

Poolside, released 2026-07-21. Sparse MoE decoder, 118B total, 8B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.

Motif Technologies, released 2026-07-21. Sparse MoE decoder, 314B total, 13B active, 256K context. Attention: GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention.

BOSS Zhipin, released 2026-07-21. Dense decoder, 4B parameters, 256K context. Attention: GQA with RoPE.

Bad Theory Labs, released 2026-07-20. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
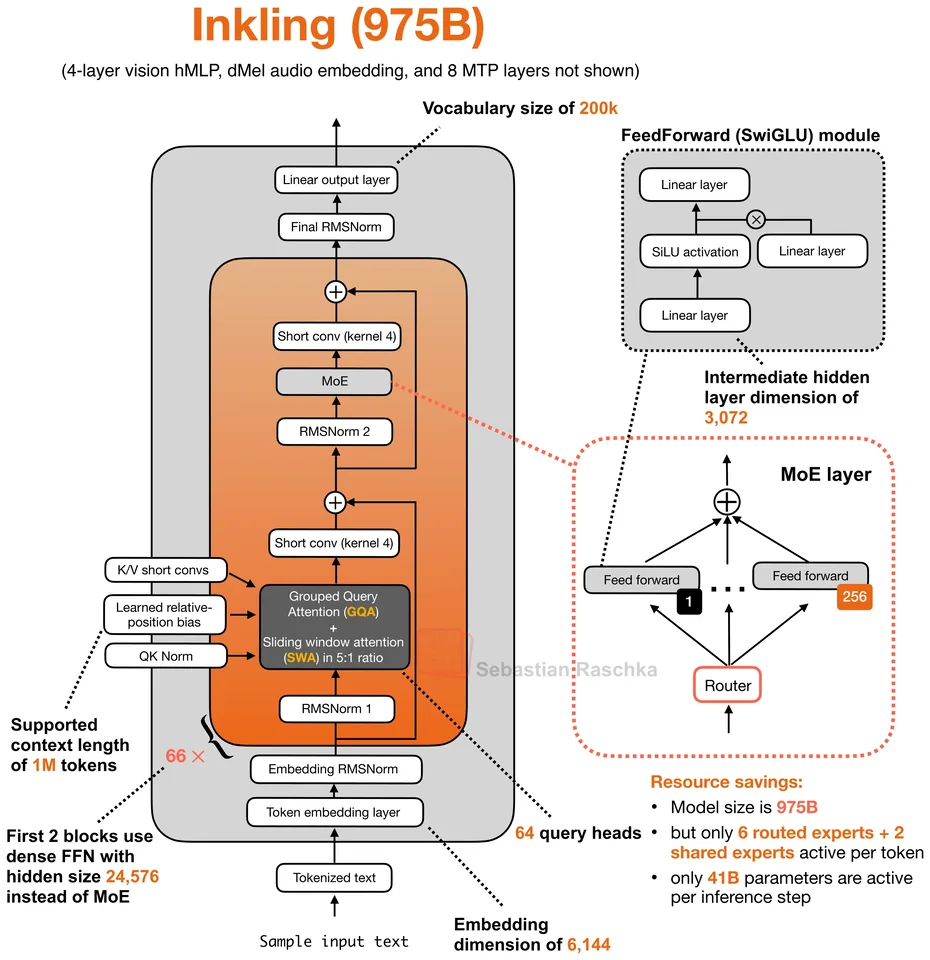
Thinking Machines Lab, released 2026-07-15. Sparse MoE decoder, 975B total, 41B active, 1M context. Attention: GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern.

SOOFI Consortium, released 2026-07-10. Hybrid MoE decoder, 32B total, 3.2B active, 1M context. Attention: Mostly Mamba-2 with 6 GQA layers and no positional embeddings (NoPE).

Poolside, released 2026-07-02. Sparse MoE decoder, 33B total, 3B active, 256K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
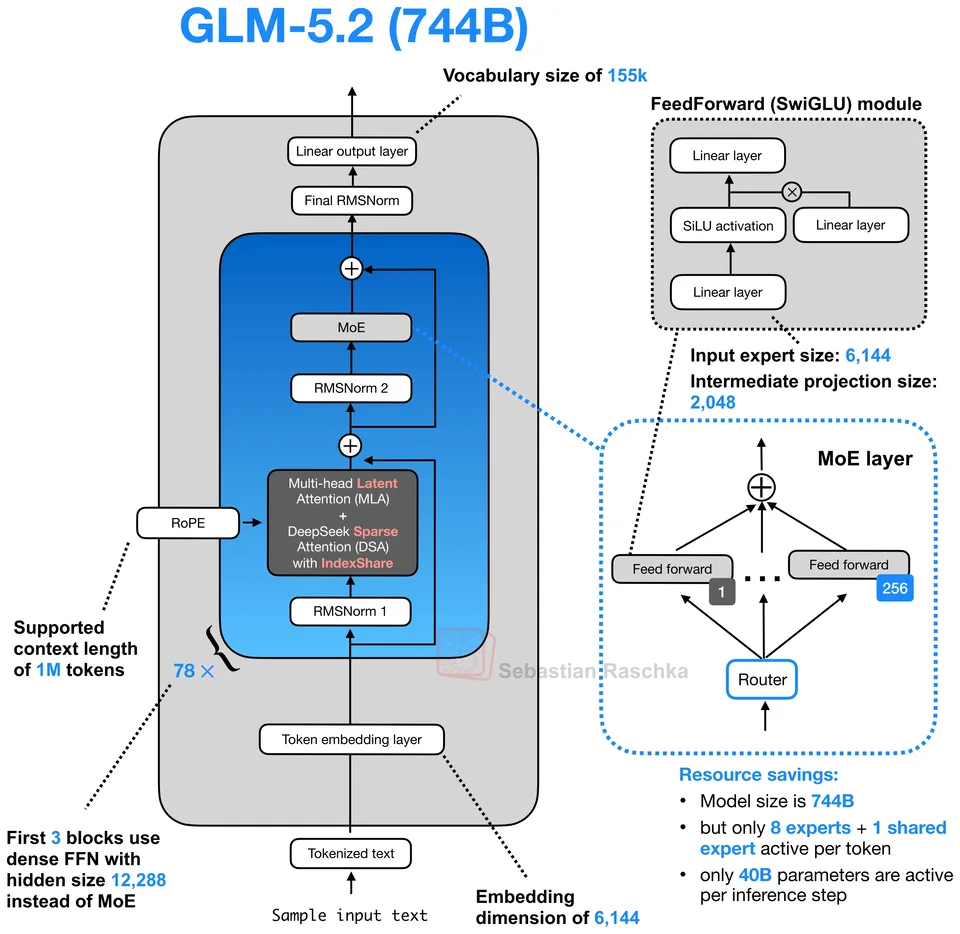
Z.ai, released 2026-06-17. Sparse MoE decoder, 744B total, 40B active, 1M context. Attention: MLA with DeepSeek Sparse Attention and IndexShare.

Weibo, released 2026-06-15. Dense decoder, 3B parameters, 128K context. Attention: 8:1 GQA with RoPE.

MiniMax, released 2026-06-13. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.

Moonshot AI, released 2026-06-12. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Cohere, released 2026-06-05. Sparse MoE decoder, 30B total, 3B active, 256K context. Attention: 8:1 GQA with 3:1 sliding-window/global attention.
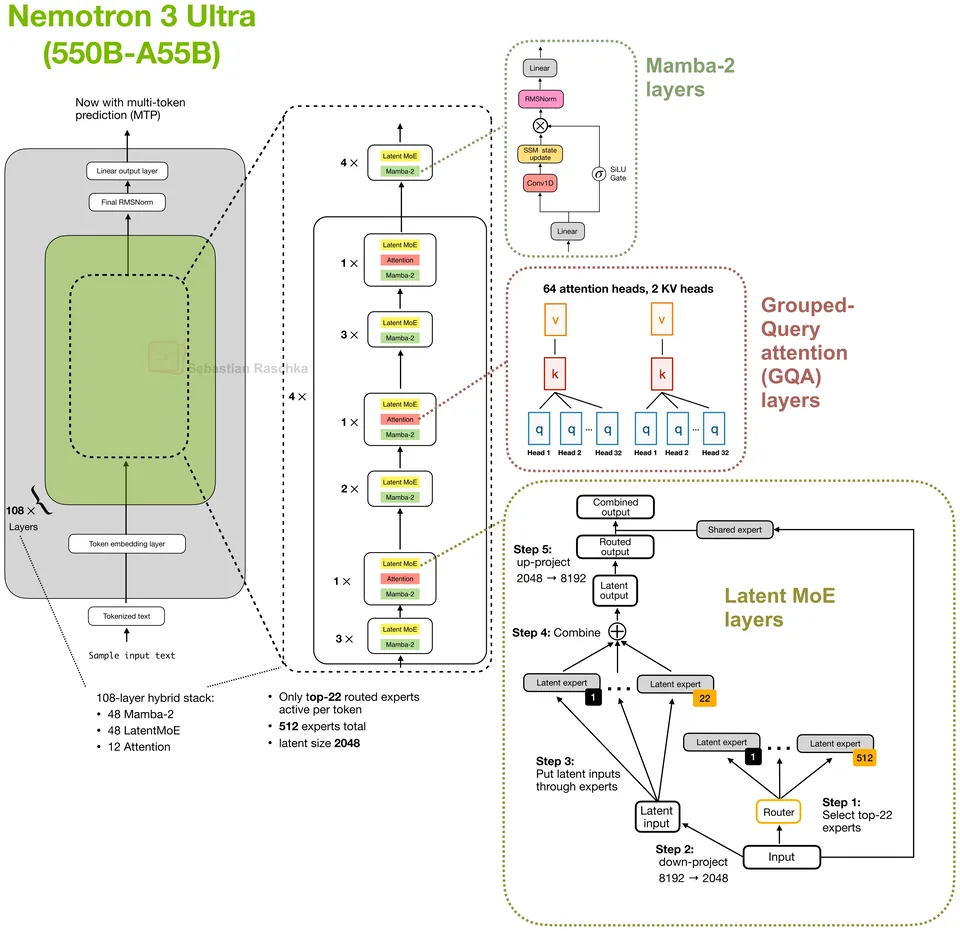
NVIDIA, released 2026-06-04. Hybrid MoE decoder, 550B total, 55B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.

Google, released 2026-06-03. Dense decoder, 12B parameters, 128K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.

JetBrains, released 2026-06-01. Sparse MoE decoder, 12B total, 2.5B active, 128K context. Attention: GQA with 3:1 sliding-window/full attention.

Liquid AI, released 2026-05-28. Dense hybrid decoder, 1.2B parameters, 128K context. Attention: LIV convolution blocks plus GQA.

Liquid AI, released 2026-05-28. Dense hybrid decoder, 350M parameters, 128K context. Attention: LIV convolution blocks plus GQA.

Liquid AI, released 2026-05-28. Hybrid MoE decoder, 8.3B total, 1.5B active, 128K context. Attention: LIV convolution blocks plus GQA and MoE.

Cohere, released 2026-05-20. Sparse MoE decoder, 218B total, 25B active, 128K context. Attention: 16:1 GQA with 3:1 sliding-window/global attention.

Zyphra, released 2026-05-06. Sparse MoE decoder, 8.4B total, 760M active, 128K context. Attention: CCA with 4:1 GQA, RoPE, and Q/K L2 norm.

IBM, released 2026-04-29. Dense decoder, 30B parameters, 128K context. Attention: GQA with RoPE.

Poolside, released 2026-04-28. Sparse MoE decoder, 33B total, 3B active, 128K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
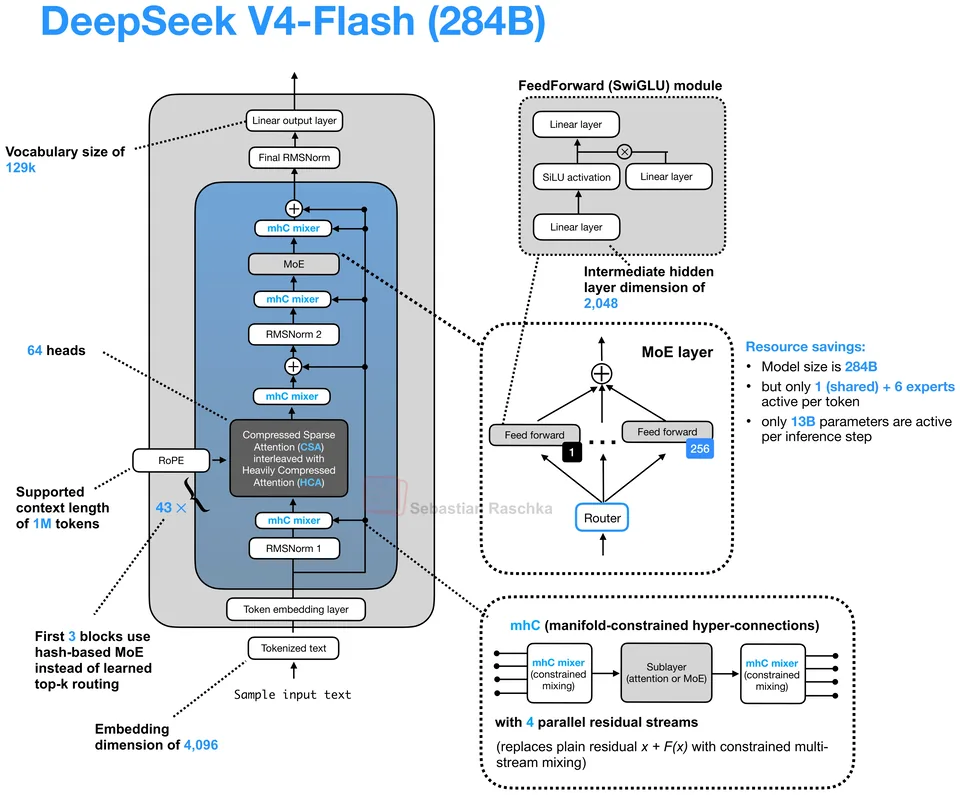
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

DeepSeek, released 2026-04-24. Sparse MoE decoder, 1.6T total, 49B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

InclusionAI, released 2026-04-23. Hybrid MoE decoder, 1T total, 63B active, 256K context. Attention: Lightning Attention plus MLA.

Tencent, released 2026-04-23. Sparse MoE decoder, 295B total, 21B active, 256K context. Attention: GQA with QK-Norm.

Alibaba Cloud, released 2026-04-22. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

Xiaomi, released 2026-04-22. Sparse MoE decoder, 310B total, 15B active, 1M context. Attention: 5:1 sliding-window/global attention.

Xiaomi, released 2026-04-22. Sparse MoE decoder, 1.02T total, 42B active, 1M context. Attention: GQA with 6:1 sliding-window/global attention.
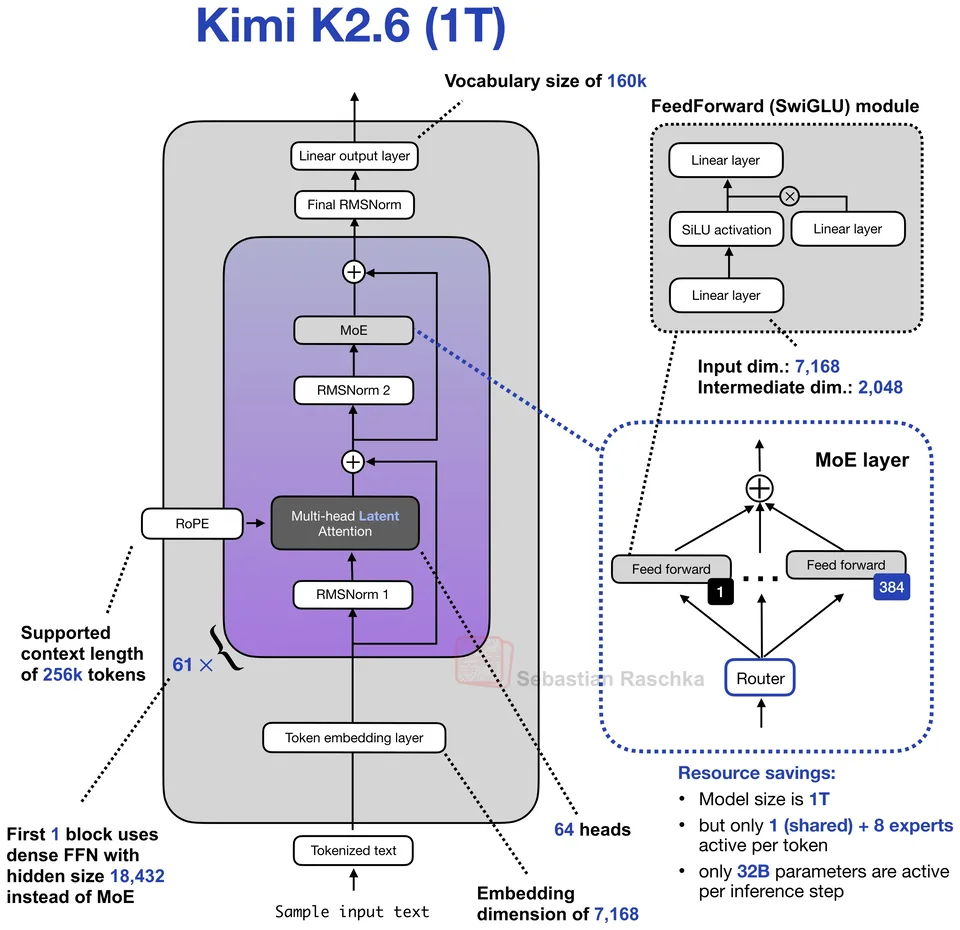
Moonshot AI, released 2026-04-20. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Alibaba Cloud, released 2026-04-15. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

Z.ai, released 2026-04-07. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

Google, released 2026-04-02. Dense decoder, 31B parameters, 256K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.

Google, released 2026-04-02. Sparse MoE decoder, 25B total, 3.8B active, 256K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.

Google, released 2026-04-02. Dense decoder, 5.1B parameters, 128K context. Attention: Multi-query attention with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 4:1 sliding-window/global attention.

Google, released 2026-04-02. Dense decoder, 8B parameters, 128K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.

MiniMax, released 2026-03-18. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.

Mistral AI, released 2026-03-16. Sparse MoE decoder, 119B total, 6.6B active, 256K context. Attention: MLA.

NVIDIA, released 2026-03-16. Dense hybrid decoder, 4B parameters, 256K context. Attention: GQA with only 4 attention layers.

NVIDIA, released 2026-03-11. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.

Sarvam AI, released 2026-03-03. Sparse MoE decoder, 30B total, 2.4B active, 128K context. Attention: GQA with QK-Norm.

Sarvam AI, released 2026-03-03. Sparse MoE decoder, 105B total, 10B active, 128K context. Attention: MLA with KV LayerNorm and NoPE + RoPE.

Alibaba Cloud, released 2026-02-16. Hybrid MoE decoder, 397B total, 17B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

InclusionAI, released 2026-02-15. Hybrid MoE decoder, 1T total, 63B active, 256K context. Attention: Lightning Attention plus MLA.

Cohere, released 2026-02-13. Dense decoder, 3.4B parameters, 8K context. Attention: GQA with 3:1 sliding-window attention.

MiniMax, released 2026-02-12. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

BOSS Zhipin, released 2026-02-10. Dense decoder, 3B parameters, 256K context. Attention: GQA.

StepFun, released 2026-02-01. Sparse MoE decoder, 196B total, 11B active, 256K context. Attention: GQA with 3:1 sliding-window attention.

Meituan, released 2026-01-28. Sparse MoE decoder, 69B total, 3B active, 256K context. Attention: MLA with RoPE + NoPE.

Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.

Moonshot AI, released 2026-01-27. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Z.ai, released 2025-12-22. Sparse MoE decoder, 355B total, 32B active, 198K context. Attention: GQA with QK-Norm.

Xiaomi, released 2025-12-16. Sparse MoE decoder, 309B total, 15B active, 256K context. Attention: 5:1 sliding-window/global attention.

NVIDIA, released 2025-12-04. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.

Mistral AI, released 2025-12-02. Sparse MoE decoder, 673B total, 41B active, 256K context. Attention: MLA.

DeepSeek, released 2025-12-01. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA with DeepSeek Sparse Attention.

Prime Intellect, released 2025-11-26. Sparse MoE decoder, 106B total, 12B active, 128K context. Attention: GQA.

Ai2, released 2025-11-20. Dense decoder, 32B parameters, 64K context. Attention: GQA with QK-Norm and 3:1 sliding-window/global attention.

Ai2, released 2025-11-20. Dense decoder, 7B parameters, 64K context. Attention: MHA with QK-Norm and 3:1 sliding-window/global attention.

Moonshot AI, released 2025-10-30. Hybrid MoE decoder, 48B total, 3B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA.
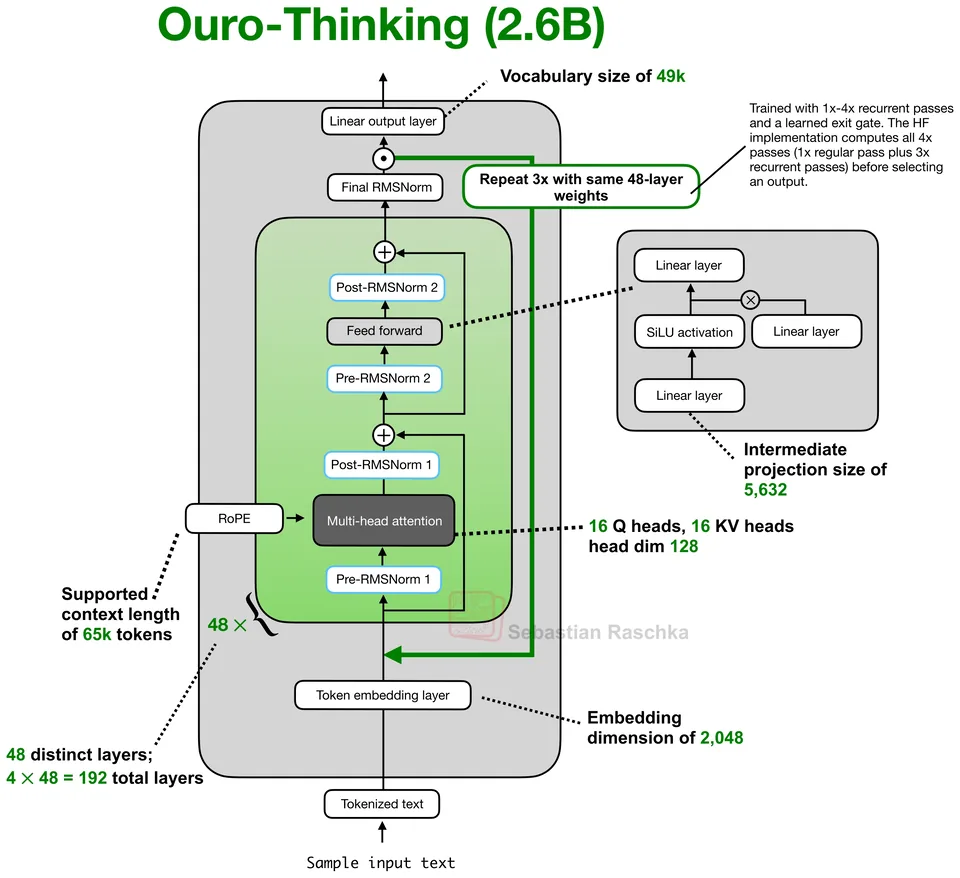
ByteDance, released 2025-10-29. Dense decoder, 2.6B parameters, 64K context. Attention: MHA with RoPE.

MiniMax, released 2025-10-23. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm and partial RoPE.

Alibaba Cloud, released 2025-09-09. Hybrid MoE decoder, 80B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

xAI, released 2025-08-22. Sparse MoE decoder, 270B parameters, 128K context. Attention: GQA.

Google, released 2025-08-14. Dense decoder, 270M parameters, 128K context. Attention: Multi-query attention with QK-Norm and 5:1 sliding-window/global attention.
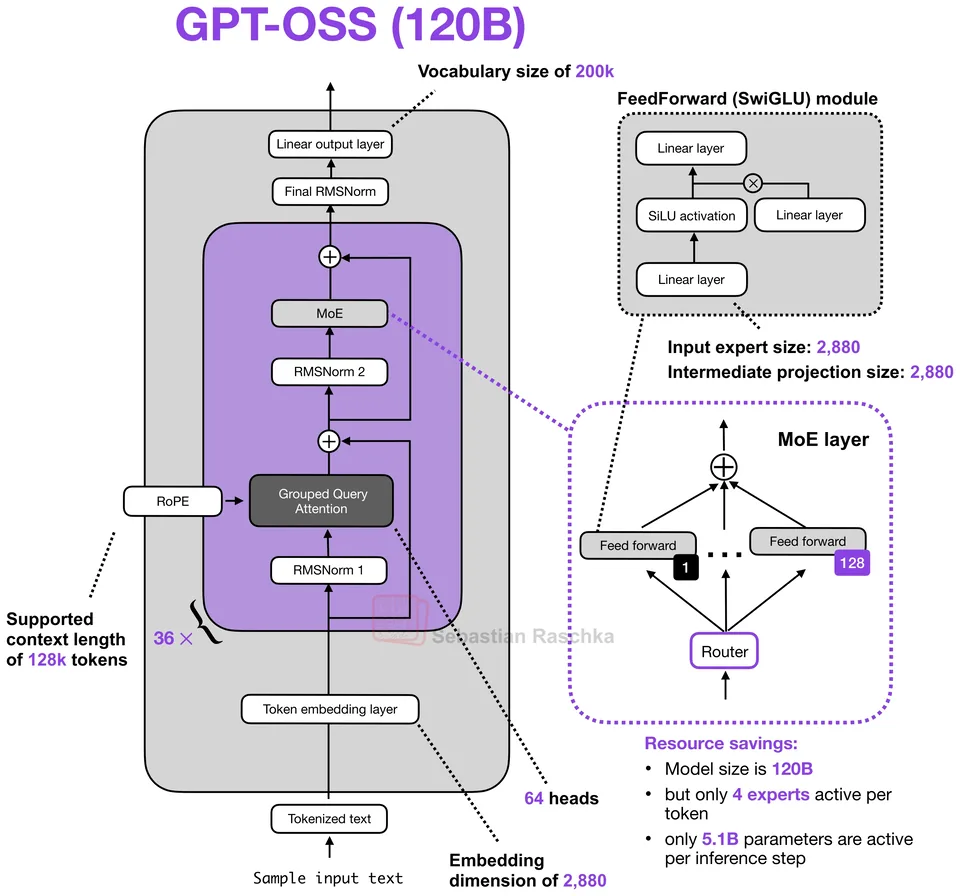
OpenAI, released 2025-08-04. Sparse MoE decoder, 117B total, 5.1B active, 128K context. Attention: GQA with alternating sliding-window and global layers.

OpenAI, released 2025-08-04. Sparse MoE decoder, 21B total, 3.6B active, 128K context. Attention: GQA with alternating sliding-window and global layers.

Alibaba Cloud, released 2025-07-31. Sparse MoE decoder, 30B total, 3.3B active, 256K context. Attention: GQA.

Z.ai, released 2025-07-28. Sparse MoE decoder, 355B total, 32B active, 128K context. Attention: GQA with QK-Norm.

Z.ai, released 2025-07-28. Sparse MoE decoder, 106B total, 12B active, 128K context. Attention: GQA.

Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.

Hugging Face, released 2025-06-19. Dense decoder, 3B parameters, 128K context. Attention: GQA with periodic NoPE layers.

Alibaba Cloud, released 2025-04-28. Dense decoder, 600M parameters, 32K context. Attention: GQA.
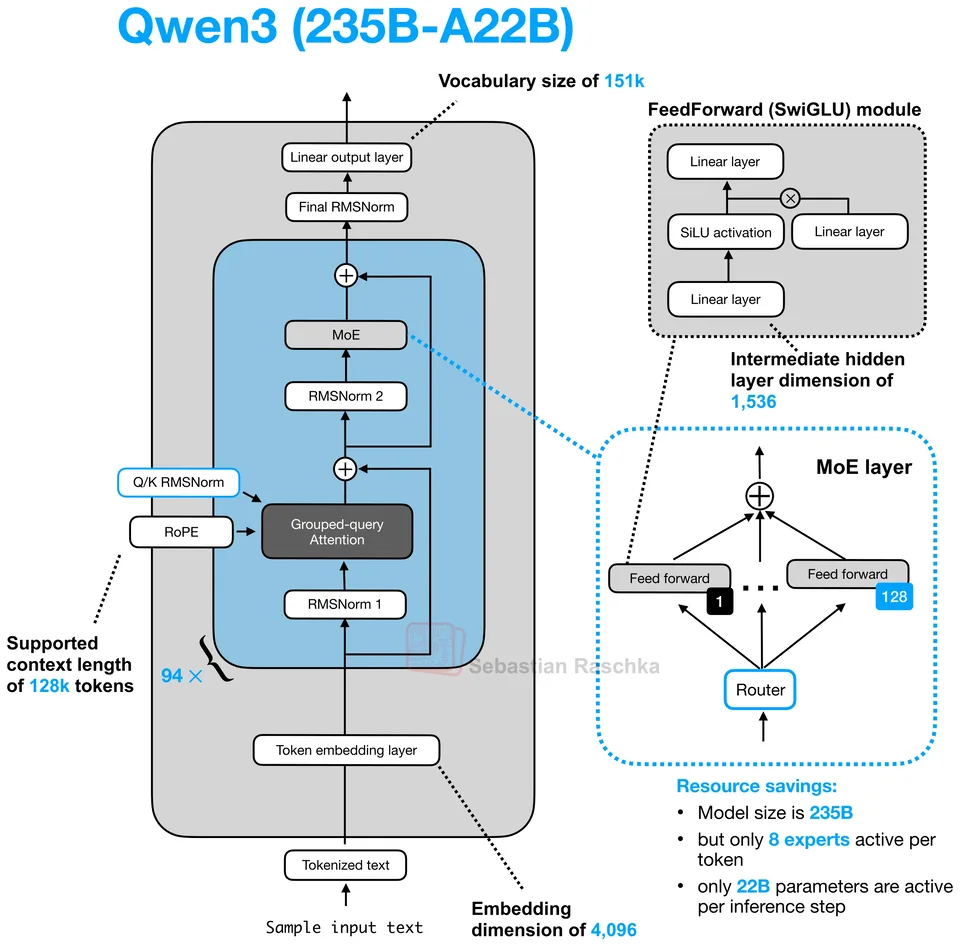
Alibaba Cloud, released 2025-04-28. Sparse MoE decoder, 235B total, 22B active, 128K context. Attention: GQA with QK-Norm.

Alibaba Cloud, released 2025-04-28. Sparse MoE decoder, 30B total, 3B active, 128K context. Attention: GQA.

Alibaba Cloud, released 2025-04-28. Dense decoder, 32B parameters, 128K context. Attention: GQA with QK-Norm.

Alibaba Cloud, released 2025-04-28. Dense decoder, 4B parameters, 32K context. Attention: GQA with QK-Norm.

Alibaba Cloud, released 2025-04-28. Dense decoder, 8B parameters, 128K context. Attention: GQA with QK-Norm.

Meta, released 2025-04-05. Sparse MoE decoder, 400B total, 17B active, 1M context. Attention: GQA.

Mistral AI, released 2025-03-18. Dense decoder, 24B parameters, 128K context. Attention: Standard GQA.

NXAI, released 2025-03-17. Recurrent decoder, 7B parameters, — context. Attention: No self-attention; mLSTM recurrent layers with matrix memory.

Google, released 2025-03-11. Dense decoder, 27B parameters, 128K context. Attention: GQA with QK-Norm and 5:1 sliding-window/global attention.
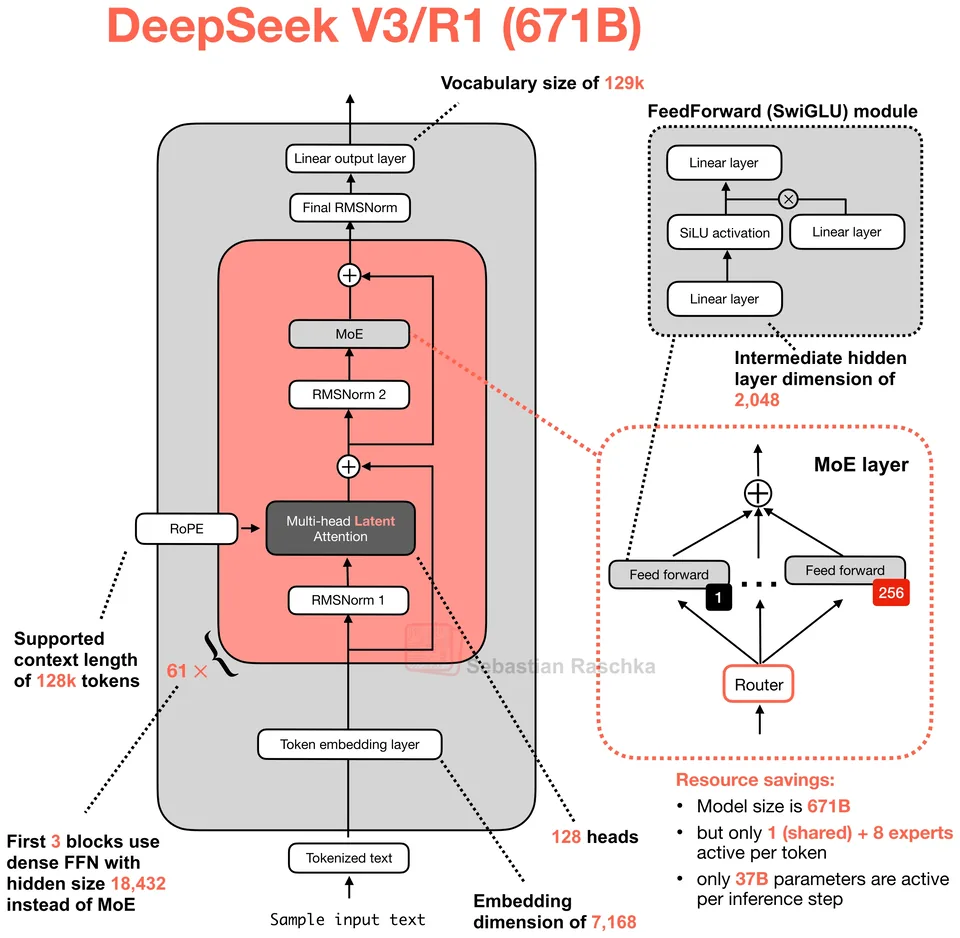
DeepSeek, released 2025-01-20. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.
DeepSeek, released 2024-12-26. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.

Microsoft, released 2024-12-12. Dense decoder, 14B parameters, 16K context. Attention: GQA with RoPE.

Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.

Meta, released 2024-09-25. Dense decoder, 1B parameters, 128K context. Attention: GQA.

Meta, released 2024-09-25. Dense decoder, 3B parameters, 128K context. Attention: GQA.
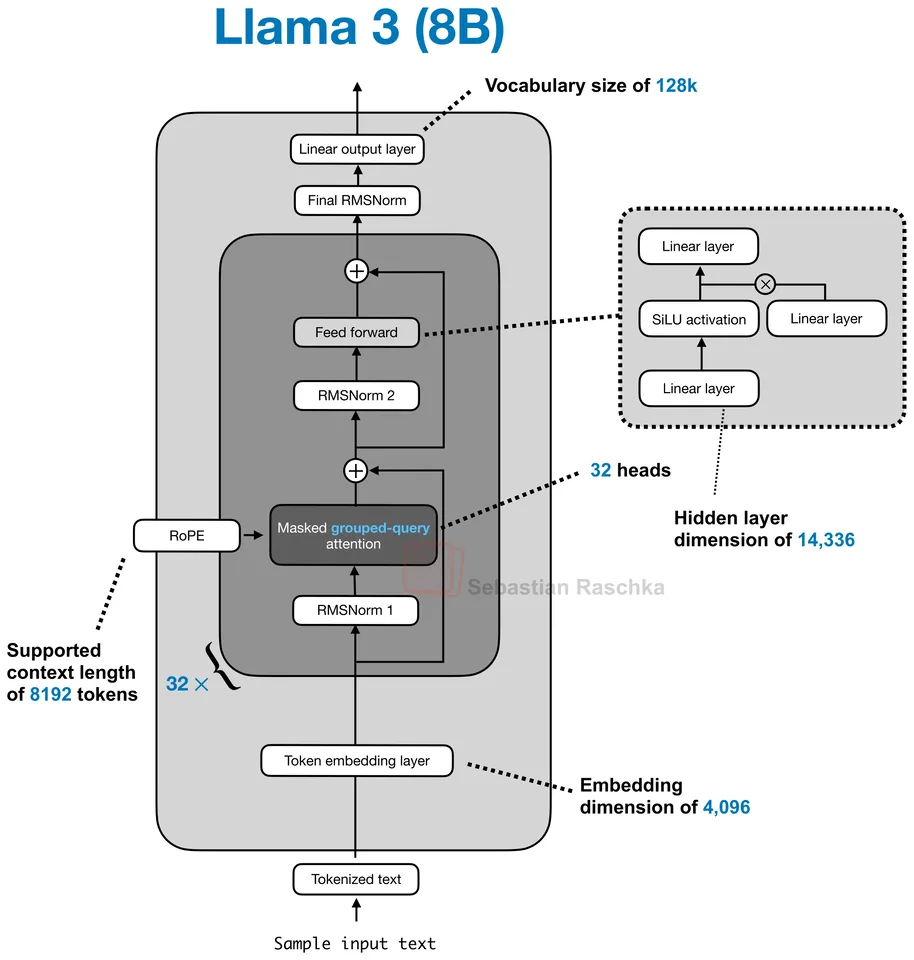
Meta, released 2024-04-18. Dense decoder, 8B parameters, 8K context. Attention: GQA with RoPE.

OpenAI, released 2019-11-05. Dense decoder, 1.5B parameters, 1K context. Attention: MHA with learned absolute positional embeddings.
Jump to a model, concept or page