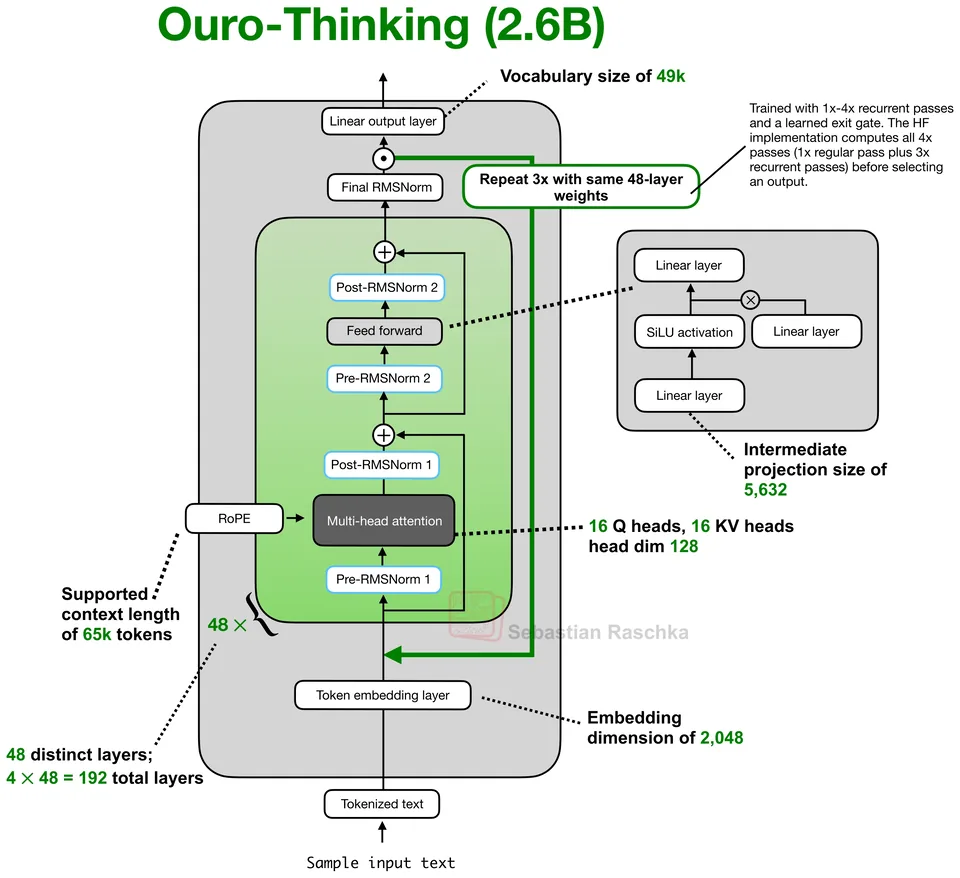
ByteDance, released 2025-10-29. Dense decoder, 2.6B parameters, 64K context. Attention: MHA with RoPE.
Late-2019 dense baseline included here as a reference point for how much decoder stacks have changed since GPT-2.
Key detail
Classic GPT-2 recipe with dropout, GELU, LayerNorm, and full multi-head attention.Parameters
1.5B
Context
1K
KV / token
300 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
Use the ← and → keys to step through releases.
ByteDance, released 2025-10-29. Dense decoder, 2.6B parameters, 64K context. Attention: MHA with RoPE.

Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.

Ai2, released 2025-11-20. Dense decoder, 7B parameters, 64K context. Attention: MHA with QK-Norm and 3:1 sliding-window/global attention.

Meta, released 2024-09-25. Dense decoder, 1B parameters, 128K context. Attention: GQA.
Jump to a model, concept or page