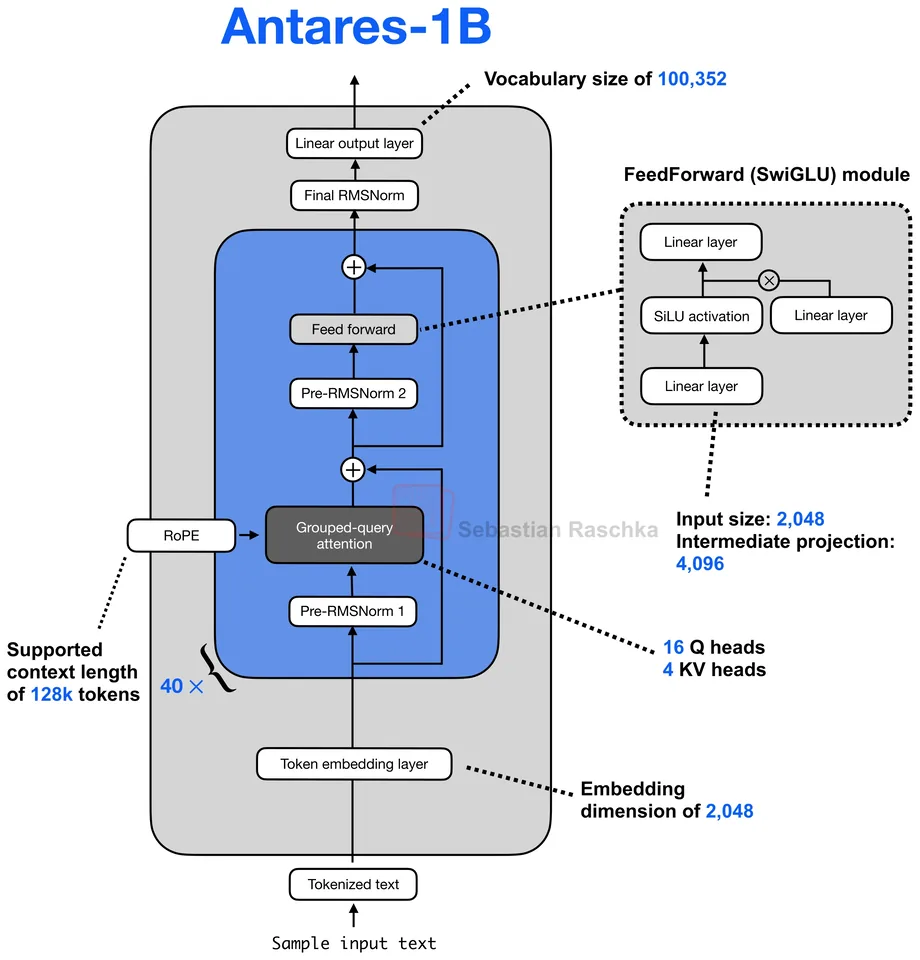
Cisco, released 2026-07-21. Dense decoder, 1B parameters, 128K context. Attention: GQA with RoPE.
Small dense Llama baseline in the Qwen comparison, with fewer layers but more width.
Key detail
Wider architecture with more heads than Qwen3 0.6B.Parameters
1B
Context
128K
KV / token
32 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
4.8
Use the ← and → keys to step through releases.
Cisco, released 2026-07-21. Dense decoder, 1B parameters, 128K context. Attention: GQA with RoPE.

Alibaba Cloud, released 2025-04-28. Dense decoder, 600M parameters, 32K context. Attention: GQA.

Hugging Face, released 2025-06-19. Dense decoder, 3B parameters, 128K context. Attention: GQA with periodic NoPE layers.

Meta, released 2024-09-25. Dense decoder, 3B parameters, 128K context. Attention: GQA.
Jump to a model, concept or page