
Meta, released 2024-09-25. Dense decoder, 1B parameters, 128K context. Attention: GQA.
Tiny current-generation Qwen model that trades width for more depth and a low memory footprint.
Key detail
Deeper than Llama 3.2 1B and unusually practical for local experiments and teaching.Parameters
600M
Context
32K
KV / token
112 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
4.8
Use the ← and → keys to step through releases.
Meta, released 2024-09-25. Dense decoder, 1B parameters, 128K context. Attention: GQA.
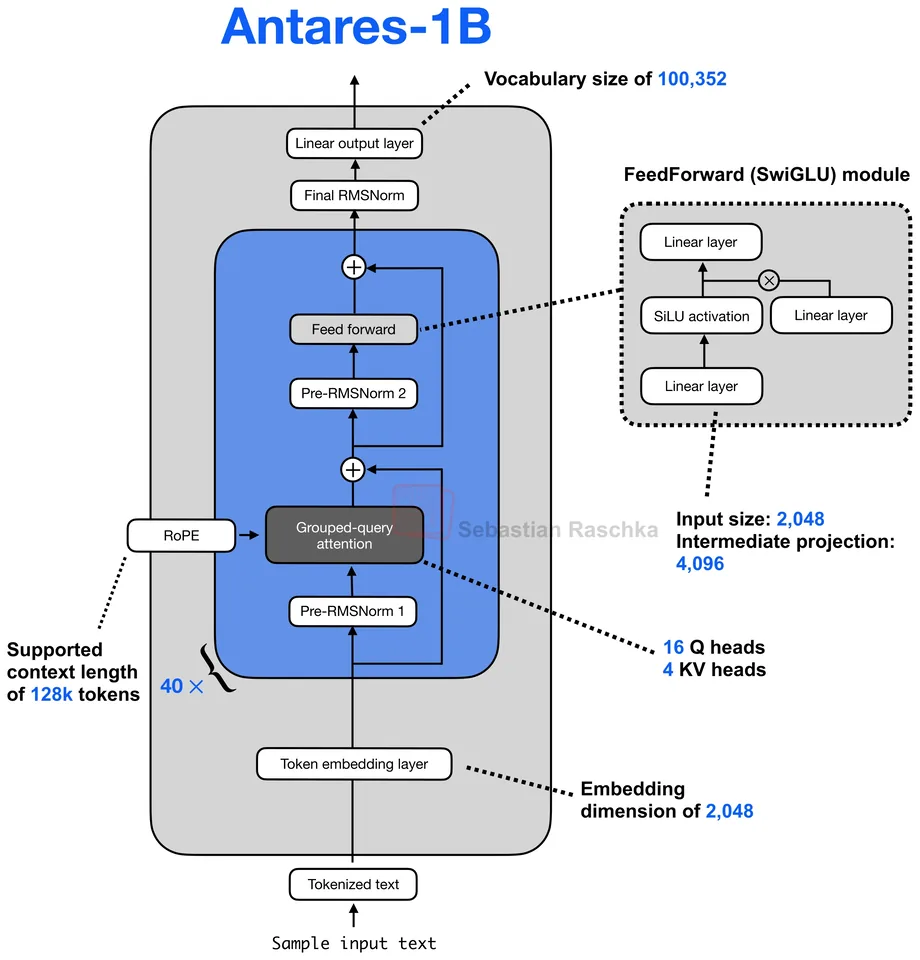
Cisco, released 2026-07-21. Dense decoder, 1B parameters, 128K context. Attention: GQA with RoPE.

Hugging Face, released 2025-06-19. Dense decoder, 3B parameters, 128K context. Attention: GQA with periodic NoPE layers.

Meta, released 2024-09-25. Dense decoder, 3B parameters, 128K context. Attention: GQA.
Jump to a model, concept or page