118 releases
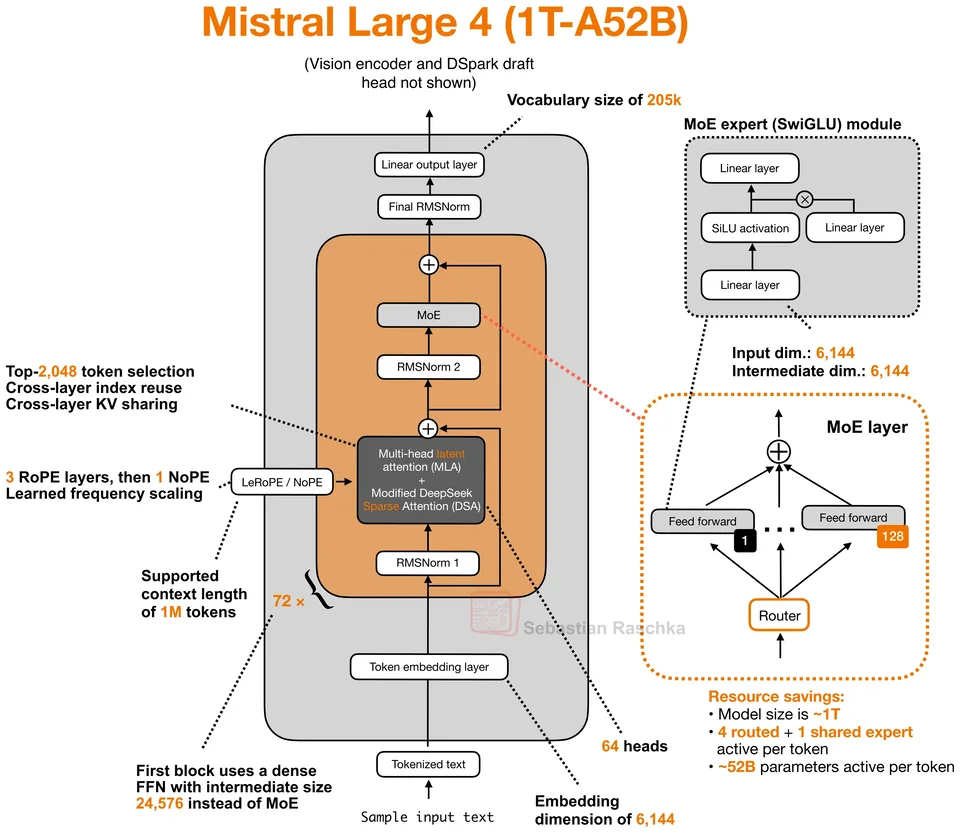
Mistral's trillion-parameter multimodal MoE combines MLA with sparse token selection and cross-layer KV sharing.
1T total · 52B active · MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing
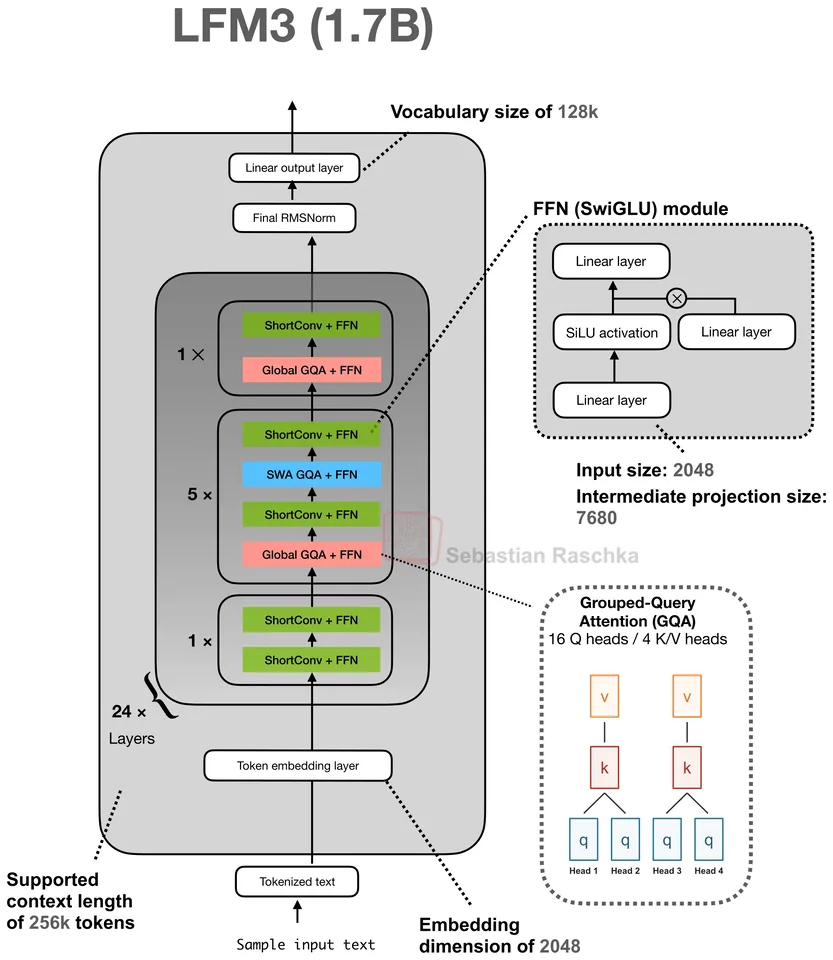
Liquid AI's 1.73B dense hybrid combines short convolutions with sliding-window and global GQA in a 24-layer stack.
1.7B params · ShortConv plus gated GQA with QK-Norm and sliding-window/global attention
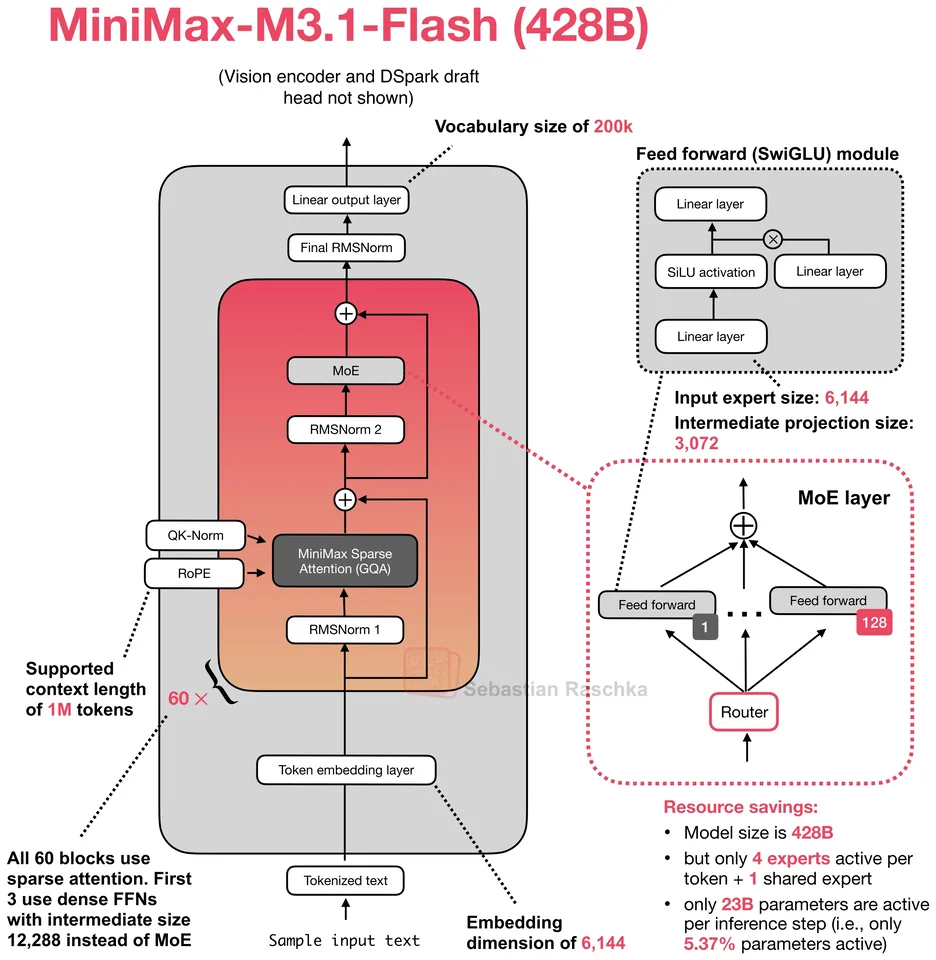
MiniMax M3 successor with sparse attention in all 60 decoder layers, quantization-aware training, and a DSpark draft head for speculative decoding.
428B total · 23B active · GQA with QK-Norm and MiniMax Sparse Attention
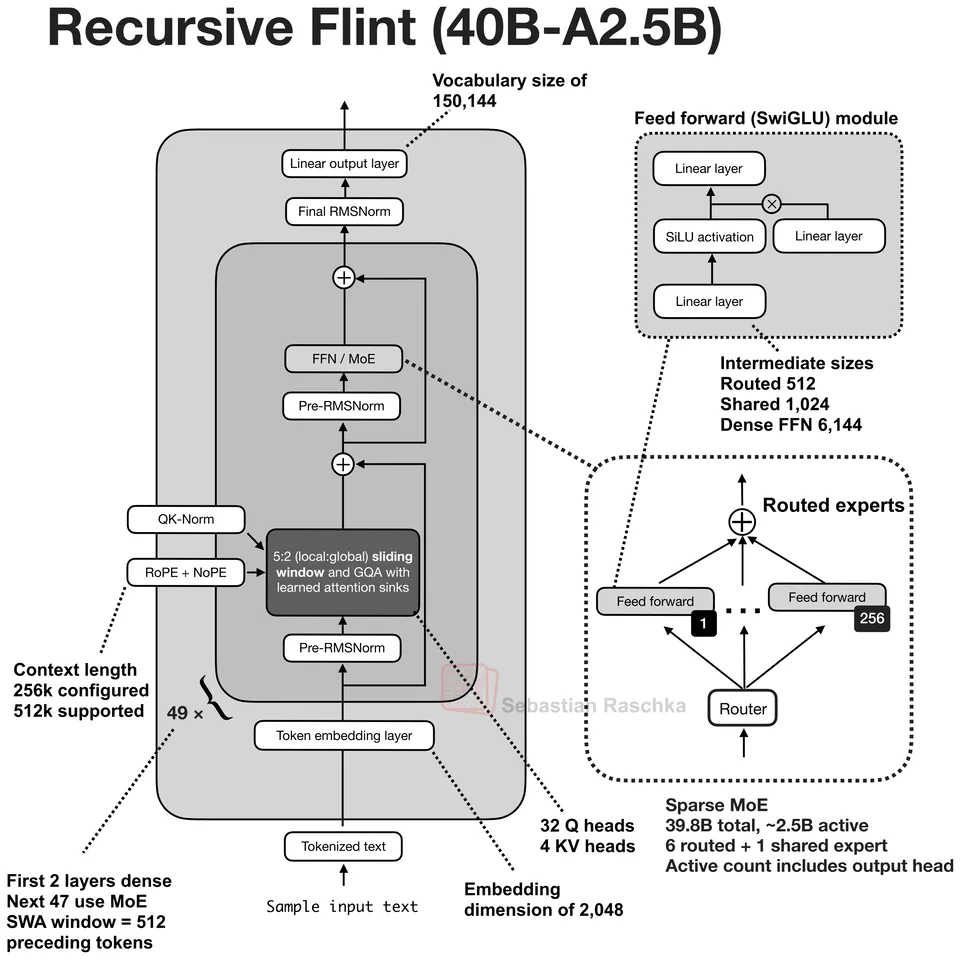
Recursive's coding model uses two dense FFN layers followed by 47 MoE layers. The active-parameter count includes the output head.
40B total · 2.5B active · GQA with QK-Norm, learned attention sinks, and sliding-window/global attention
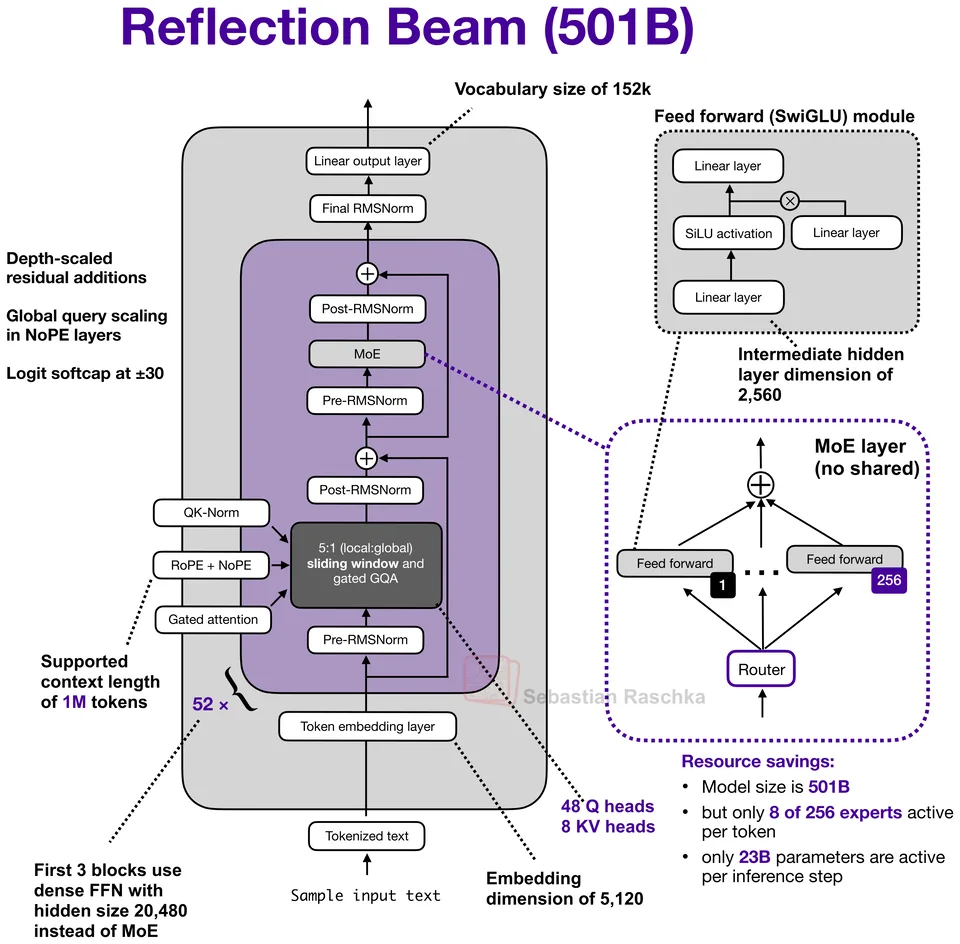
Text-only MoE decoder with three dense FFN layers followed by 49 expert layers. Each MoE layer activates 8 of 256 experts without a shared expert.
501B total · 23B active · Gated GQA with QK-Norm and sliding-window/global attention
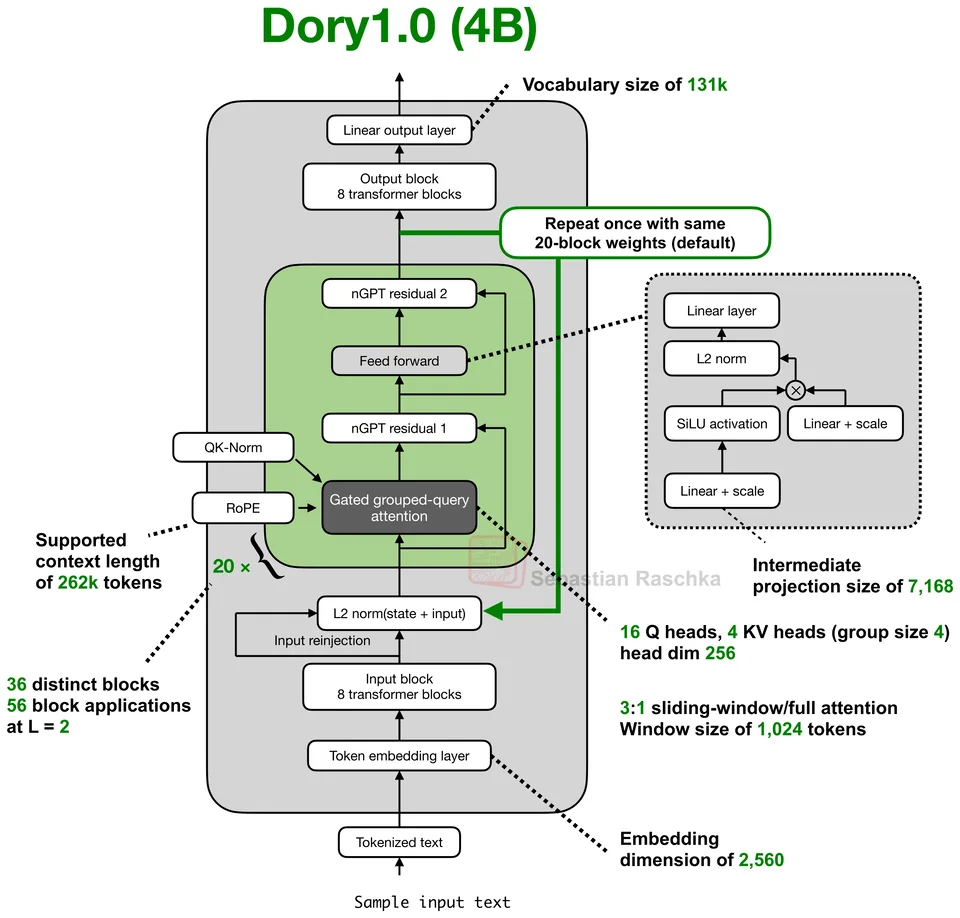
NVIDIA's dense looped transformer applies a shared 20-block core twice between 8-block input and output stacks, using normalized GPT (nGPT) residual updates.
4B params · Gated GQA; 3:1 sliding-window/full, RoPE
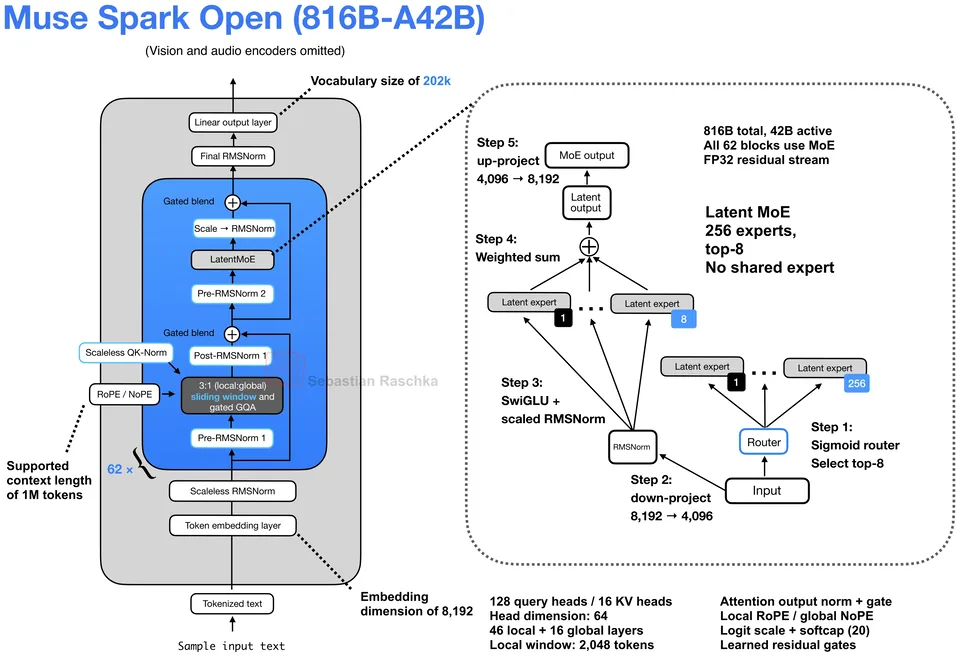
Meta's multimodal MoE model combines 62 latent-expert blocks with gated GQA, local-only RoPE, global NoPE, and learned residual gates; the figure focuses on the text decoder.
816B total · 42B active · Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
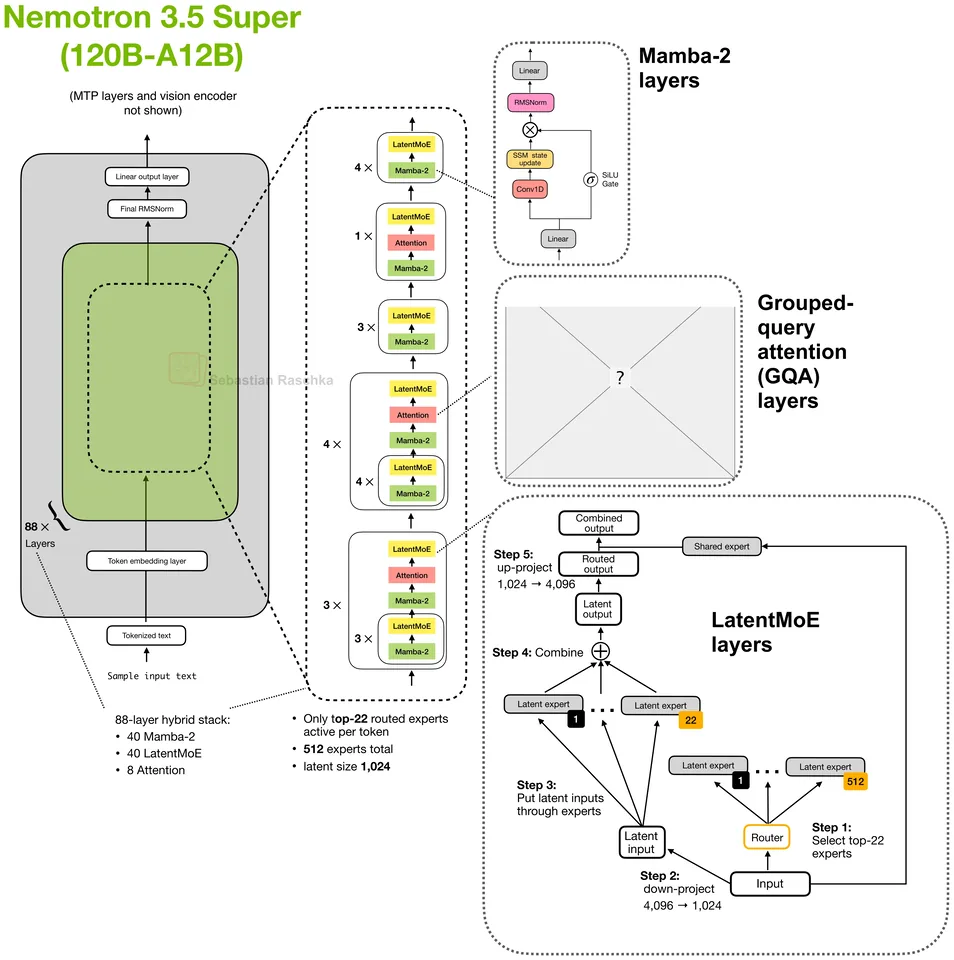
NVIDIA's vision-language model extends the Nemotron 3 Super backbone with C-RADIO vision encoding and shared-weight multi-token prediction. The figure shows the language backbone, with the vision encoder and MTP omitted.
120B total · 12B active · Mostly Mamba-2 with eight GQA layers
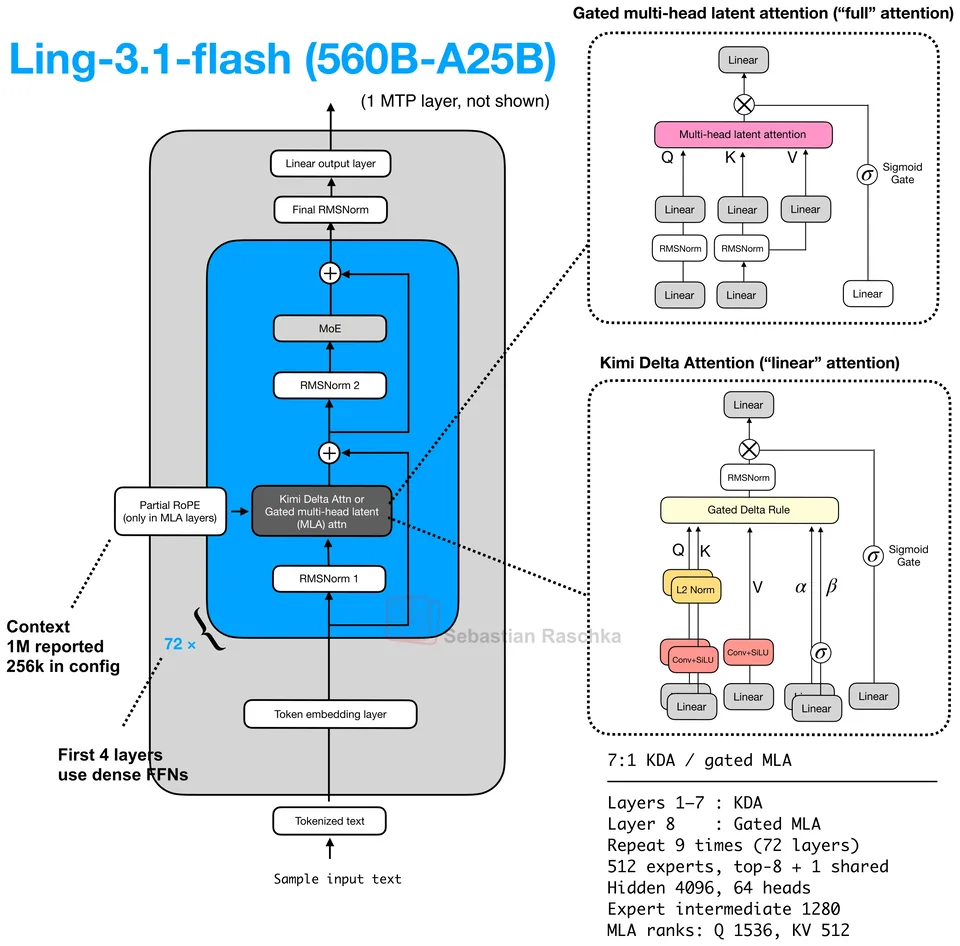
Hybrid MoE that extends Ling 3.0 Flash to 72 layers, with seven Kimi Delta Attention layers for every gated MLA layer.
560B total · 25B active · 7:1 Kimi Delta Attention and gated MLA
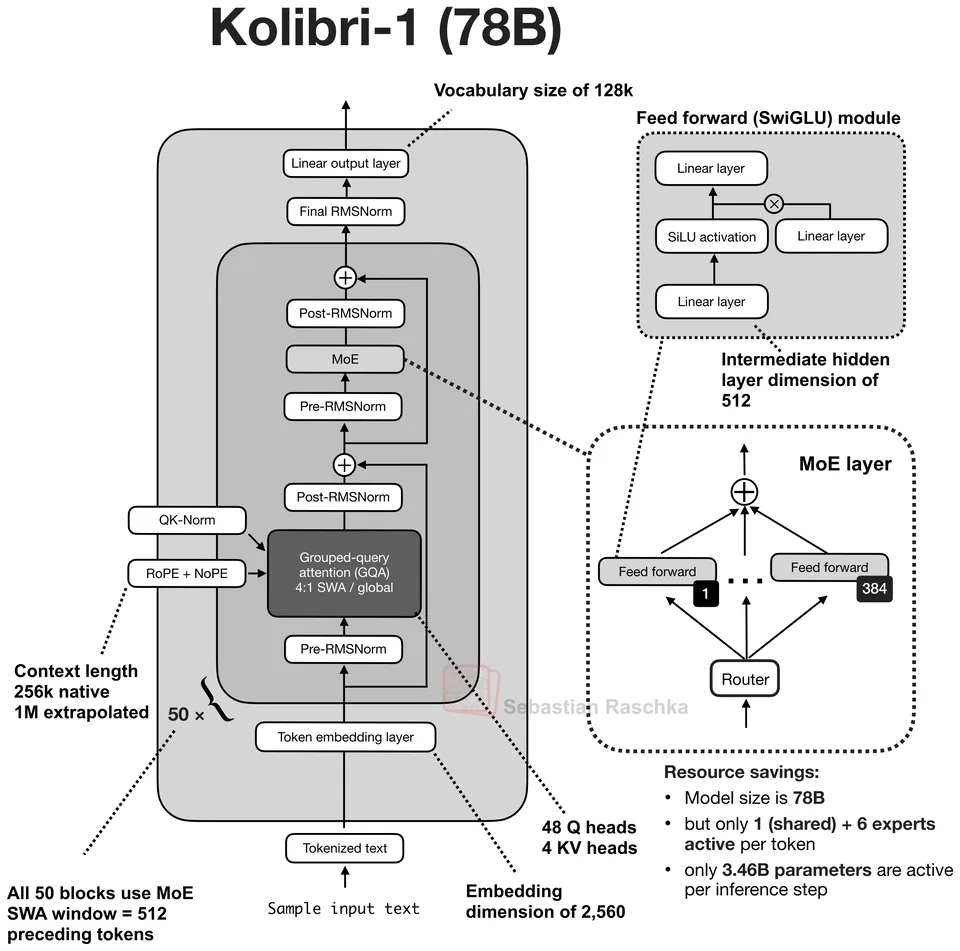
Aleph Alpha's German-English reasoning model uses 50 MoE blocks with a 4:1 mix of sliding-window and global GQA.
78B total · 3.5B active · GQA with QK-Norm and 4:1 sliding-window/global attention
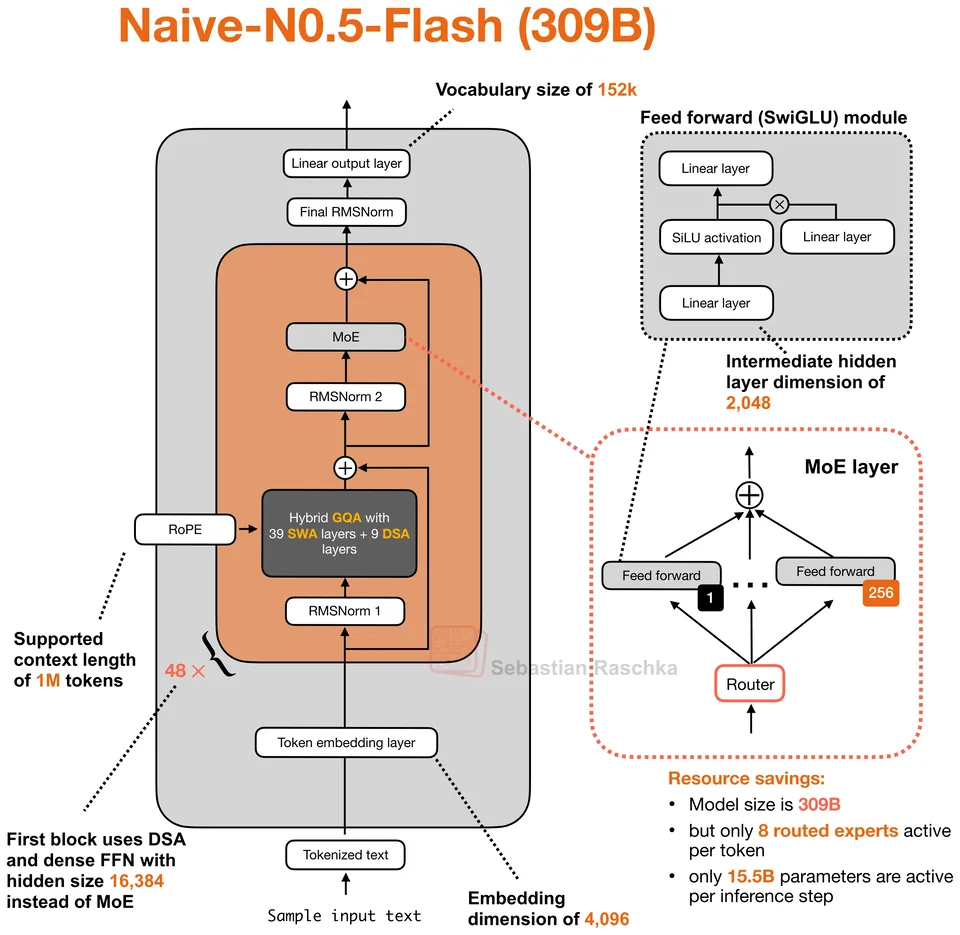
MiMo-V2.5-derived sparse MoE that replaces its global attention layers with GQA-based DeepSeek Sparse Attention for a native 1M-token context.
309B total · 16B active · GQA with sliding-window attention and DeepSeek Sparse Attention
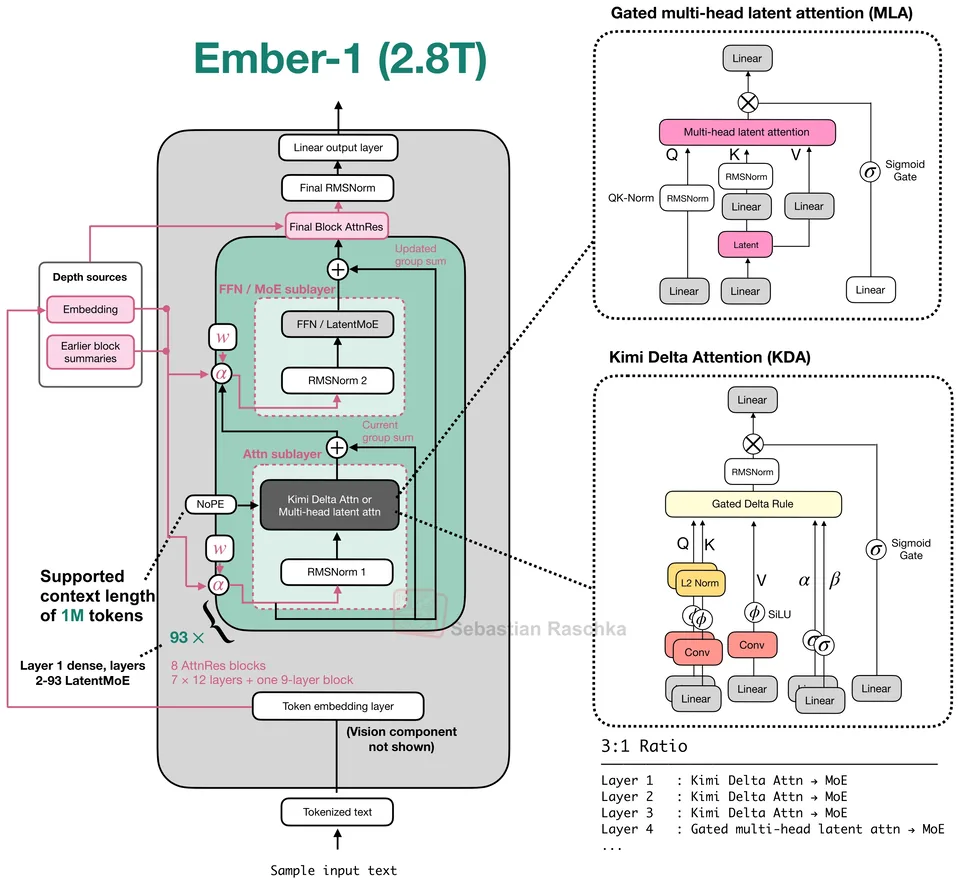
Fireworks' Kimi K3 derivative, post-trained for shorter reasoning traces. Architecture details follow the published Kimi K3 base model; the diagram focuses on its text backbone.
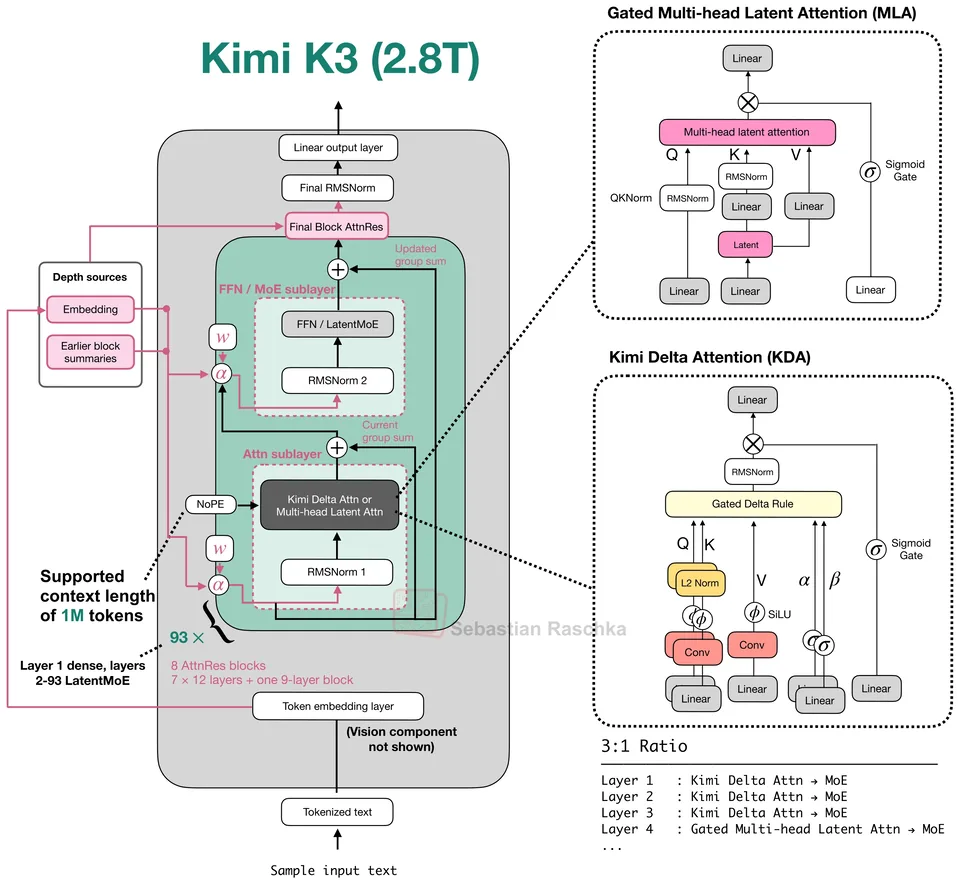
2.8T total · 104B active · 3:1 Kimi Delta Attention and Gated MLA with NoPE
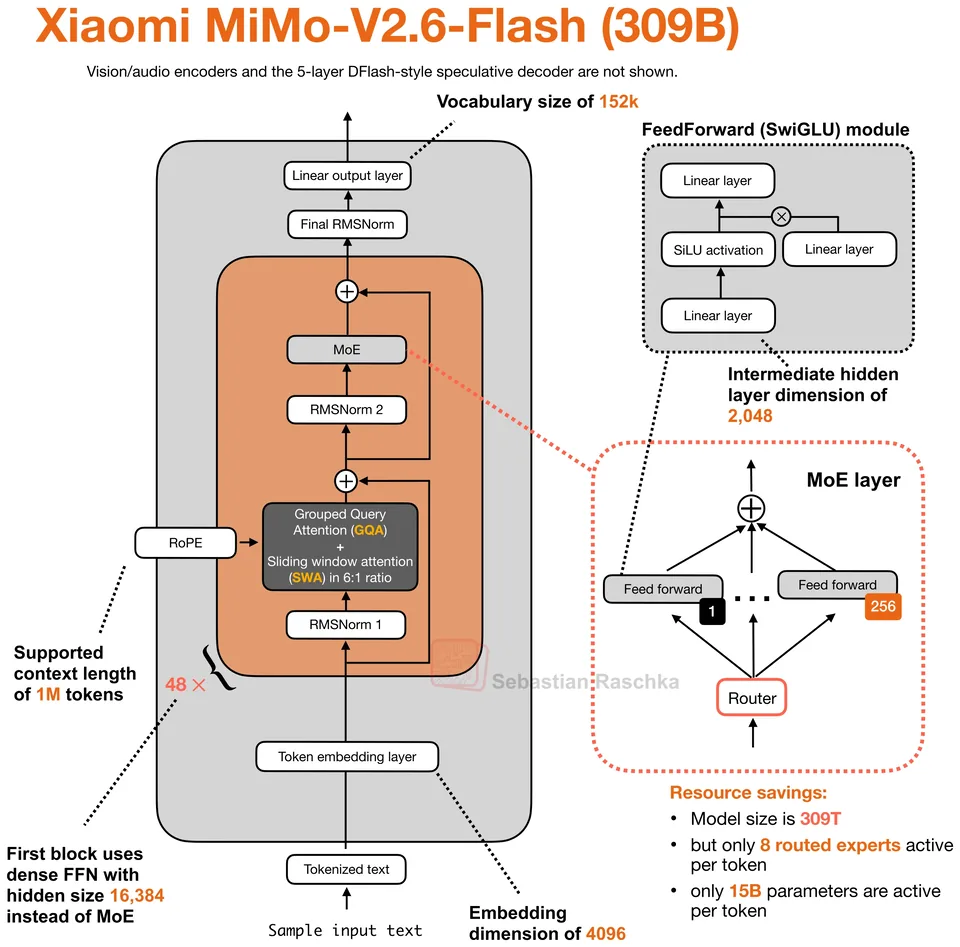
Omnimodal sparse MoE model with the MiMo-V2.5 text backbone, mixed-domain reinforcement learning, and a five-layer DFlash speculative decoder.
309B total · 15B active · GQA with sliding-window/global attention
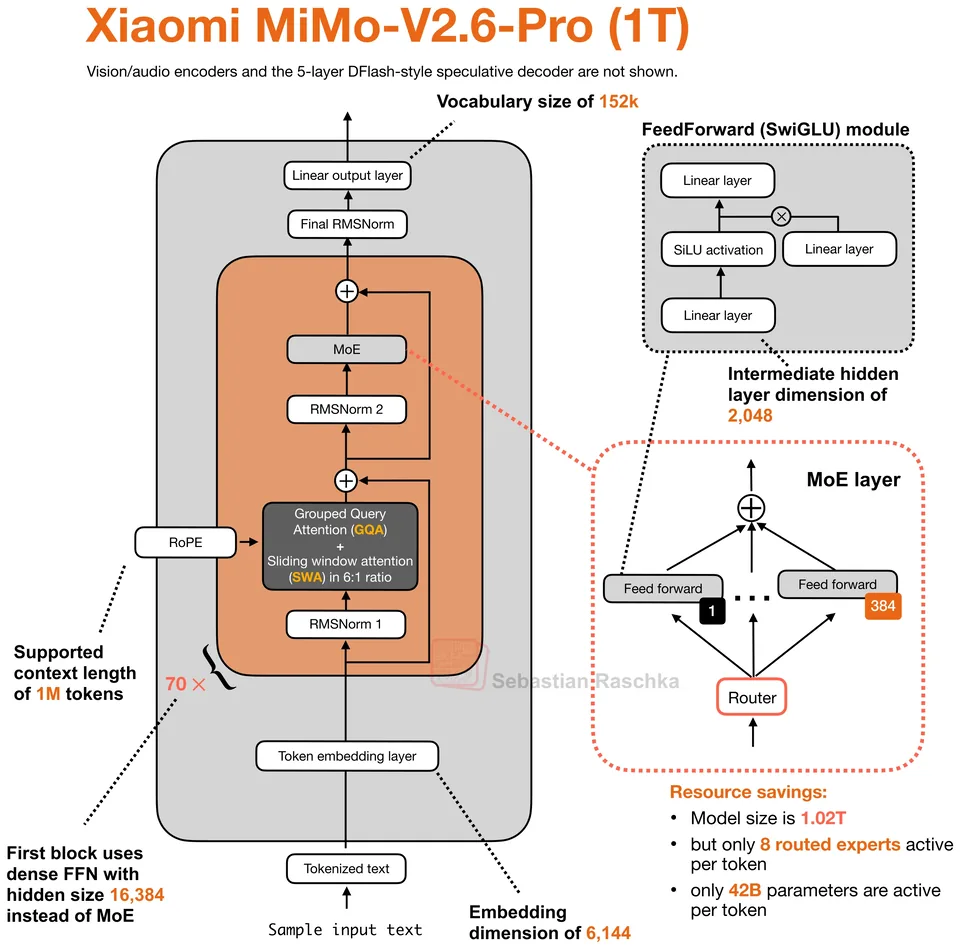
Omnimodal sparse MoE model with the MiMo-V2.5-Pro text backbone, mixed-domain reinforcement learning, and a five-layer DFlash speculative decoder.
1.02T total · 42B active · GQA with 6:1 sliding-window/global attention
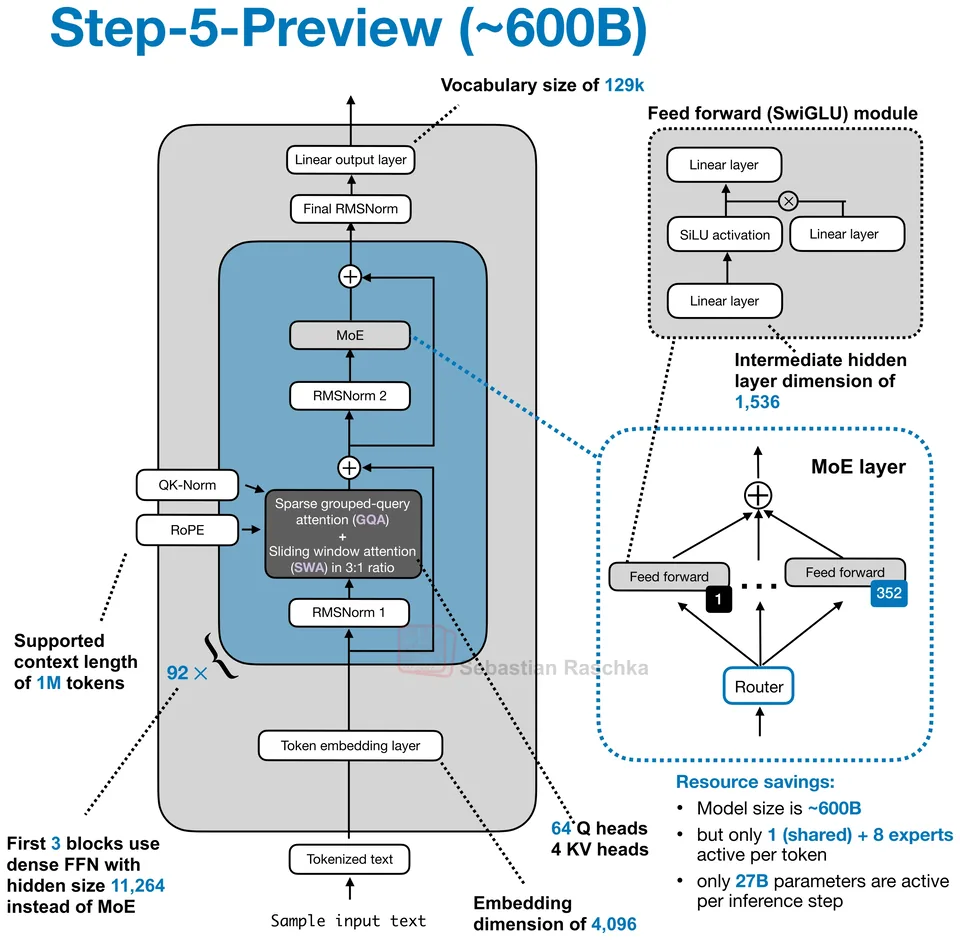
StepFun's 92-layer MoE pairs 512-token sliding-window attention with sparse GQA for a 1M-token context window; the figure shows the text decoder.
600B total · 27B active · Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention
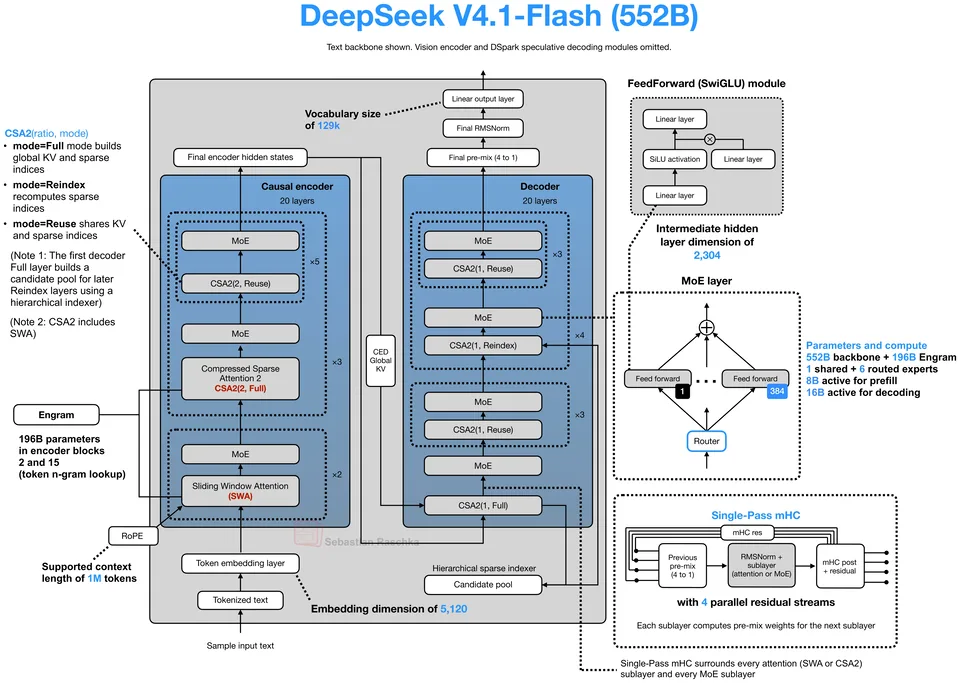
Causal encoder-decoder MoE with CSA2 cache sharing, Engram memory, and a million-token context. The figure shows the text backbone.
552B total · 8B active · MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse
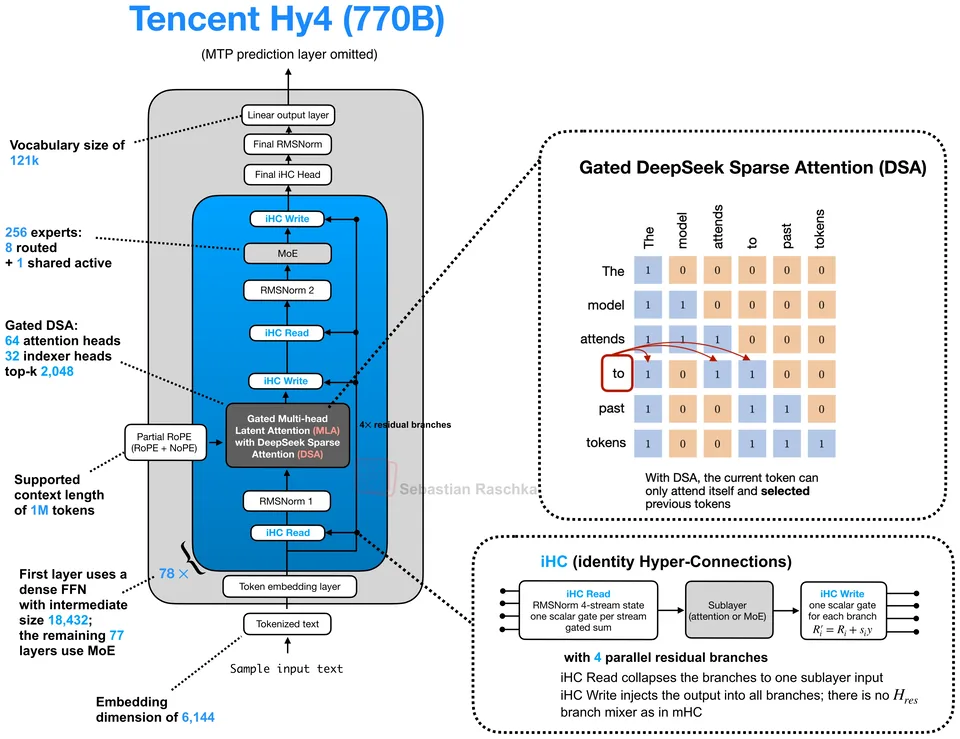
Tencent's 770B sparse MoE combines gated DeepSeek Sparse Attention, cross-layer index reuse, and four-stream identity Hyper-Connections.
770B total · 49B active · Gated MLA with DeepSeek Sparse Attention and IndexCache
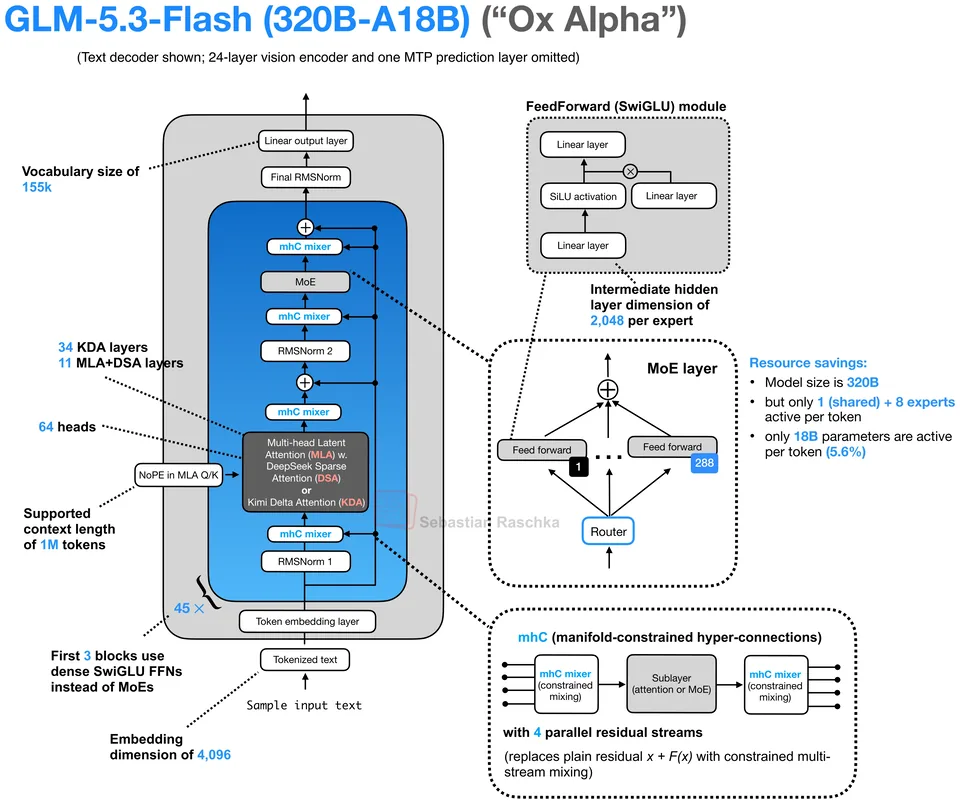
Natively multimodal GLM refresh, previously previewed as Ox Alpha, that replaces most MLA/DSA layers with Kimi Delta Attention and adds four-stream mHC.
320B total · 18B active · 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention
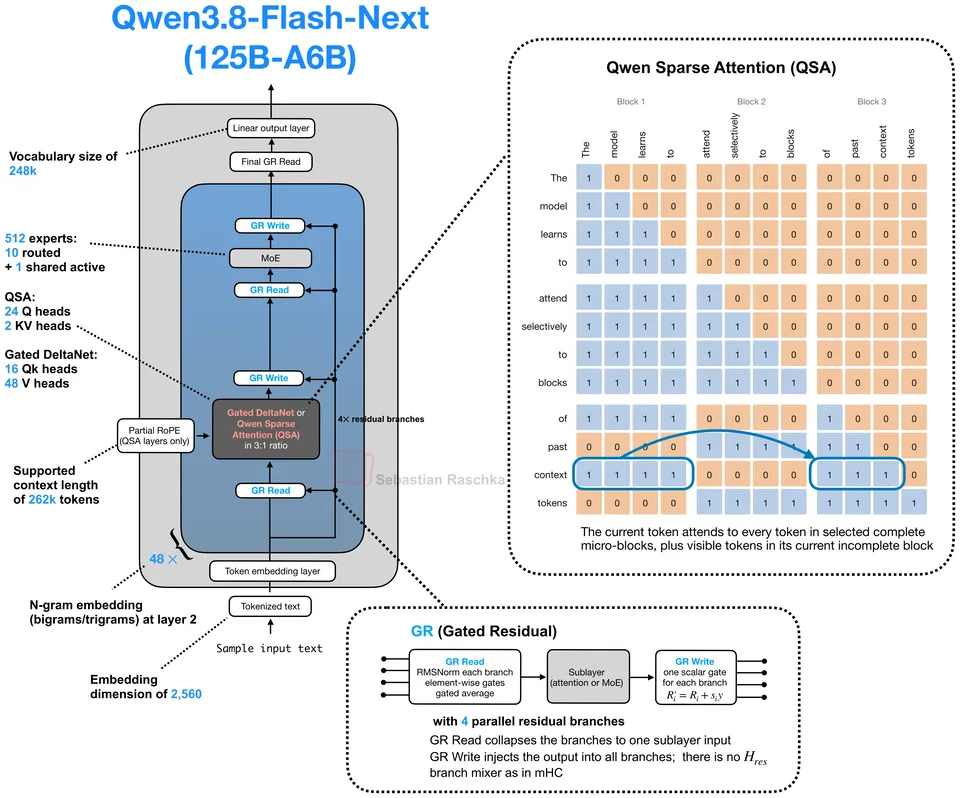
Experimental vision-language MoE whose text backbone combines Gated DeltaNet, micro-block QSA, four-branch gated residuals, and n-gram embeddings; the figure omits the vision encoder and MTP head.
125B total · 6B active · 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA)
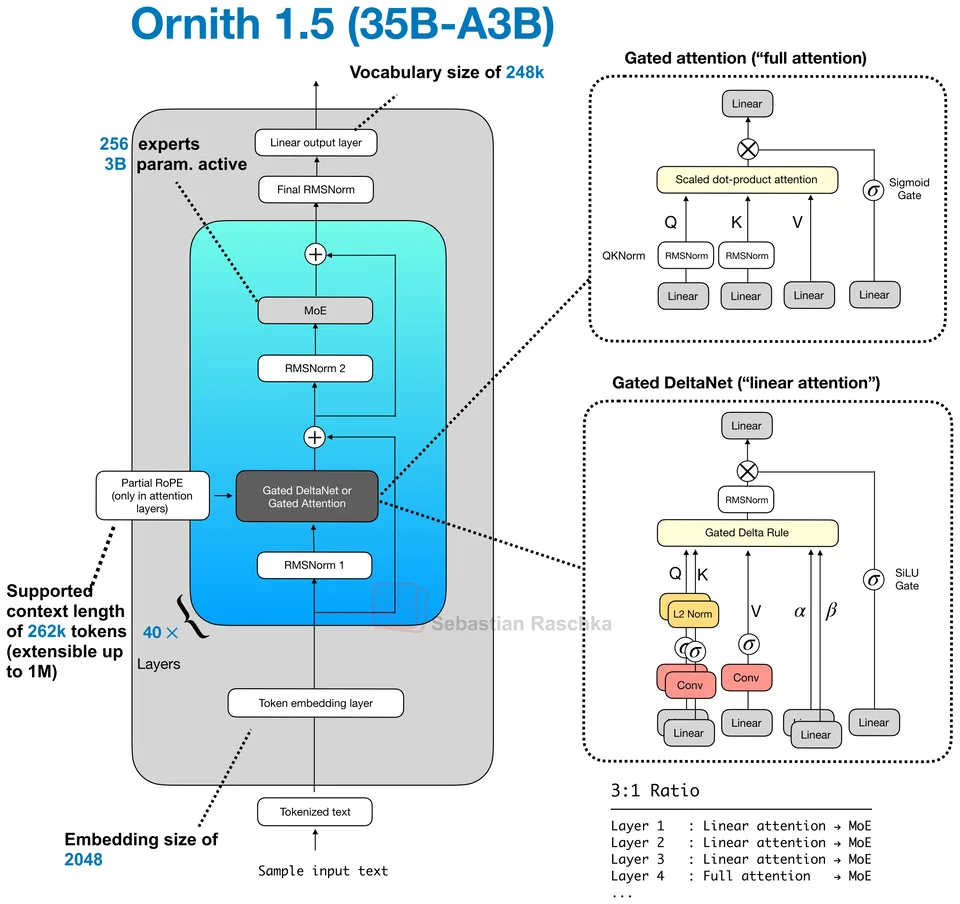
Uses the same sparse-hybrid decoder geometry as Qwen3.6 35B-A3B, paired with Ornith's self-improvement training recipe.
35B total · 3B active · 3:1 Gated DeltaNet and Gated Attention
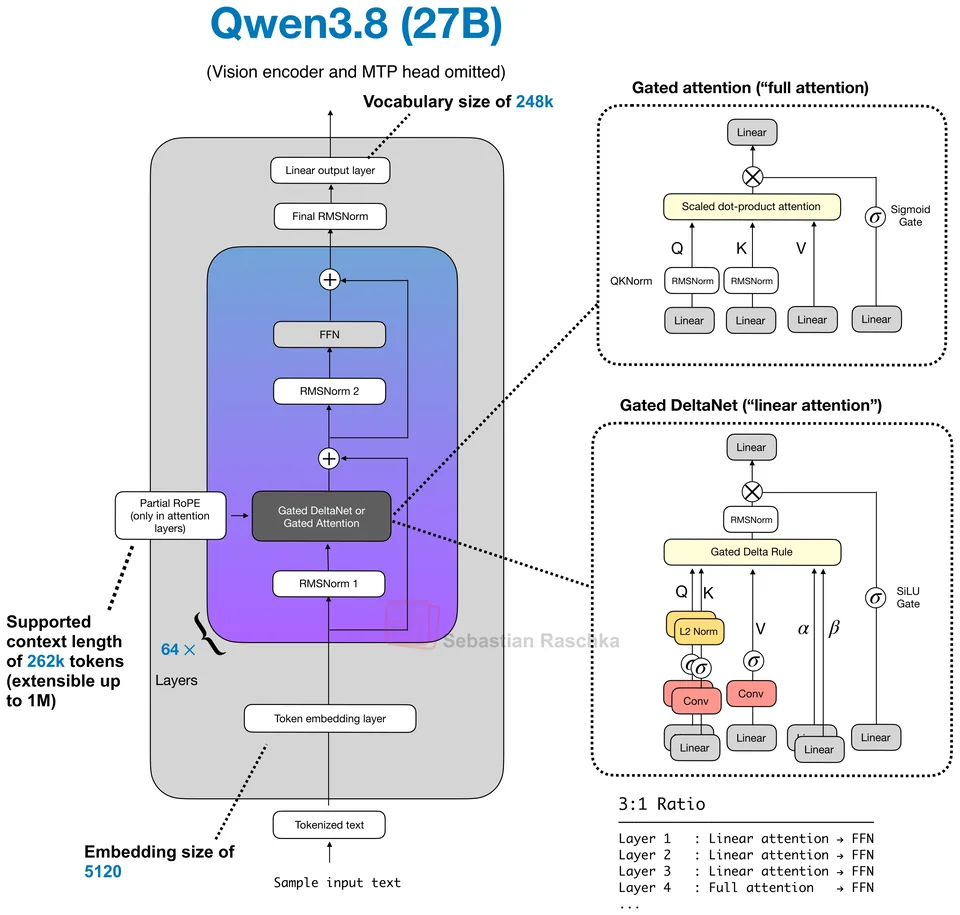
Dense 27B native vision-language model with a 64-layer Gated DeltaNet and Gated Attention language backbone; the figure omits the vision encoder and MTP head.
27B params · 3:1 Gated DeltaNet and Gated Attention
NVIDIA's 30B hybrid model keeps 3B parameters active and extends the Nemotron 3 Nano backbone with a 1M-token context window and multi-token prediction.
30B total · 3B active · Mostly Mamba-2 with six GQA layers
Meta's dense 29.6B multimodal model combines a 52-layer sandwich-norm decoder with gated GQA and a separate perception encoder; the figure focuses on the text backbone.
30B params · Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
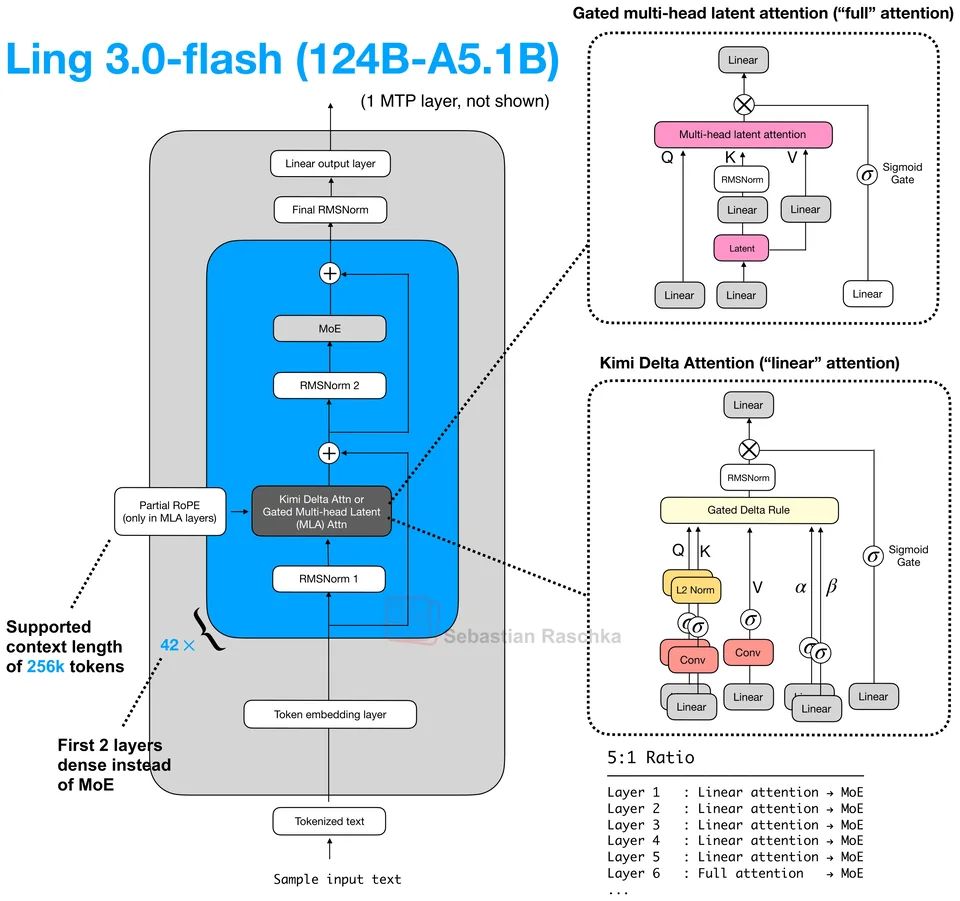
Hybrid MoE that alternates five Kimi Delta Attention layers with one gated MLA layer.
124B total · 5.1B active · 5:1 Kimi Delta Attention and gated MLA
2.8T sparse hybrid that combines a 3:1 KDA and Gated MLA stack with Block Attention Residuals and Stable LatentMoE. It is also native multimodal, but the figure focuses on the text portion.
Upstage's sparse hybrid alternates one gated GQA layer with three Kimi Delta Attention layers and reaches a 1M-token context without positional embeddings.
250B total · 15B active · 3:1 Kimi Delta Attention and gated GQA with NoPE
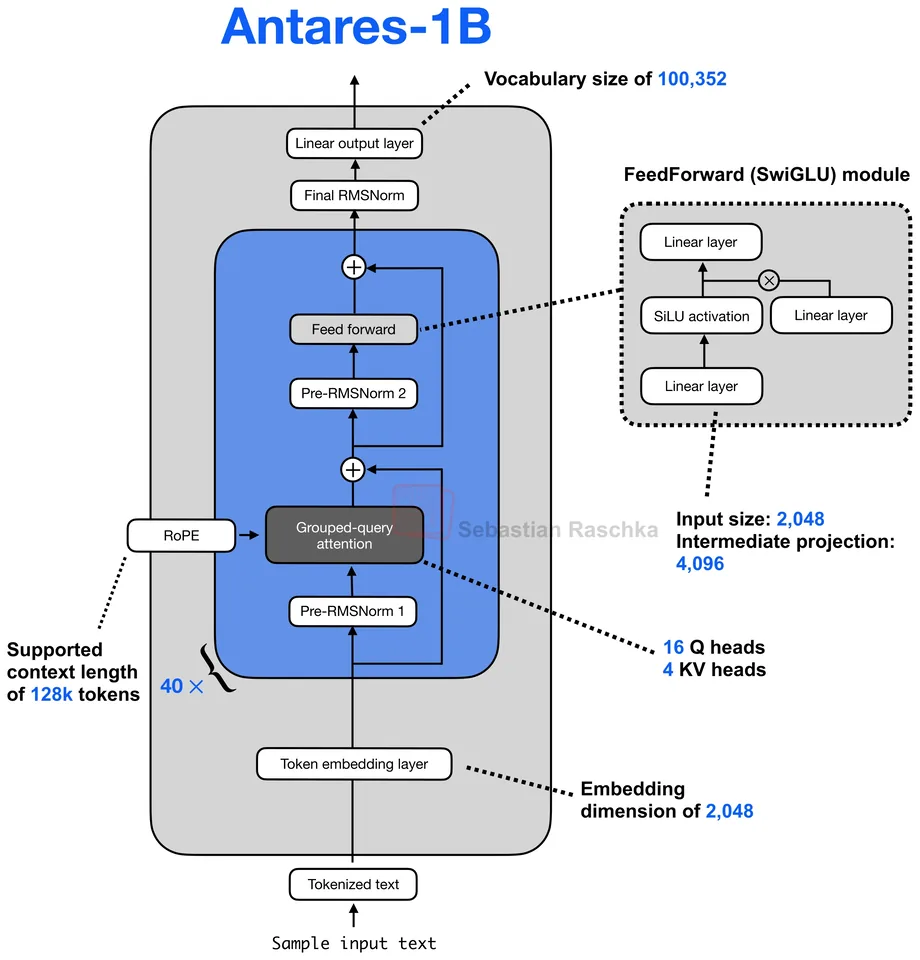
Cisco Foundation AI's compact terminal agent uses a dense Granite 4.0 backbone and is post-trained with SFT and GRPO for vulnerability localization.
1B params · GQA with RoPE
Poolside's 118B sparse MoE scales the Laguna XS recipe to 48 layers and 1M context while activating about 8B parameters per token.
118B total · 8B active · Gated GQA with QK-Norm and 3:1 sliding-window/global attention
Large sparse MoE that combines Grouped Differential Latent Attention, per-expert PolyNorm, and modified mHC in a 53-layer decoder.
314B total · 13B active · GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention
Compact agentic model that runs the same 22-layer dense transformer stack twice, resulting in 44 transformer blocks (layers) without duplicating the layer weights.
4B params · GQA with RoPE
Agent-oriented Qwen3.6-27B derivative that adds a rank-32 LoRA adapter for coding, structured tool use, and long multi-turn execution.
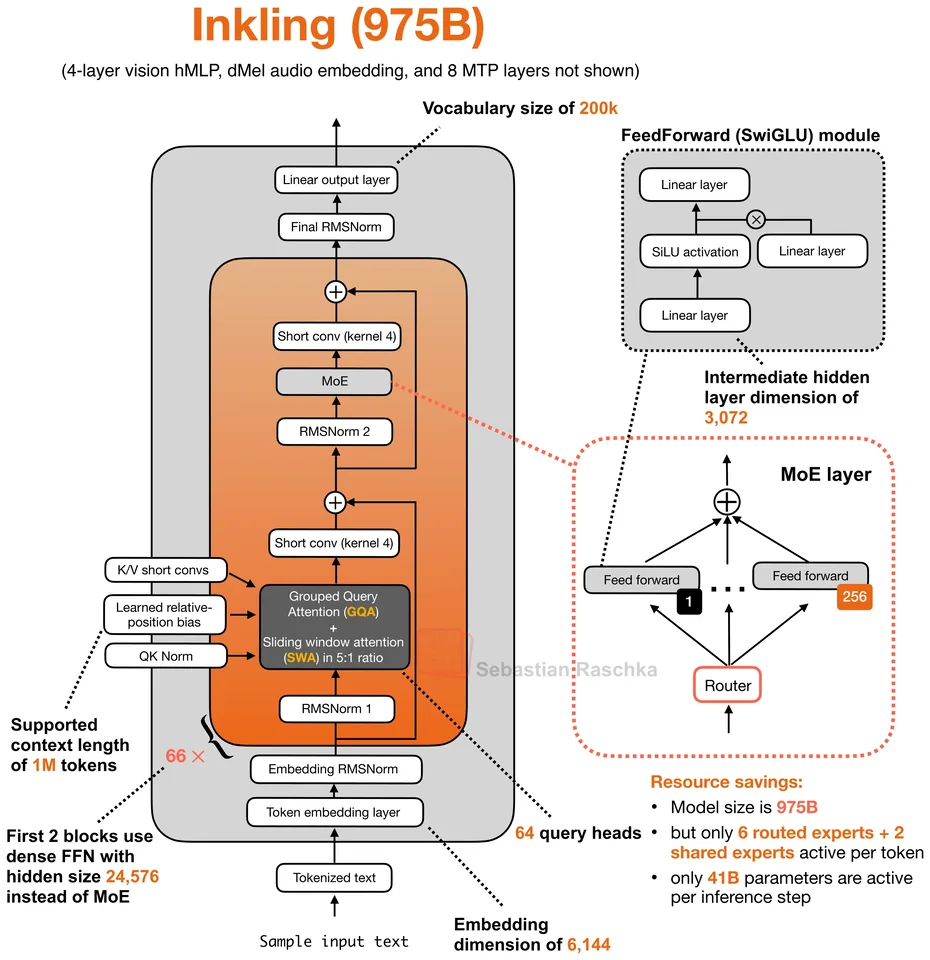
Thinking Machines Lab's native multimodal model combines a 66-layer sparse MoE decoder with a 5:1 mix of local and global GQA.
975B total · 41B active · GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern
German-English base model that retrains the Nemotron 3 Nano architecture on 26.68T tokens with a fully documented data mixture.
32B total · 3.2B active · Mostly Mamba-2 with 6 GQA layers and no positional embeddings (NoPE)
Poolside's 33B Laguna refresh extends the sparse MoE architecture to 262k context while keeping about 3B parameters active per token.
33B total · 3B active · Gated GQA with QK-Norm and 3:1 sliding-window/global attention
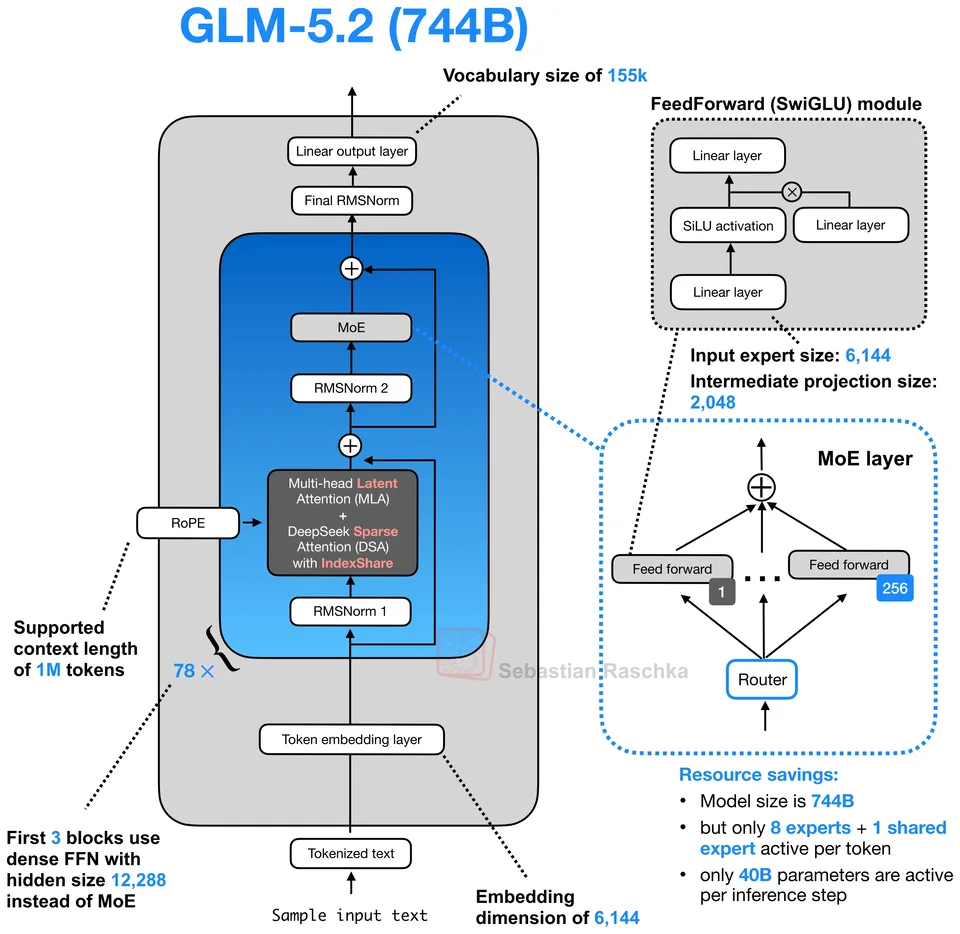
Long-context GLM refresh that keeps the 744B sparse MoE backbone and adds IndexShare for 1M-token DSA inference.
744B total · 40B active · MLA with DeepSeek Sparse Attention and IndexShare
Qwen2.5-Coder-based dense reasoner whose gains mainly come from verifier-driven post-training rather than a new block design.
3B params · 8:1 GQA with RoPE
Native multimodal MiniMax model that adds sparse attention to an M2-style MoE backbone for 1M-token context.
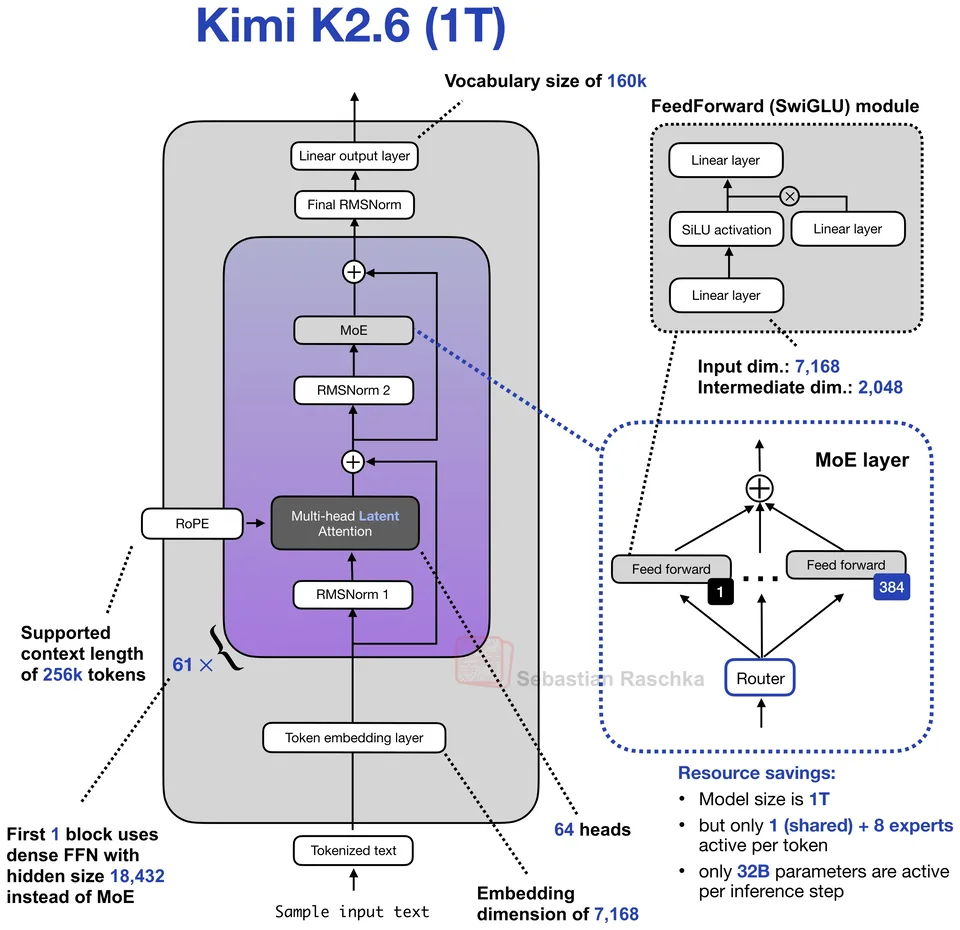
Coding-focused K2.6 successor that keeps the same 1T sparse MoE text backbone and emphasizes long-horizon software engineering agents.
1T total · 32B active · MLA
Cohere's compact agentic coding MoE adapts the parallel Cohere2-MoE block to a 30B total, 3B active model.
30B total · 3B active · 8:1 GQA with 3:1 sliding-window/global attention
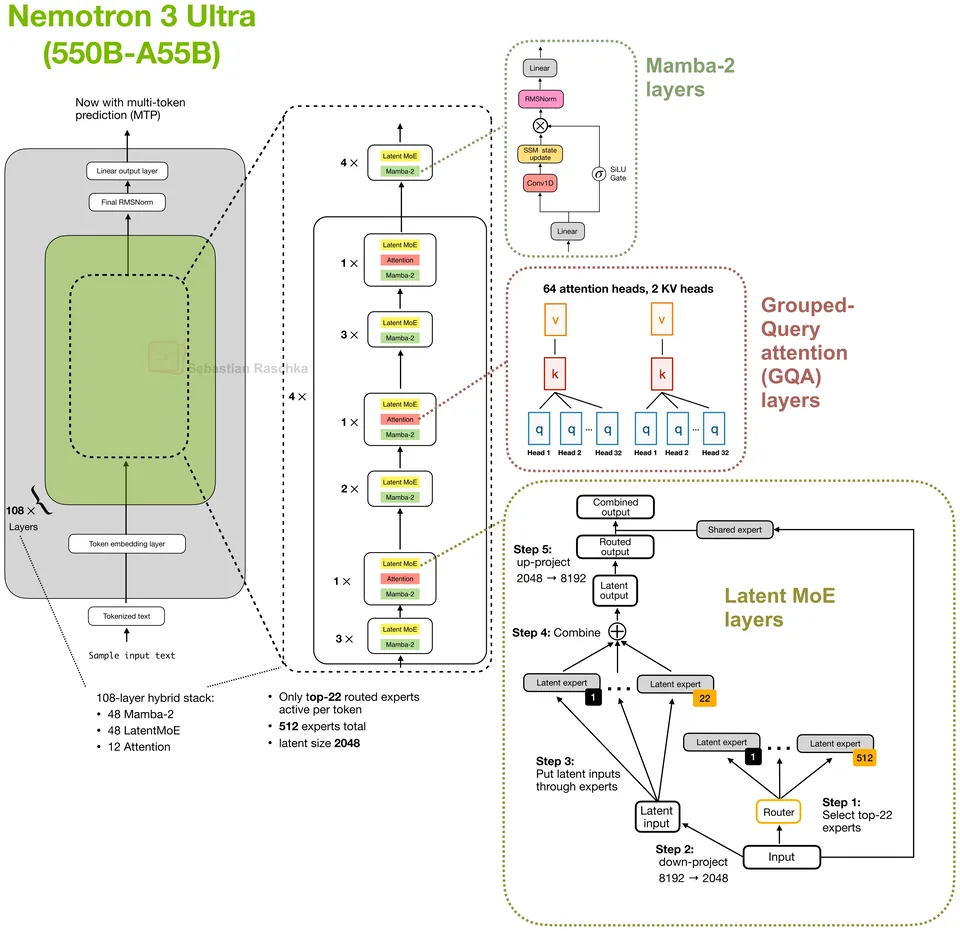
NVIDIA's Ultra model scales the Nemotron 3 hybrid stack to 550B total parameters while keeping 55B active per token.
550B total · 55B active · Mostly Mamba-2 with a few GQA layers
Dense Gemma 4 12B Unified uses an encoder-free multimodal input path, while its text decoder keeps the 31B-style local-global attention recipe.
12B params · GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
JetBrains' Mellum2 Thinking is a compact reasoning-tuned sparse MoE for code and agentic workflows.
12B total · 2.5B active · GQA with 3:1 sliding-window/full attention
Liquid AI's 1.2B LFM2.5 model keeps the 16-layer hybrid LIV convolution and GQA stack at a wider hidden size.
1.2B params · LIV convolution blocks plus GQA
Liquid AI's compact LFM2.5 model combines double-gated LIV convolution blocks with periodic GQA layers.
350M params · LIV convolution blocks plus GQA
Liquid AI's sparse LFM2.5 model combines LIV convolution, GQA, and MoE routing with 4 of 32 experts active per token.
8.3B total · 1.5B active · LIV convolution blocks plus GQA and MoE
Cohere's open sparse MoE model scales the Command A parallel transformer block to 218B total parameters while keeping 25B active per token.
218B total · 25B active · 16:1 GQA with 3:1 sliding-window/global attention
Zyphra's compact reasoning MoE pairs CCA/GQA attention updates with top-1 routed expert FFN updates to keep fewer than 1B parameters active per token.
8.4B total · 760M active · CCA with 4:1 GQA, RoPE, and Q/K L2 norm
IBM's dense 30B Granite 4.1 model keeps a straightforward long-context GQA transformer stack and improves tool calling, instruction following, and chat behavior through post-training.
30B params · GQA with RoPE
Poolside's open-weight agentic coding MoE uses mixed sliding-window/global attention and activates only 3B of 33B parameters per token.
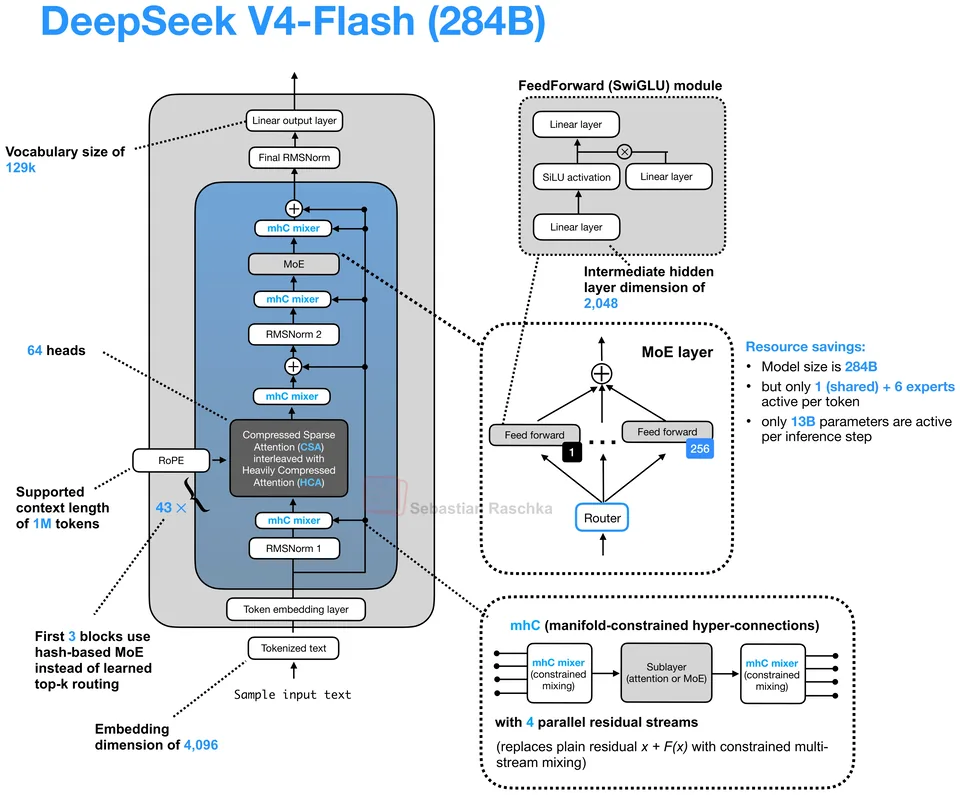
DeepSeek's efficient V4 preview keeps the million-token architecture while reducing the MoE scale to 284B parameters and 13B active parameters.
284B total · 13B active · MLA-style CSA/HCA with mHC
DeepSeek's flagship V4 preview scales to 1.6T parameters and introduces compressed sparse attention plus manifold-constrained hyper-connections for million-token contexts.
1.6T total · 49B active · MLA-style CSA/HCA with mHC
Ling 2.5 successor that keeps the Lightning Attention and MLA hybrid stack while adding an MTP layer for multi-token prediction.
1T total · 63B active · Lightning Attention plus MLA
Tencent Hunyuan's 295B sparse MoE preview combines a dense first FFN layer, GQA with QK-Norm, and one extra MTP layer for faster generation.
295B total · 21B active · GQA with QK-Norm
Dense Qwen3.6 model that keeps the Qwen3.5-style Gated DeltaNet/Gated Attention hybrid stack while replacing MoE blocks with dense FFNs.
Omnimodal sparse MoE model that extends the MiMo-V2-Flash backbone with vision and audio encoders.
310B total · 15B active · 5:1 sliding-window/global attention
Trillion-parameter sparse MoE model for long-horizon agentic and software-engineering tasks.
Native-multimodal K2.5 successor that keeps the same 1T sparse MoE backbone while targeting stronger long-horizon coding, design, and agent orchestration.
Compact Qwen3.6 open-weight MoE that keeps the Qwen3.5 hybrid Gated DeltaNet/Gated Attention recipe while activating only about 3B parameters.
Post-trained GLM refresh that keeps the GLM-5 backbone intact but targets stronger long-horizon agentic coding.
744B total · 40B active · MLA with DeepSeek Sparse Attention
Dense Gemma 4 scales the family to a 256K-context multimodal checkpoint without changing the core local-global recipe much.
31B params · GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
Sparse Gemma 4 variant that keeps the local:global attention backbone while swapping dense FFNs for MoE layers.
25B total · 3.8B active · GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
Smallest Gemma 4 edge model keeps the family's hybrid attention stack and adds native audio on a phone-scale multimodal footprint. Uses per-layer embeddings, which add small layer-specific token vectors without scaling the full compute path, so its compute footprint is closer to 2.3B than a full 5.1B dense model.
5.1B params · Multi-query attention with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 4:1 sliding-window/global attention
Larger Gemma 4 edge variant keeps the same multimodal hybrid recipe but doubles width and KV heads for a stronger 128K mobile checkpoint. Uses per-layer embeddings, which add small layer-specific token vectors without scaling the full compute path, so its compute footprint is closer to 4.5B than a full 8B dense model.
8B params · GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
Agent-focused 230B follow-up built for self-evolution, agent harnesses, and productivity workflows.
230B total · 10B active · GQA with QK-Norm
Multimodal Mistral Small refresh that jumps from the older dense 24B stack to an MLA-based sparse MoE design.
119B total · 6.6B active · MLA
Compact on-device hybrid that compresses Nemotron Nano 9B v2 into a mostly Mamba-2 stack with only four attention layers.
4B params · GQA with only 4 attention layers
The Super variant scales up Nano and adds both latent experts and native speculative decoding support.
120B total · 12B active · Mostly Mamba-2 with a few GQA layers
Reasoning-oriented Indian-language sparse MoE that keeps GQA at the smaller size.
30B total · 2.4B active · GQA with QK-Norm
Larger Sarvam variant keeps the sparse MoE layout but switches from GQA to MLA.
105B total · 10B active · MLA with KV LayerNorm and NoPE + RoPE
Mainline Qwen refresh that brings the Next-style hybrid attention into the flagship series.
397B total · 17B active · 3:1 Gated DeltaNet and Gated Attention
Trillion-parameter long-context model that swaps DeltaNet for Lightning Attention.
Compact multilingual model from Cohere with a rare parallel transformer block.
3.4B params · GQA with 3:1 sliding-window attention
Popular 230B coder that opts for a classic architecture instead of the newer hybrid-attention ideas.
Huge GLM refresh that adopts both MLA and DeepSeek Sparse Attention for flagship-scale inference.
Small on-device oriented model that stays close to Llama 3.2 while nudging the scaling choices.
3B params · GQA
Throughput-oriented MoE model that stays competitive with much larger DeepSeek-style systems.
196B total · 11B active · GQA with 3:1 sliding-window attention
Meituan's LongCat-Next text backbone is a lightweight MoE that shifts a large share of parameters into N-gram embeddings while keeping sparse inference around 3B active parameters.
69B total · 3B active · MLA with RoPE + NoPE
Arcee's flagship blends several efficiency tricks into a DeepSeek-like coarse MoE design; the AA score shown here refers to the Trinity Large Thinking checkpoint.
400B total · 13B active · GQA with gated attention and 3:1 sliding-window/global attention
Native-multimodal Moonshot flagship that keeps the K2/DeepSeek-style MoE layout and pushes native context to 256k.
Immediate GLM predecessor that stays closer to the older GLM-4.5 style before the MLA shift.
355B total · 32B active · GQA with QK-Norm
Large MoE model that pushes sliding-window attention harder than most contemporaries.
309B total · 15B active · 5:1 sliding-window/global attention
NVIDIA's Nano model is the most extreme transformer-state-space hybrid in the gallery.
30B total · 3B active · Mostly Mamba-2 with a few GQA layers
Mistral's new flagship effectively adopts the DeepSeek architecture and retunes the expert sizes.
673B total · 41B active · MLA
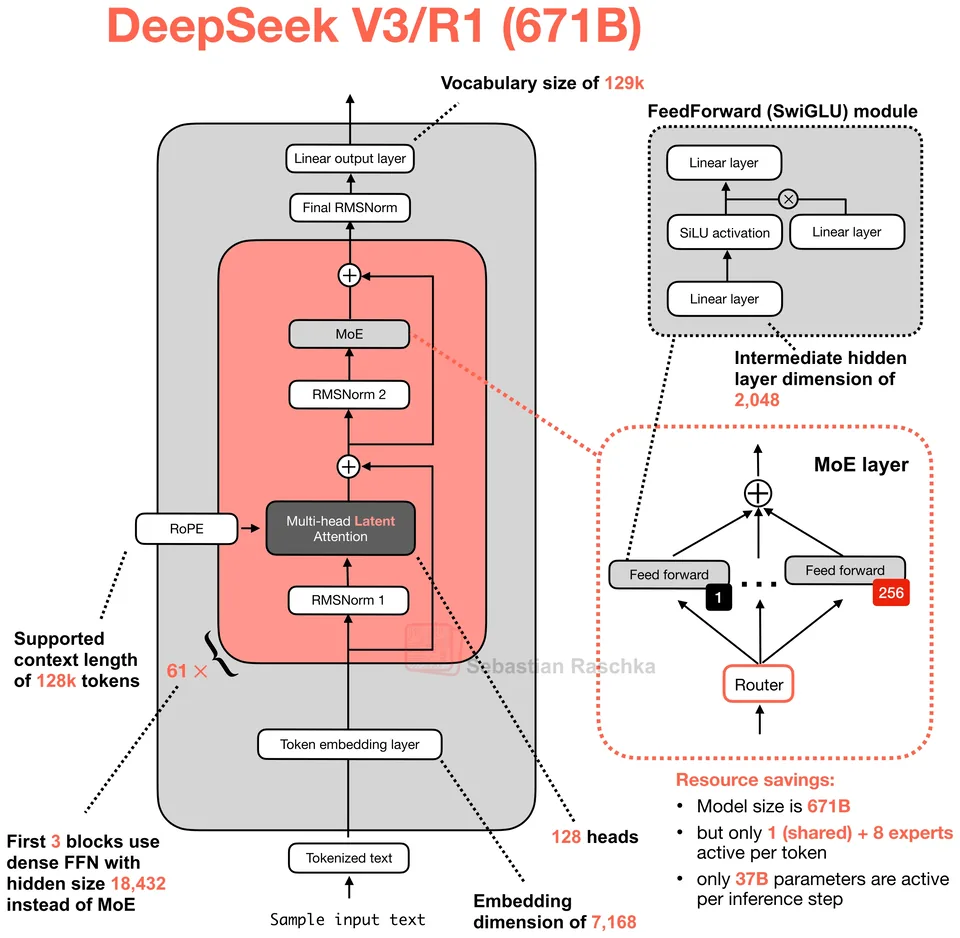
DeepSeek's successor keeps the V3 template but adds sparse attention to cut long-context costs.
671B total · 37B active · MLA with DeepSeek Sparse Attention
Large-scale RL post-training of GLM-4.5-Air that keeps the compact 106B sparse MoE backbone intact.
106B total · 12B active · GQA
Scaled-up OLMo 3 keeps the same block design but moves to grouped-query attention.
32B params · GQA with QK-Norm and 3:1 sliding-window/global attention
New transparent Allen AI model that keeps OLMo's post-norm flavor while modernizing context handling.
7B params · MHA with QK-Norm and 3:1 sliding-window/global attention
Linear-attention hybrid that keeps a transformer backbone but replaces most full-attention layers.
48B total · 3B active · 3:1 Kimi Delta Attention and MLA
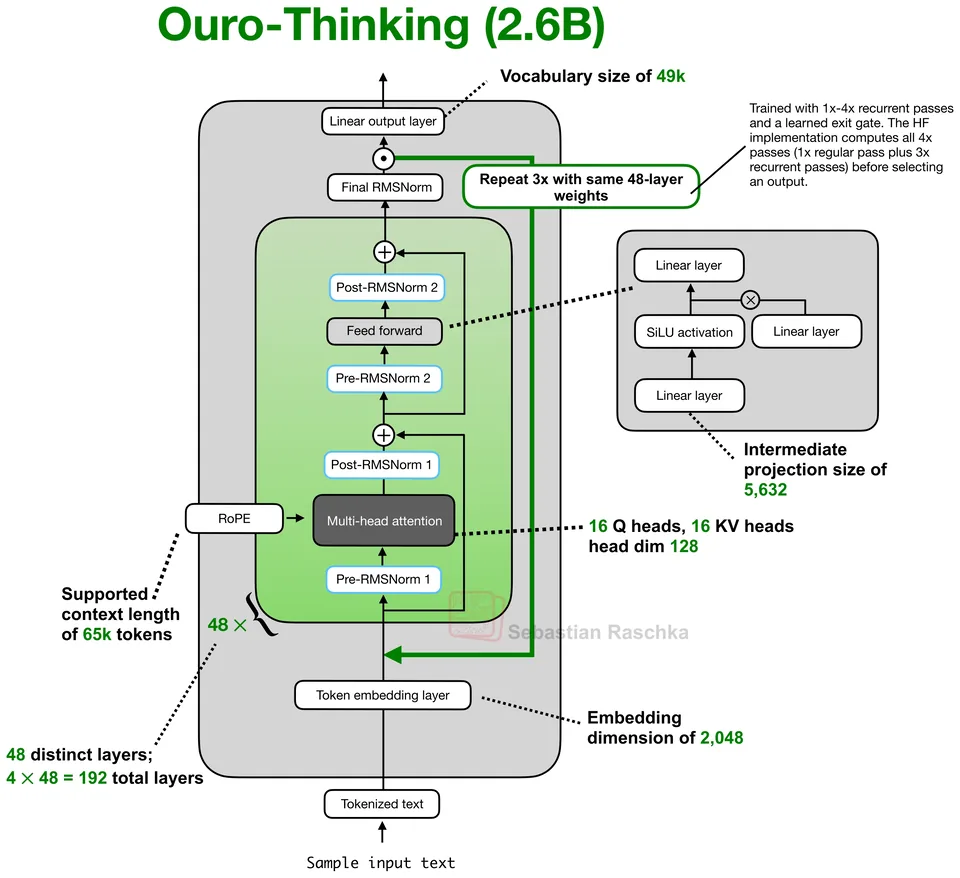
ByteDance's dense LoopLM reuses one 48-layer MHA stack across four recurrent passes and trains an exit gate over the intermediate representations.
2.6B params · MHA with RoPE
MiniMax's flagship returns to full attention and looks like a leaner, sparser cousin of Qwen3.
230B total · 10B active · GQA with QK-Norm and partial RoPE
Efficiency-focused Qwen refresh that swaps standard attention for a DeltaNet-attention hybrid.
80B total · 3B active · 3:1 Gated DeltaNet and Gated Attention
Rare production-model release that shows an older MoE style with fewer, larger experts.
270B params · GQA
Tiny Gemma 3 variant that preserves the family's local-global attention recipe at a toy scale.
270M params · Multi-query attention with QK-Norm and 5:1 sliding-window/global attention
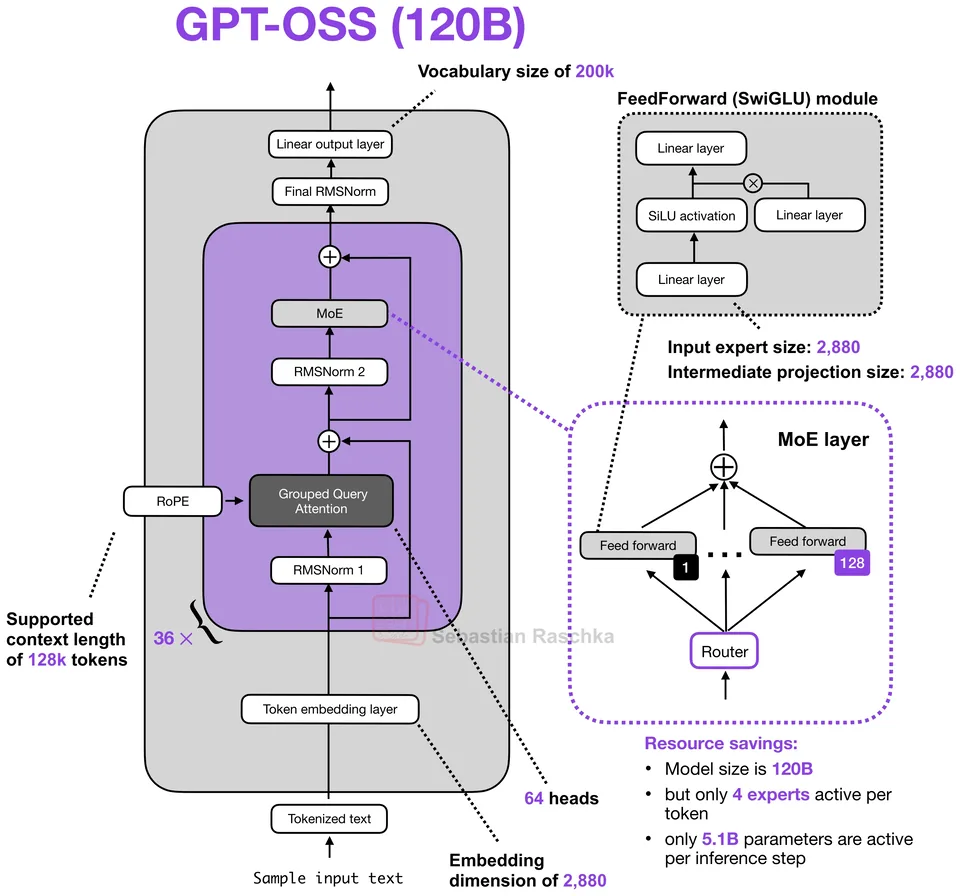
Larger gpt-oss variant keeps the same alternating-attention recipe as the 20B model.
117B total · 5.1B active · GQA with alternating sliding-window and global layers
OpenAI's smaller open-weight MoE model favors width and alternating local/global attention.
21B total · 3.6B active · GQA with alternating sliding-window and global layers
Coding-tuned Qwen model that keeps a straightforward grouped-query MoE stack instead of the newer hybrid-attention variants.
30B total · 3.3B active · GQA
Agent-oriented instruction/reasoning hybrid that borrows DeepSeek's dense-prefix MoE layout.
Compact GLM-4.5 companion that keeps the same agent-oriented sparse MoE recipe at a smaller serving footprint.
Trillion-parameter Moonshot model that essentially scales the DeepSeek V3 recipe upward.
Compact dense model that experiments with leaving out positional encodings in selected layers.
3B params · GQA with periodic NoPE layers
Tiny current-generation Qwen model that trades width for more depth and a low memory footprint.
600M params · GQA
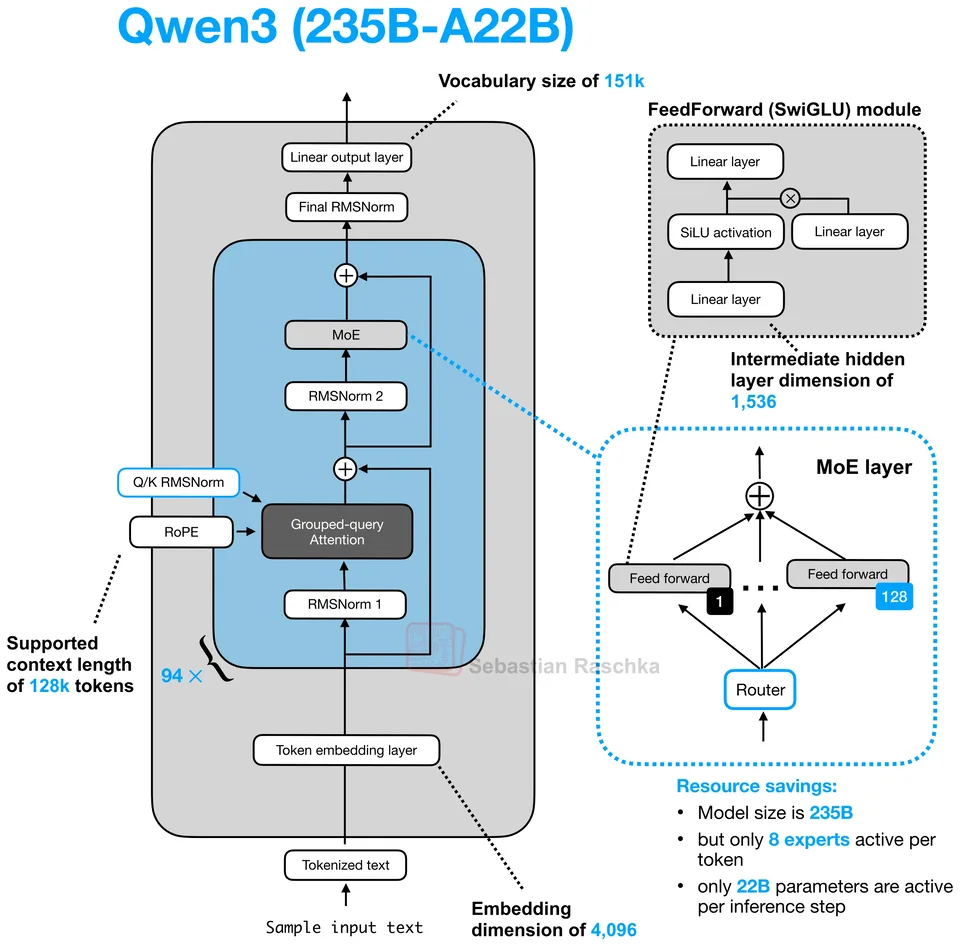
Large sparse Qwen variant that stays very close to DeepSeek V3 while removing the shared expert.
235B total · 22B active · GQA with QK-Norm
Small sparse Qwen3 model that sits close to GPT-OSS in active size but uses a deeper stack.
30B total · 3B active · GQA
Large dense Qwen3 model that serves as the clearest like-for-like comparison for OLMo 3 32B.
32B params · GQA with QK-Norm
Mid-size dense Qwen3 model used here as a clean baseline against SmolLM3 and Tiny Aya.
4B params · GQA with QK-Norm
Dense Qwen3 baseline used here to show how little OLMo 3 changed the overall decoder recipe.
8B params · GQA with QK-Norm
Meta's large MoE follows the DeepSeek V3 playbook but with a more conventional attention stack.
400B total · 17B active · GQA
Fast dense 24B model that drops the sliding-window setup used in older Mistral releases.
24B params · Standard GQA
Recurrent 7B language model that replaces self-attention with xLSTM blocks built around matrix memory.
7B params · No self-attention; mLSTM recurrent layers with matrix memory
Gemma's flagship text stack leans on local attention more aggressively than Gemma 2.
27B params · GQA with QK-Norm and 5:1 sliding-window/global attention
Reasoning-tuned DeepSeek model built on the V3 architecture rather than a new base design.
671B total · 37B active · MLA
DeepSeek's flagship template kicked off the recent wave of large open MoE models.
Microsoft's 14B dense Phi refresh stays close to Phi-3-medium but swaps its sliding-window attention for full-context GQA and a larger tokenizer.
14B params · GQA with RoPE
Transparent dense model that keeps classic MHA and pushes normalization changes for training stability.
7B params · MHA with QK-Norm
Small dense Llama baseline in the Qwen comparison, with fewer layers but more width.
1B params · GQA
Small Llama baseline used to show how closely Nanbeige follows the mainstream compact decoder recipe.
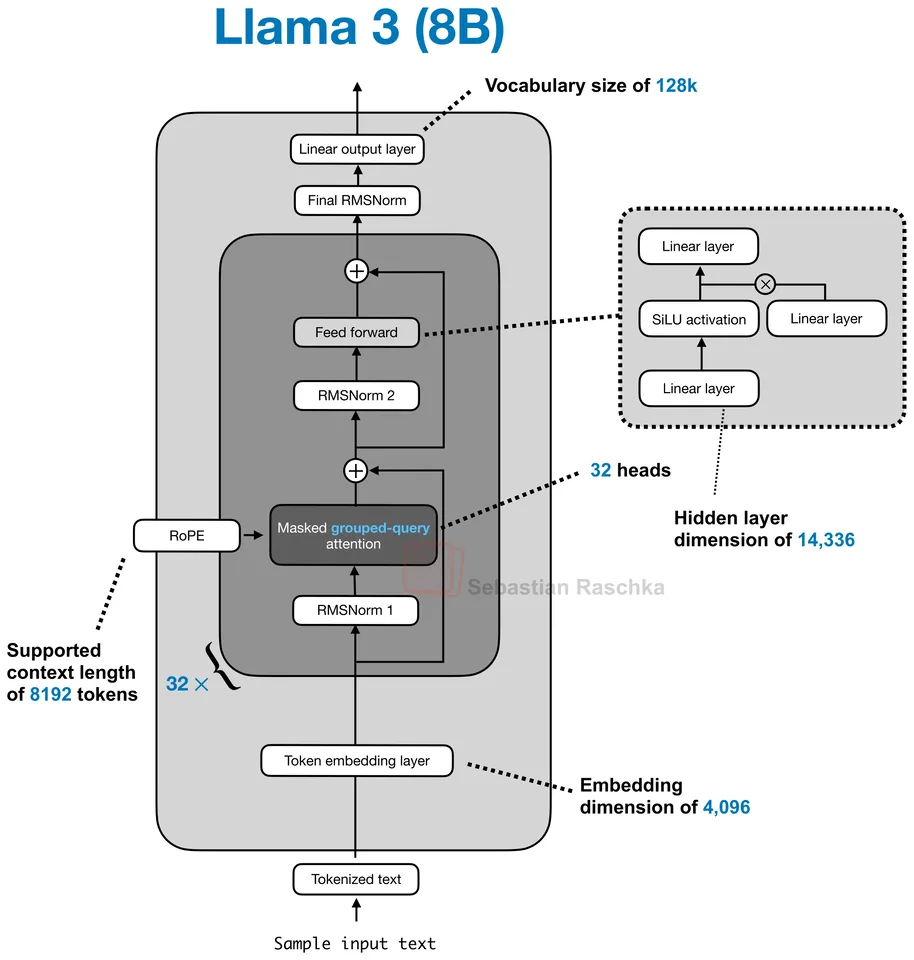
Reference dense Llama stack used to contrast OLMo 2's normalization and attention choices.
8B params · GQA with RoPE
Late-2019 dense baseline included here as a reference point for how much decoder stacks have changed since GPT-2.
1.5B params · MHA with learned absolute positional embeddings
Jump to a model, concept or page