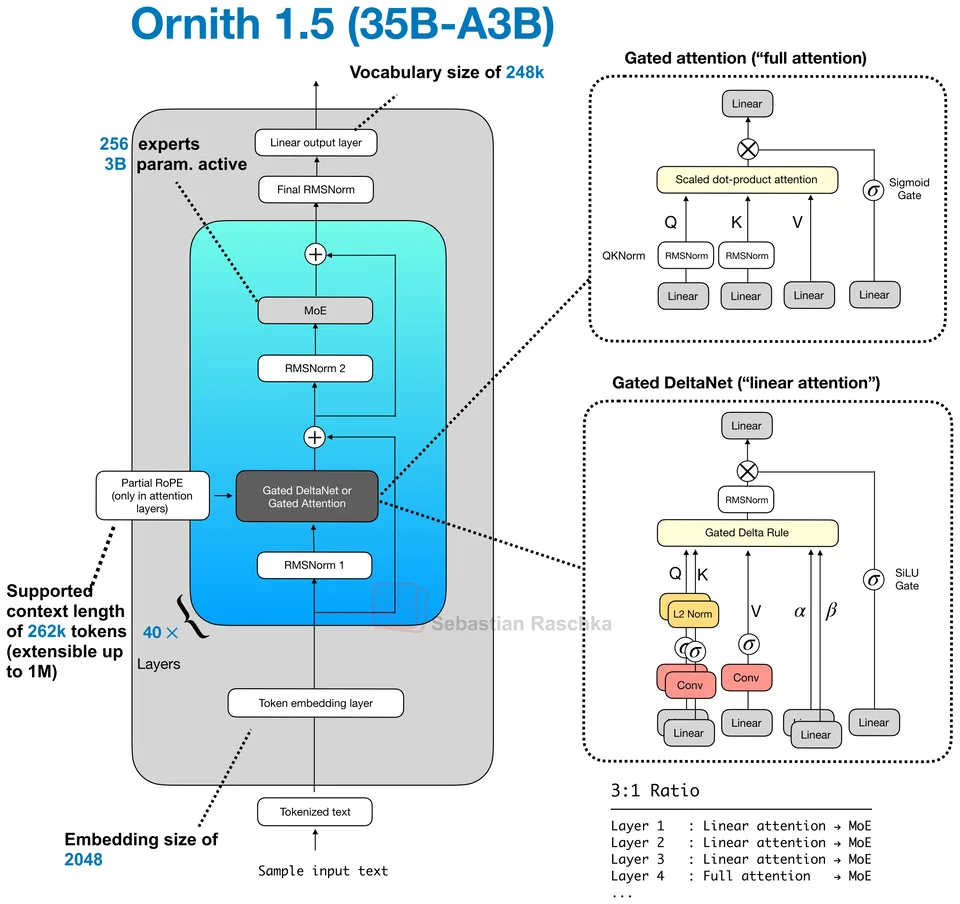
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
Compact Qwen3.6 open-weight MoE that keeps the Qwen3.5 hybrid Gated DeltaNet/Gated Attention recipe while activating only about 3B parameters.
Key detail
Uses 256 experts with 8 routed plus 1 shared expert active inside a 40-layer hybrid stack.Total params
35B
Active / token
3B
Context
256K
Parameters active per token
8.6%
3B of 35B weights run for each token.
18.2
Use the ← and → keys to step through releases.
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

Alibaba Cloud, released 2025-09-09. Hybrid MoE decoder, 80B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
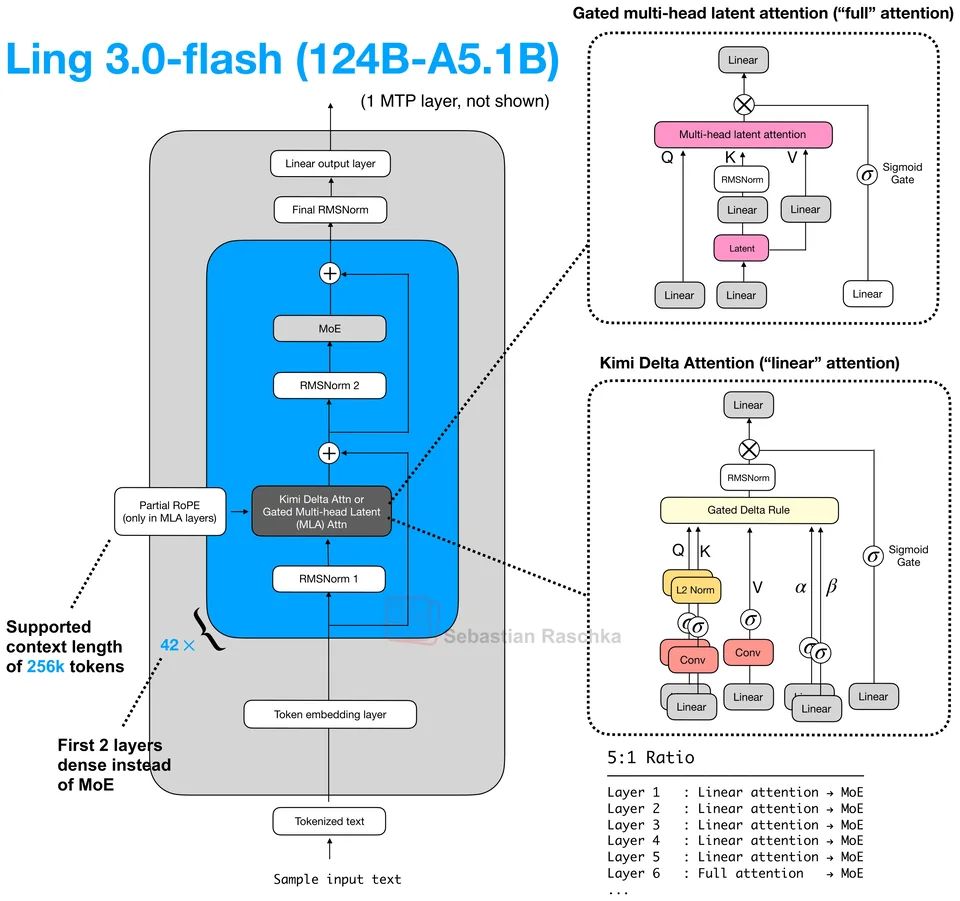
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
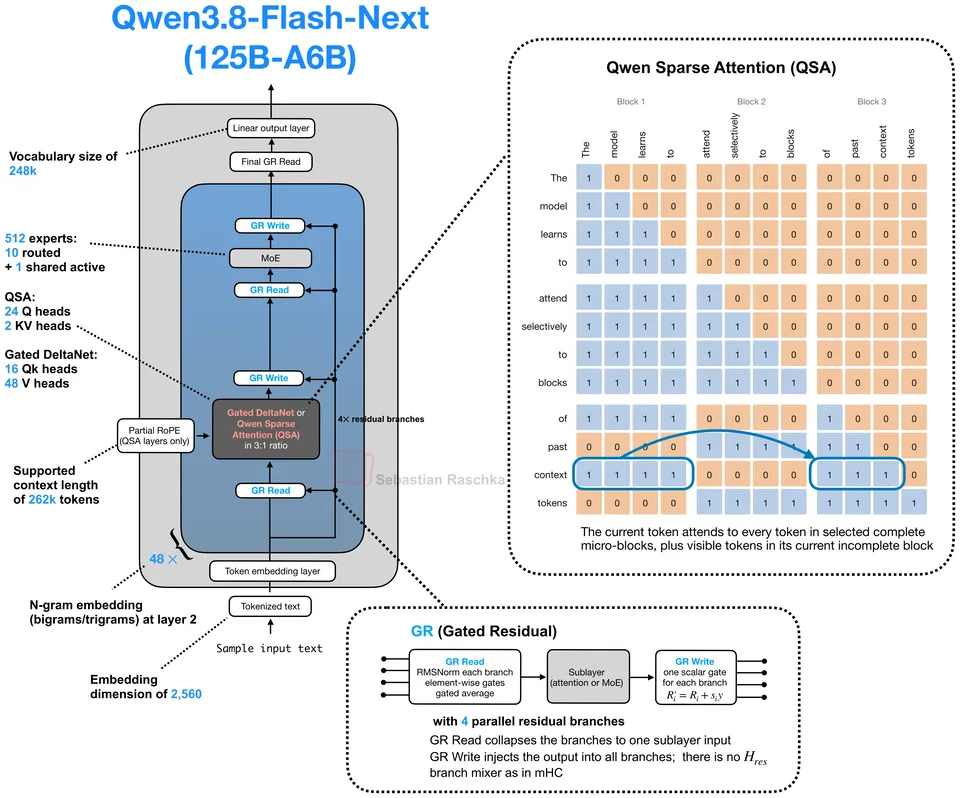
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
Jump to a model, concept or page