
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.
Native-multimodal K2.5 successor that keeps the same 1T sparse MoE backbone while targeting stronger long-horizon coding, design, and agent orchestration.
Key detail
Uses the same text architecture as Kimi K2.5, with the main change coming from the multimodal and agentic training recipe.Total params
1T
Active / token
32B
Context
256K
Parameters active per token
3.2%
32B of 1T weights run for each token.
27
Use the ← and → keys to step through releases.
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.

Moonshot AI, released 2026-01-27. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Moonshot AI, released 2026-06-12. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
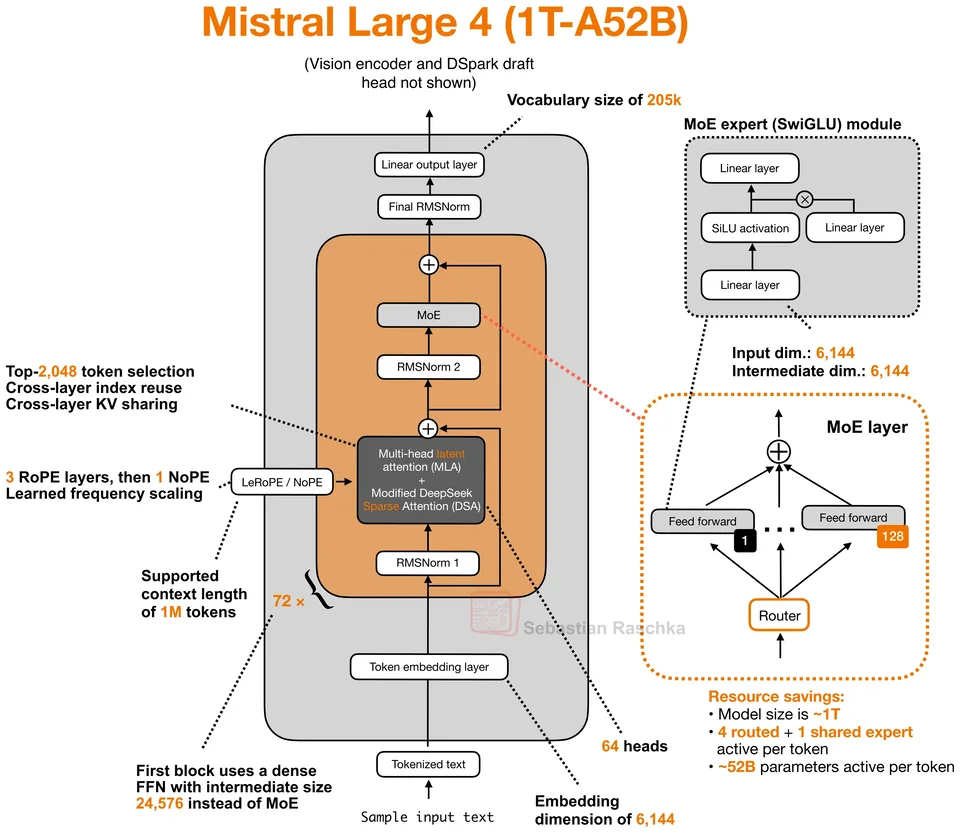
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Jump to a model, concept or page