
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.
Coding-focused K2.6 successor that keeps the same 1T sparse MoE text backbone and emphasizes long-horizon software engineering agents.
Key detail
Keeps the Kimi K2.5/K2.6 text architecture and shifts the release focus toward coding-agent workflows.Total params
1T
Active / token
32B
Context
256K
Parameters active per token
3.2%
32B of 1T weights run for each token.
25.8
Use the ← and → keys to step through releases.
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.

Moonshot AI, released 2026-01-27. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
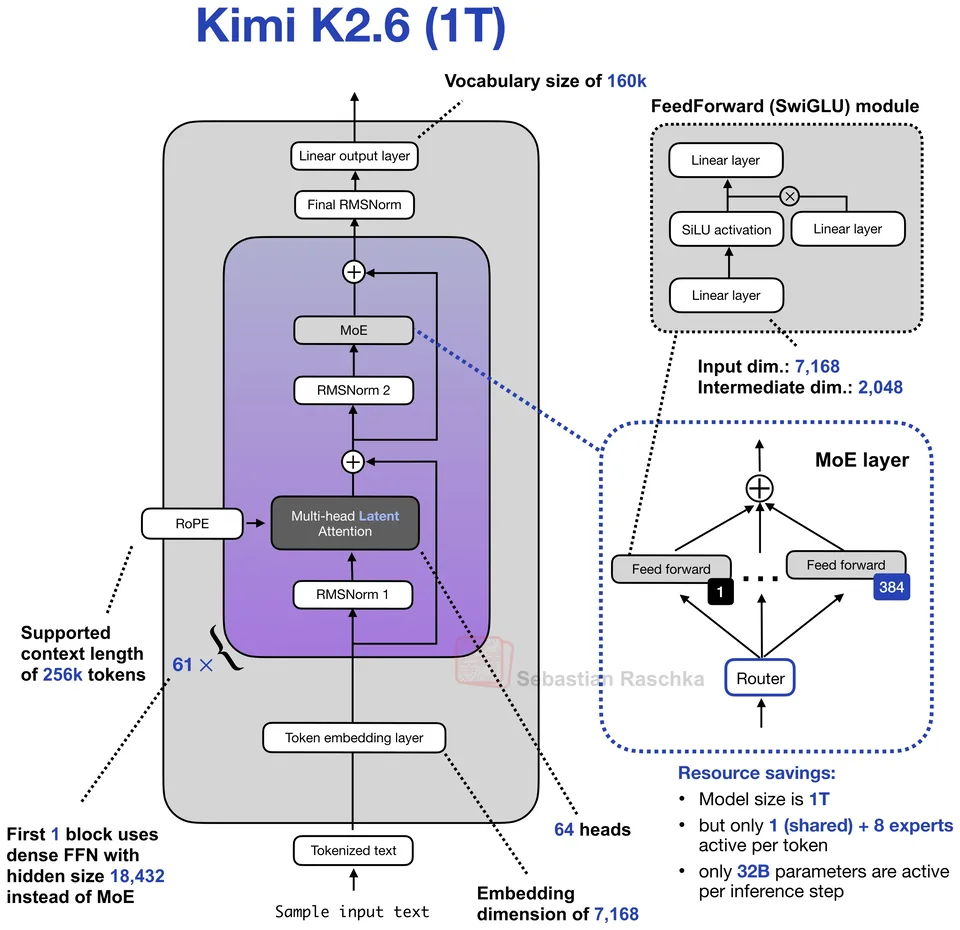
Moonshot AI, released 2026-04-20. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
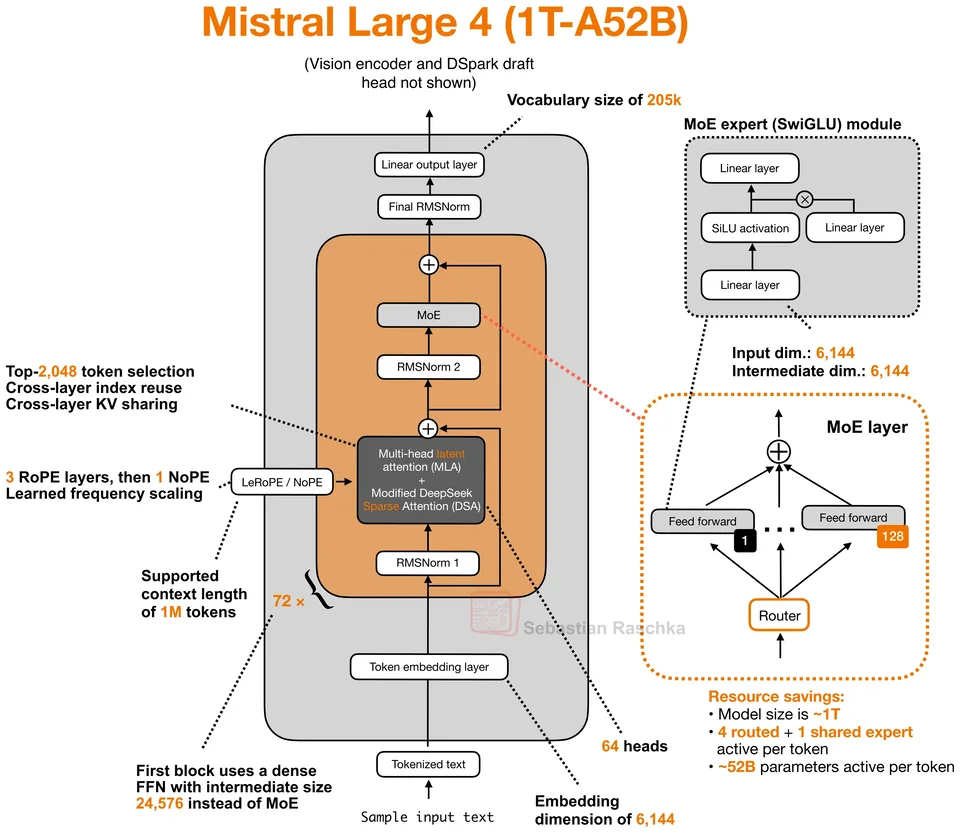
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Jump to a model, concept or page