
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.
Native-multimodal Moonshot flagship that keeps the K2/DeepSeek-style MoE layout and pushes native context to 256k.
Key detail
Keeps the 384-expert K2 backbone, but adds multimodal capabilities (not shown) and doubles the native context length.Total params
1T
Active / token
32B
Context
256K
Parameters active per token
3.2%
32B of 1T weights run for each token.
19.4
Use the ← and → keys to step through releases.
Moonshot AI, released 2025-07-10. Sparse MoE decoder, 1T total, 32B active, 128K context. Attention: MLA.
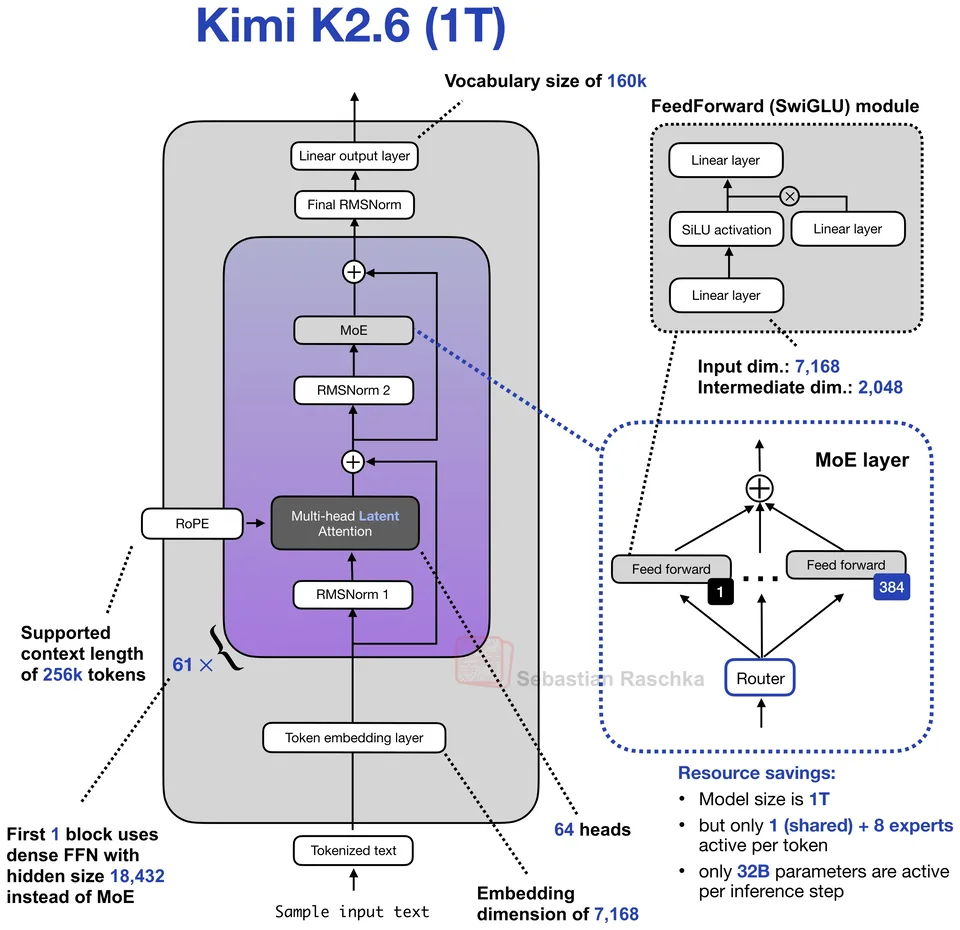
Moonshot AI, released 2026-04-20. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Moonshot AI, released 2026-06-12. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
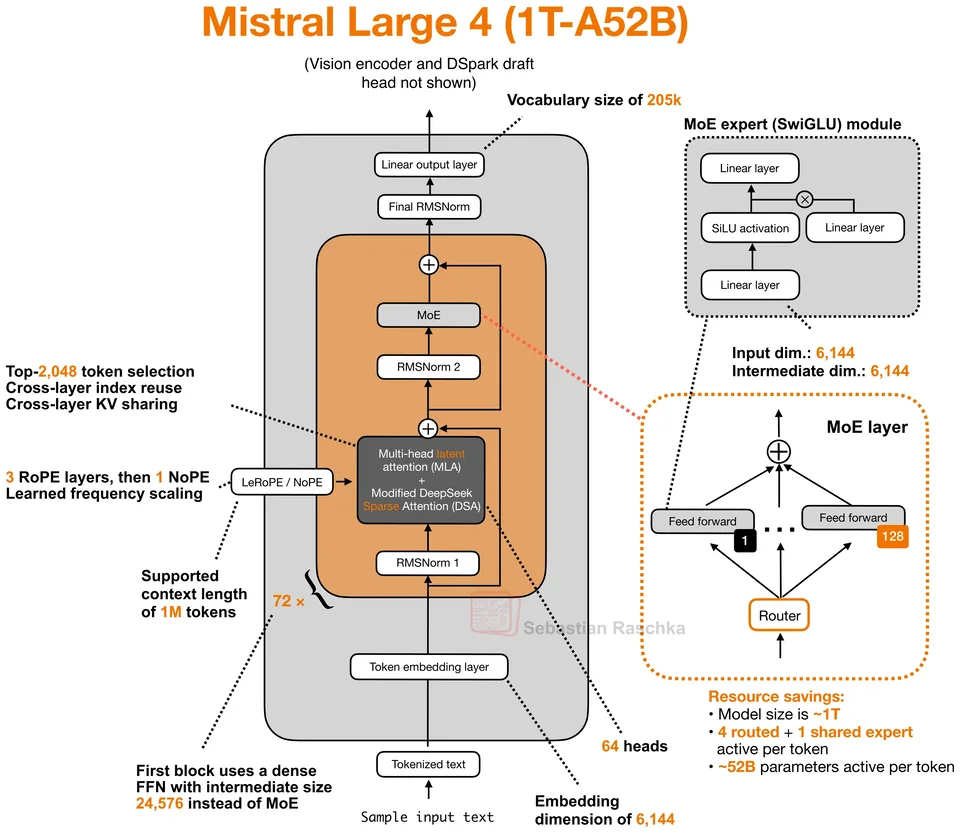
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Jump to a model, concept or page