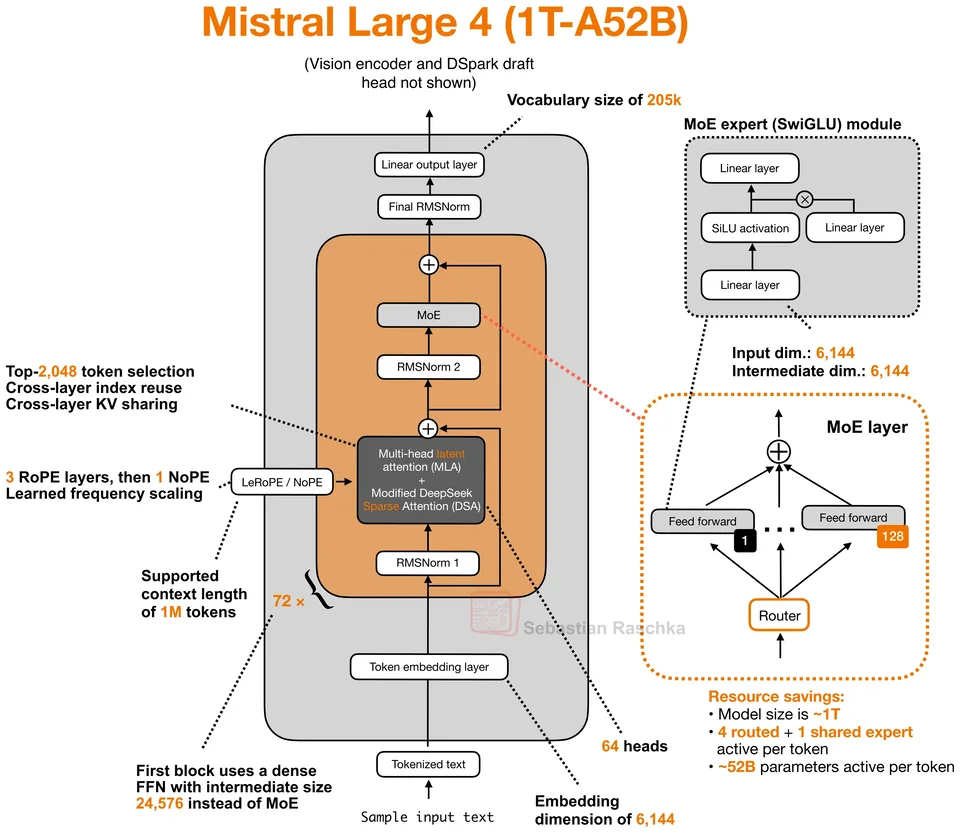
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Attention · MLA
Keys and values are compressed into a small latent vector that is cached instead of full K/V.
Instead of sharing KV heads (as GQA does), MLA down-projects each token's keys and values into a compact latent and stores only that latent in the cache. At attention time it is projected back up.
Introduced with DeepSeek V2 and popularised by DeepSeek V3/R1, MLA reported quality on par with or better than MHA while caching far less per token. A decoupled RoPE path handles positional information.
Many large MoE models released since 2025 (Kimi, GLM-5, Mistral Large 3 and others) adopted MLA or variants of it.
Models in the atlas using MLA, per half-year of release.
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
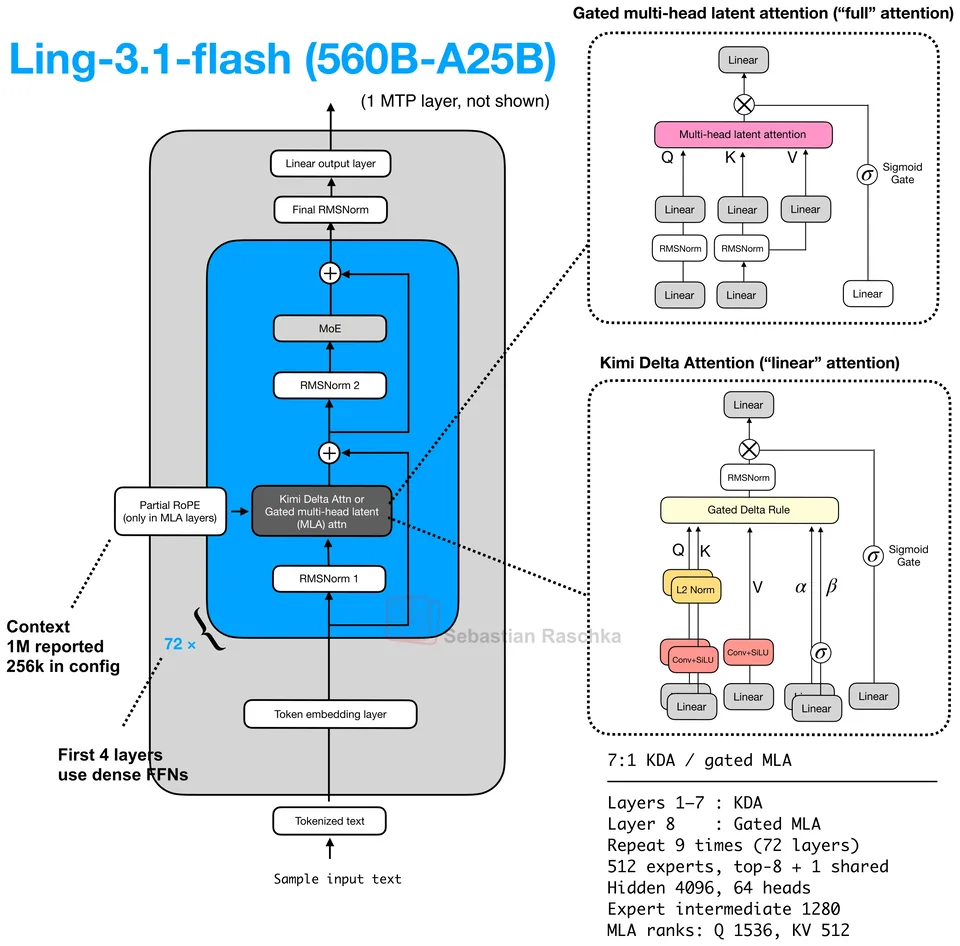
InclusionAI, released 2026-10-13. Hybrid MoE decoder, 560B total, 25B active, 1M context. Attention: 7:1 Kimi Delta Attention and gated MLA.
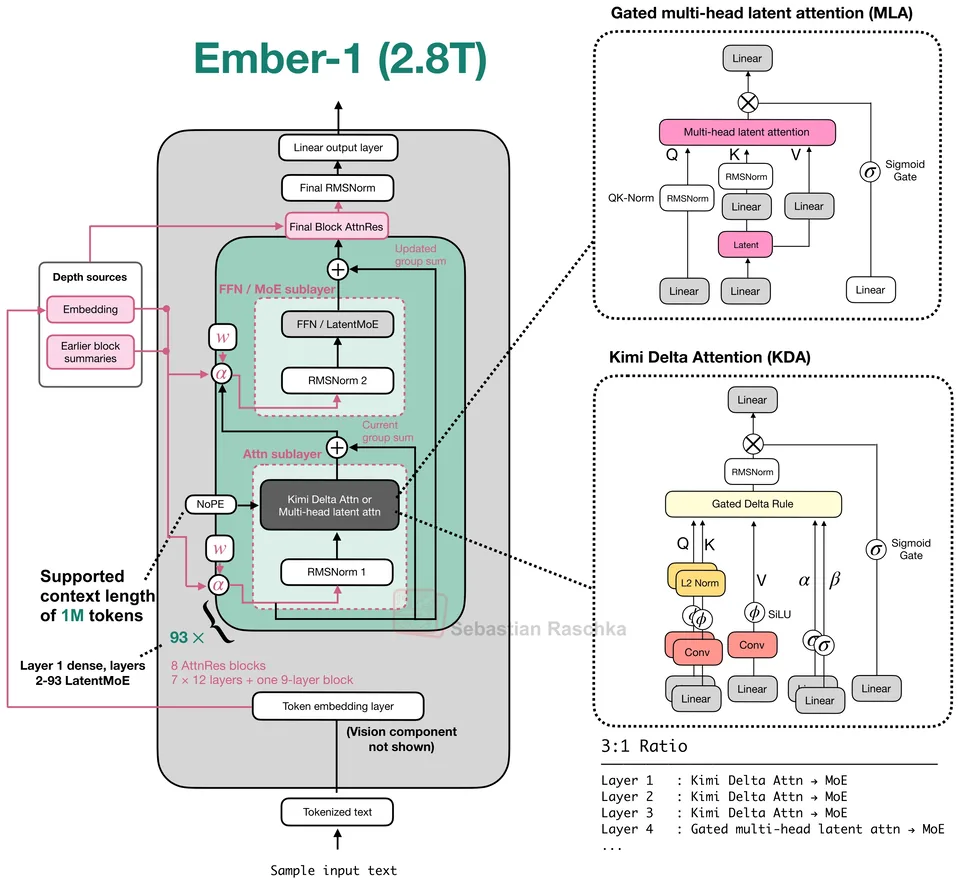
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
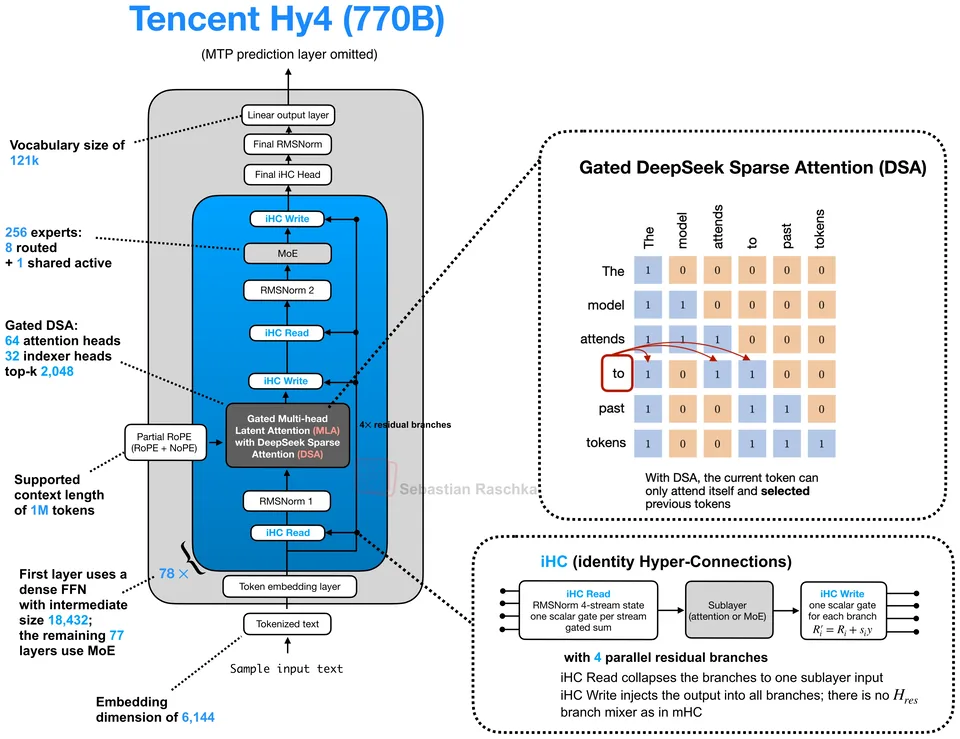
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
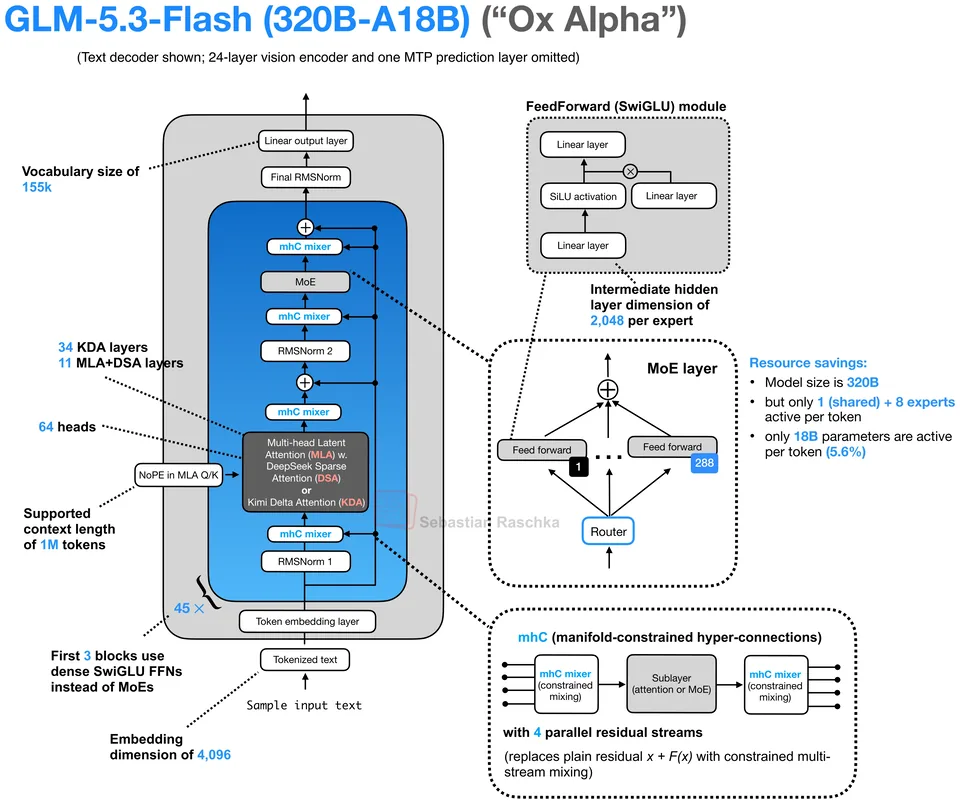
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
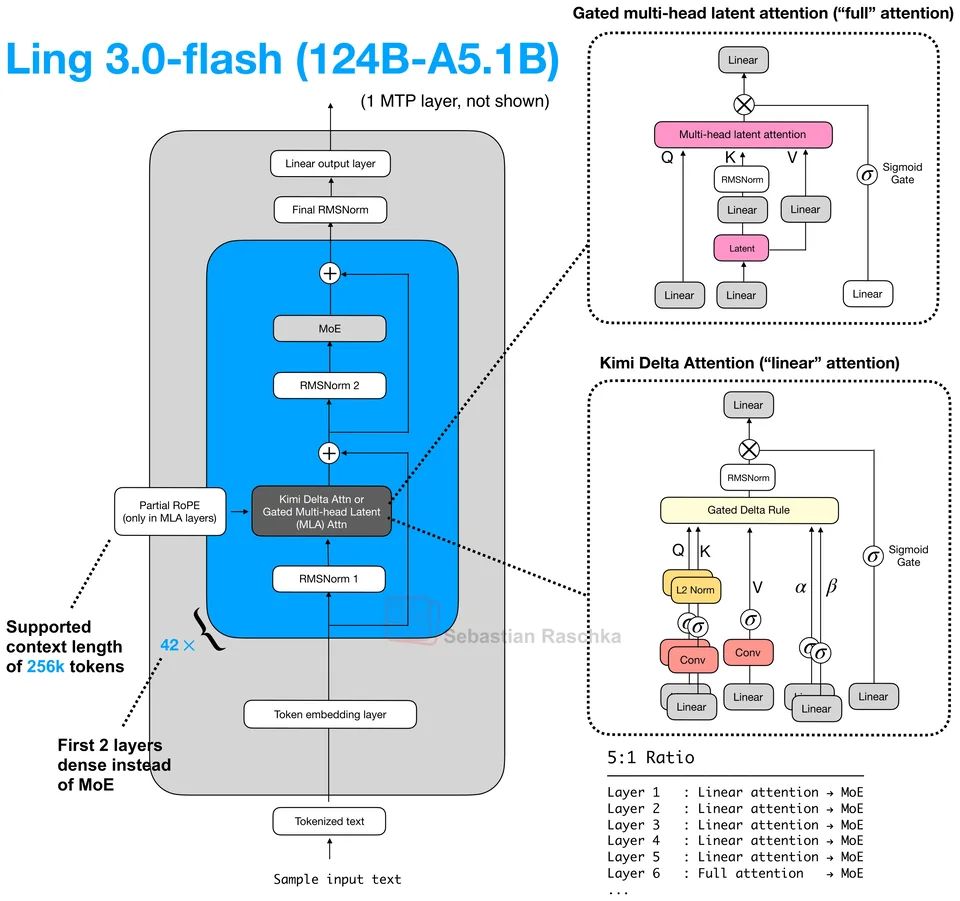
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
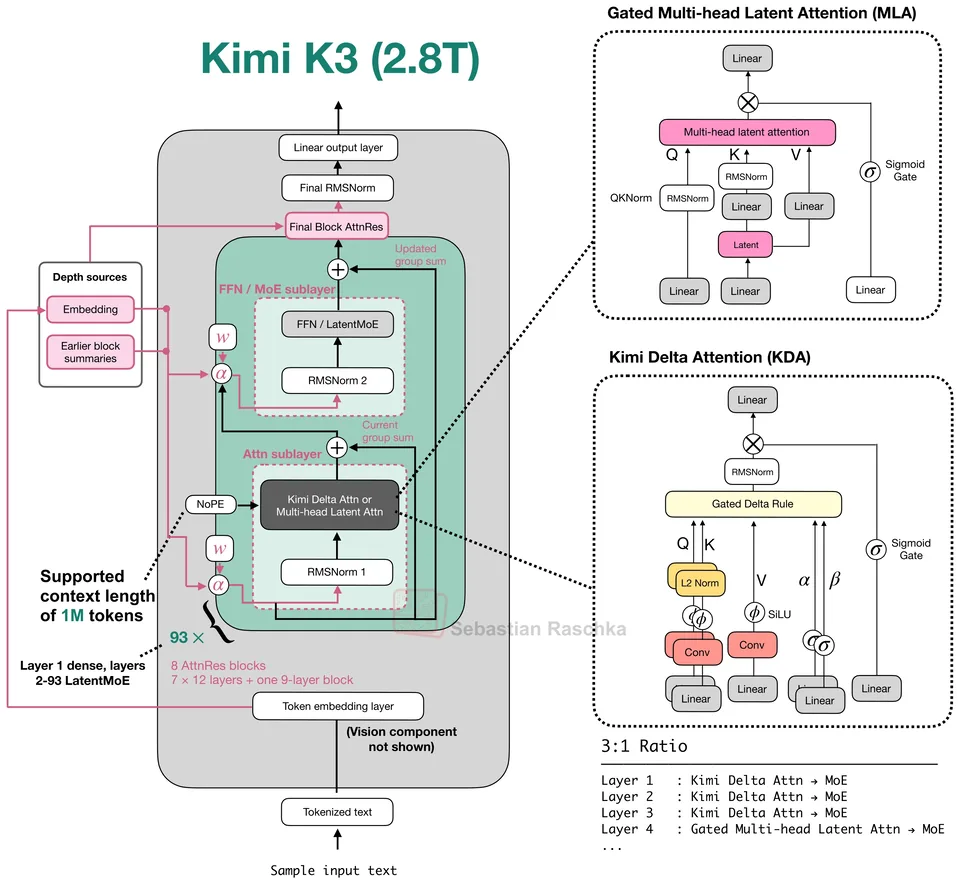
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Motif Technologies, released 2026-07-21. Sparse MoE decoder, 314B total, 13B active, 256K context. Attention: GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention.
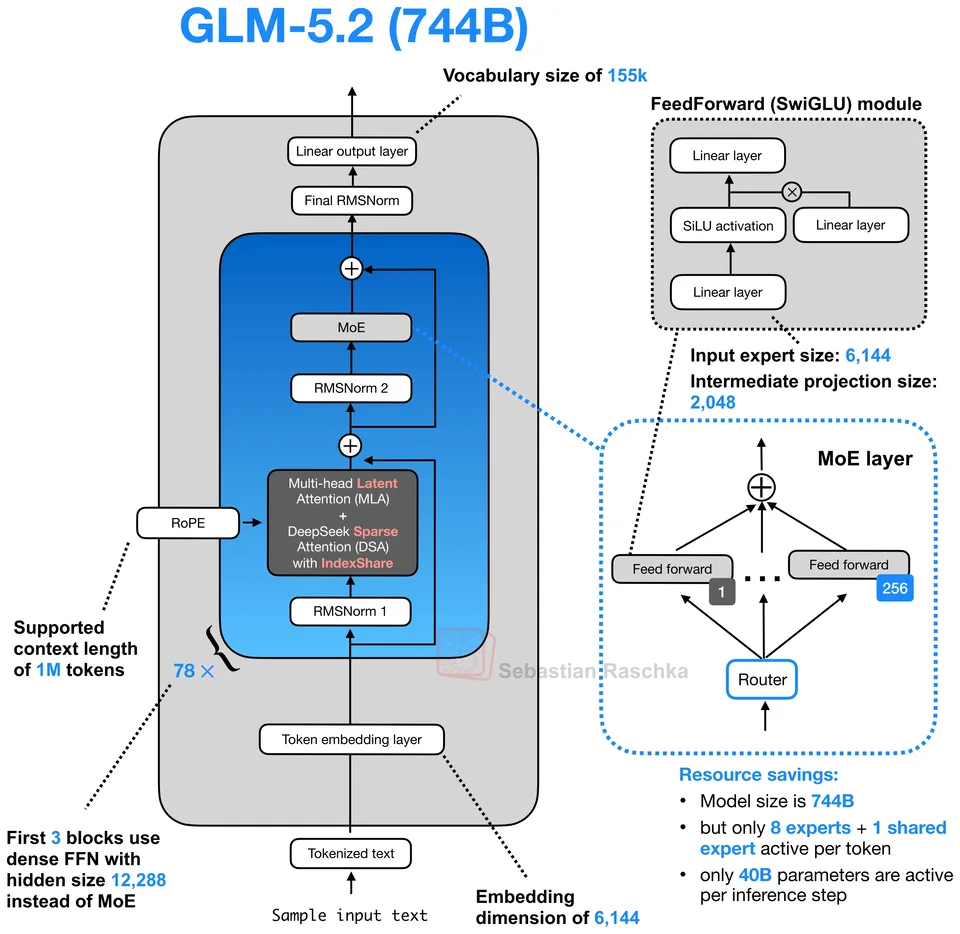
Z.ai, released 2026-06-17. Sparse MoE decoder, 744B total, 40B active, 1M context. Attention: MLA with DeepSeek Sparse Attention and IndexShare.

Moonshot AI, released 2026-06-12. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
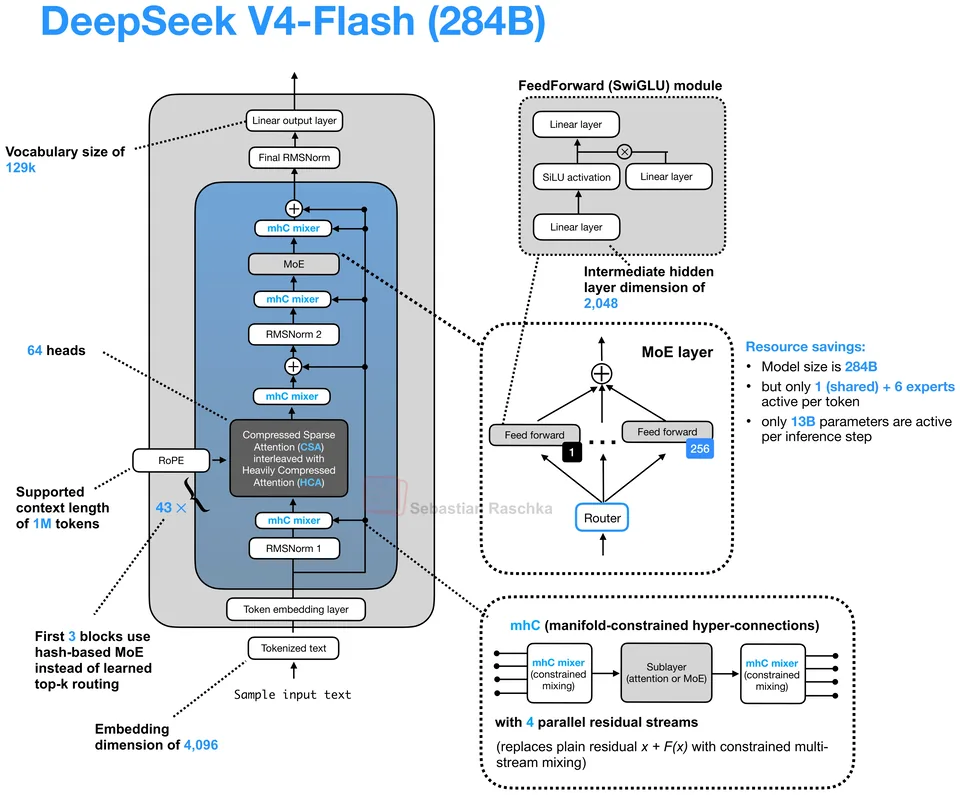
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

DeepSeek, released 2026-04-24. Sparse MoE decoder, 1.6T total, 49B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
Jump to a model, concept or page