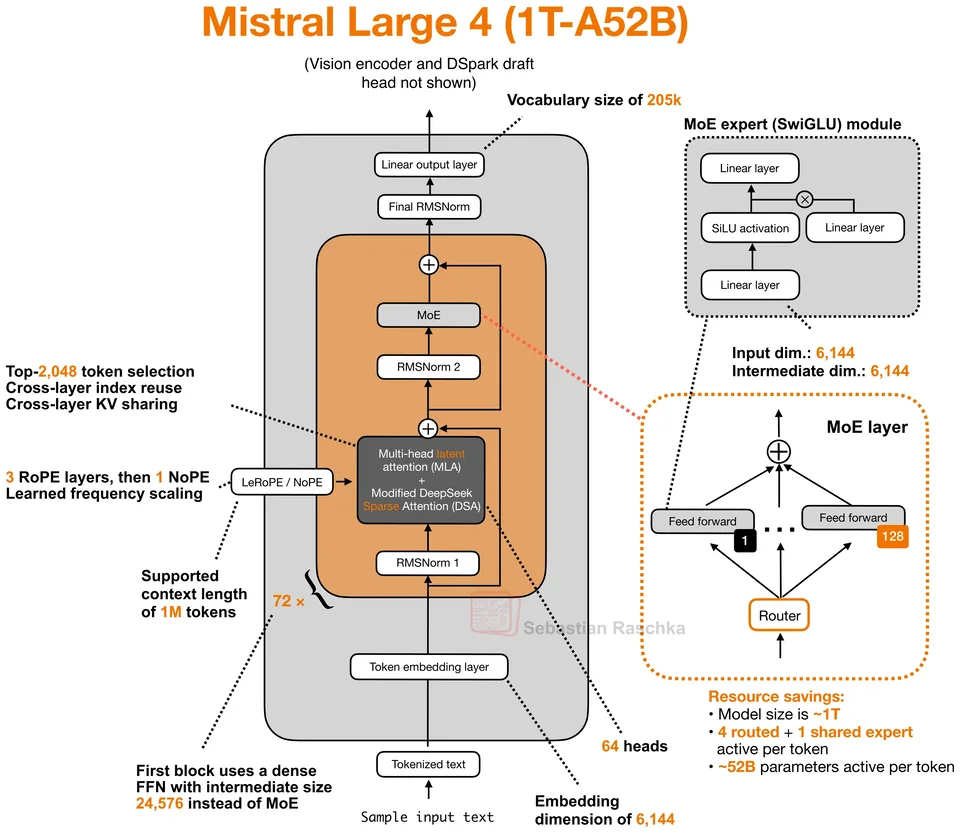
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Sparse & compressed attention · DSA
A lightweight indexer scores past tokens and each query attends only to its top-k picks.
DSA adds a small, fast indexer that estimates how relevant each earlier token is to the current query. A selector keeps the top-k tokens (2,048 in DeepSeek's code), and full attention is computed only over those.
Unlike a fixed sliding window, the selection is learned and can reach anywhere in the context. It was introduced with DeepSeek V3.2 on top of MLA and later adopted by GLM-5.
Models in the atlas using DSA, per half-year of release.
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
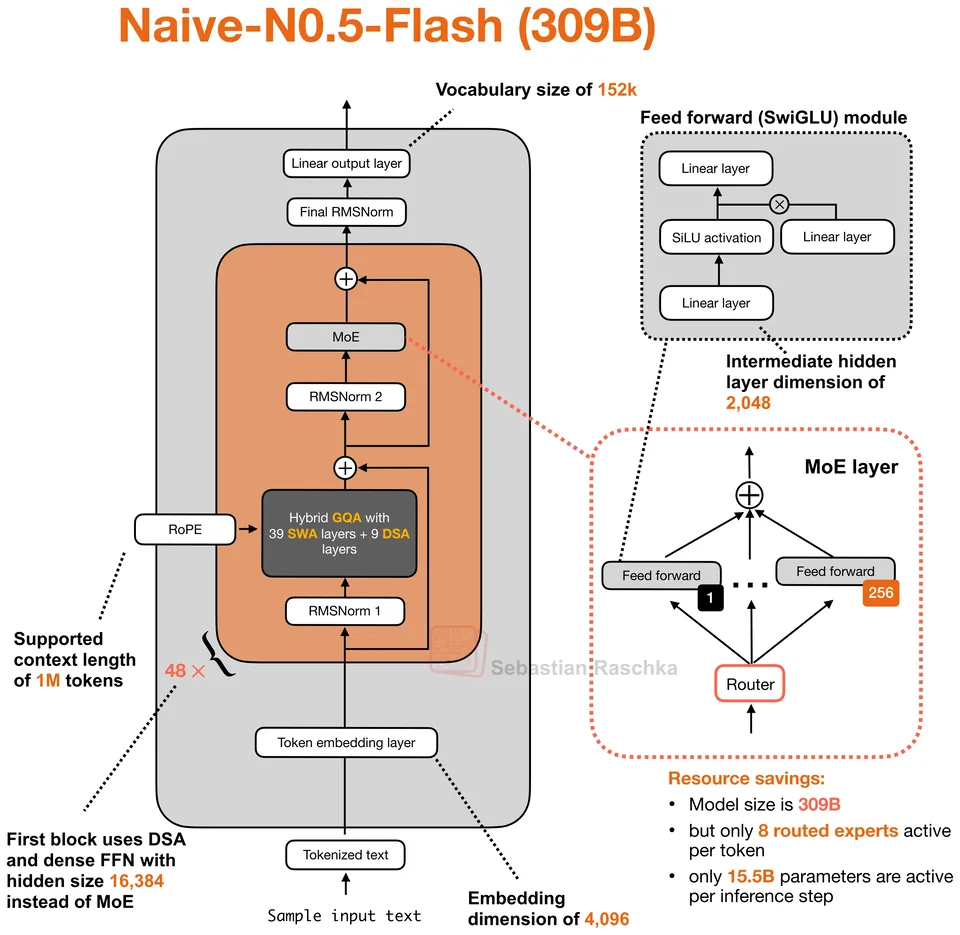
NaiveAI, released 2026-09-27. Sparse MoE decoder, 309B total, 16B active, 1M context. Attention: GQA with sliding-window attention and DeepSeek Sparse Attention.
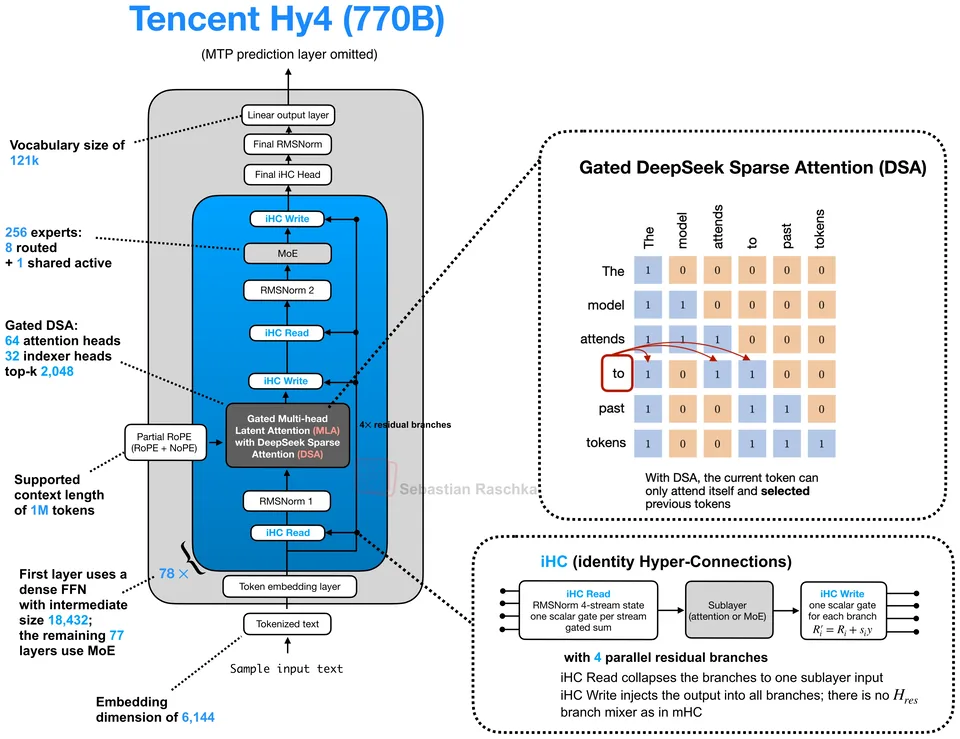
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
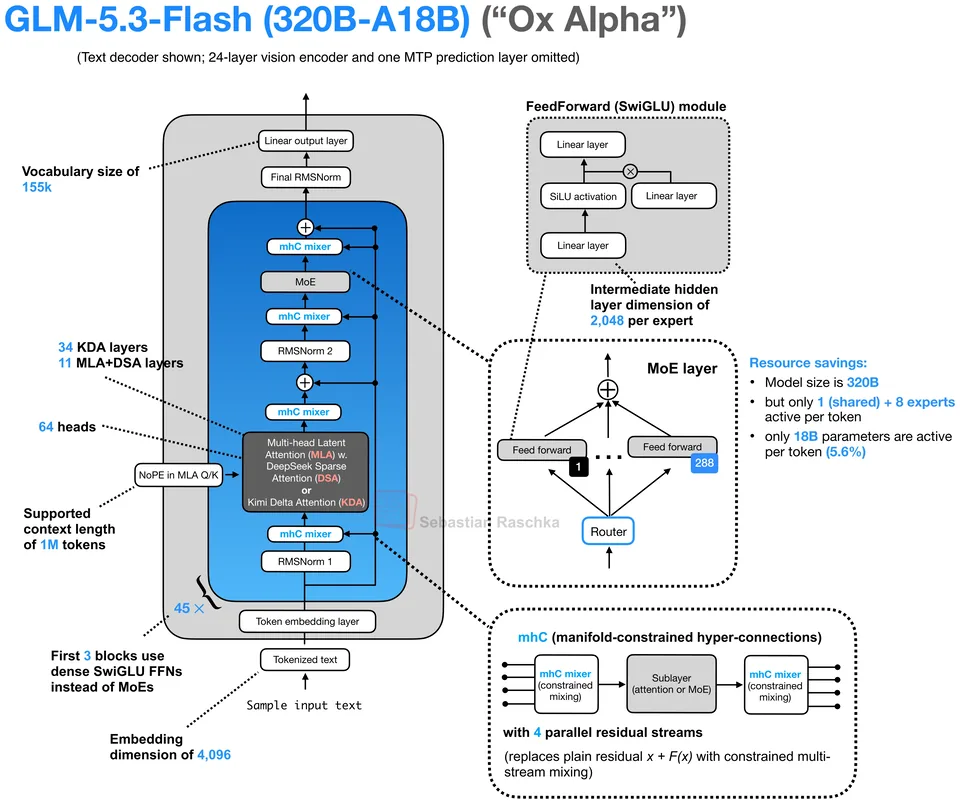
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
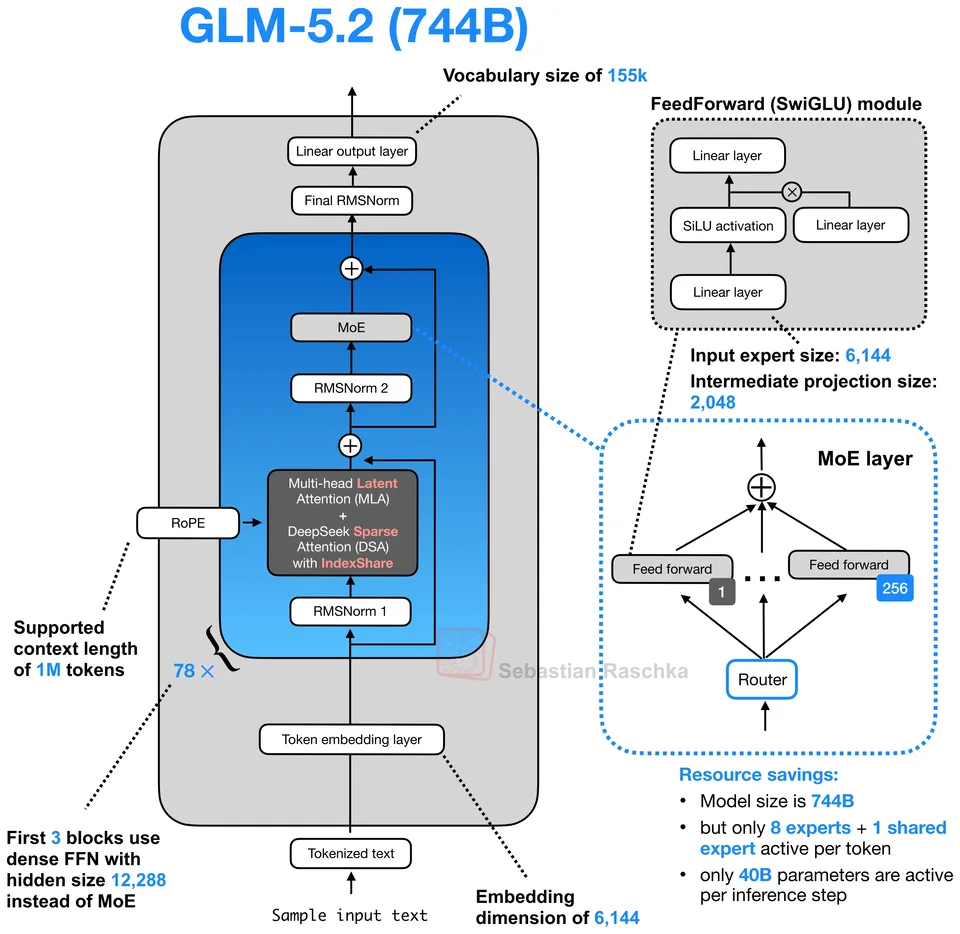
Z.ai, released 2026-06-17. Sparse MoE decoder, 744B total, 40B active, 1M context. Attention: MLA with DeepSeek Sparse Attention and IndexShare.
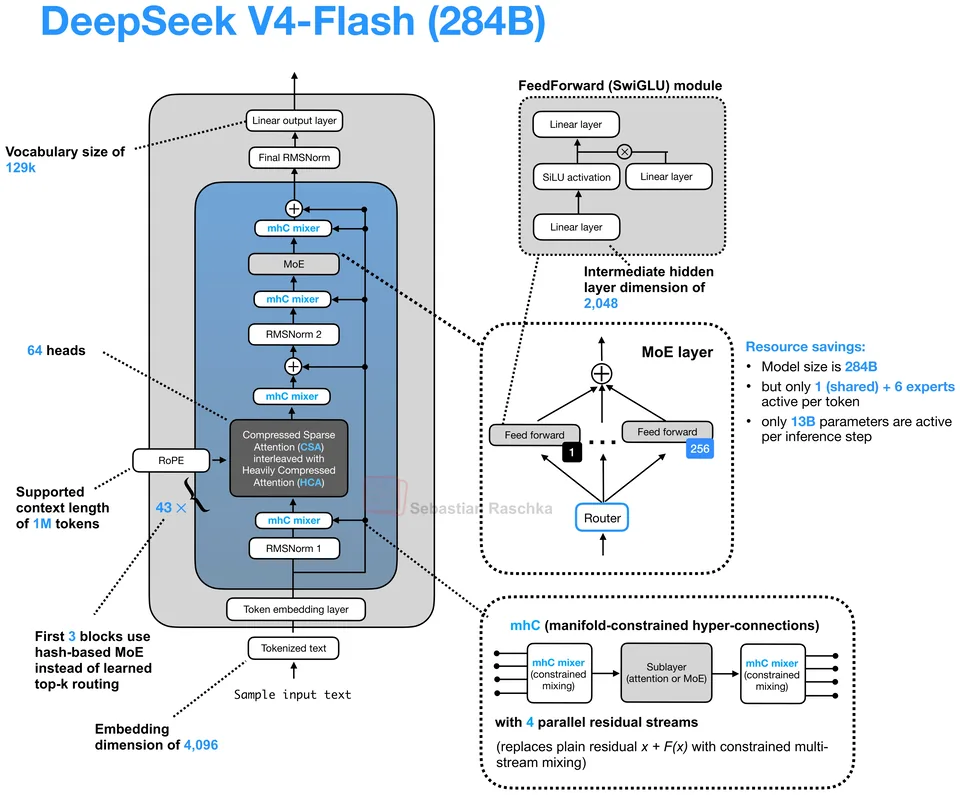
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

DeepSeek, released 2026-04-24. Sparse MoE decoder, 1.6T total, 49B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

Z.ai, released 2026-04-07. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

DeepSeek, released 2025-12-01. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA with DeepSeek Sparse Attention.
Jump to a model, concept or page