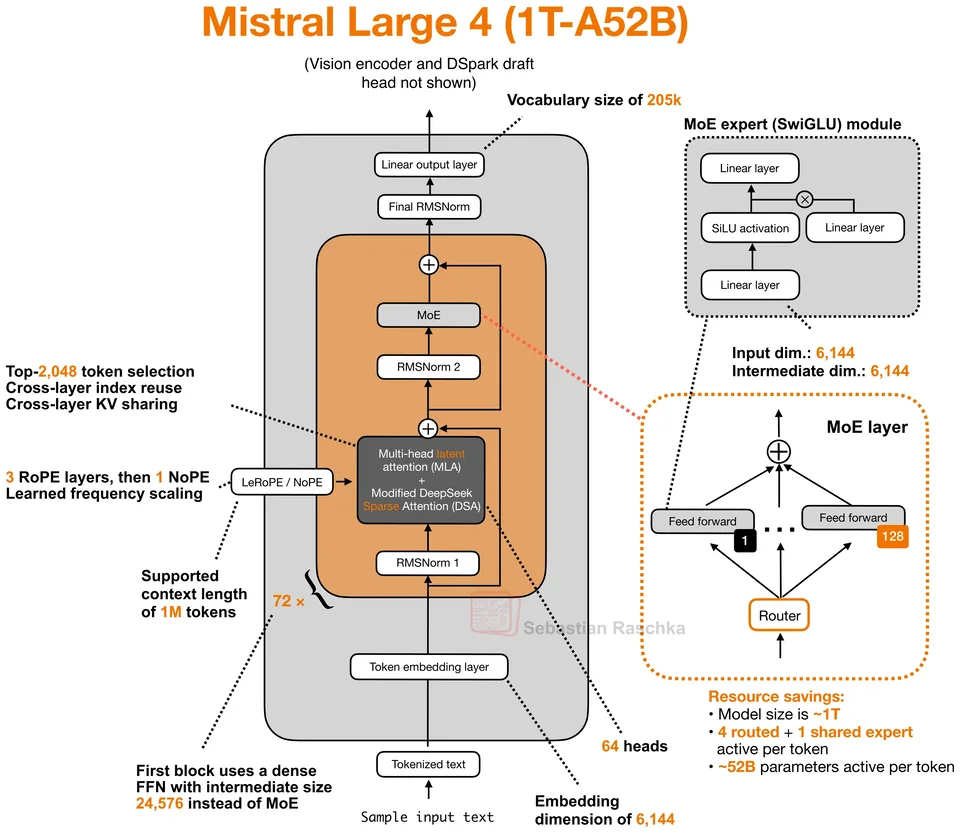
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Sparse & compressed attention · IndexShare
Nearby layers reuse the token selection computed by one DSA indexer.
Computing a DSA indexer in every layer still costs time. IndexShare computes the top-k selection once and lets the following layers (three, in GLM-5.2) reuse it.
The goal is to keep most of the quality of per-layer selection while cutting the indexer overhead.
Models in the atlas using IndexShare, per half-year of release.
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
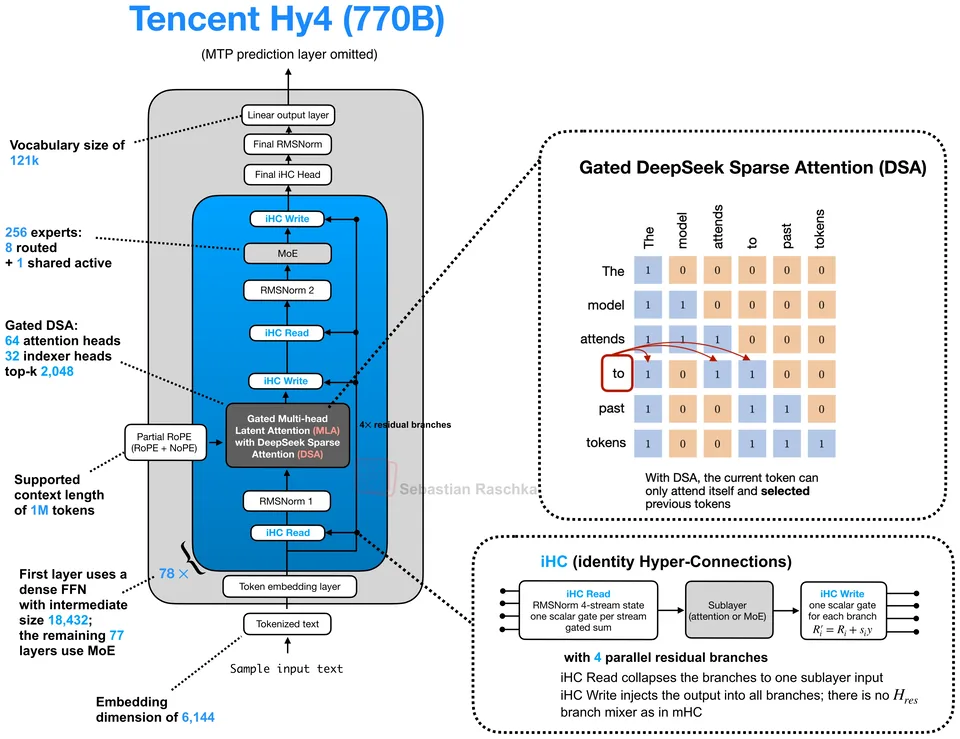
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
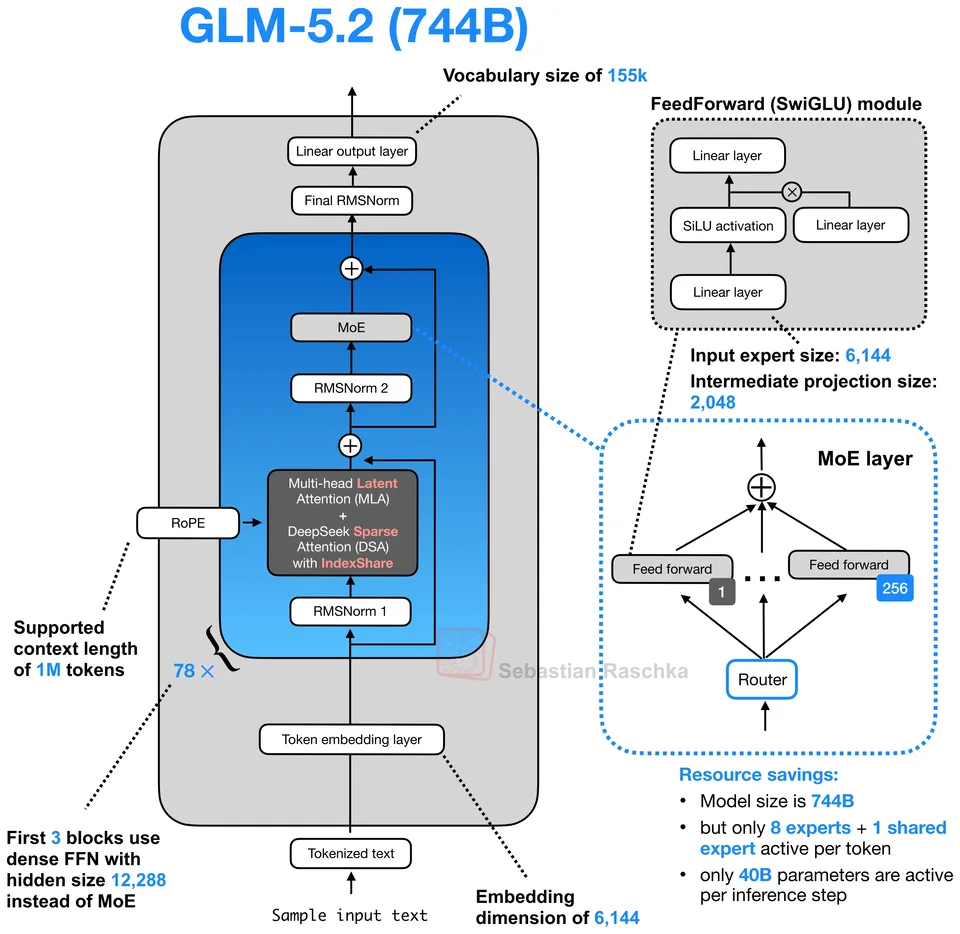
Z.ai, released 2026-06-17. Sparse MoE decoder, 744B total, 40B active, 1M context. Attention: MLA with DeepSeek Sparse Attention and IndexShare.
Jump to a model, concept or page