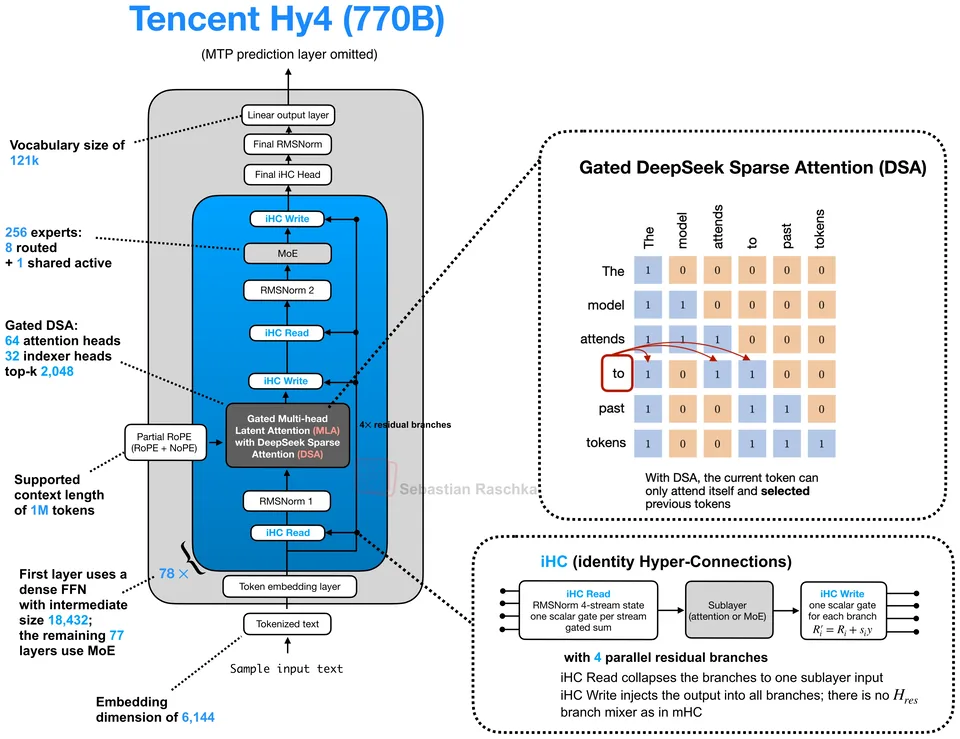
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
Long-context GLM refresh that keeps the 744B sparse MoE backbone and adds IndexShare for 1M-token DSA inference.
Key detail
Reuses each full DSA indexer result across the next three layers, making 1M-token sparse attention cheaper.Total params
744B
Active / token
40B
Context
1M
Parameters active per token
5.4%
40B of 744B weights run for each token.
33.7
Use the ← and → keys to step through releases.
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
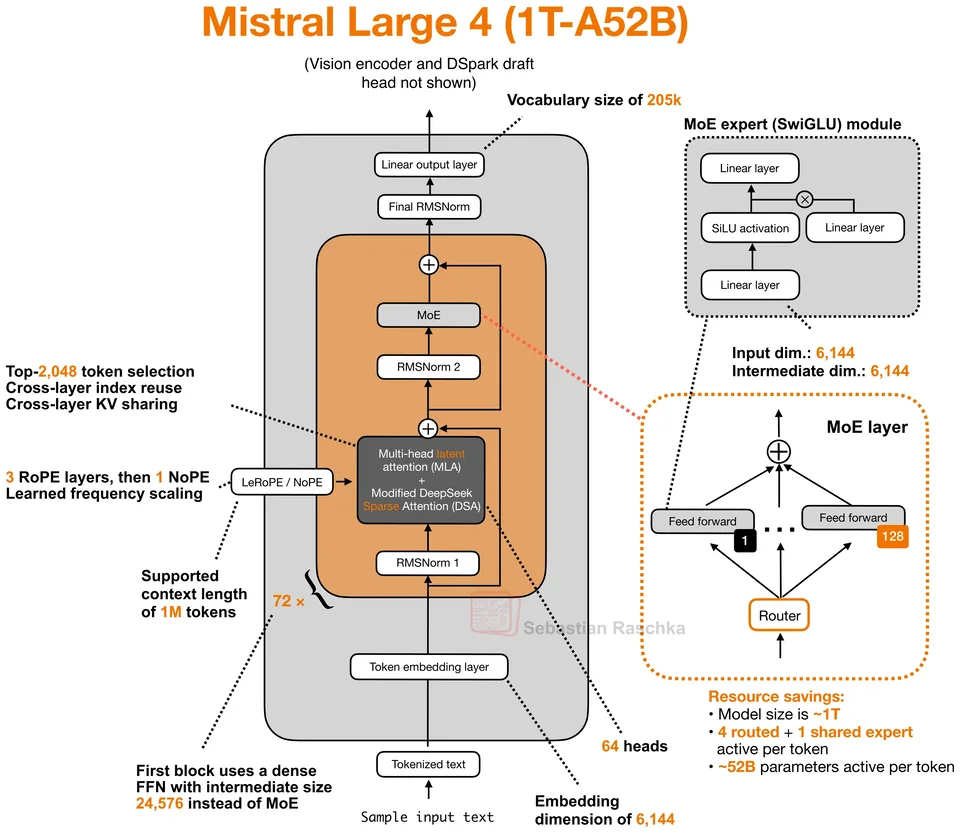
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-04-07. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.
Jump to a model, concept or page