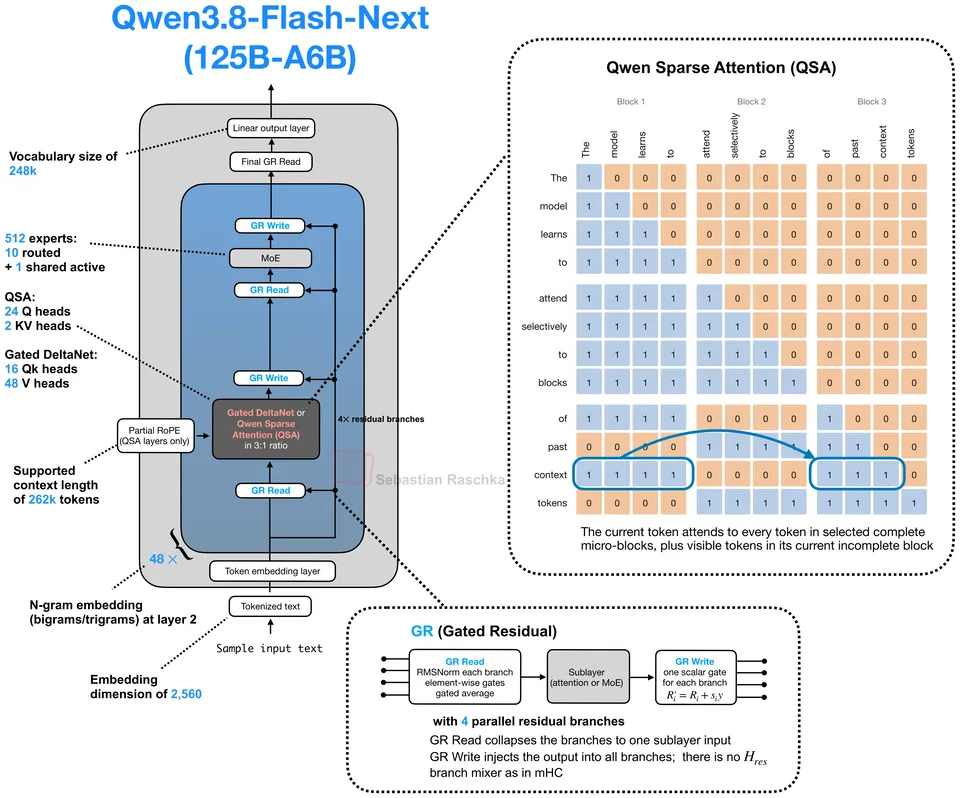
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
Sparse & compressed attention · QSA
Like DSA, but the indexer picks whole four-token blocks rather than single tokens.
The indexer averages keys within each complete four-token block, scores the pooled keys against the query, and expands the winning blocks back into their tokens. The current incomplete block is always visible.
Selecting contiguous blocks is friendlier to memory access patterns than scattering over individual token positions.
Models in the atlas using QSA, per half-year of release.
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
Jump to a model, concept or page