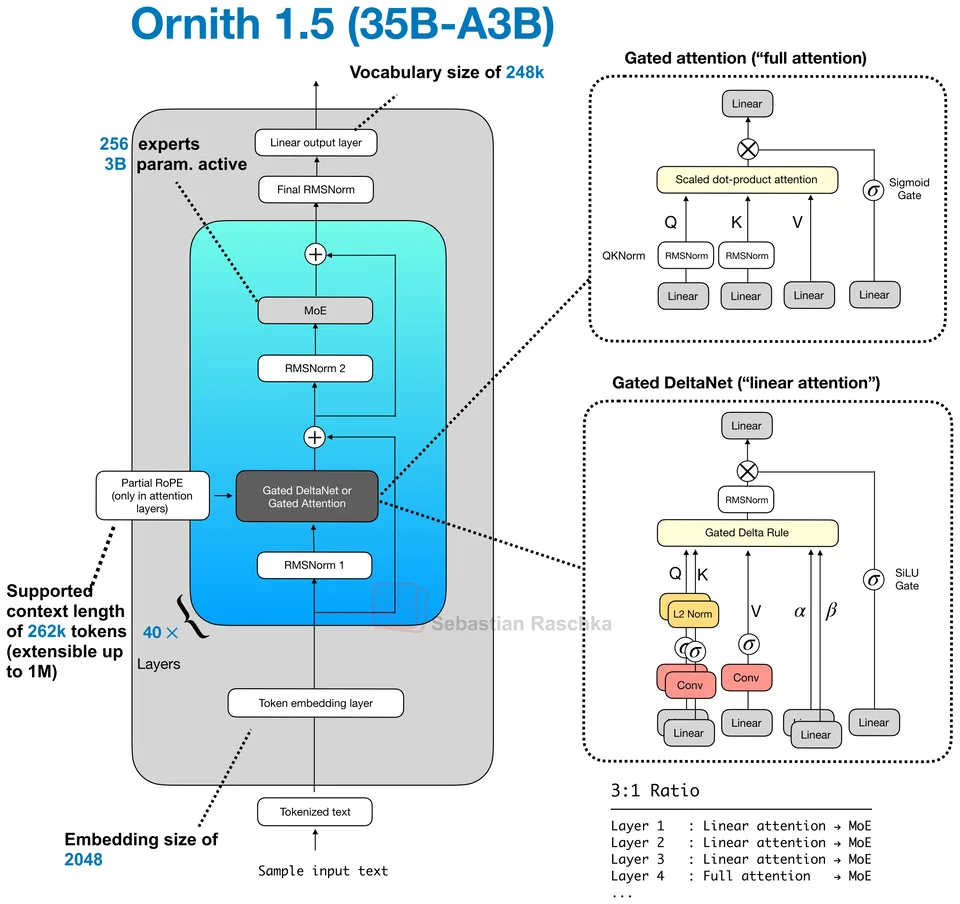
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
Experimental vision-language MoE whose text backbone combines Gated DeltaNet, micro-block QSA, four-branch gated residuals, and n-gram embeddings; the figure omits the vision encoder and MTP head.
Key detail
Replaces full attention with micro-block QSA while using four gated residual branches and a 20M-entry n-gram embedding at layer 2.Total params
125B
Active / token
6B
Context
256K
Parameters active per token
4.8%
6B of 125B weights run for each token.
Use the ← and → keys to step through releases.
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
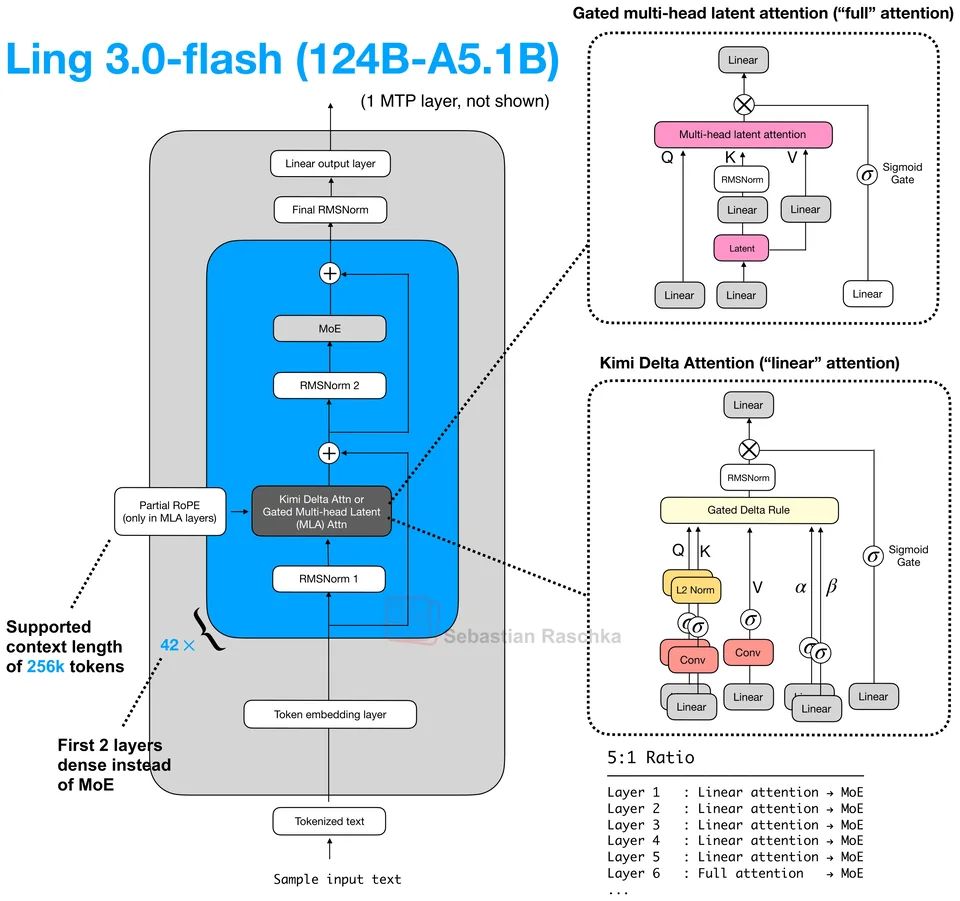
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.

NVIDIA, released 2026-03-11. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.
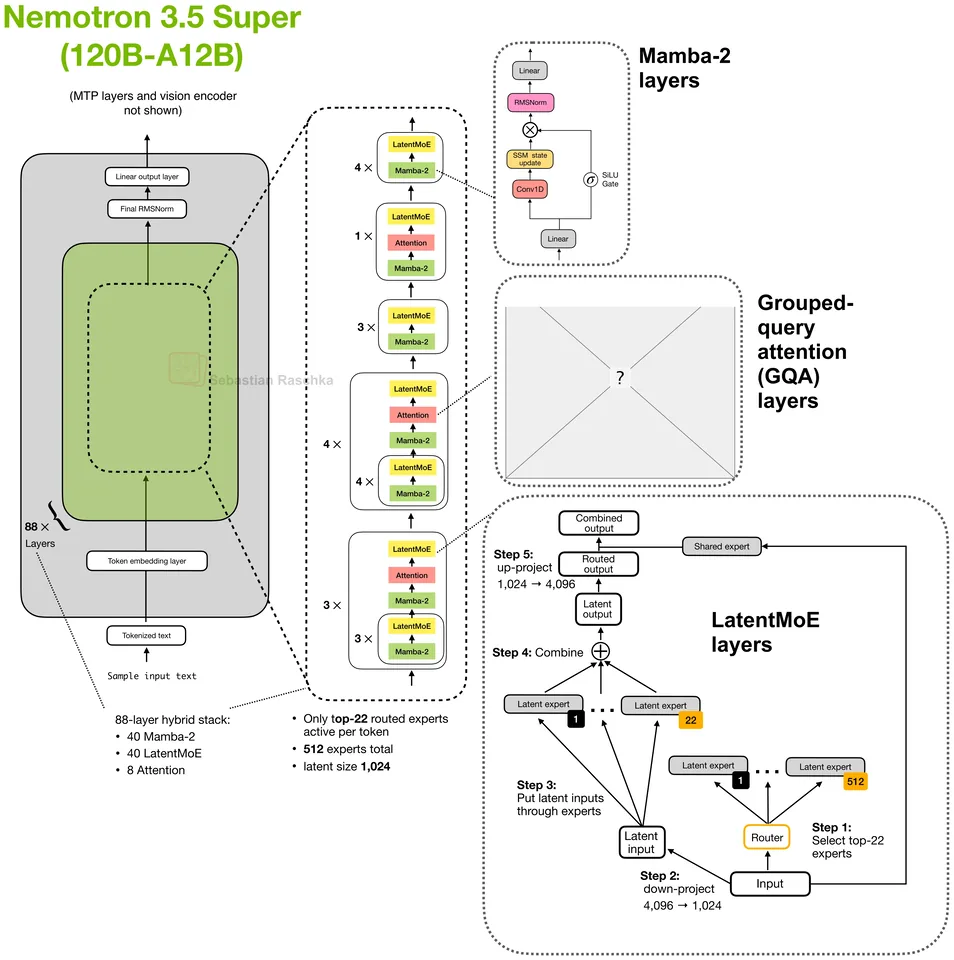
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
Jump to a model, concept or page