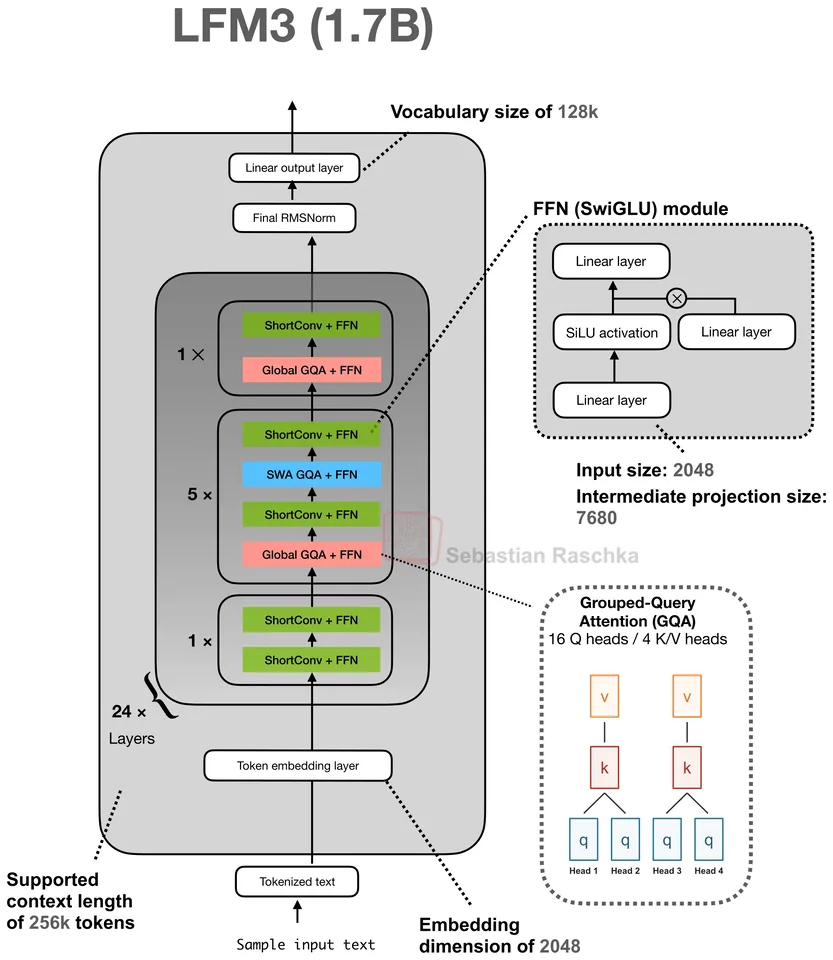
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
Positions & normalization · QK-Norm
RMSNorm applied to queries and keys before attention to keep logits well-behaved.
Normalising queries and keys (usually before RoPE) prevents attention logits from growing too large, a common source of loss spikes in large-scale training.
OLMo 2 and Qwen3 helped make it standard; it is now a default ingredient in many recipes.
Models in the atlas using QK-Norm, per half-year of release.
Often paired with
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
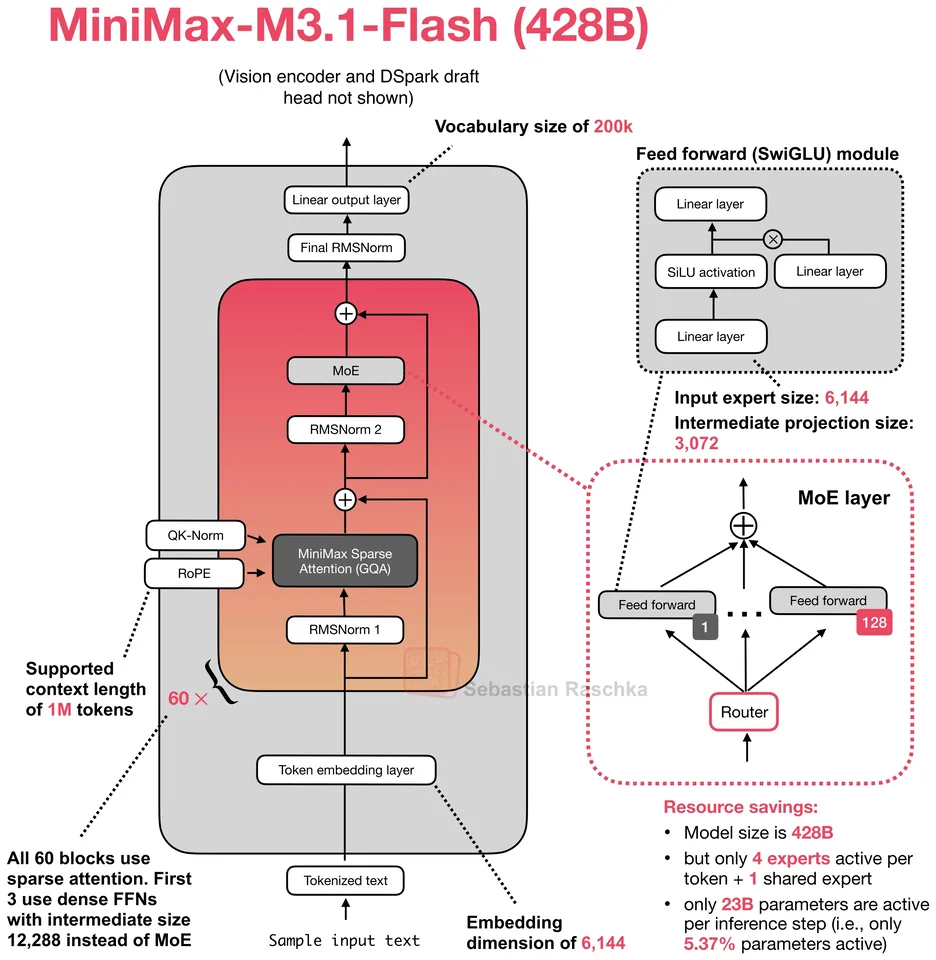
MiniMax, released 2026-10-19. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.
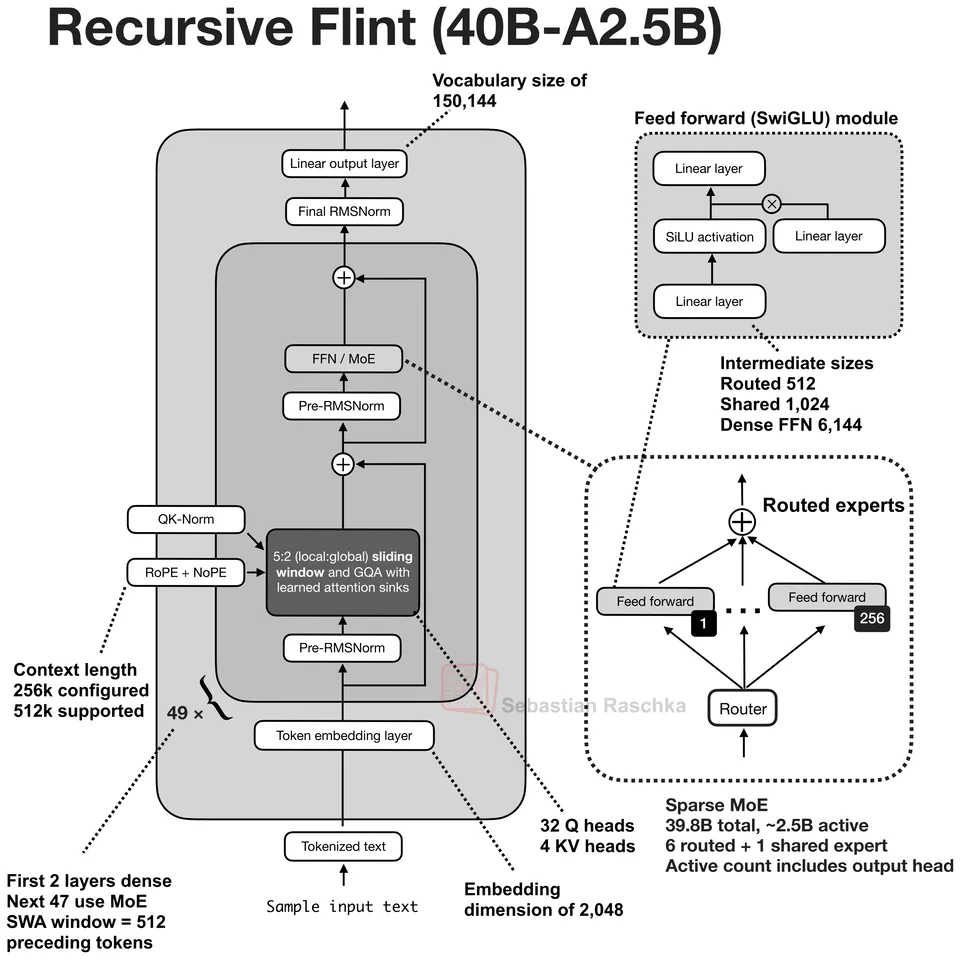
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
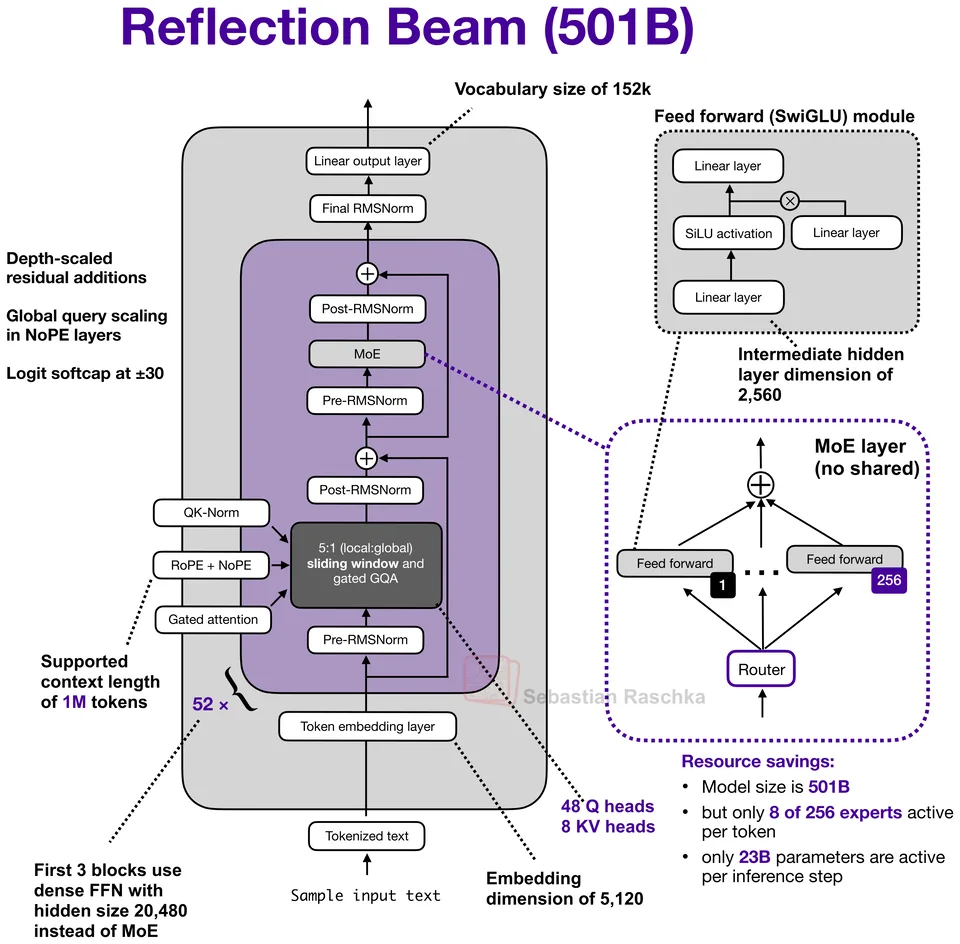
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
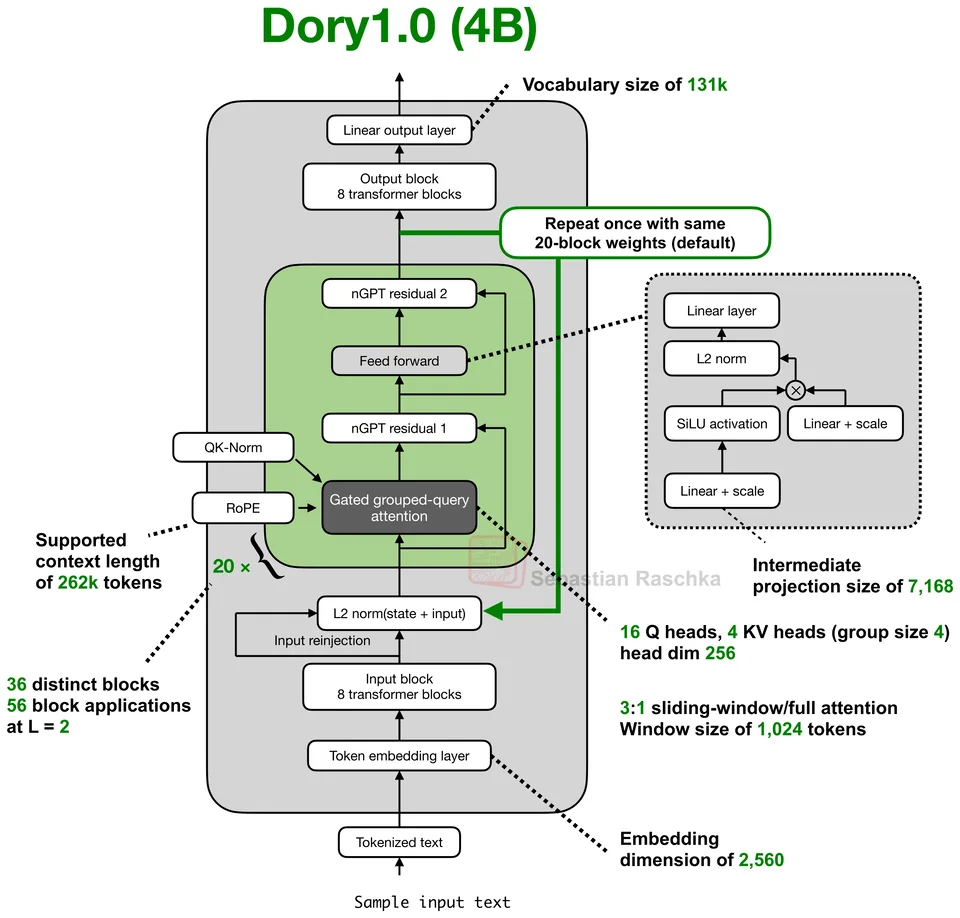
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.
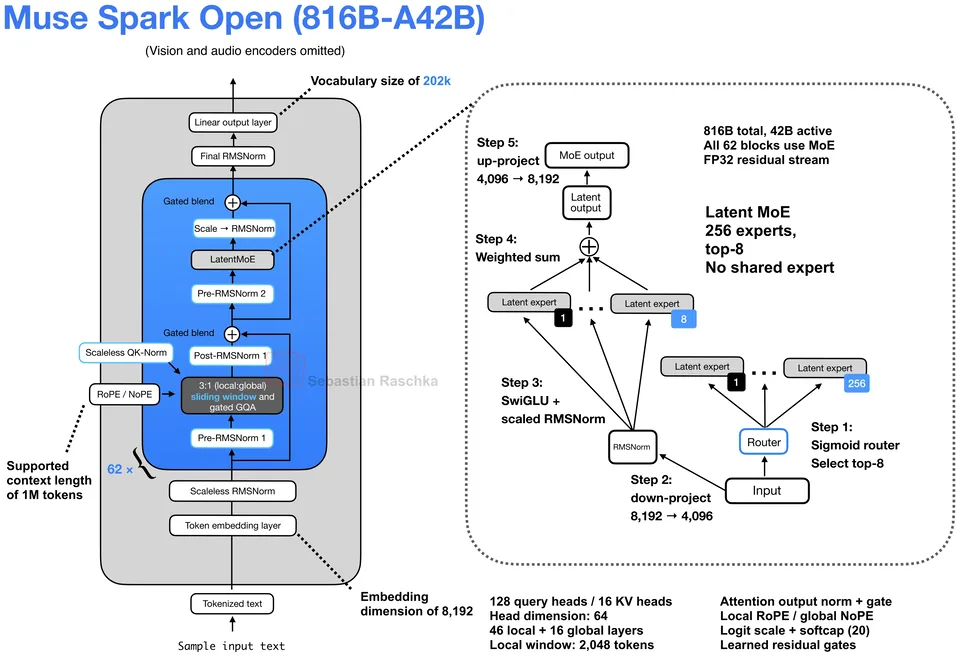
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
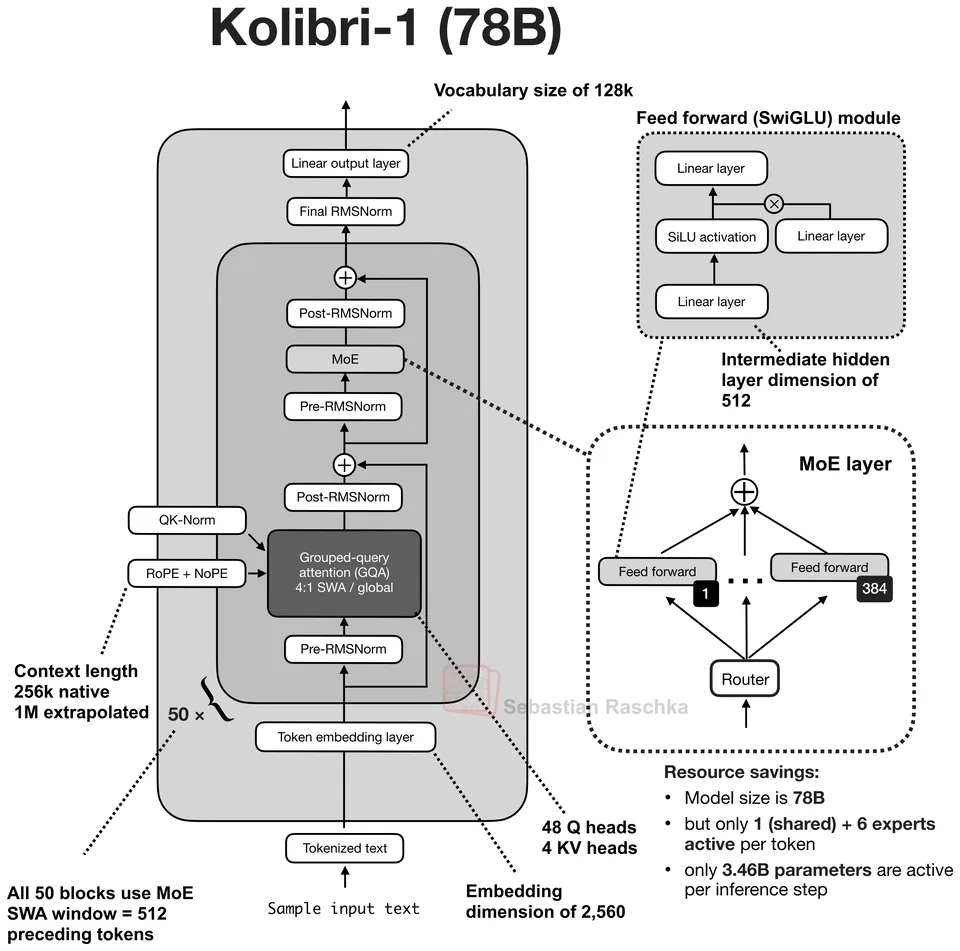
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.
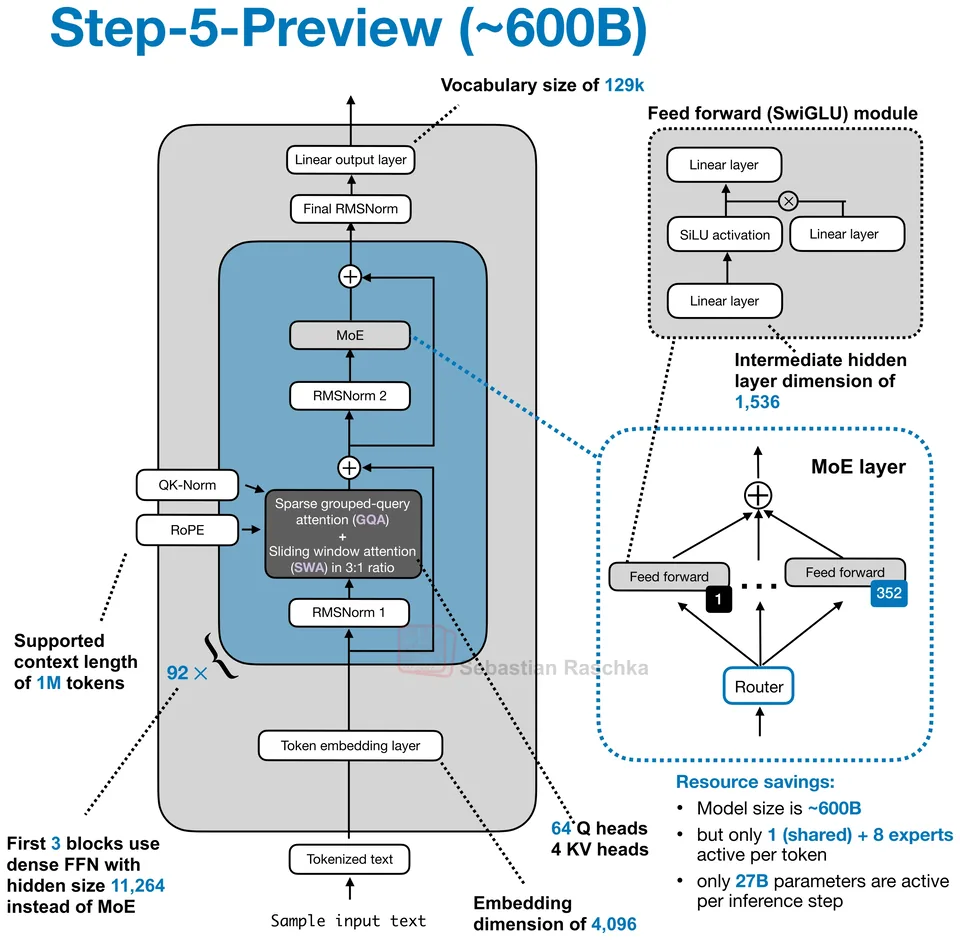
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
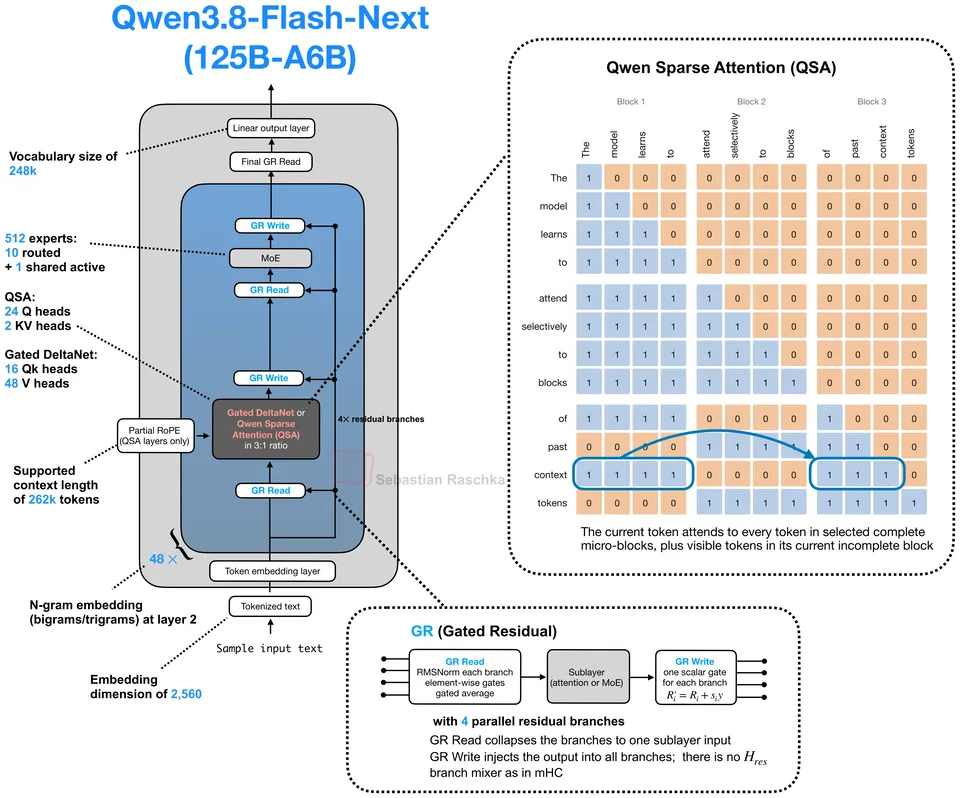
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
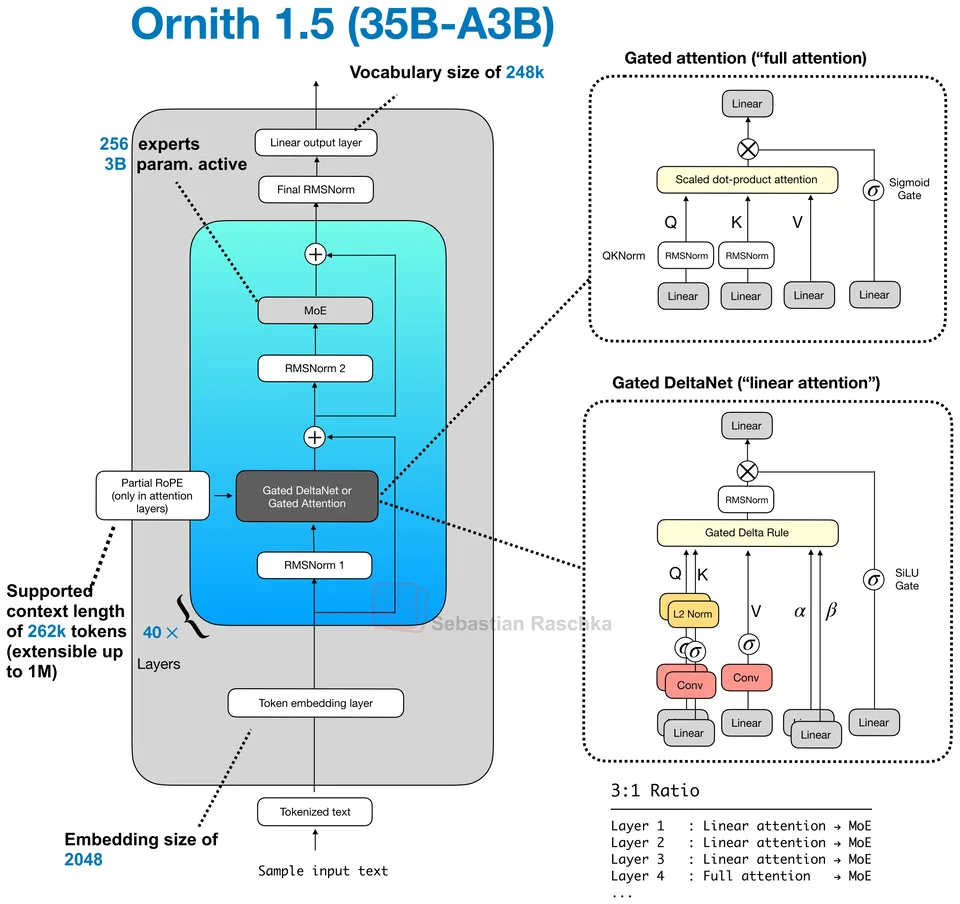
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
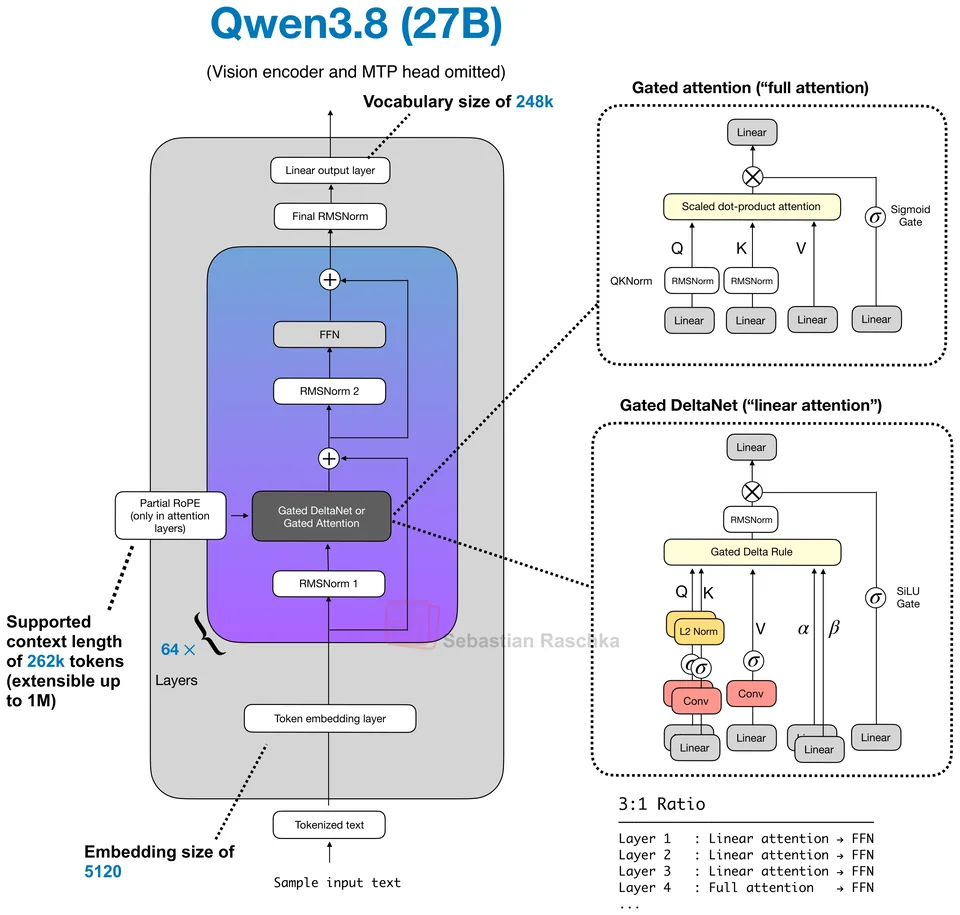
Alibaba Cloud, released 2026-08-14. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
Jump to a model, concept or page