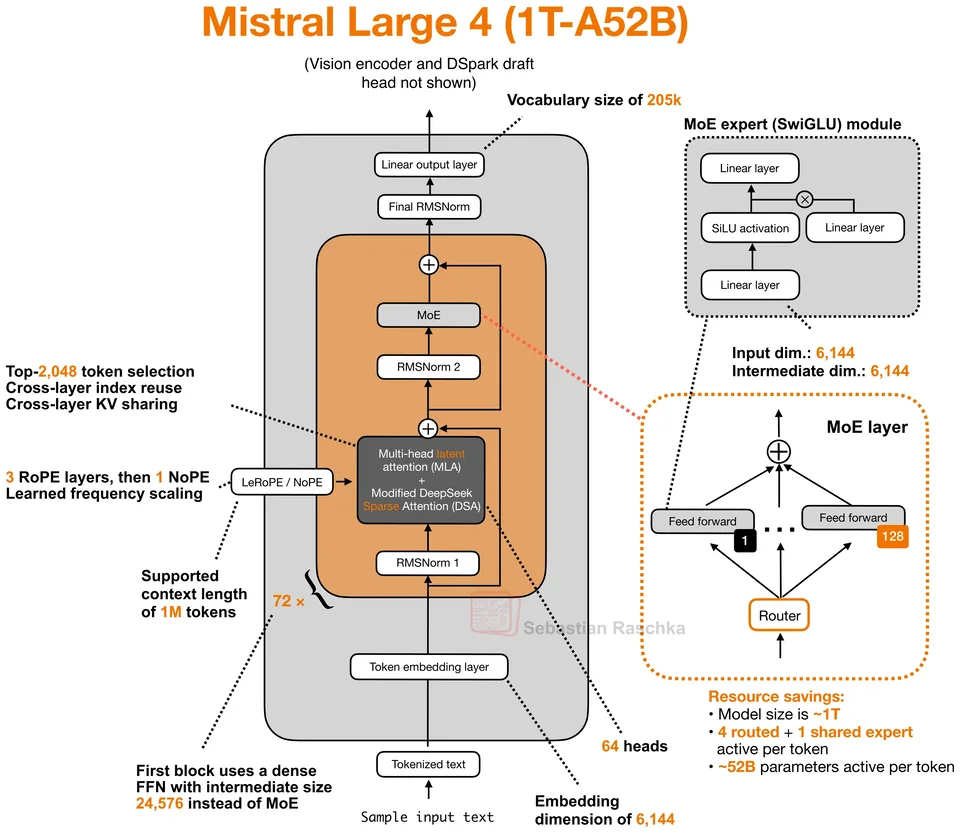
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Positions & normalization · NoPE
Some or all layers drop explicit positional encodings and rely on the causal mask.
Because a decoder's causal mask already prevents tokens from seeing the future, the model can infer order implicitly. NoPE layers omit RoPE entirely.
Studies suggest this can help length generalisation. SmolLM3 removes RoPE from every fourth layer; Kimi K3 goes NoPE throughout.
Models in the atlas using NoPE, per half-year of release.
Often paired with
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
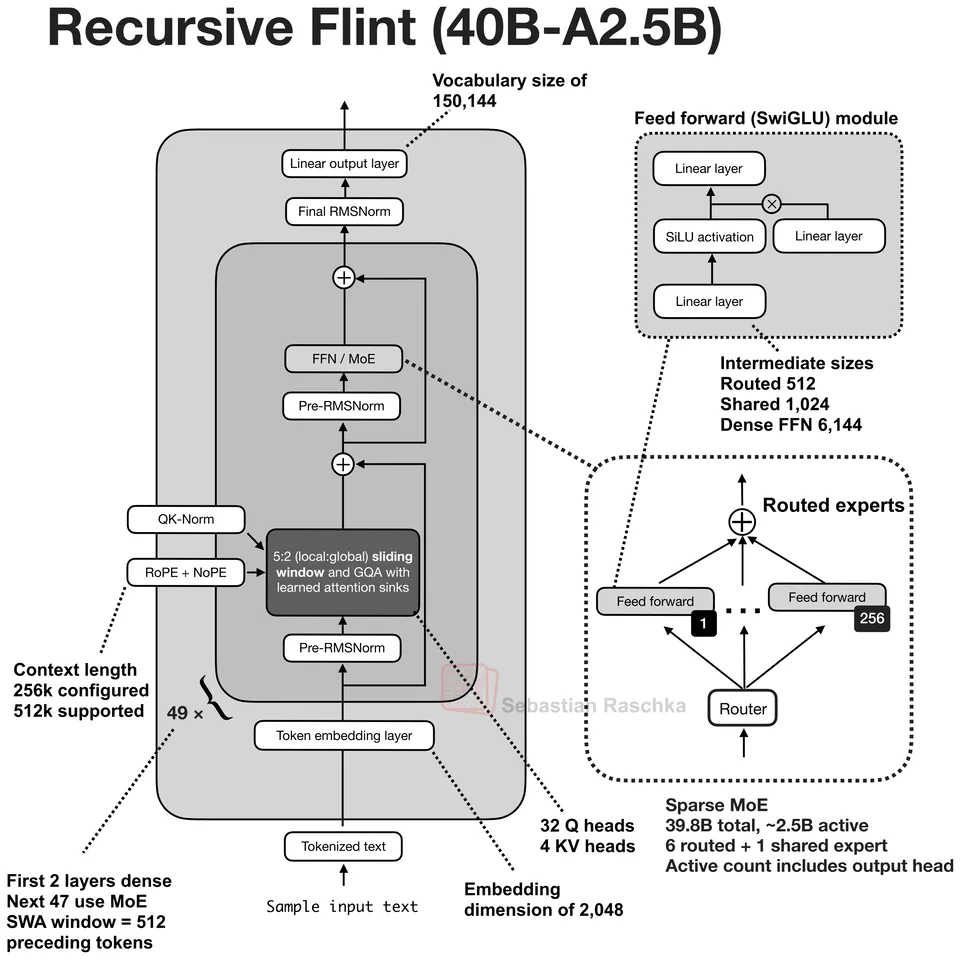
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
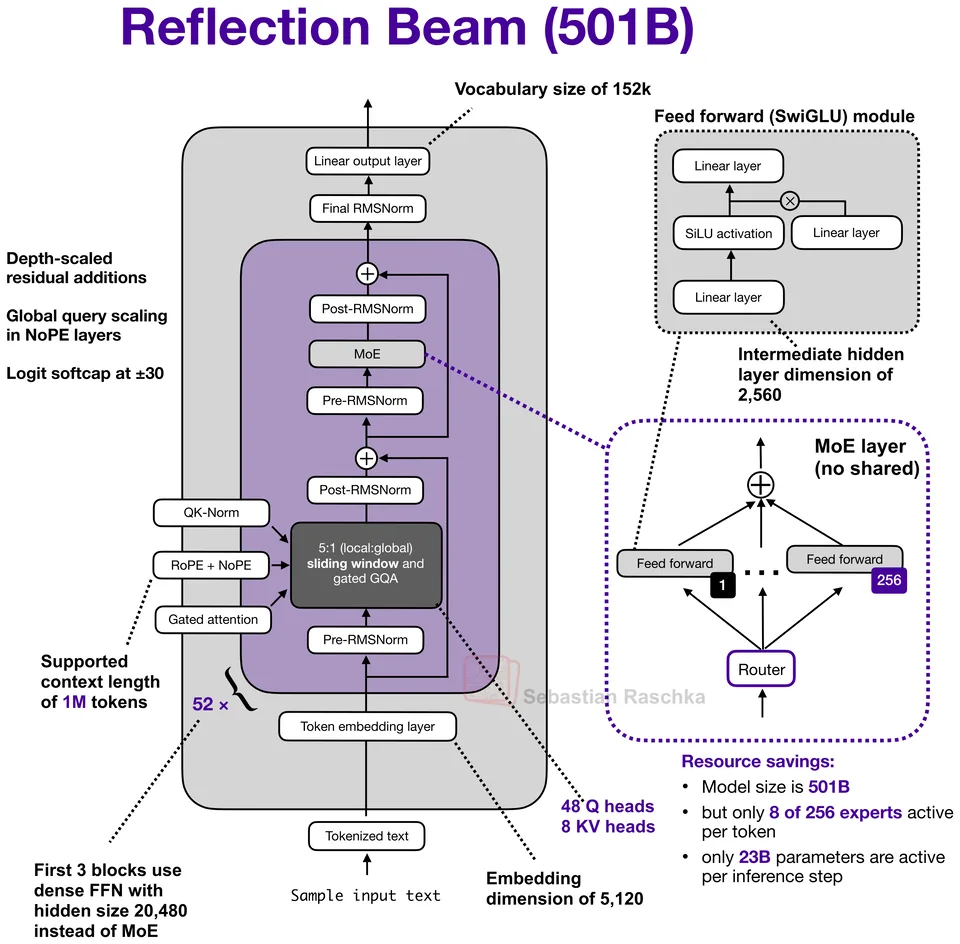
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
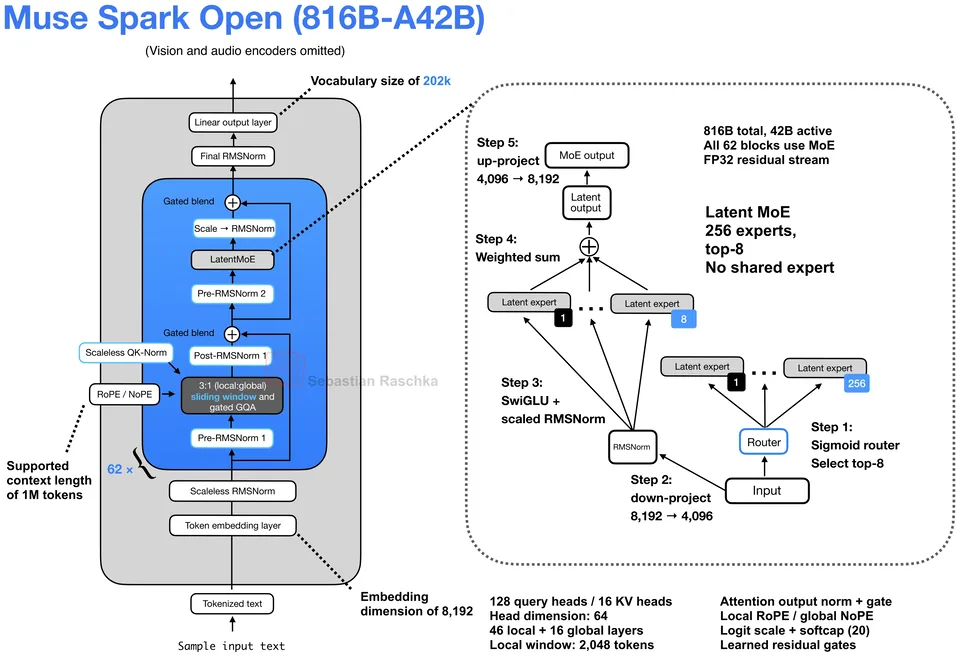
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
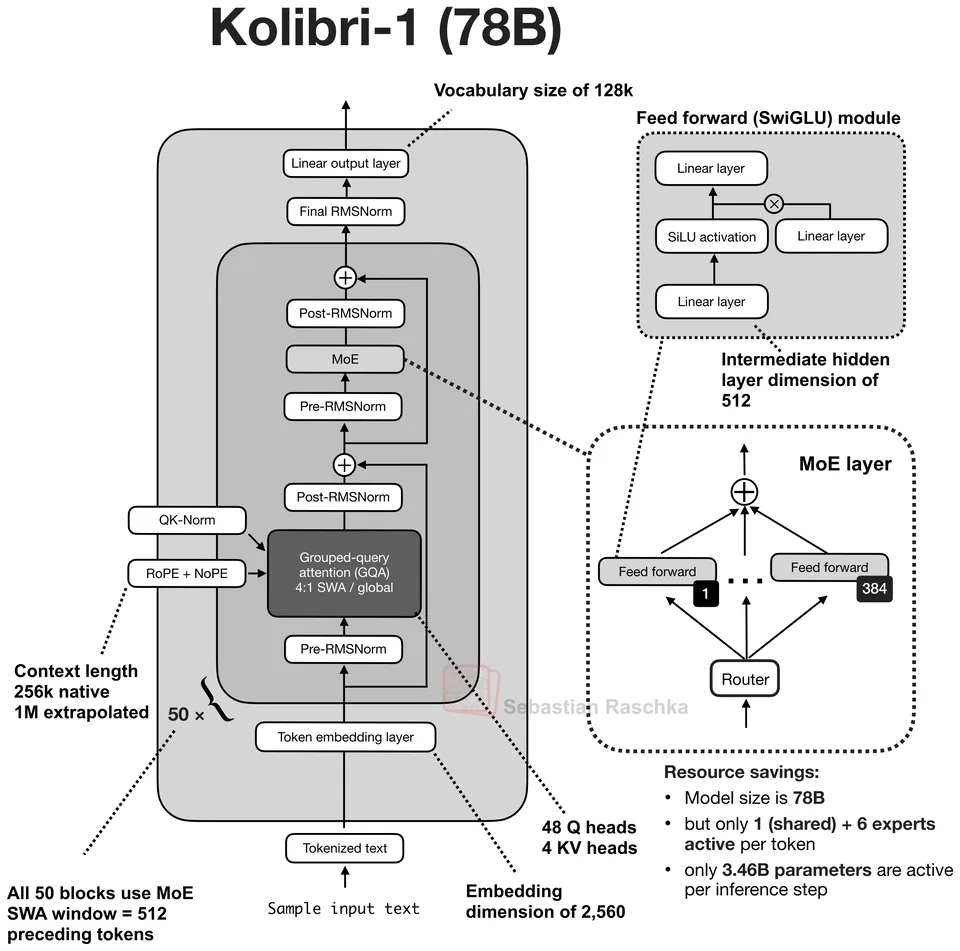
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.
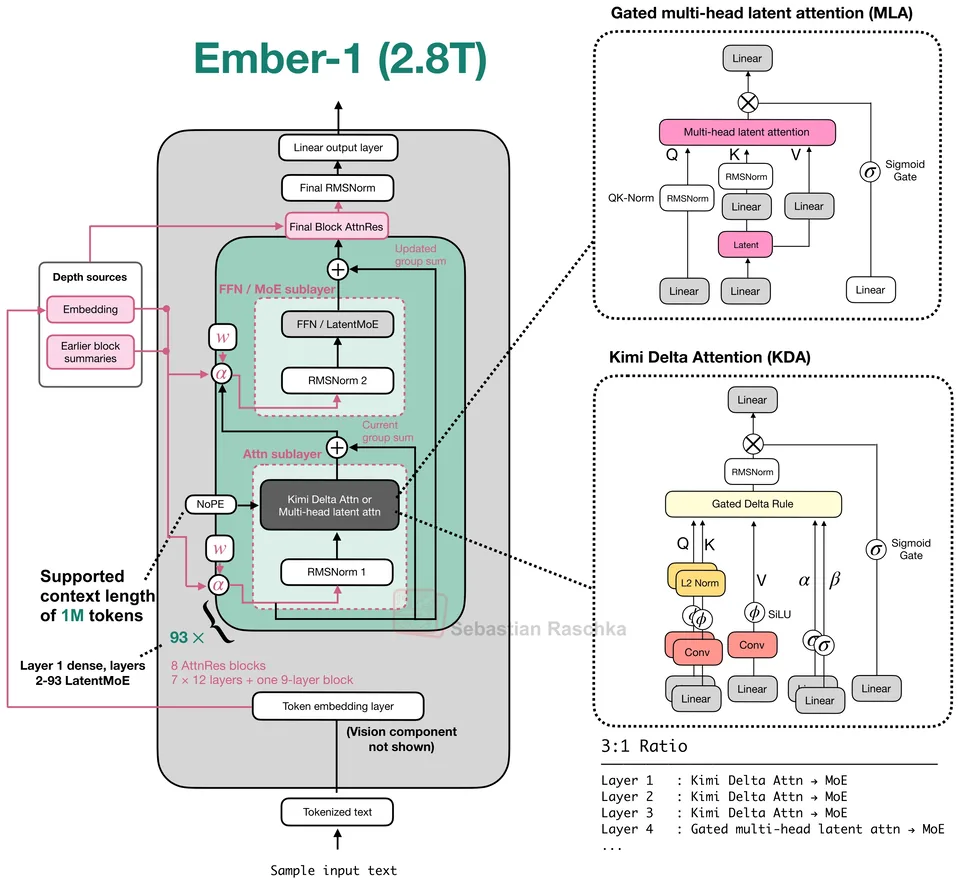
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
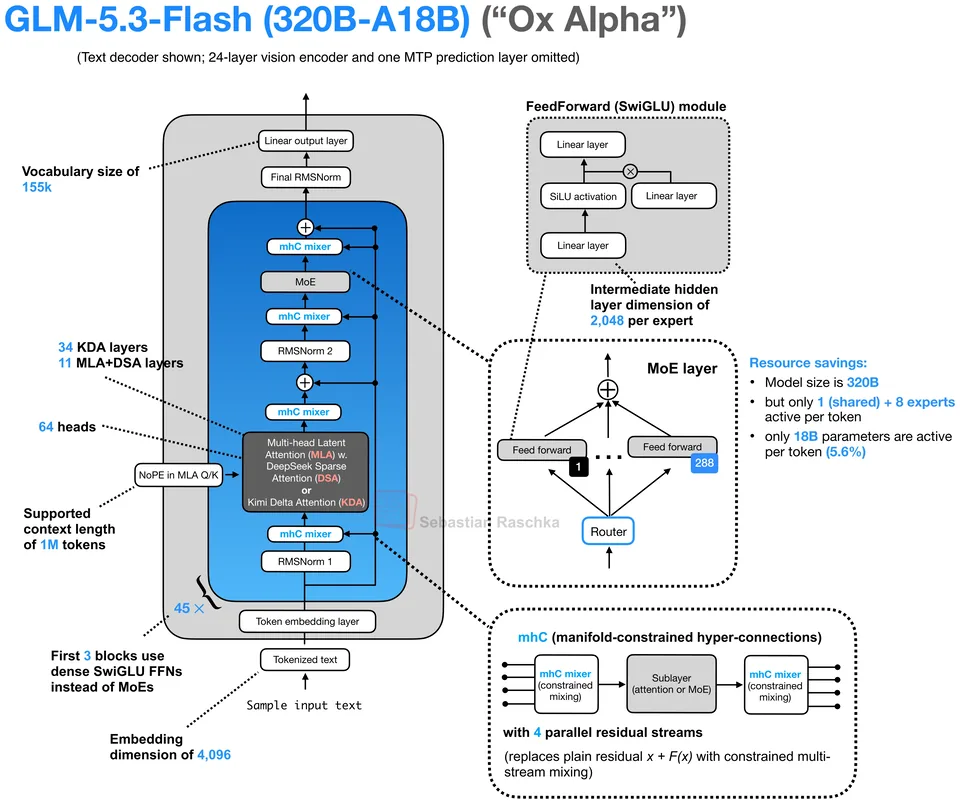
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.

Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
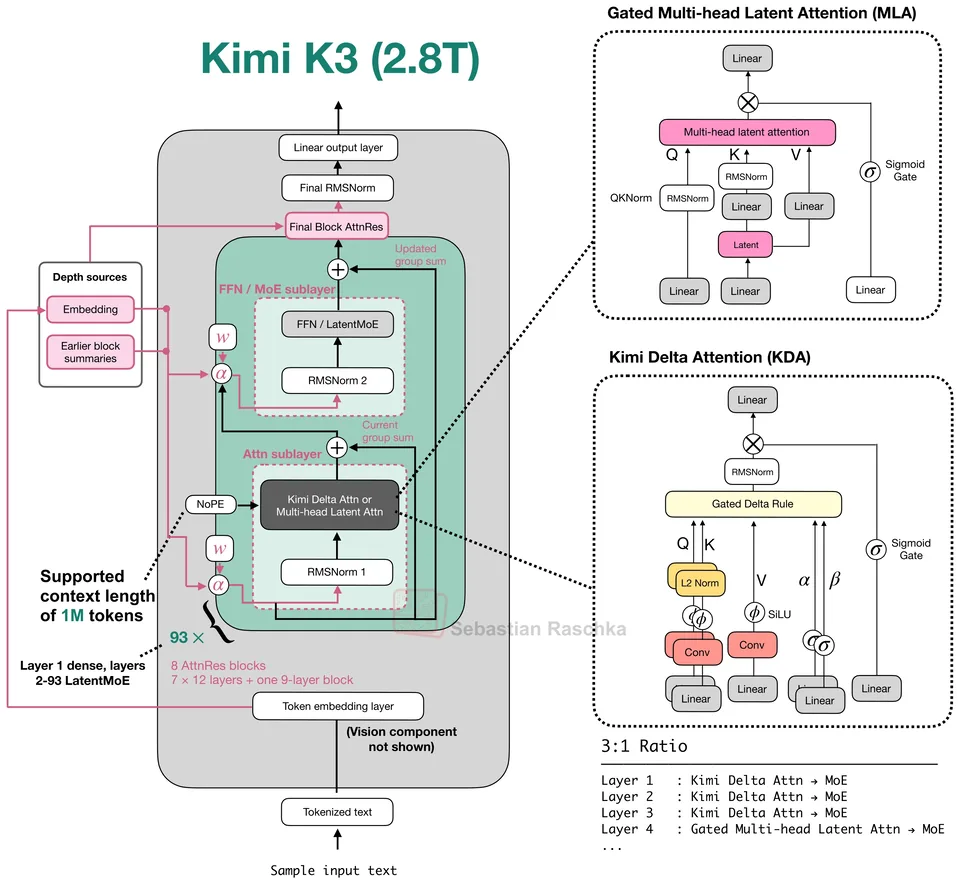
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Upstage, released 2026-07-22. Hybrid MoE decoder, 250B total, 15B active, 1M context. Attention: 3:1 Kimi Delta Attention and gated GQA with NoPE.

SOOFI Consortium, released 2026-07-10. Hybrid MoE decoder, 32B total, 3.2B active, 1M context. Attention: Mostly Mamba-2 with 6 GQA layers and no positional embeddings (NoPE).

Cohere, released 2026-06-05. Sparse MoE decoder, 30B total, 3B active, 256K context. Attention: 8:1 GQA with 3:1 sliding-window/global attention.
Jump to a model, concept or page