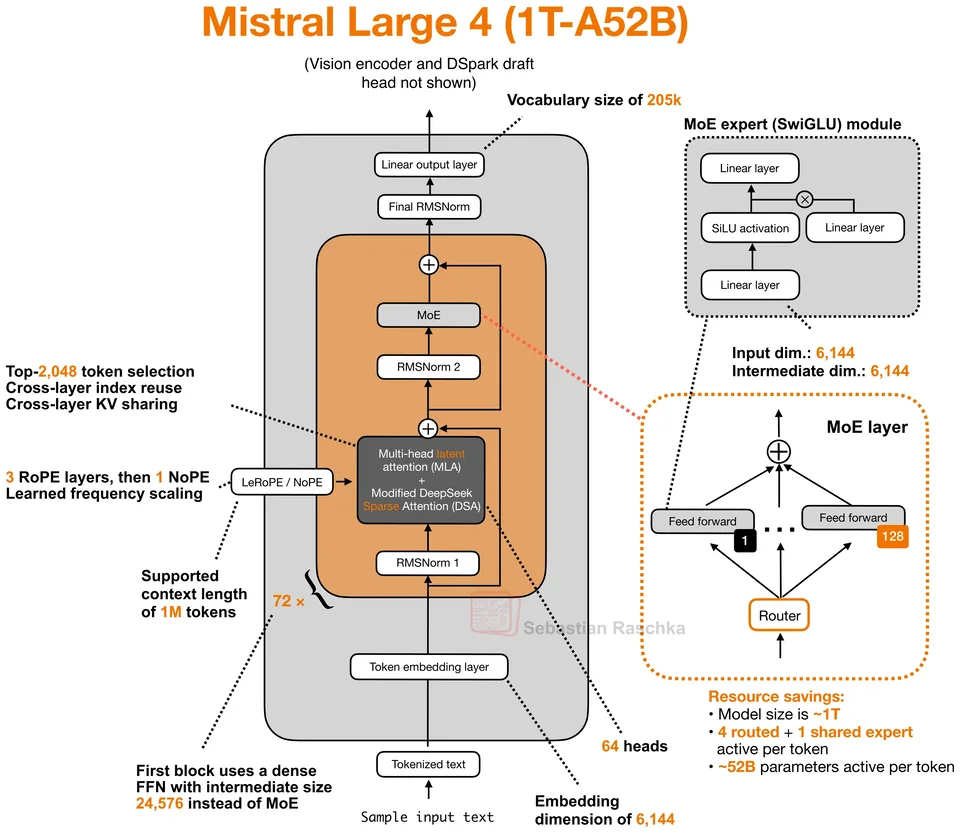
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Efficiency & sharing · KV sharing
Later layers reuse key/value states produced by earlier layers.
GQA shares KV heads across query heads within a layer; cross-layer sharing goes further and lets whole layers reuse another layer's keys and values, so fewer layers add to the cache.
Gemma 4 E2B and E4B are prominent examples of the idea from cross-layer attention research.
Models in the atlas using KV sharing, per half-year of release.
Often paired with
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
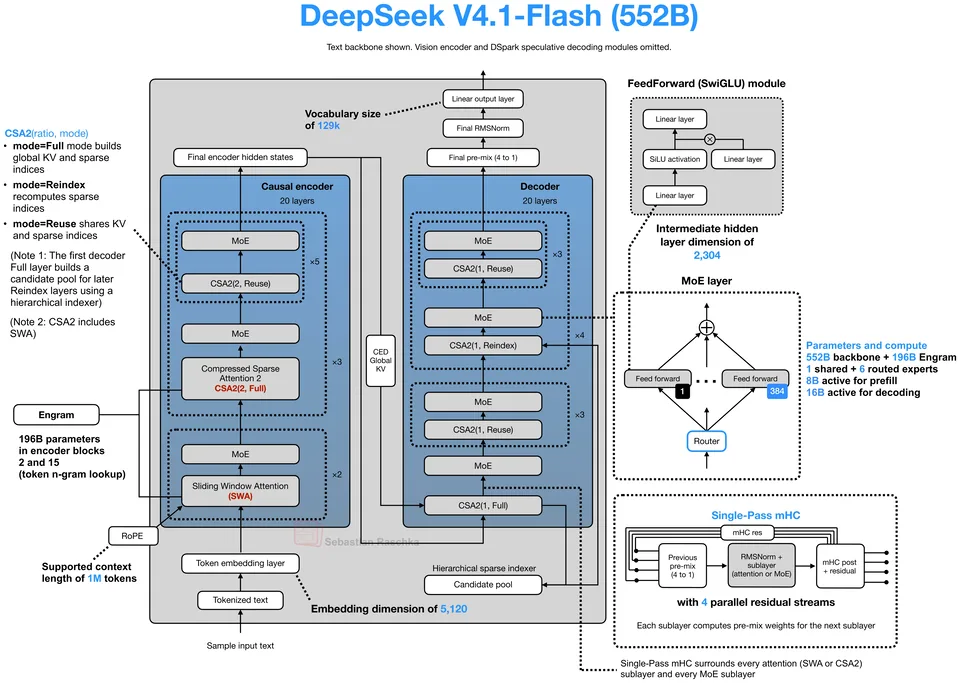
DeepSeek, released 2026-09-10. Sparse MoE decoder, 552B total, 8B active, 1M context. Attention: MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse.

Google, released 2026-04-02. Dense decoder, 5.1B parameters, 128K context. Attention: Multi-query attention with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 4:1 sliding-window/global attention.

Google, released 2026-04-02. Dense decoder, 8B parameters, 128K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.
Jump to a model, concept or page