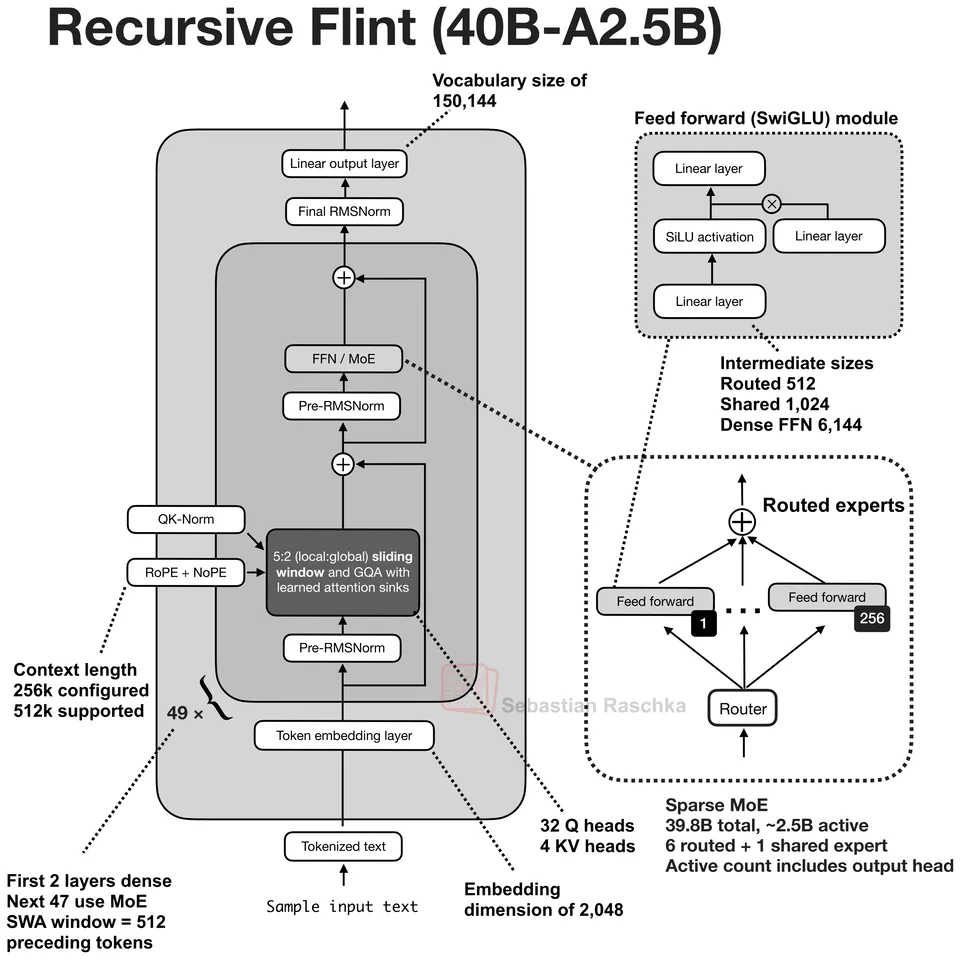
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
Cohere's compact agentic coding MoE adapts the parallel Cohere2-MoE block to a 30B total, 3B active model.
Key detail
Runs attention and MoE in parallel, with RoPE in sliding-window layers, NoPE in global layers, and top-8 routing over 128 experts.Total params
30B
Active / token
3B
Context
256K
Parameters active per token
10%
3B of 30B weights run for each token.
9.9
Use the ← and → keys to step through releases.
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.
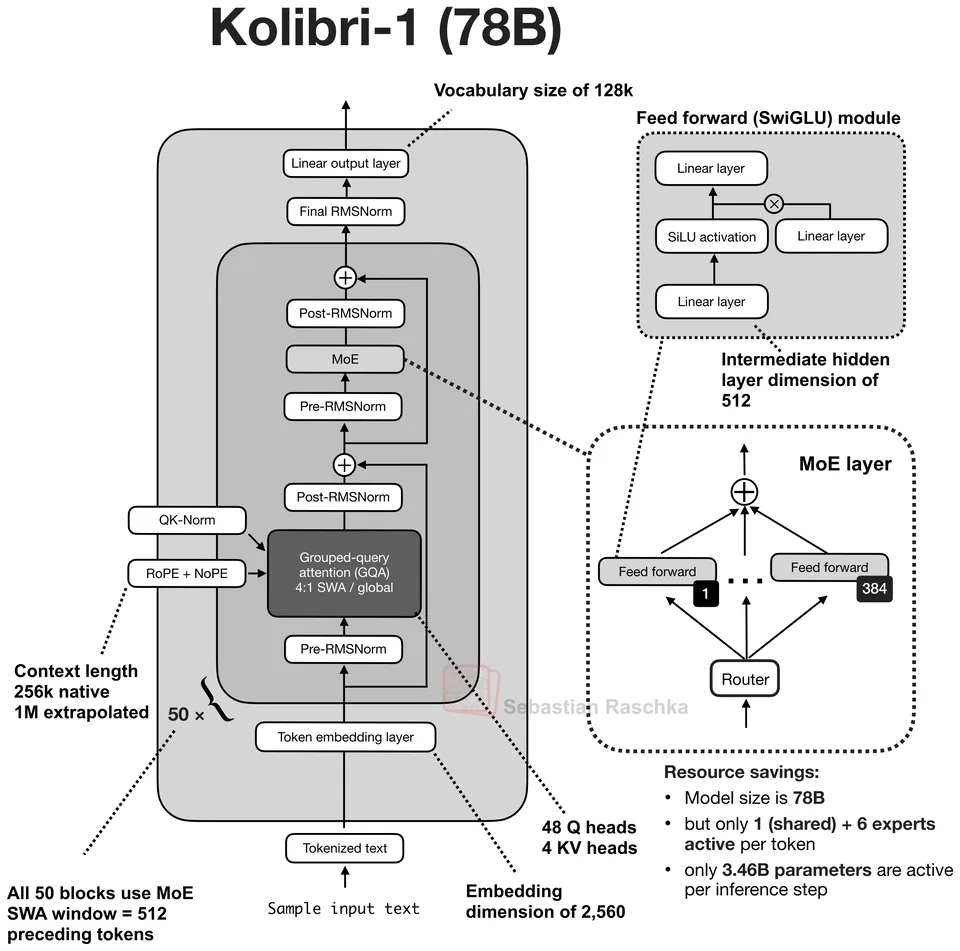
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.

Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.
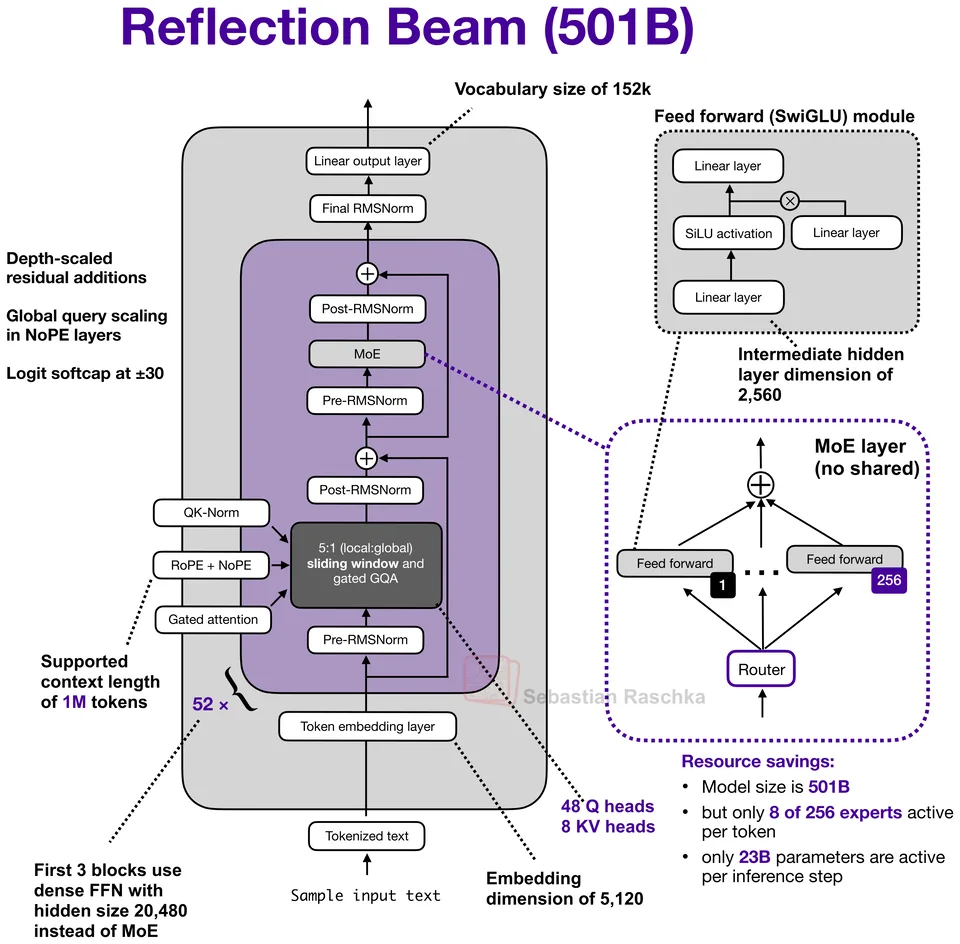
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
Jump to a model, concept or page