
Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.
Meta's dense 29.6B multimodal model combines a 52-layer sandwich-norm decoder with gated GQA and a separate perception encoder; the figure focuses on the text backbone.
Key detail
Applies RoPE only in 2,048-token local layers, uses NoPE in global layers, and gates the attention output before projection.Parameters
30B
Context
128K
KV / token
52 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
6.3
Use the ← and → keys to step through releases.
Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.
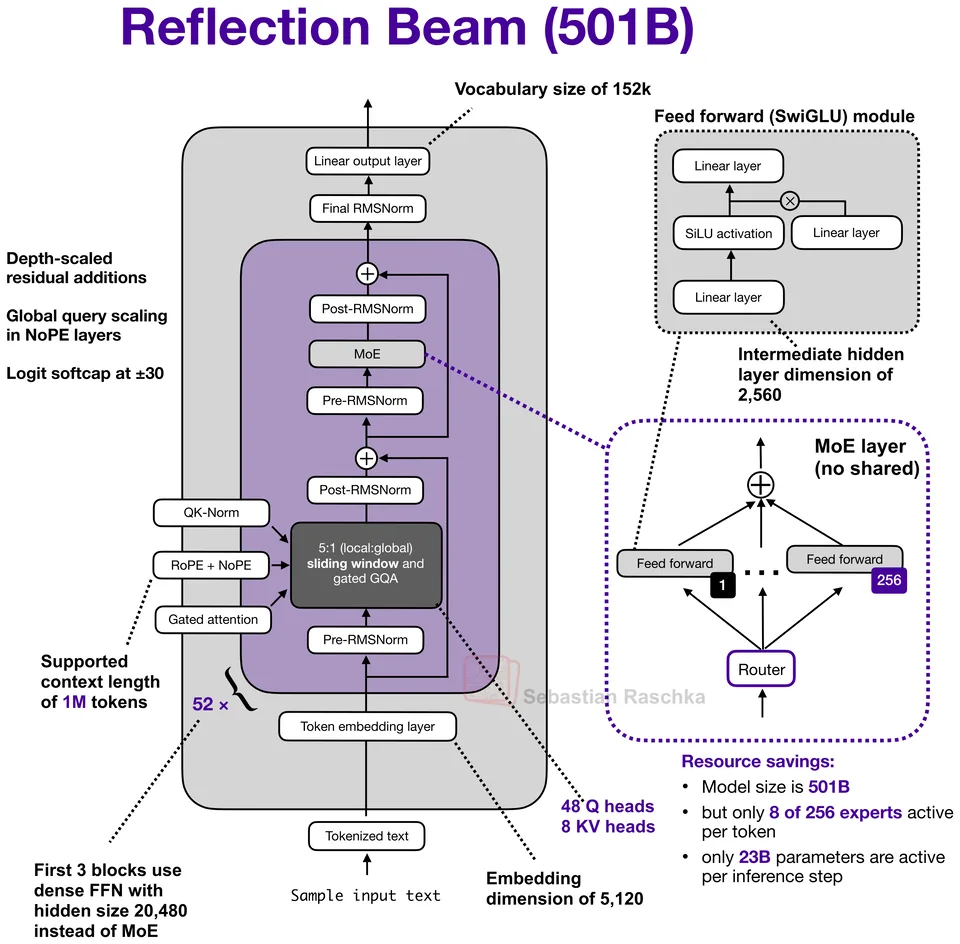
Reflection, released 2026-10-16. Sparse MoE decoder, 501B total, 23B active, 1M context. Attention: Gated GQA with QK-Norm and sliding-window/global attention.
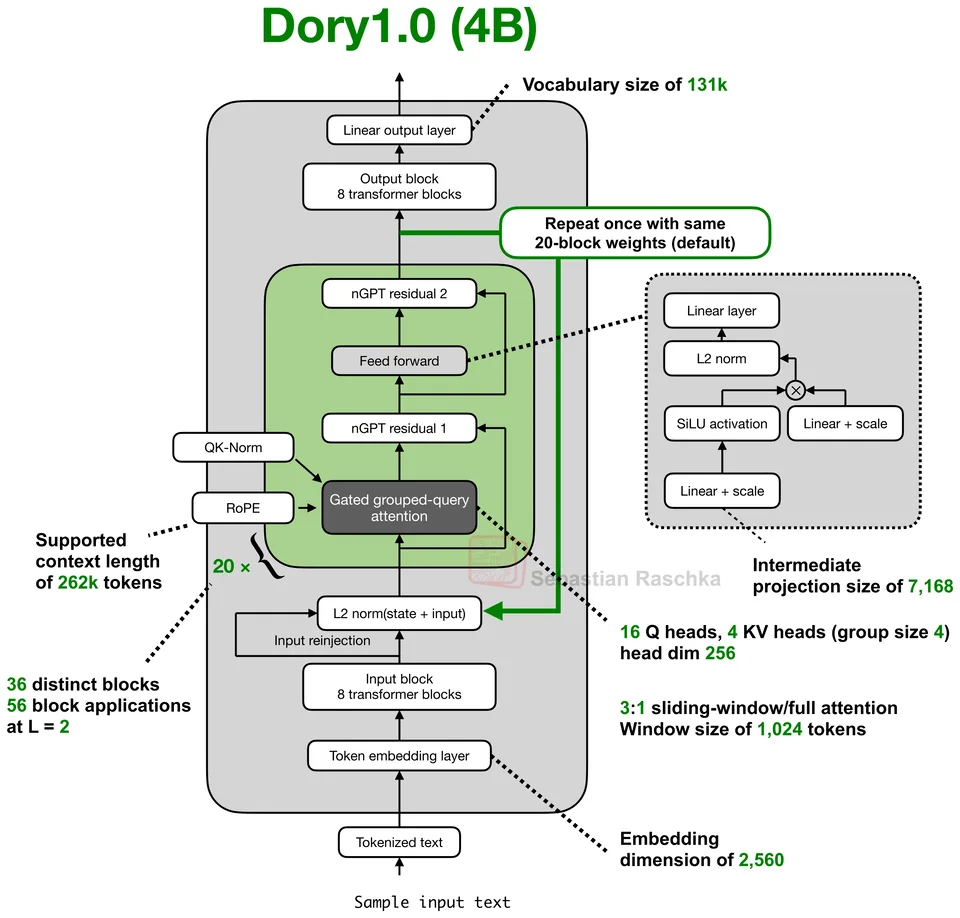
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.
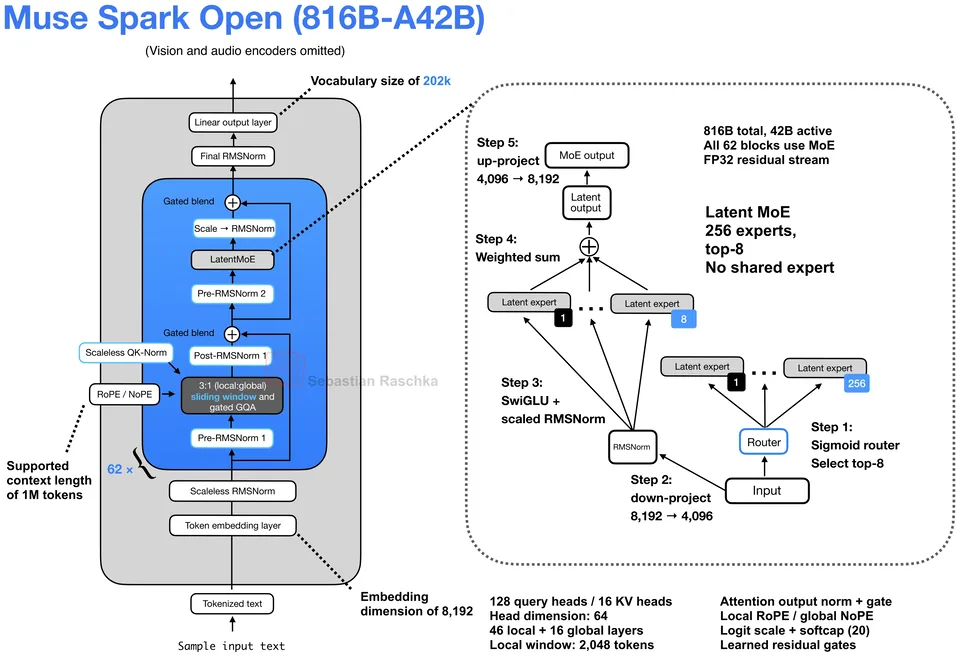
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
Jump to a model, concept or page