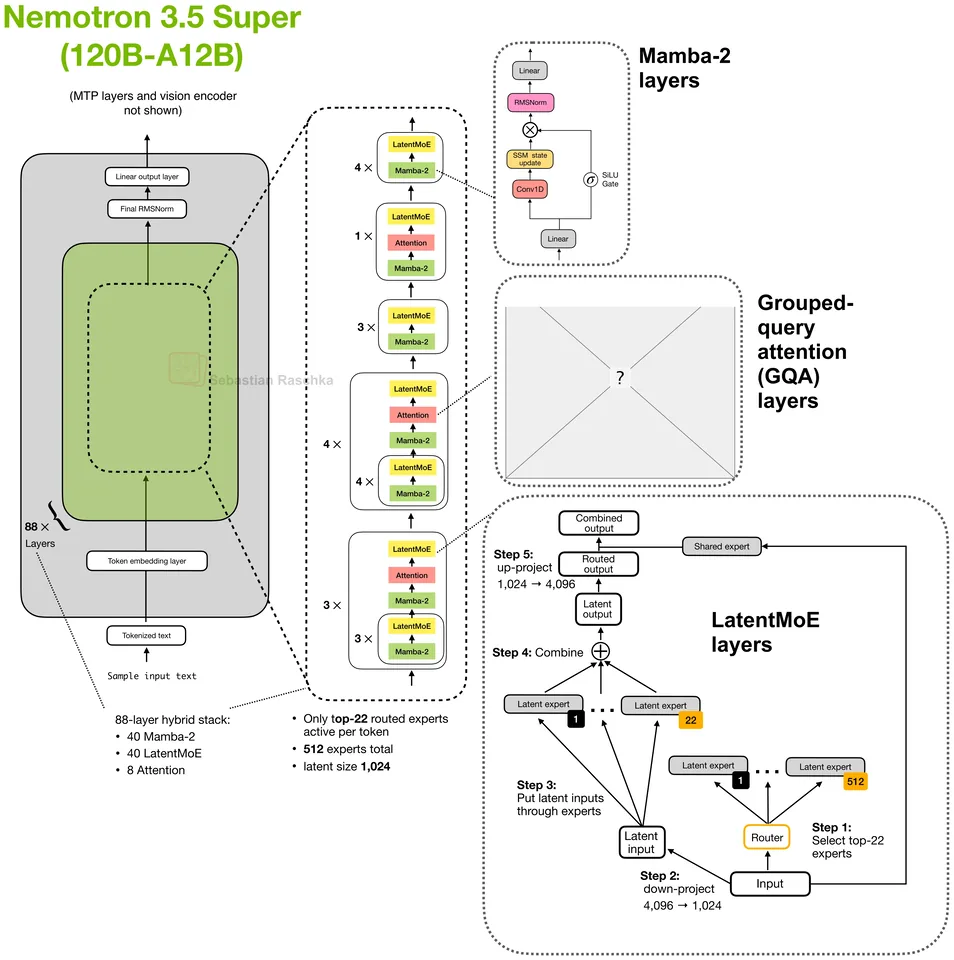
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
Training objectives · MTP
Extra heads learn to predict several future tokens, and can draft tokens at inference.
Besides the next token, small additional modules predict tokens further ahead. DeepSeek's version keeps a causal chain where each module conditions on the previous prediction.
The extra targets give a denser training signal, and at inference the MTP modules act as a built-in draft model for speculative decoding.
Models in the atlas using MTP, per half-year of release.
Often paired with
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
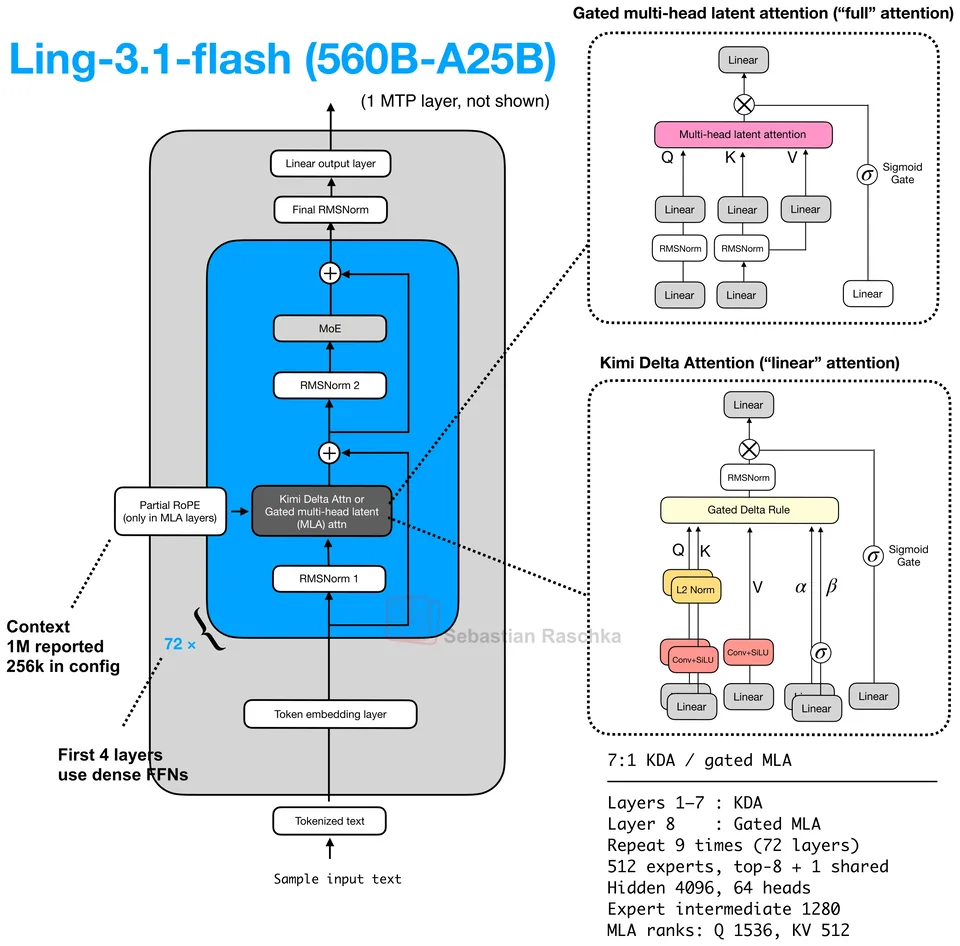
InclusionAI, released 2026-10-13. Hybrid MoE decoder, 560B total, 25B active, 1M context. Attention: 7:1 Kimi Delta Attention and gated MLA.
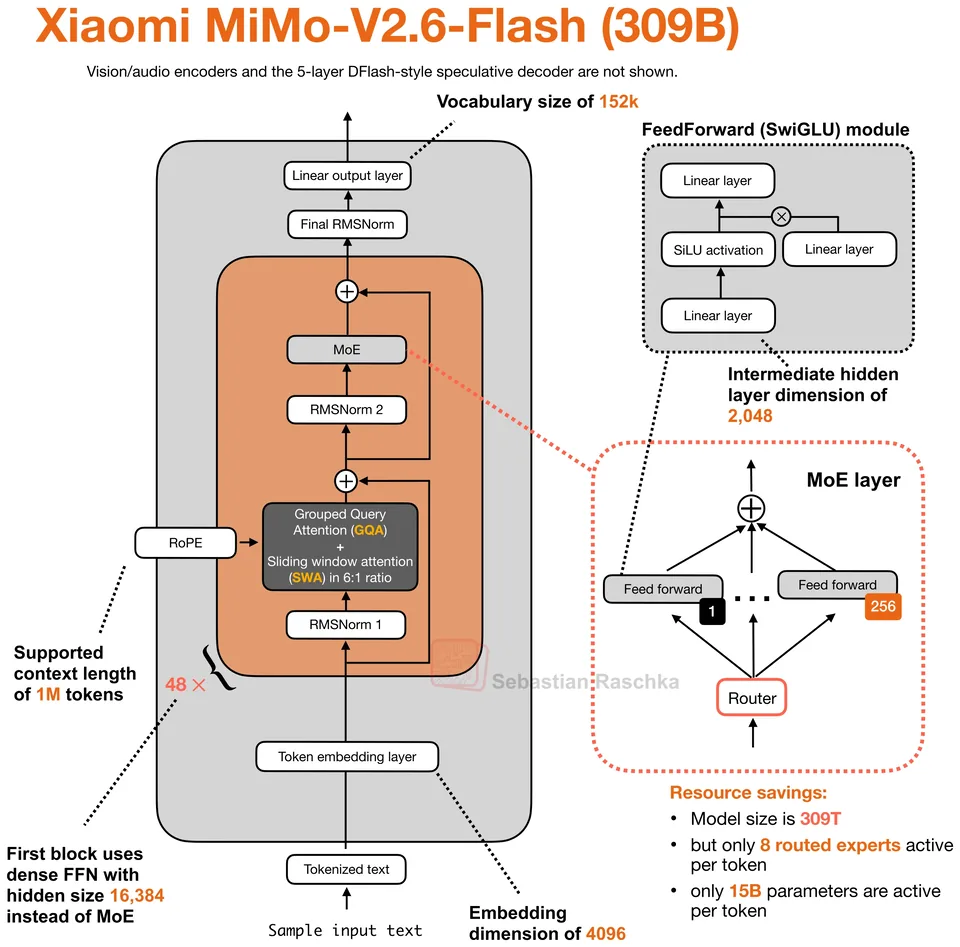
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
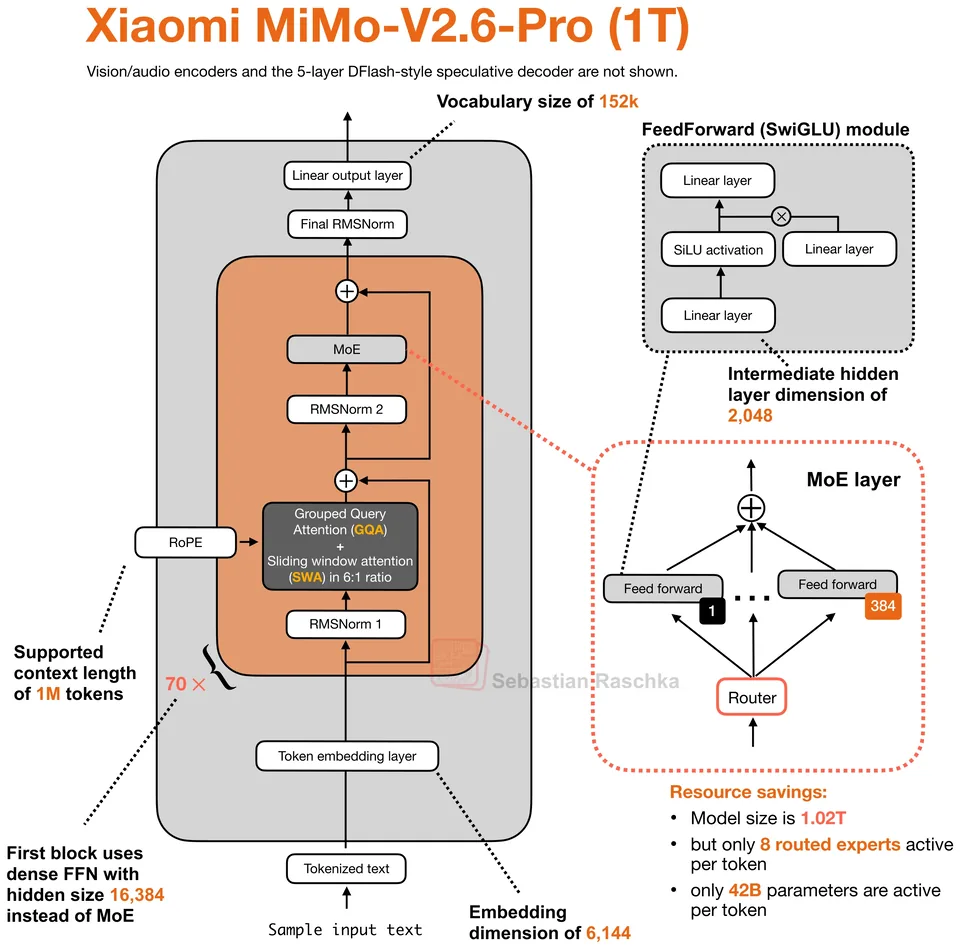
Xiaomi, released 2026-09-21. Sparse MoE decoder, 1.02T total, 42B active, 1M context. Attention: GQA with 6:1 sliding-window/global attention.
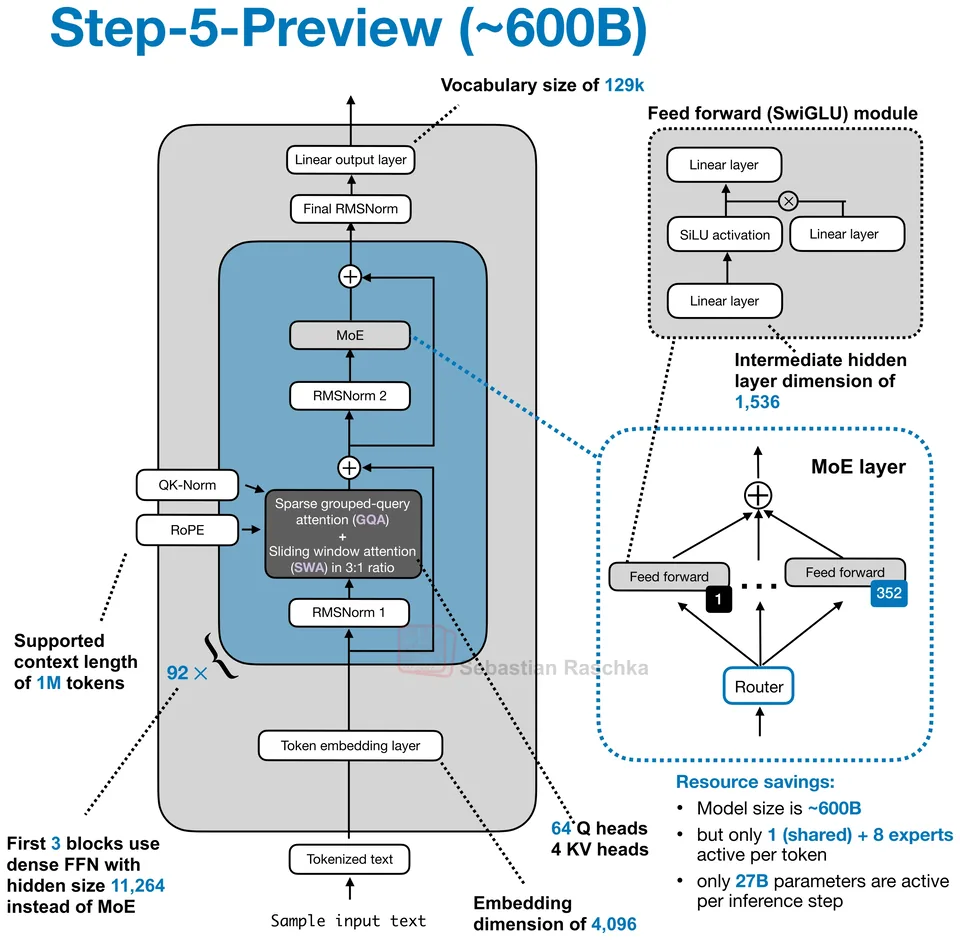
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
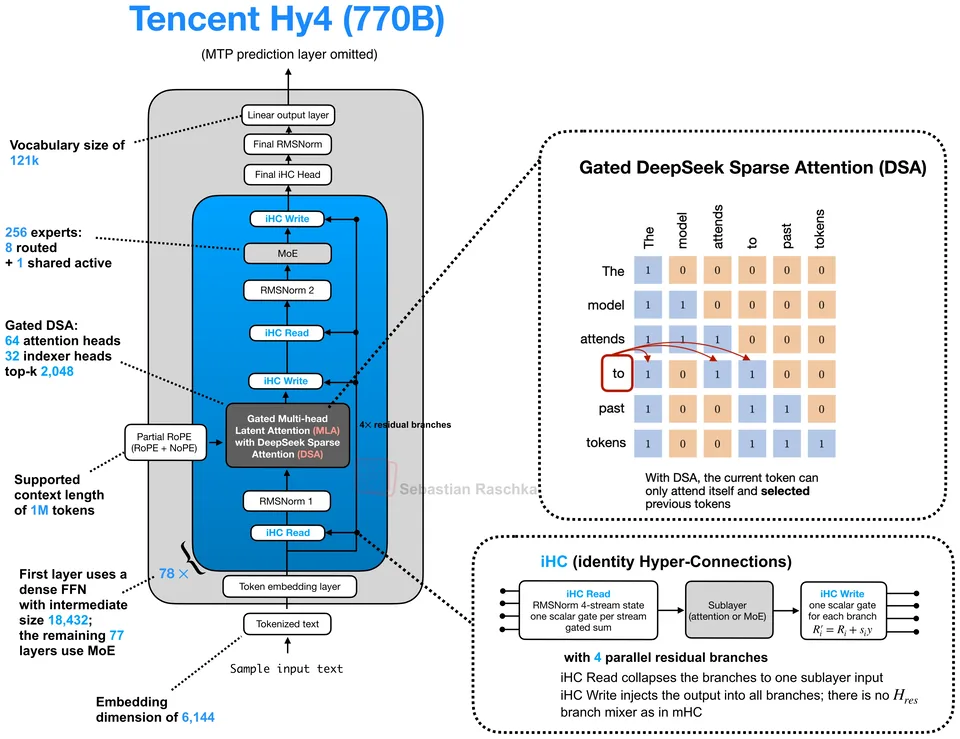
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
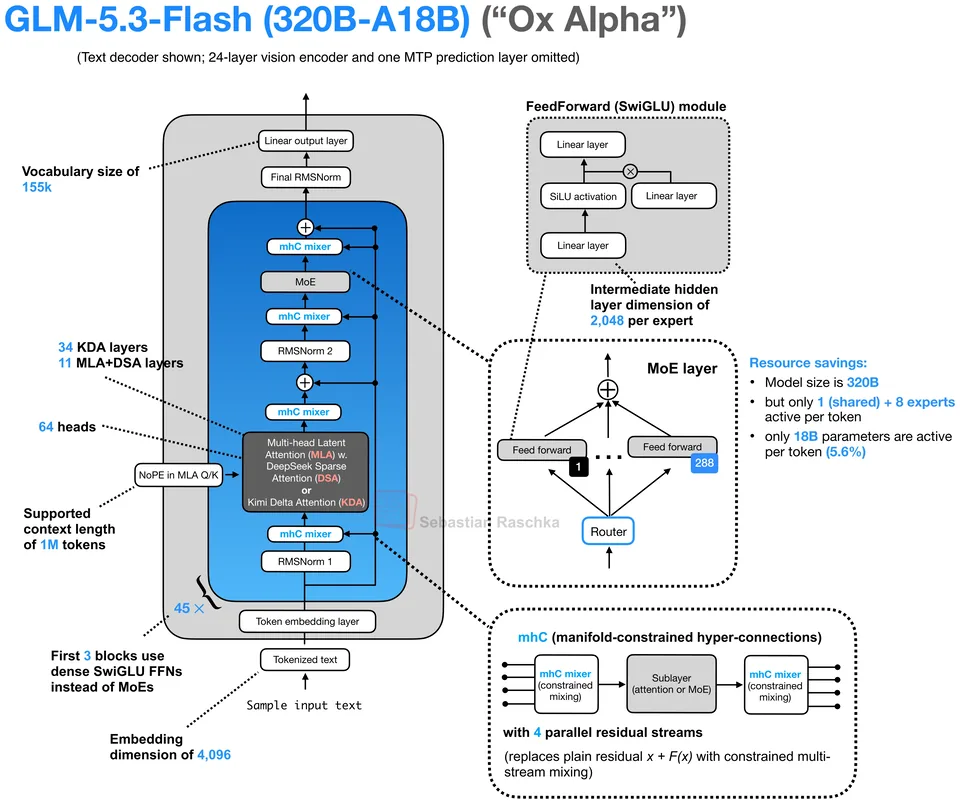
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
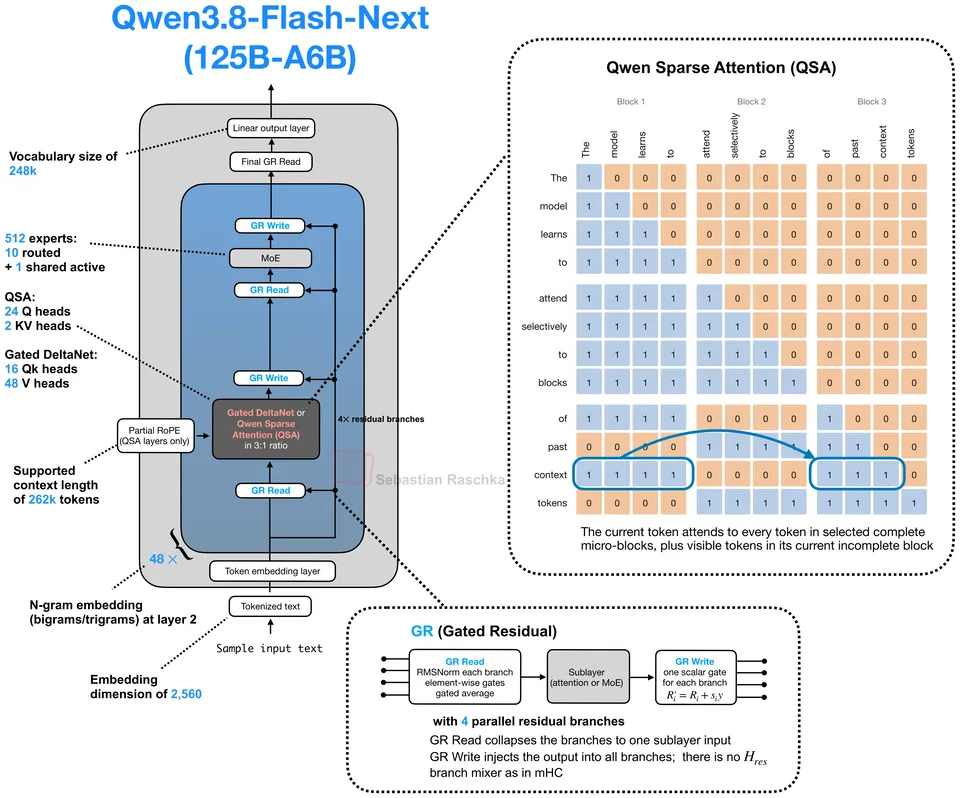
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
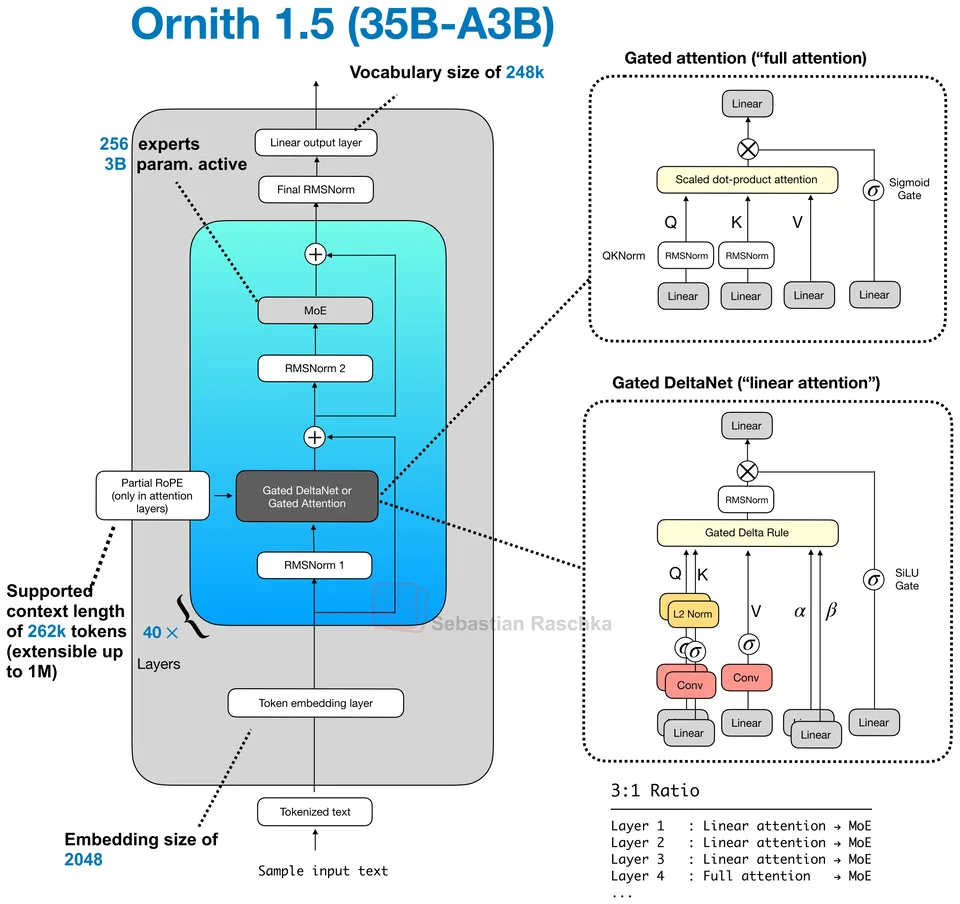
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
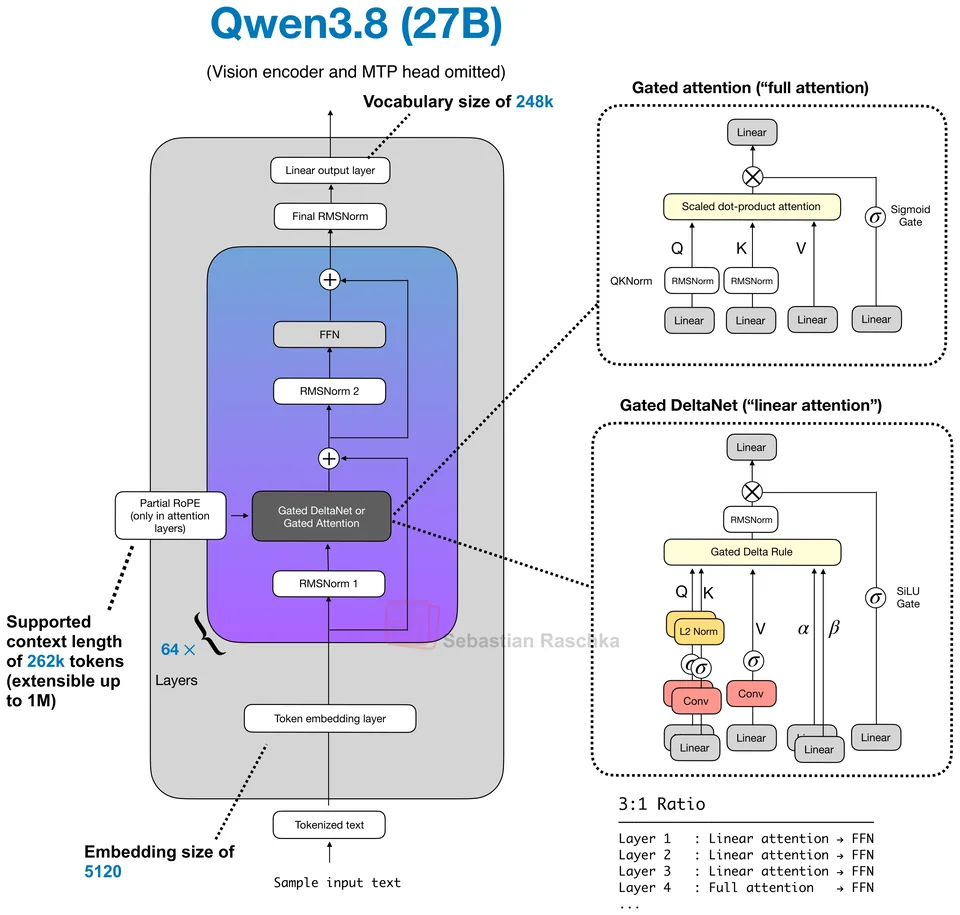
Alibaba Cloud, released 2026-08-14. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

NVIDIA, released 2026-08-11. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with six GQA layers.
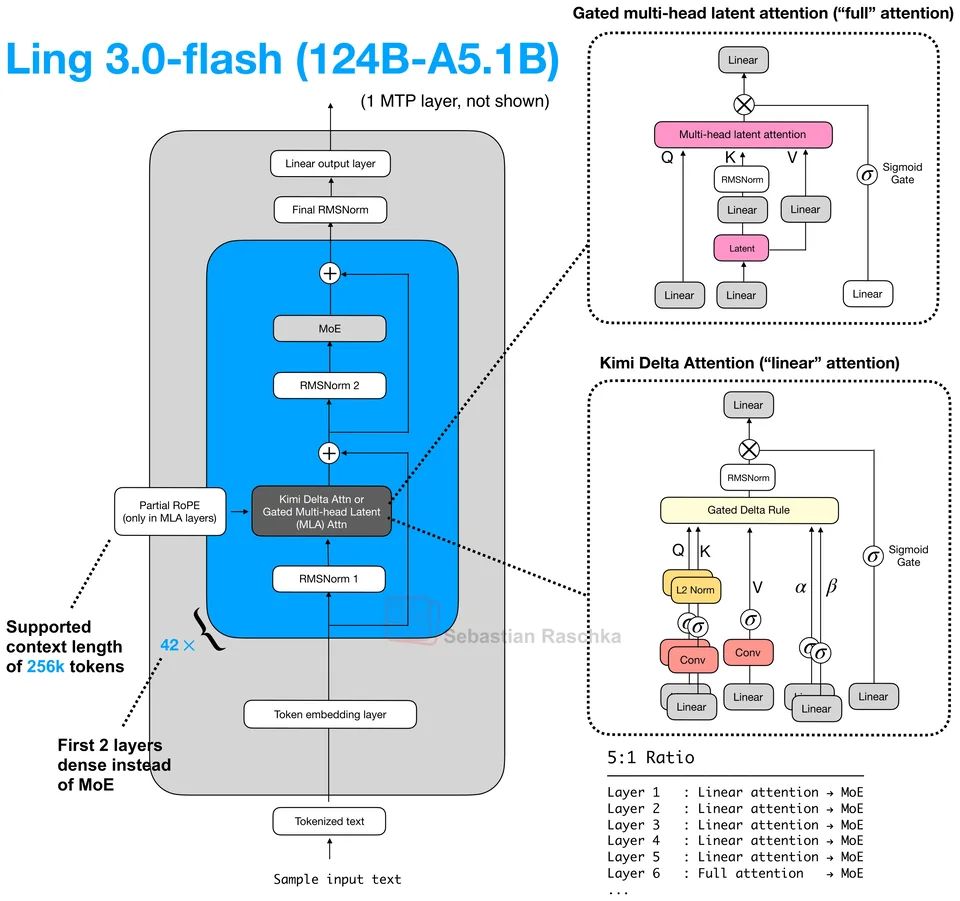
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
Jump to a model, concept or page