
Ai2, released 2025-11-20. Dense decoder, 7B parameters, 64K context. Attention: MHA with QK-Norm and 3:1 sliding-window/global attention.
Attention · MHA
The original transformer attention: every head has its own queries, keys and values.
Self-attention lets every token build its representation from a weighted mix of all earlier tokens. The weights come from comparing a token's query with every key; the values are what gets mixed.
Multi-head attention runs several of these attention operations side by side, each in a smaller subspace, so different heads can track different relationships (syntax, coreference, position) at once. Their outputs are concatenated and projected back.
In a decoder, a causal mask hides future tokens. Because every head stores its own keys and values, MHA has the largest KV cache of the common variants.
Models in the atlas using MHA, per half-year of release.
Often paired with
Ai2, released 2025-11-20. Dense decoder, 7B parameters, 64K context. Attention: MHA with QK-Norm and 3:1 sliding-window/global attention.
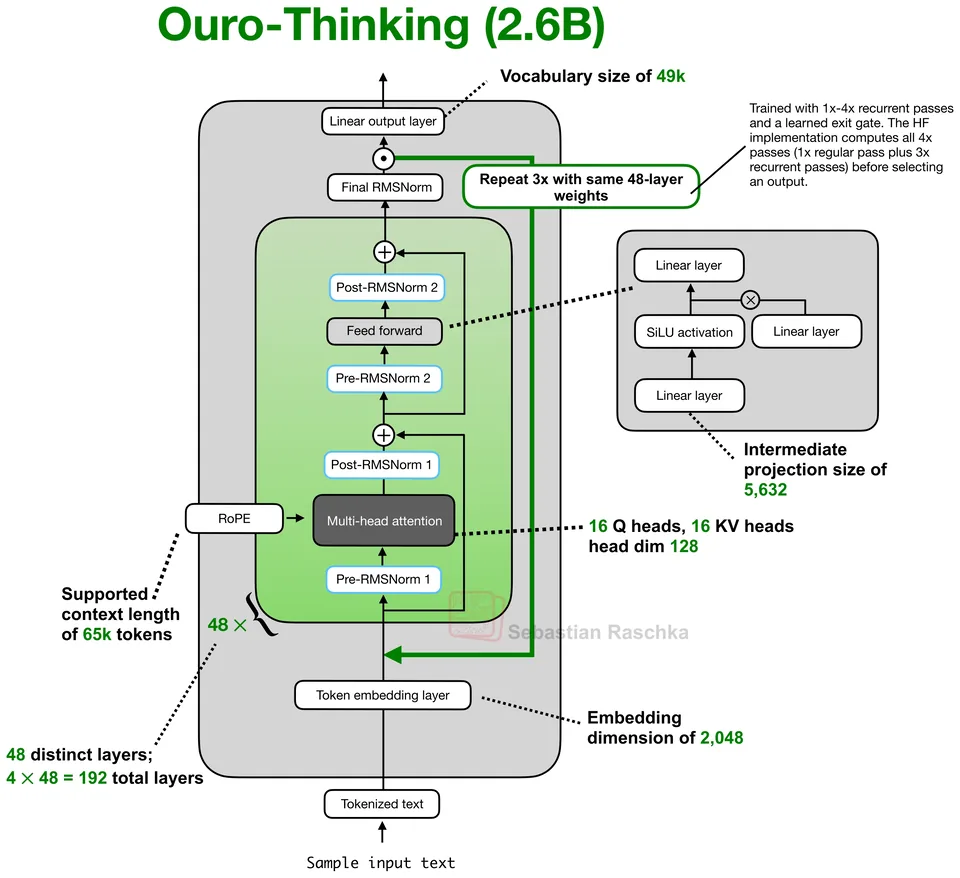
ByteDance, released 2025-10-29. Dense decoder, 2.6B parameters, 64K context. Attention: MHA with RoPE.

Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.

OpenAI, released 2019-11-05. Dense decoder, 1.5B parameters, 1K context. Attention: MHA with learned absolute positional embeddings.
Jump to a model, concept or page