
BOSS Zhipin, released 2026-07-21. Dense decoder, 4B parameters, 256K context. Attention: GQA with RoPE.
ByteDance's dense LoopLM reuses one 48-layer MHA stack across four recurrent passes and trains an exit gate over the intermediate representations.
Key detail
Reuses the same 48-layer MHA stack across four passes, yielding 192 block applications, with sandwich RMSNorm and a learned exit gate.Parameters
2.6B
Context
64K
KV / token
1.5 MiB
Parameters active per token
100%
Dense: every weight runs for every token.
Use the ← and → keys to step through releases.
BOSS Zhipin, released 2026-07-21. Dense decoder, 4B parameters, 256K context. Attention: GQA with RoPE.
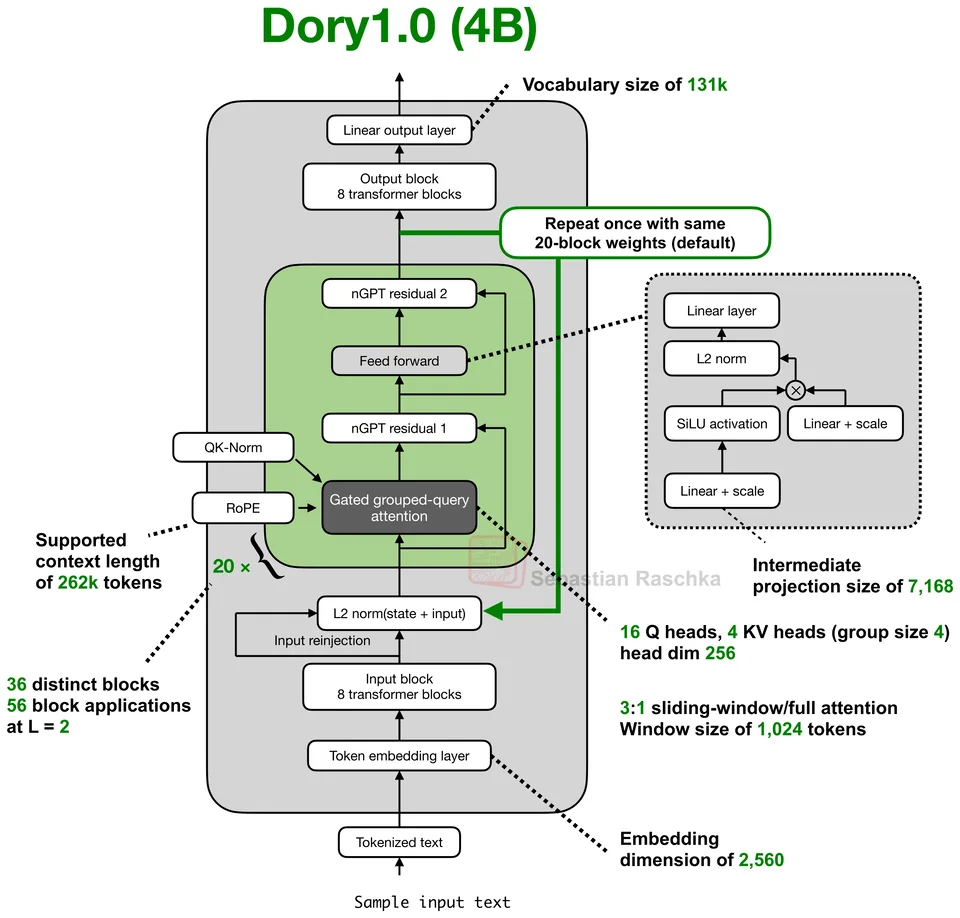
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.

OpenAI, released 2019-11-05. Dense decoder, 1.5B parameters, 1K context. Attention: MHA with learned absolute positional embeddings.

Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.
Jump to a model, concept or page