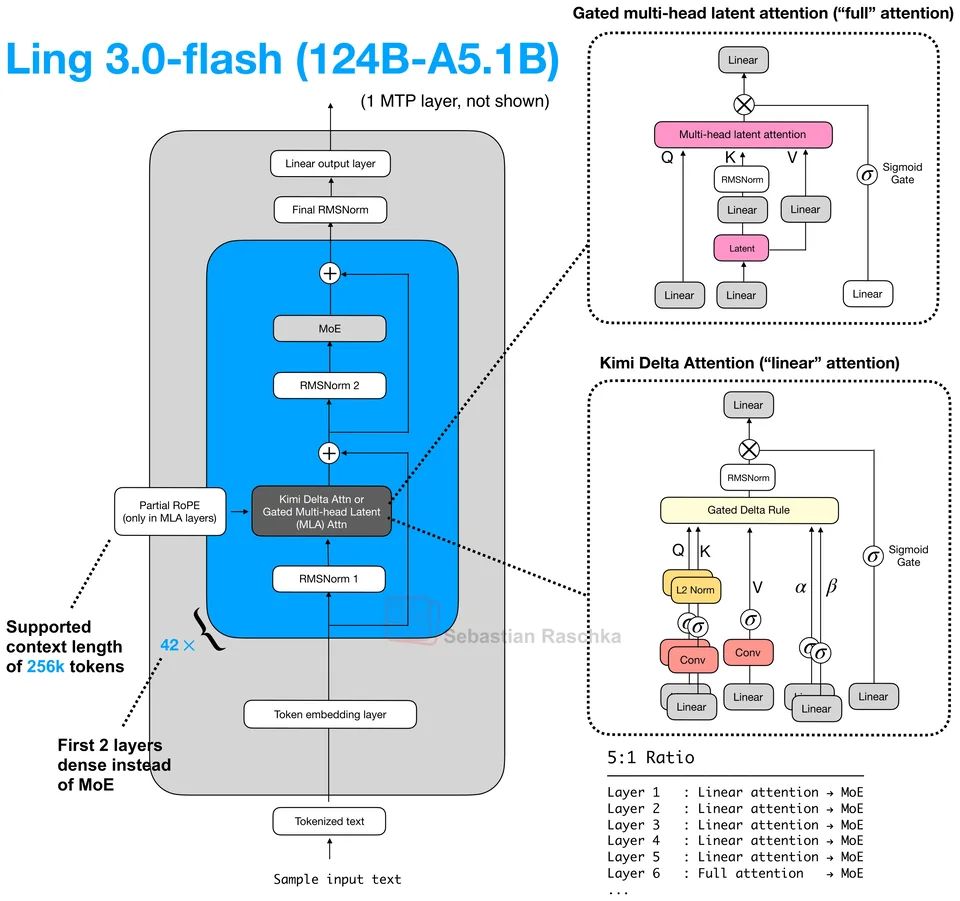
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
Hybrid MoE that extends Ling 3.0 Flash to 72 layers, with seven Kimi Delta Attention layers for every gated MLA layer.
Key detail
Uses four initial dense FFN layers, top-8 routing over 512 experts plus one shared expert, and MLA with a 1,536-dimensional query bottleneck and 512-dimensional KV latent.Total params
560B
Active / token
25B
Context
1M
Parameters active per token
4.5%
25B of 560B weights run for each token.
Use the ← and → keys to step through releases.
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
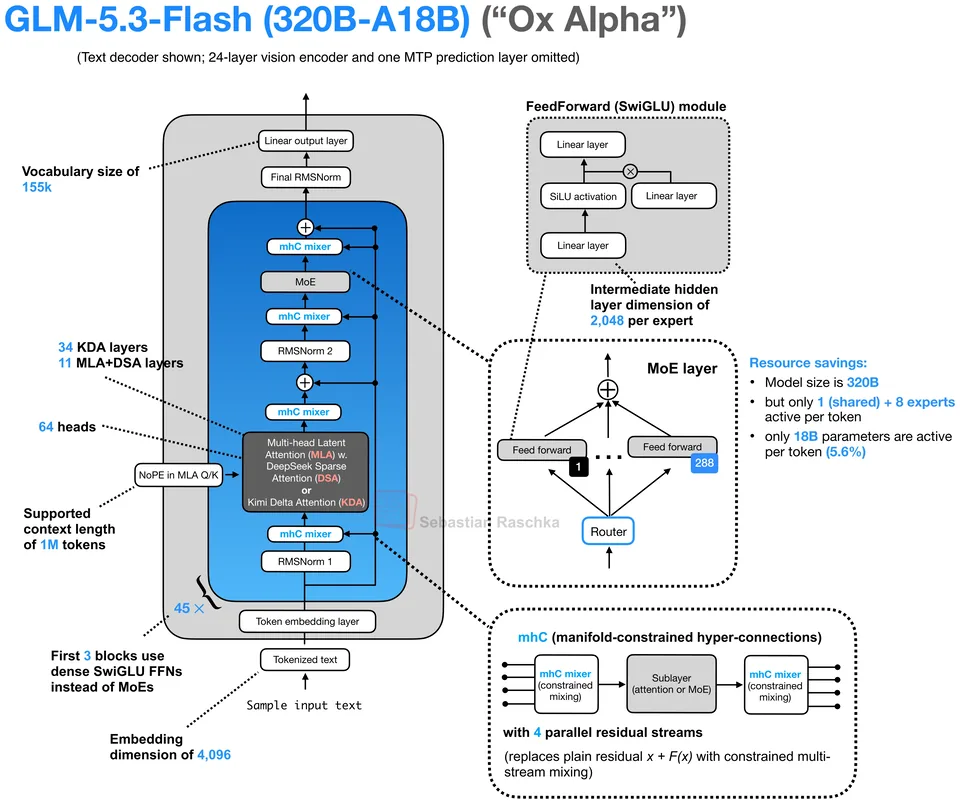
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
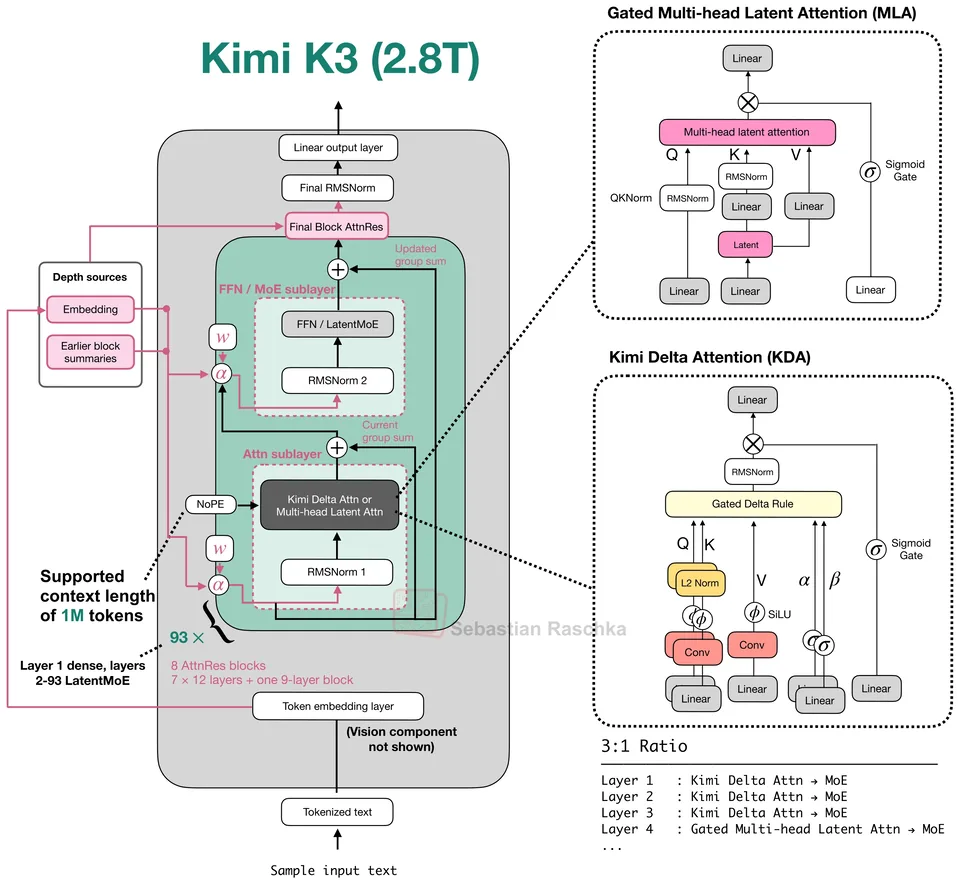
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
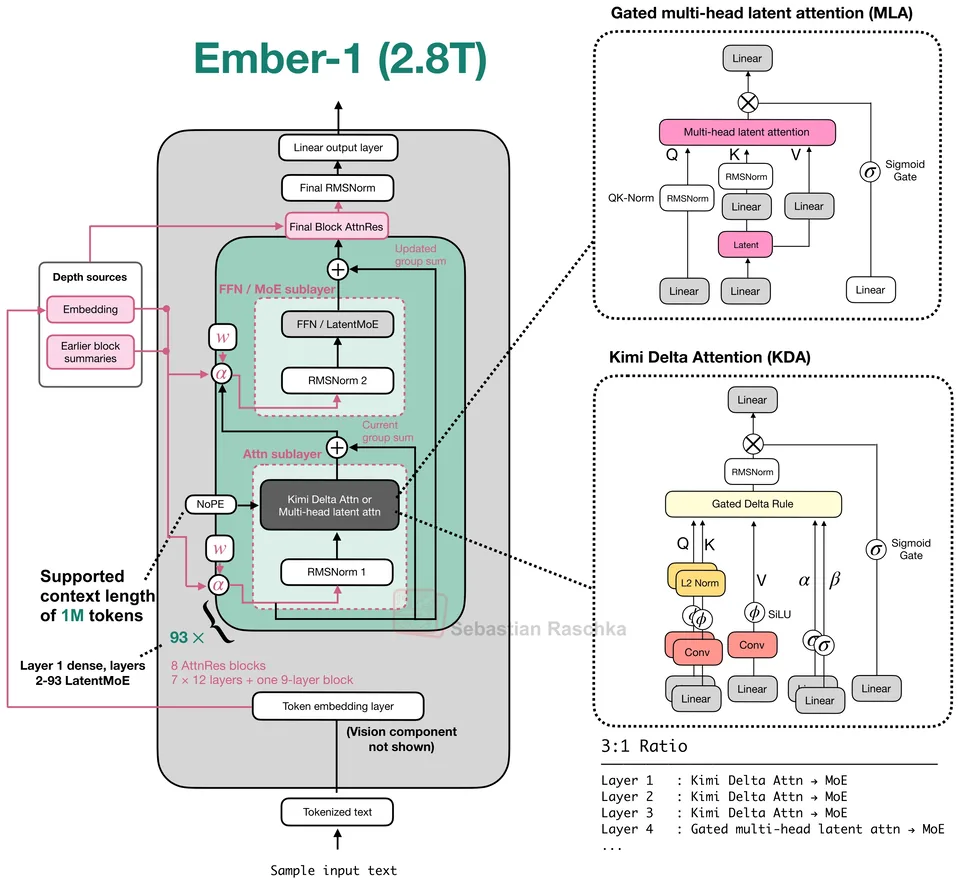
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
Jump to a model, concept or page