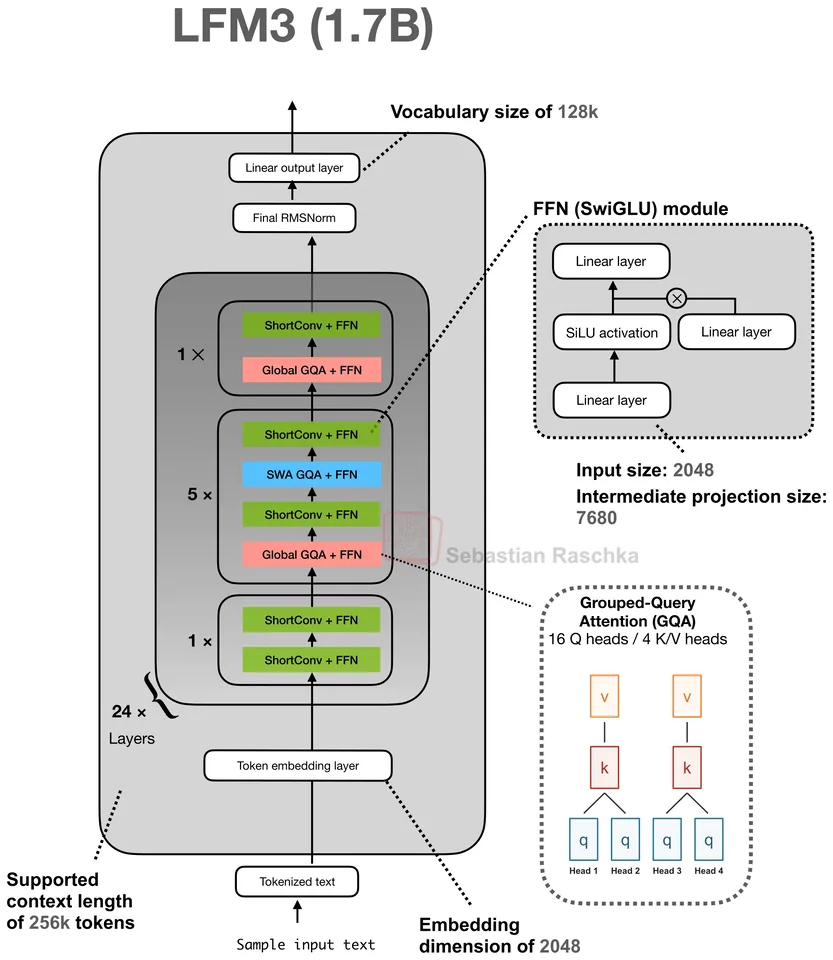
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
Attention · ShortConv
A tiny causal depthwise convolution (kernel ≈ 4) that mixes each channel over the last few tokens.
Each channel is convolved over a handful of recent positions with its own small kernel, and future positions are never seen. It is extremely cheap and gives layers a built-in notion of local order.
Kimi Linear applies ShortConv to the queries, keys and values in its delta-attention layers; Inkling places several ShortConv modules in every block. LFM-style models use convolutions as the main token mixer.
Models in the atlas using ShortConv, per half-year of release.
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.
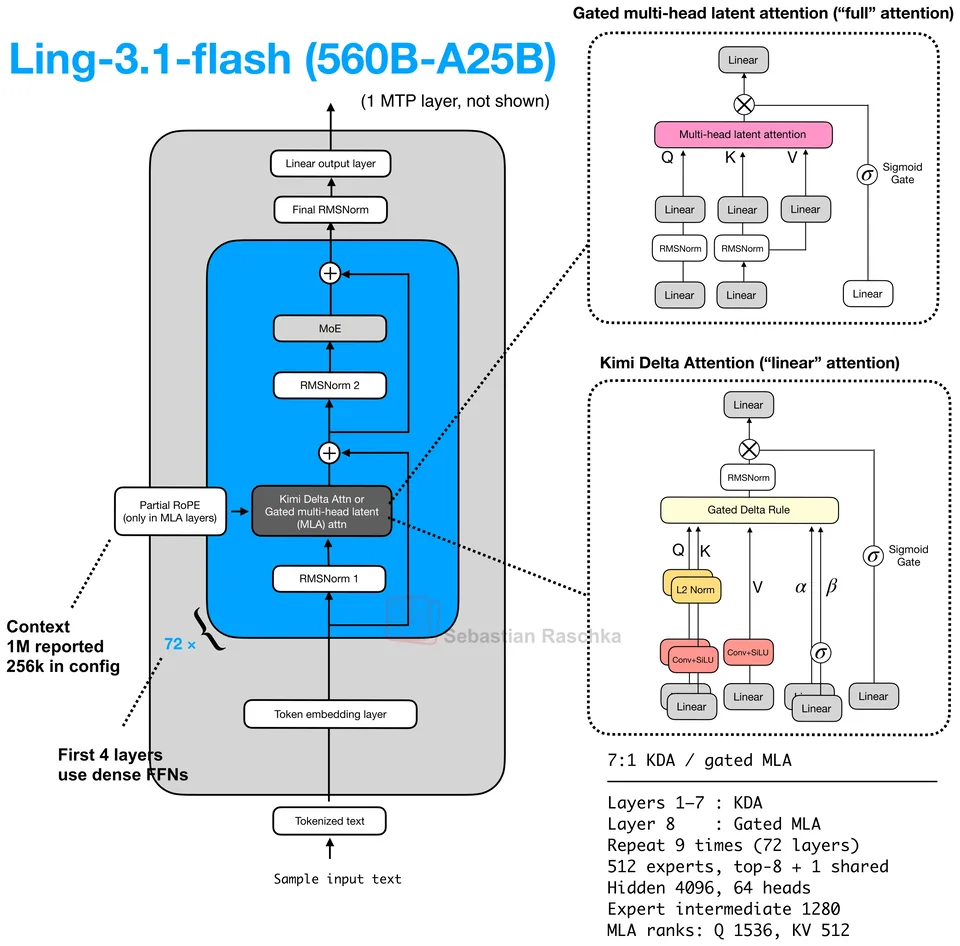
InclusionAI, released 2026-10-13. Hybrid MoE decoder, 560B total, 25B active, 1M context. Attention: 7:1 Kimi Delta Attention and gated MLA.
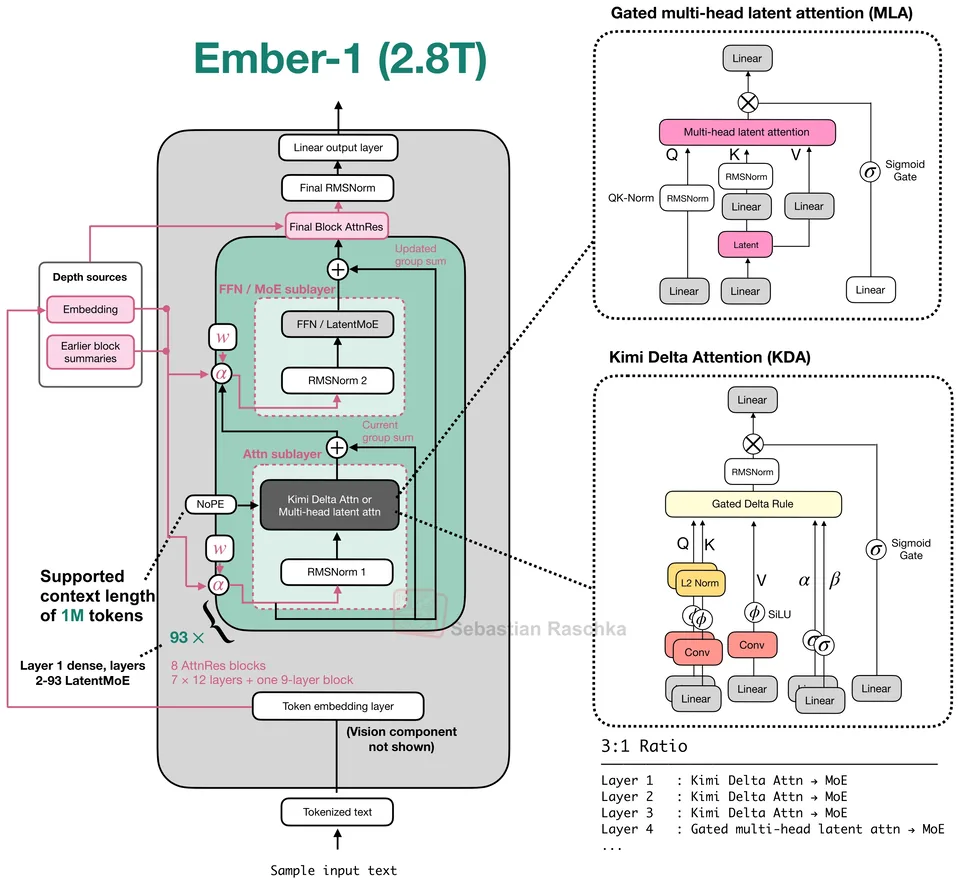
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
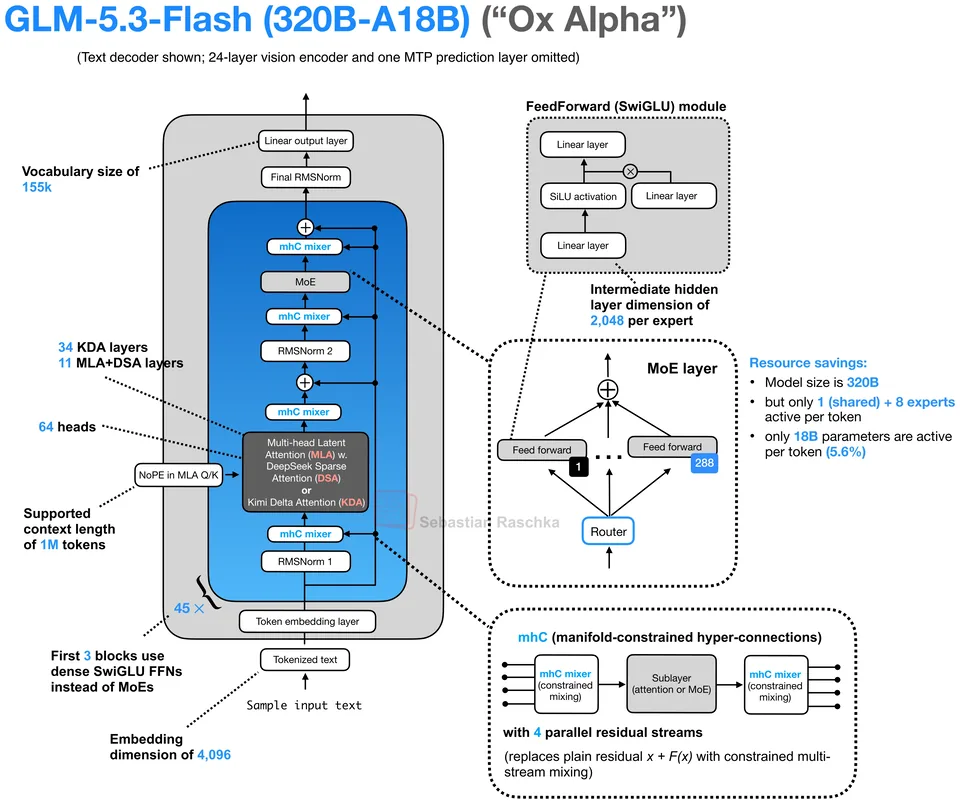
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
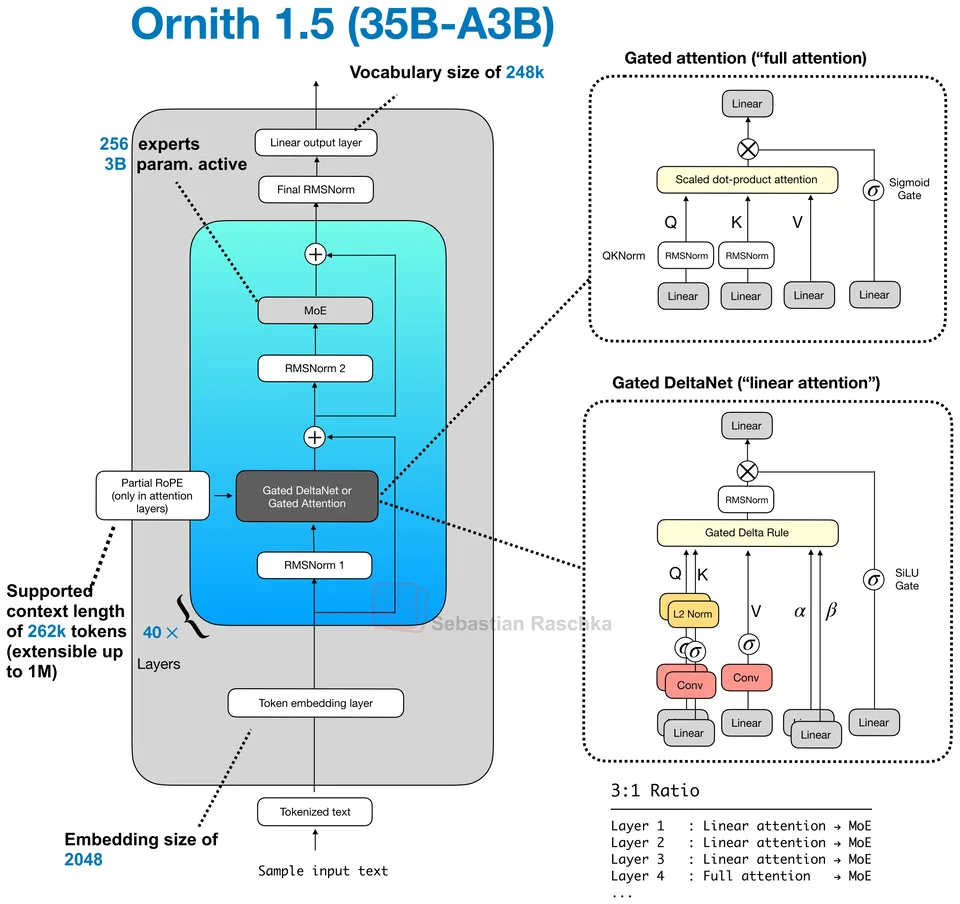
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
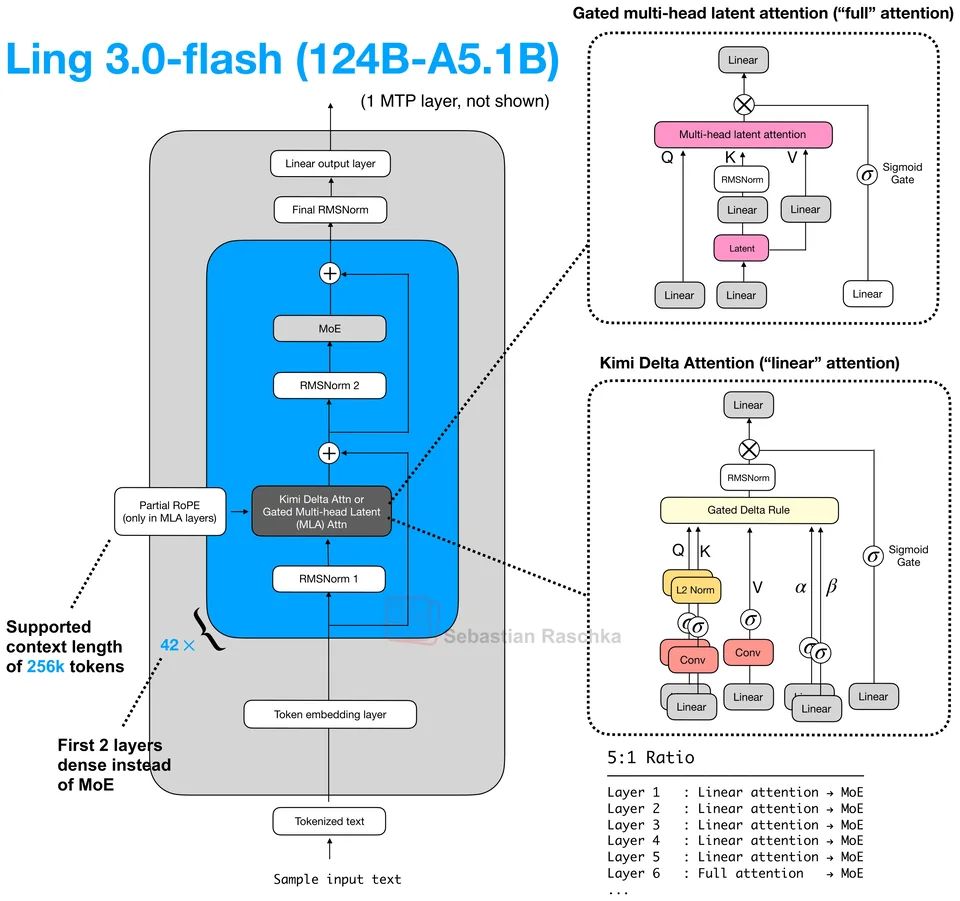
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
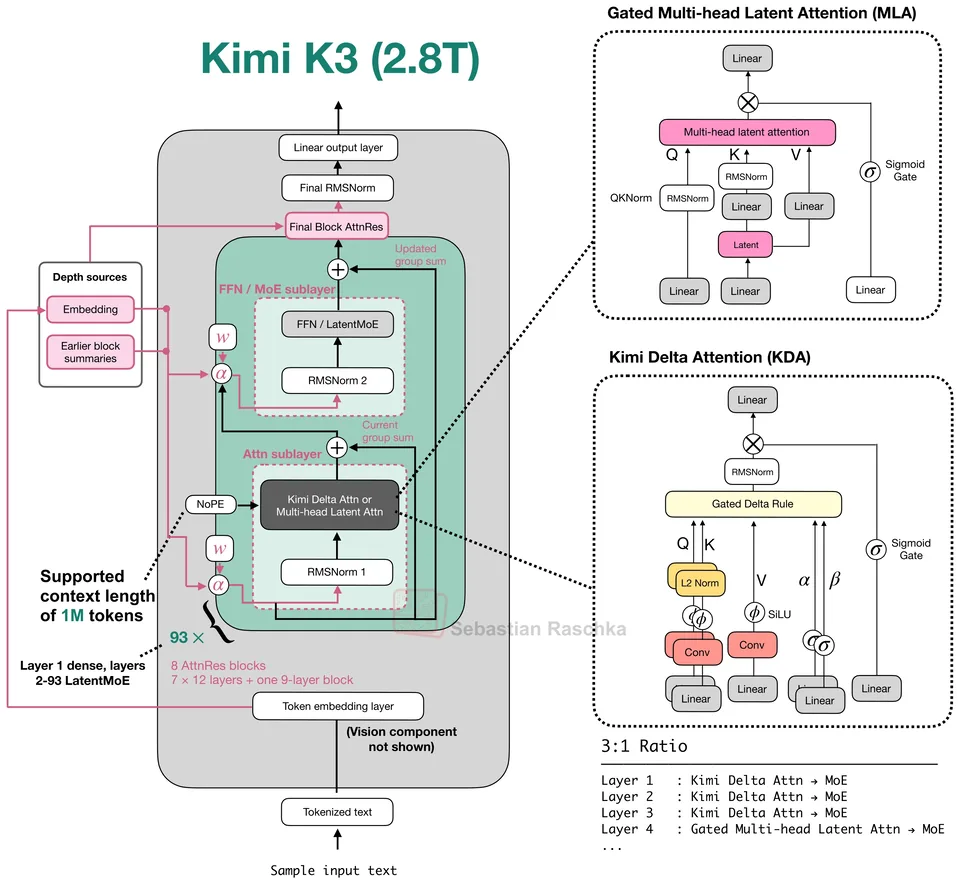
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Upstage, released 2026-07-22. Hybrid MoE decoder, 250B total, 15B active, 1M context. Attention: 3:1 Kimi Delta Attention and gated GQA with NoPE.
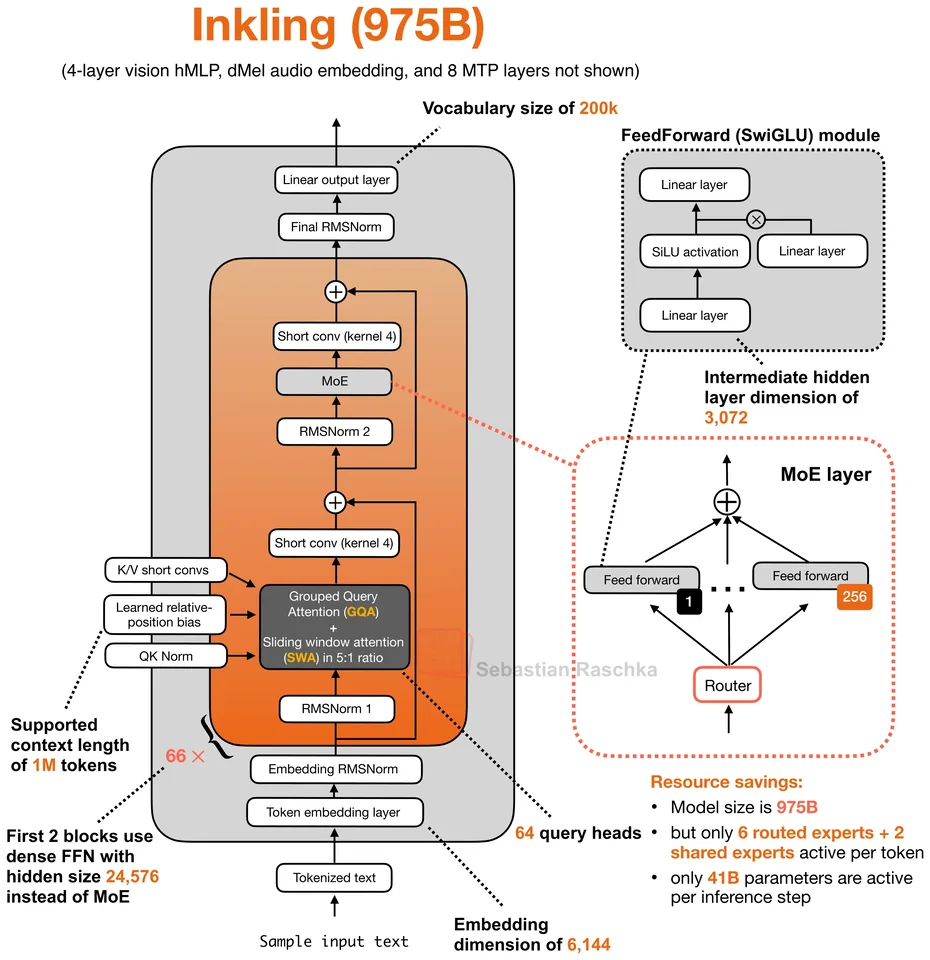
Thinking Machines Lab, released 2026-07-15. Sparse MoE decoder, 975B total, 41B active, 1M context. Attention: GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern.

Moonshot AI, released 2025-10-30. Hybrid MoE decoder, 48B total, 3B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA.
Jump to a model, concept or page