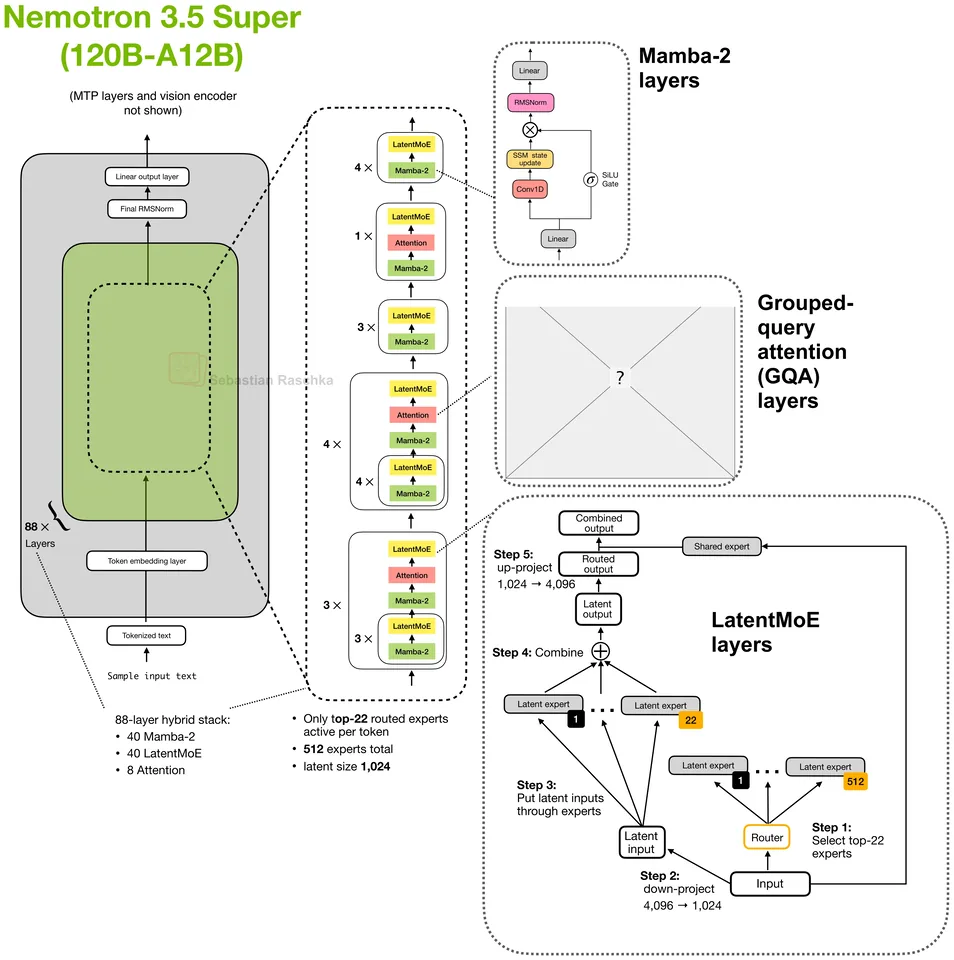
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
Attention · Hybrid attention
Mixes cheap linear-attention or state-space layers with a few full-attention layers.
Linear attention variants (Gated DeltaNet, Kimi Delta Attention, Lightning Attention) and state-space layers such as Mamba-2 keep a fixed-size recurrent state instead of a per-token KV cache, so their memory does not grow with context.
Because they are weaker at precise retrieval, hybrids interleave them with a smaller number of full-attention layers, for example three linear layers per full-attention layer in the Qwen pattern.
Models in the atlas using Hybrid attention, per half-year of release.
Often paired with
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
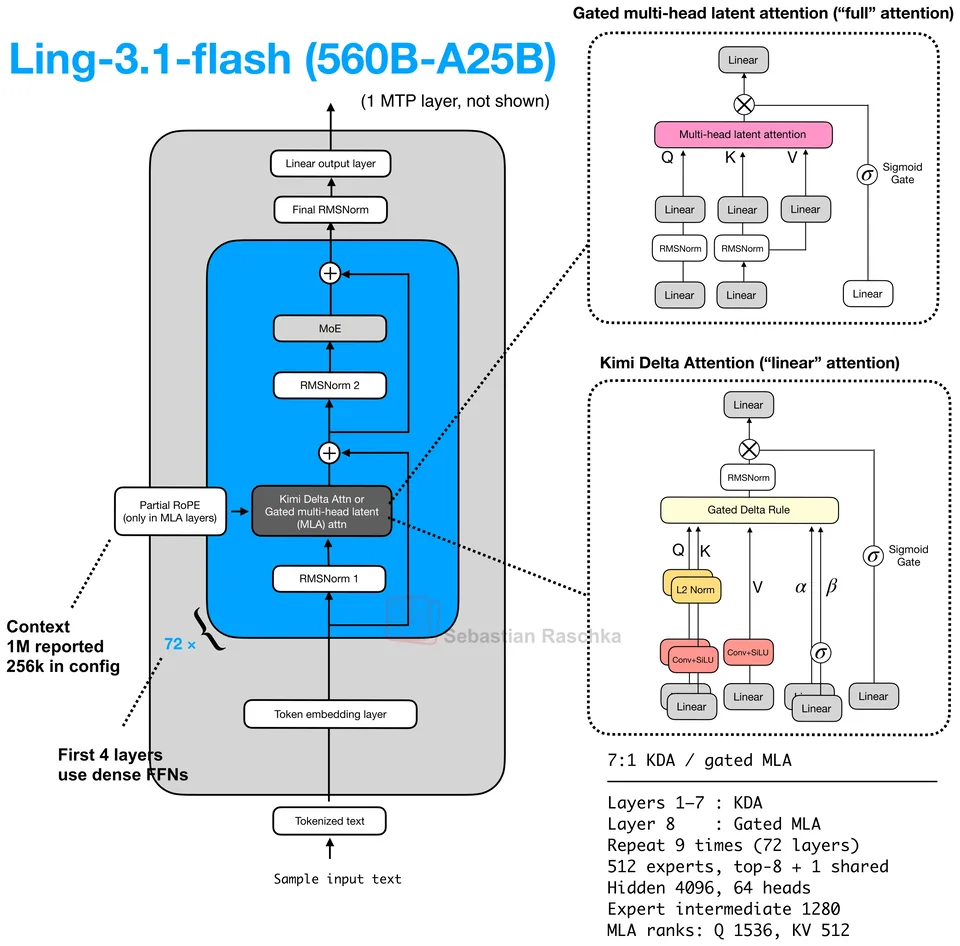
InclusionAI, released 2026-10-13. Hybrid MoE decoder, 560B total, 25B active, 1M context. Attention: 7:1 Kimi Delta Attention and gated MLA.
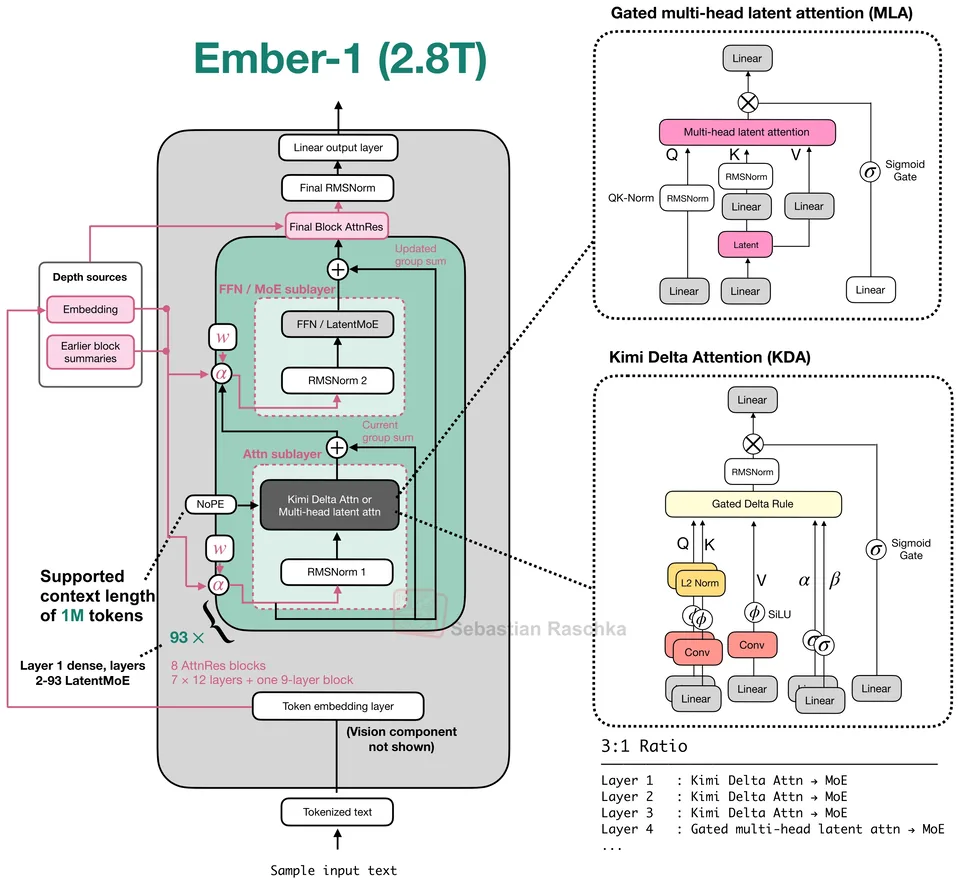
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
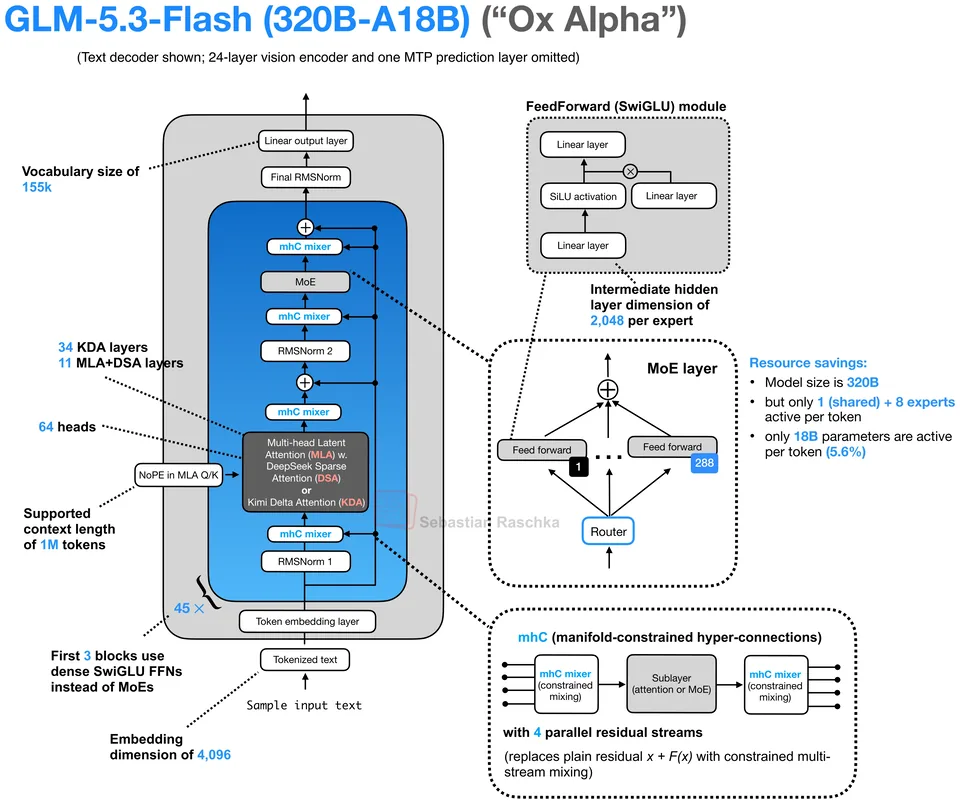
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.
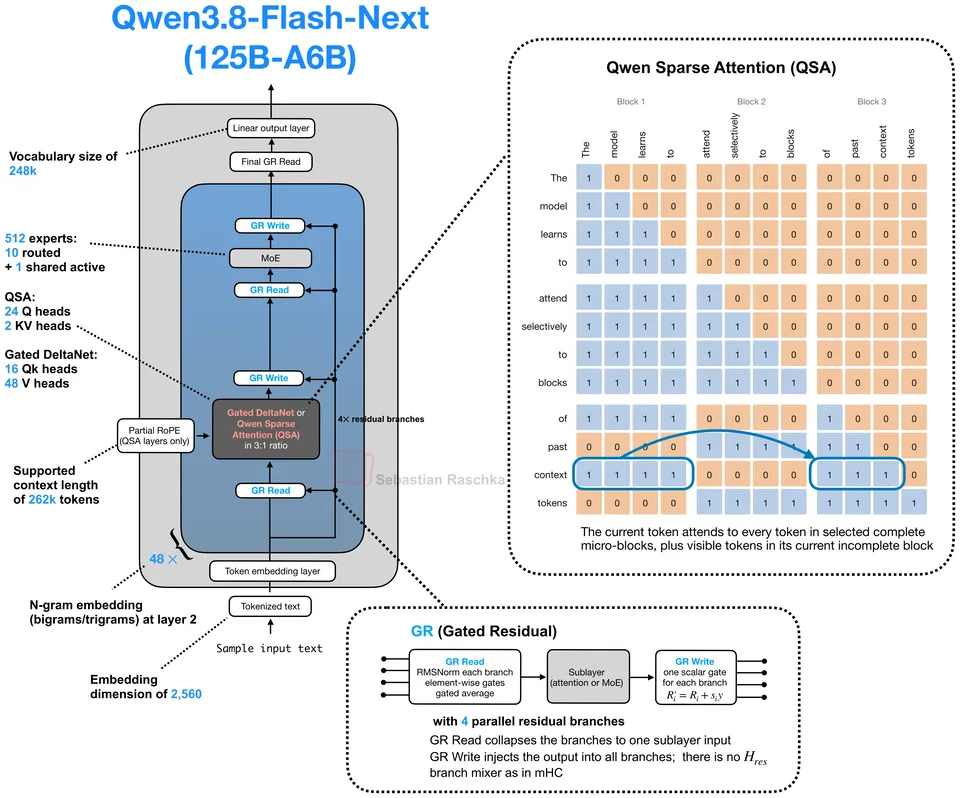
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
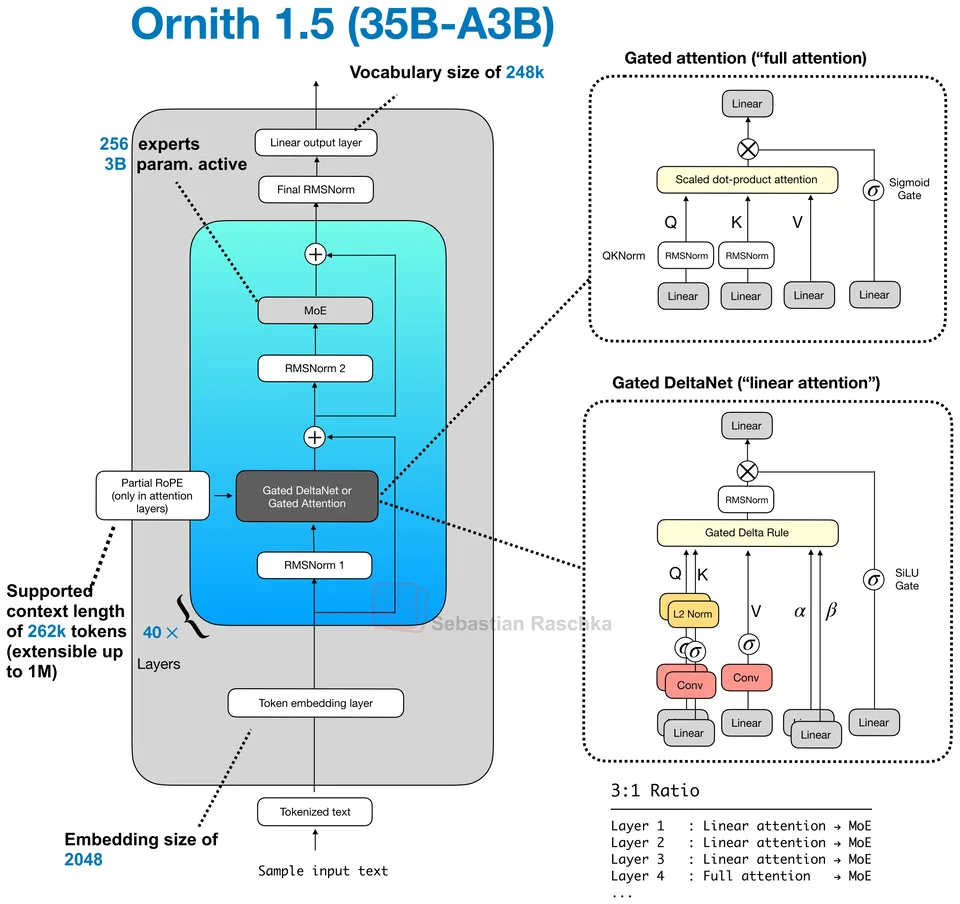
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
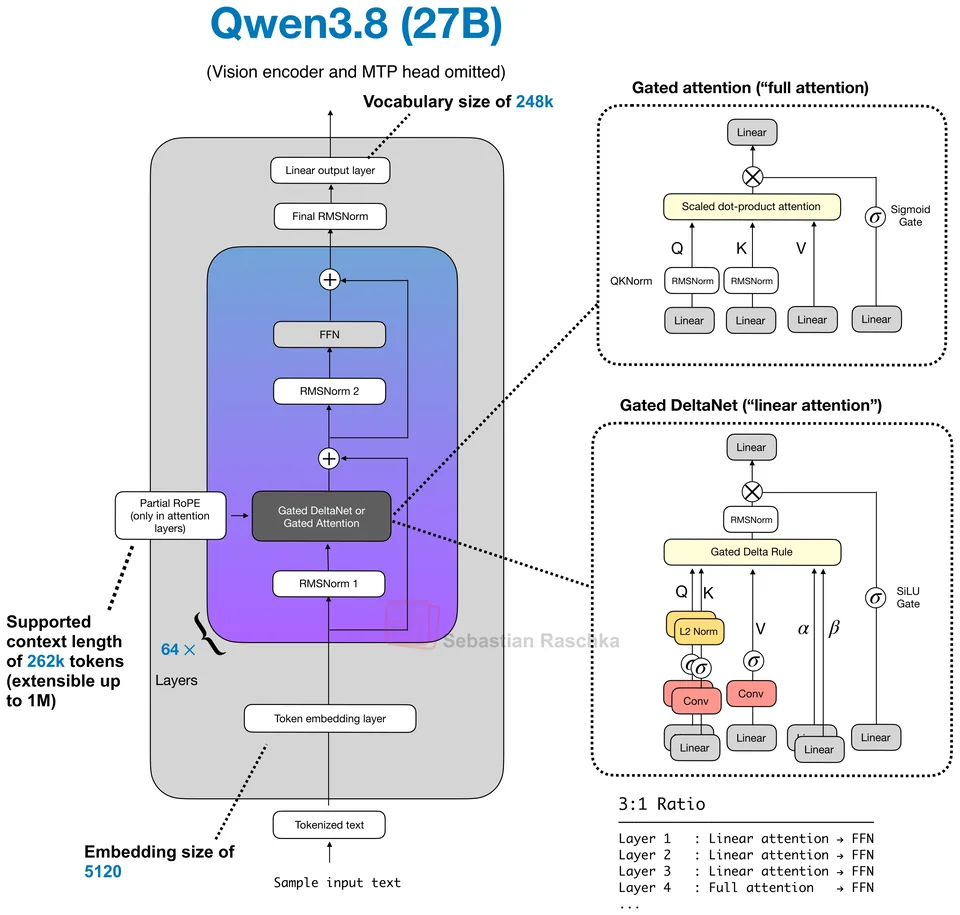
Alibaba Cloud, released 2026-08-14. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

NVIDIA, released 2026-08-11. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with six GQA layers.
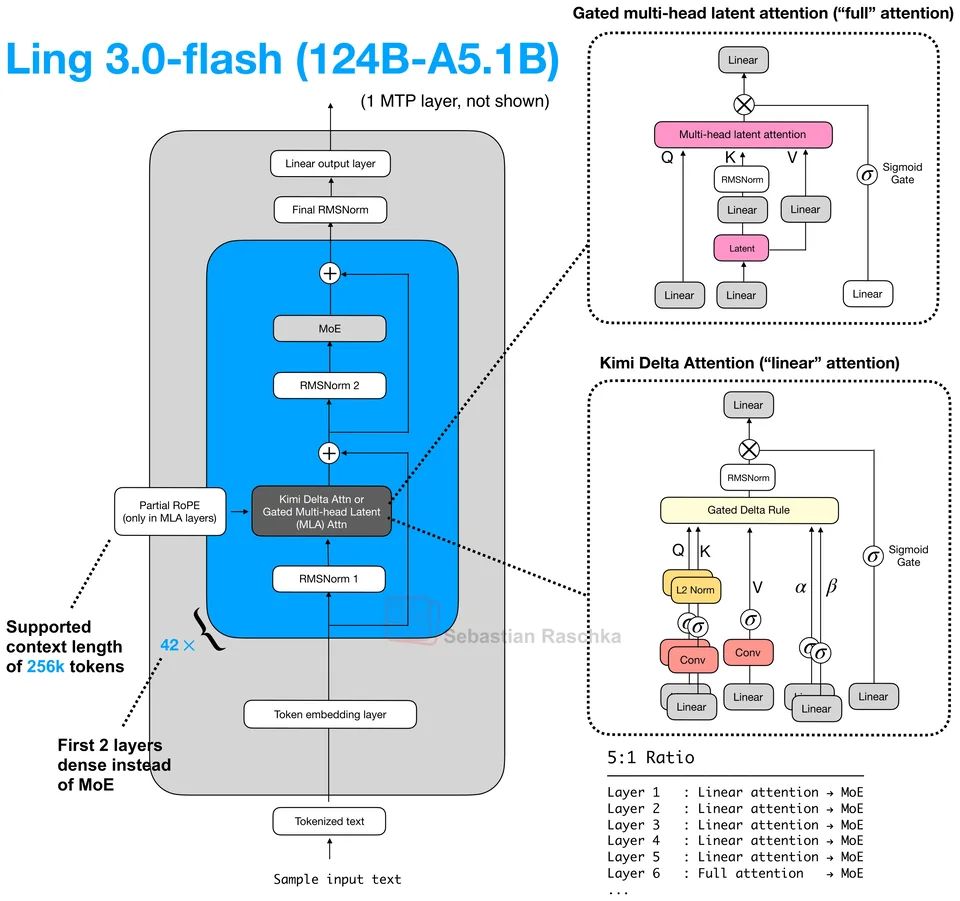
InclusionAI, released 2026-08-04. Hybrid MoE decoder, 124B total, 5.1B active, 256K context. Attention: 5:1 Kimi Delta Attention and gated MLA.
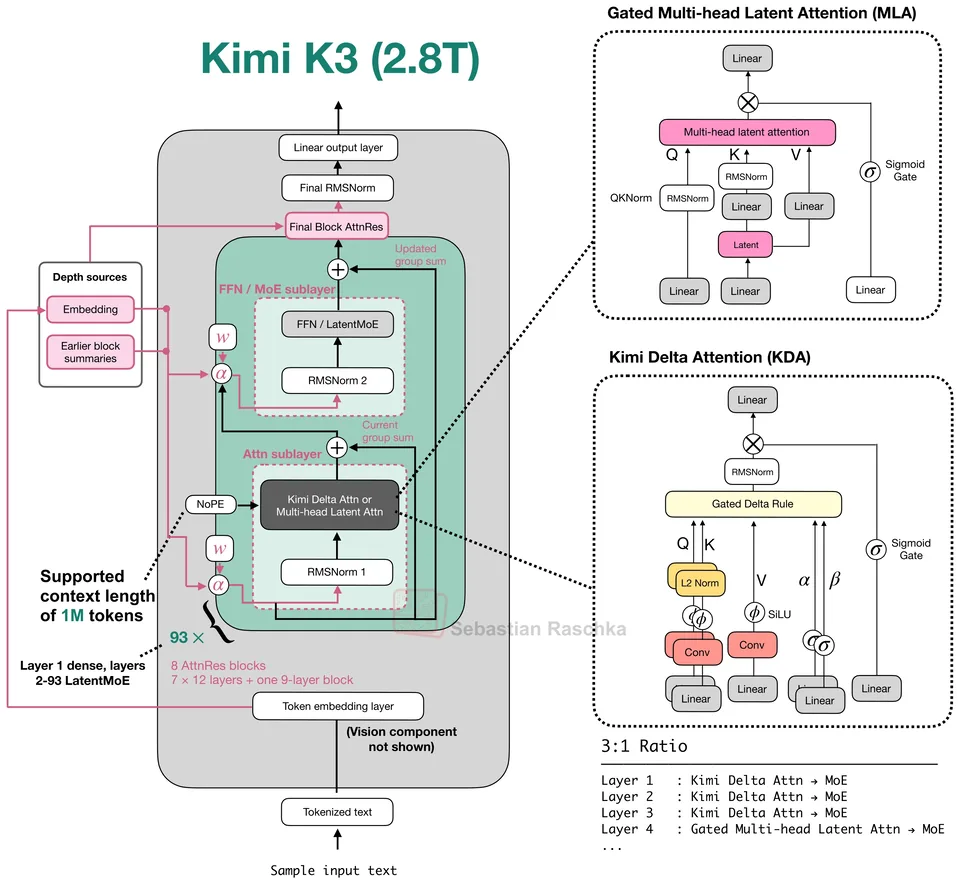
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Upstage, released 2026-07-22. Hybrid MoE decoder, 250B total, 15B active, 1M context. Attention: 3:1 Kimi Delta Attention and gated GQA with NoPE.

Bad Theory Labs, released 2026-07-20. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
Jump to a model, concept or page