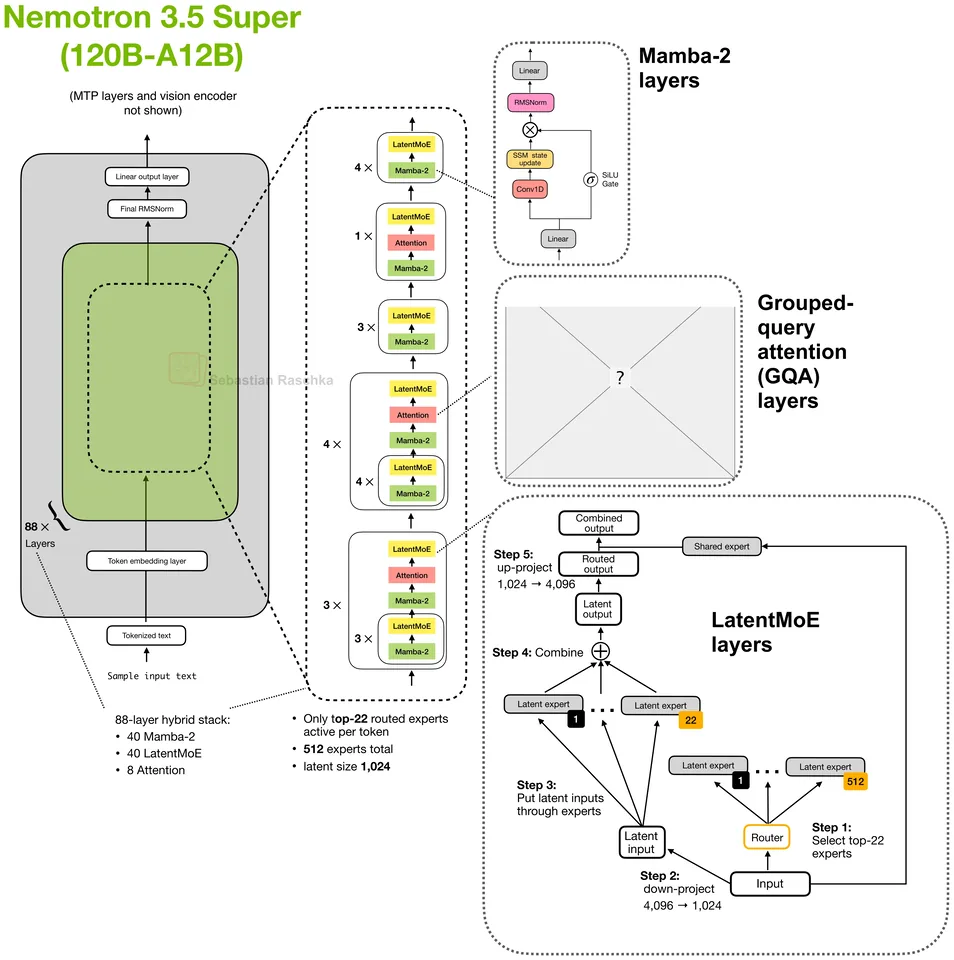
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
The Super variant scales up Nano and adds both latent experts and native speculative decoding support.
Key detail
Adds latent-space MoE and shared-weight MTP for fast inference.Total params
120B
Active / token
12B
Context
1M
Parameters active per token
10%
12B of 120B weights run for each token.
12.8
Use the ← and → keys to step through releases.
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
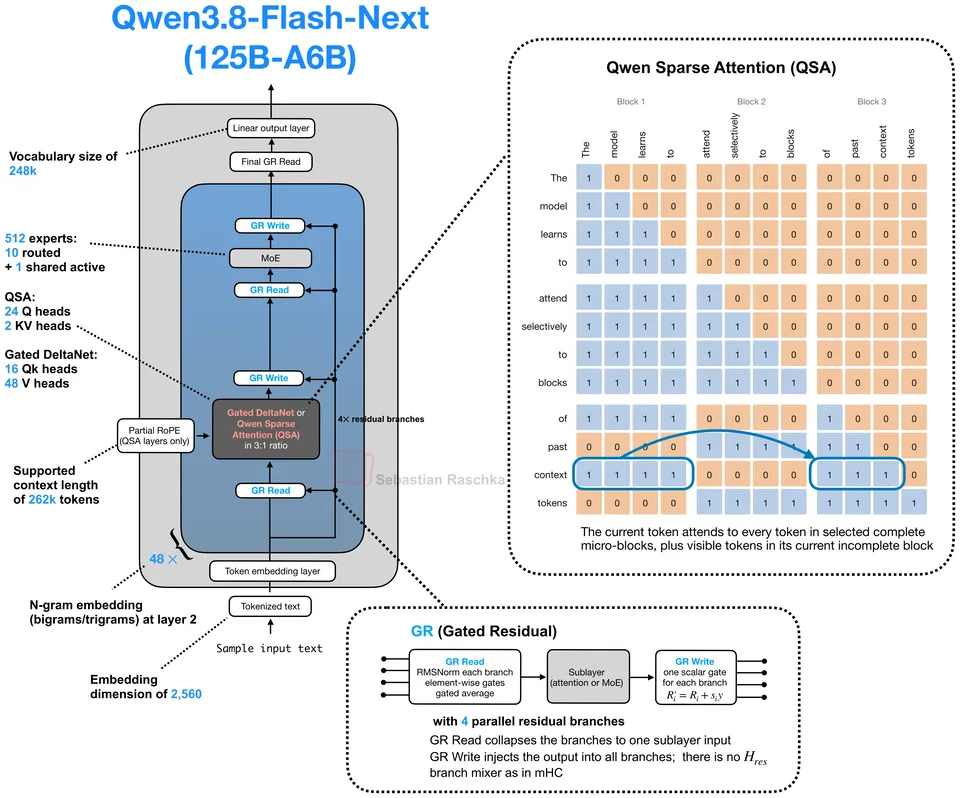
Alibaba Cloud, released 2026-08-26. Hybrid MoE decoder, 125B total, 6B active, 256K context. Attention: 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA).
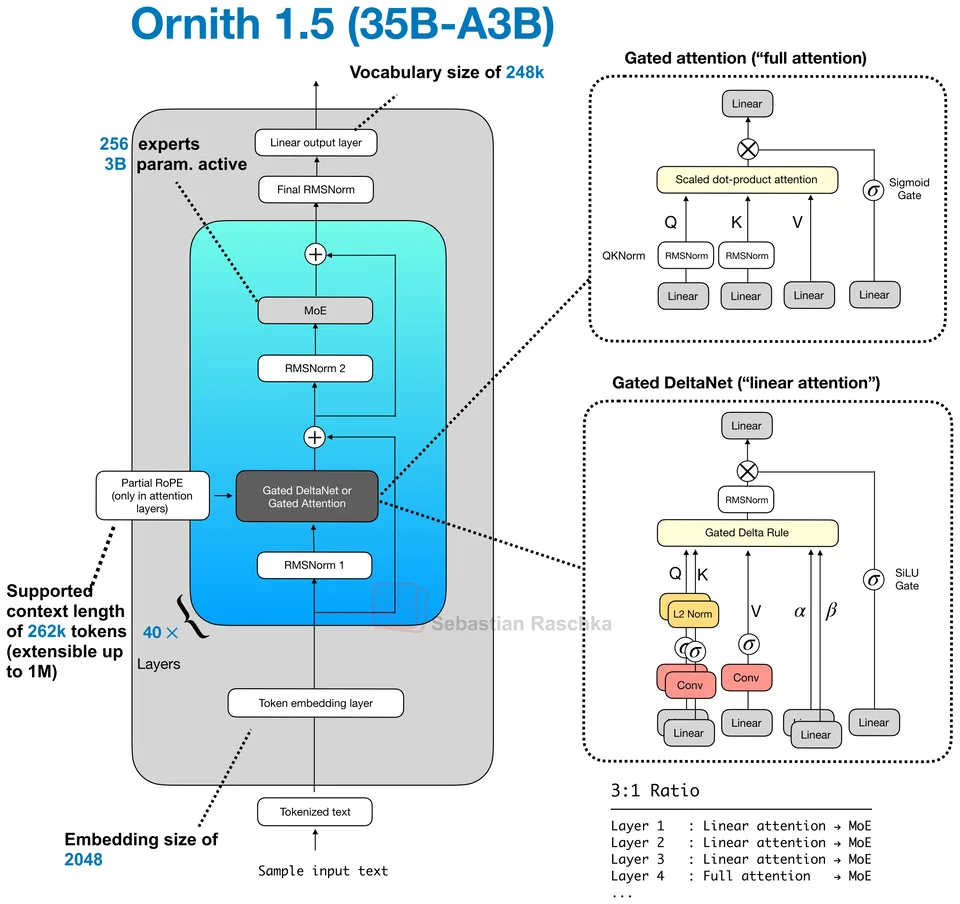
Ornith, released 2026-08-23. Hybrid MoE decoder, 35B total, 3B active, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.

NVIDIA, released 2026-08-11. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with six GQA layers.
Jump to a model, concept or page