
Bad Theory Labs, released 2026-07-20. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
Compact on-device hybrid that compresses Nemotron Nano 9B v2 into a mostly Mamba-2 stack with only four attention layers.
Key detail
Uses a 42-layer stack with 21 Mamba-2 blocks, 17 ReLU² FFNs, and just 4 GQA layers.Parameters
4B
Context
256K
KV / token
16 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
1.8
Use the ← and → keys to step through releases.
Bad Theory Labs, released 2026-07-20. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
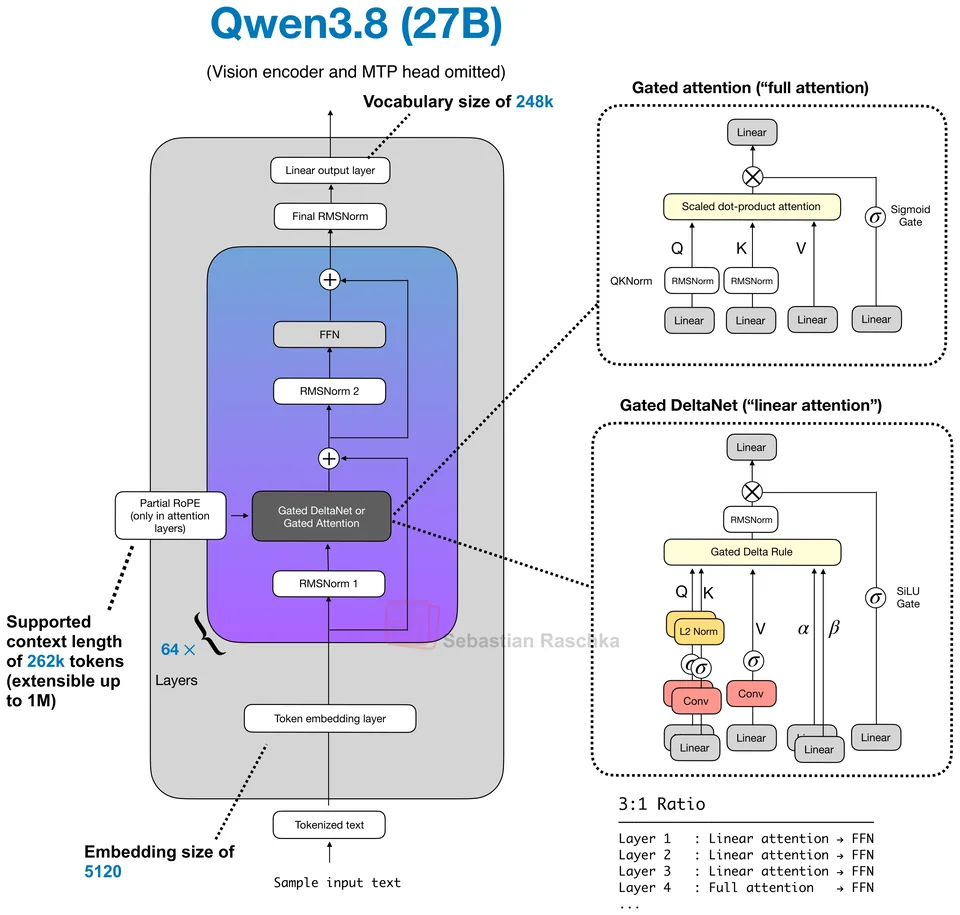
Alibaba Cloud, released 2026-08-14. Dense hybrid decoder, 27B parameters, 256K context. Attention: 3:1 Gated DeltaNet and Gated Attention.
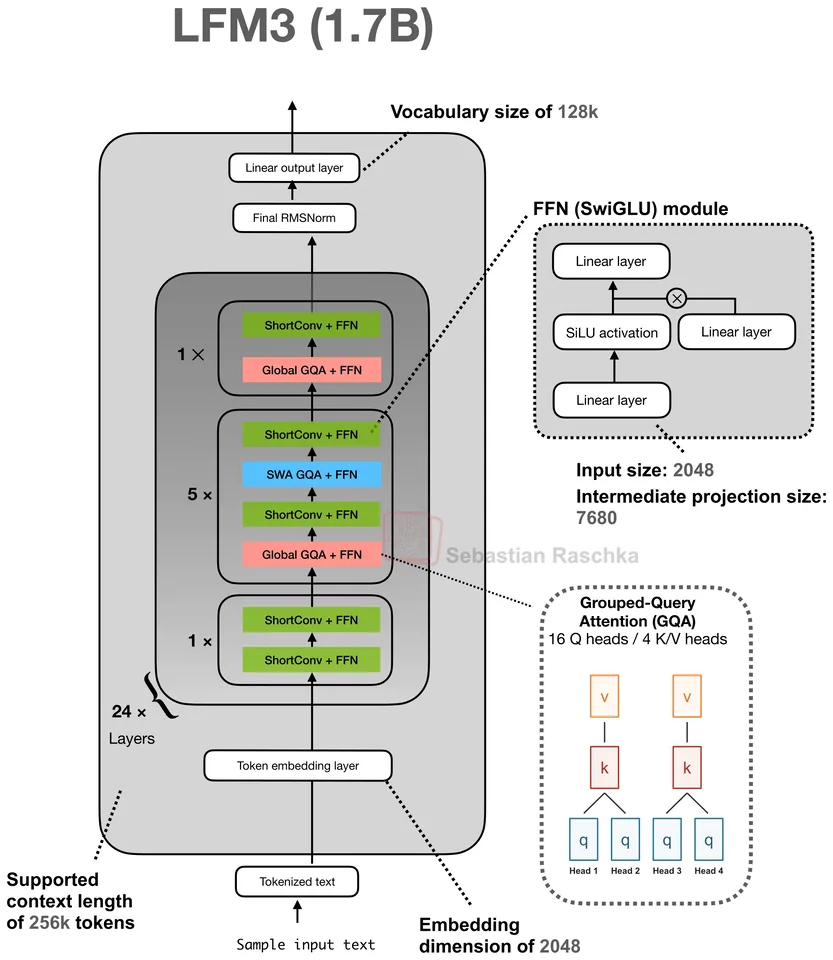
Liquid AI, released 2026-10-27. Dense hybrid decoder, 1.7B parameters, 256K context. Attention: ShortConv plus gated GQA with QK-Norm and sliding-window/global attention.

NVIDIA, released 2025-12-04. Hybrid MoE decoder, 30B total, 3B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.
Jump to a model, concept or page