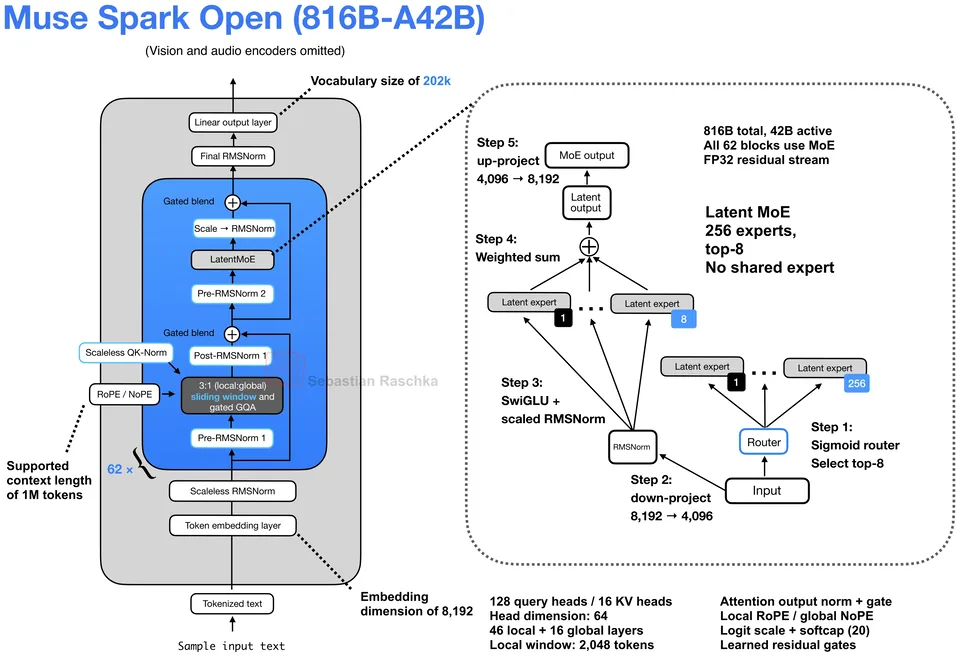
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
Feed-forward & experts · Latent MoE
Routed experts operate in a smaller latent space instead of the full hidden width.
Tokens are projected down before they enter the routed experts and projected back up afterwards. Experts become cheaper, so a model can afford more of them or activate more per token.
Nemotron 3 Super and Ultra, Kimi K3 and Muse Spark Open use this layout with different compression ratios and normalization details.
Models in the atlas using Latent MoE, per half-year of release.
Meta, released 2026-10-15. Sparse MoE decoder, 816B total, 42B active, 1M context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
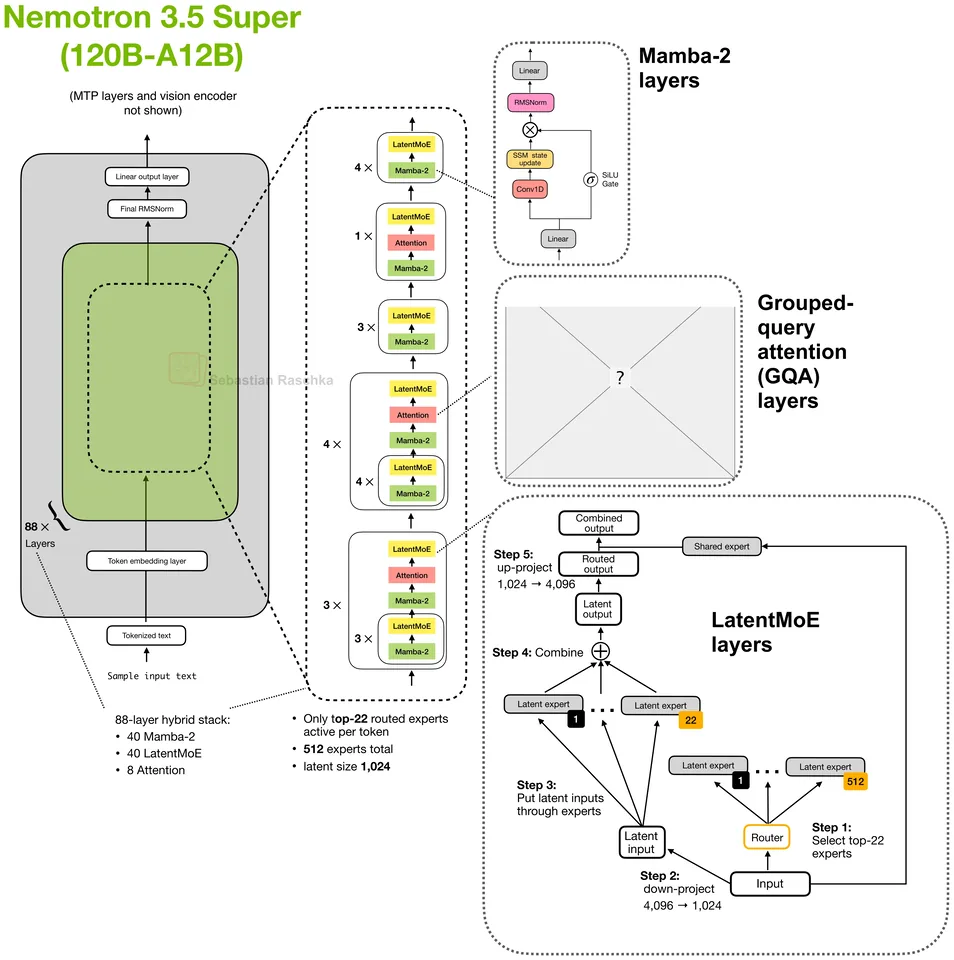
NVIDIA, released 2026-10-15. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with eight GQA layers.
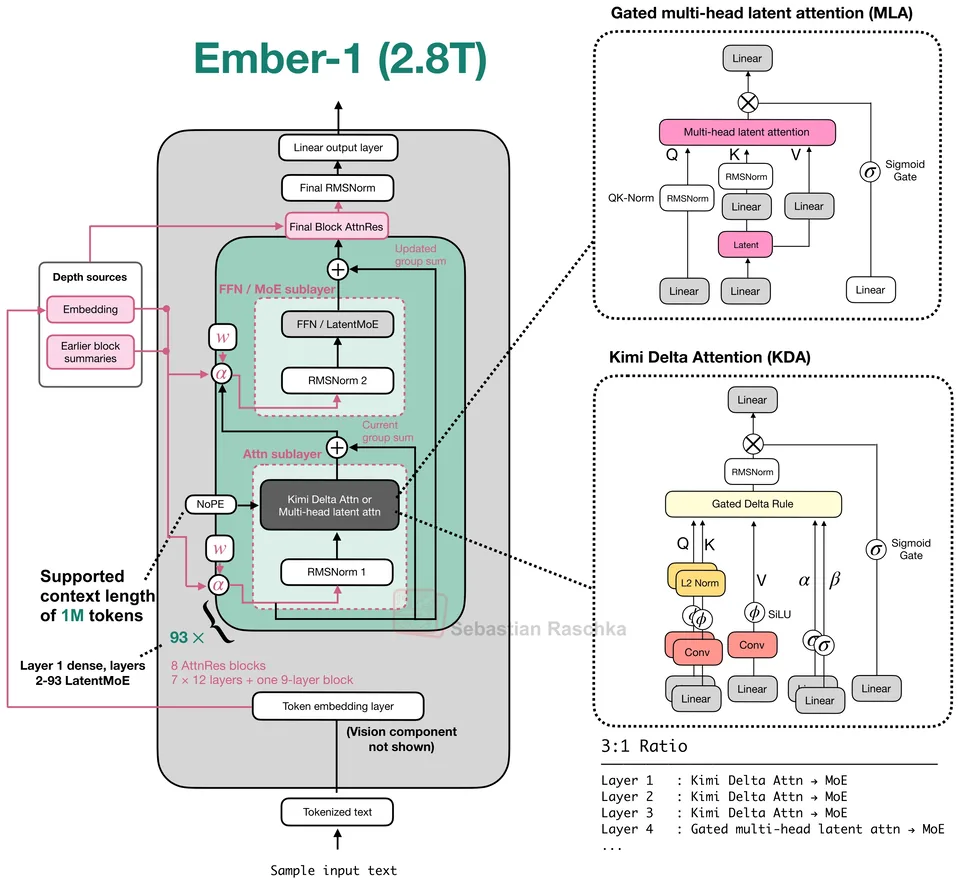
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
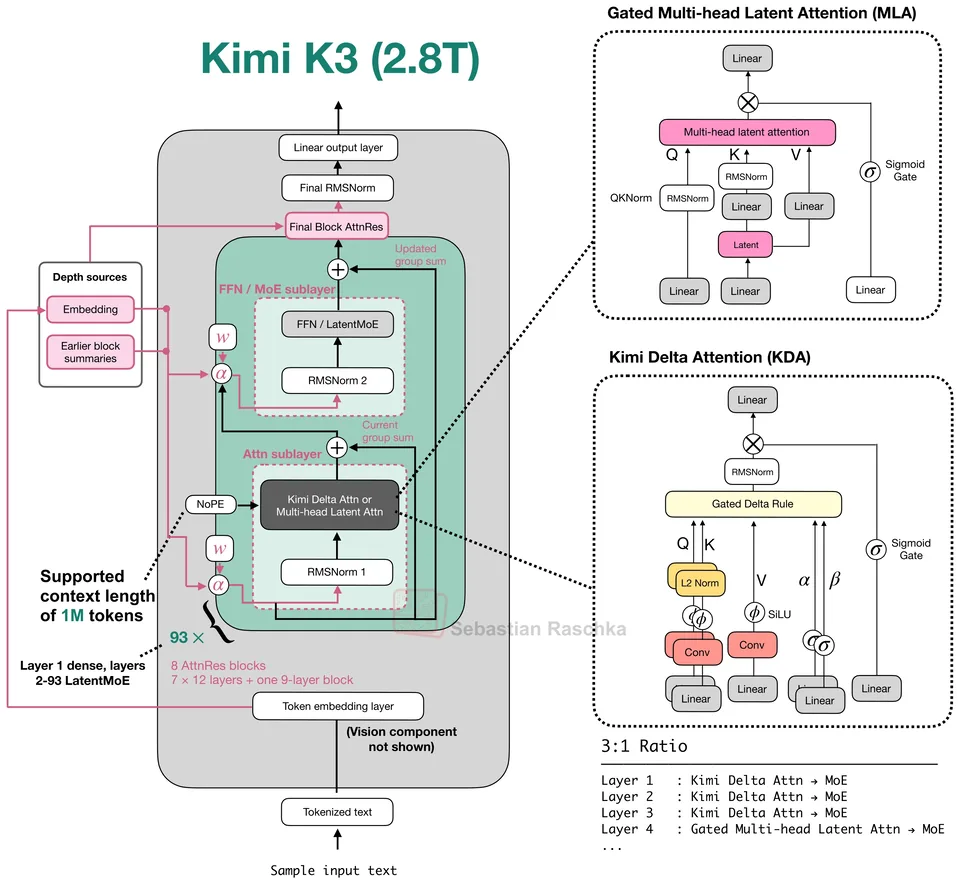
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

NVIDIA, released 2026-03-11. Hybrid MoE decoder, 120B total, 12B active, 1M context. Attention: Mostly Mamba-2 with a few GQA layers.
Jump to a model, concept or page