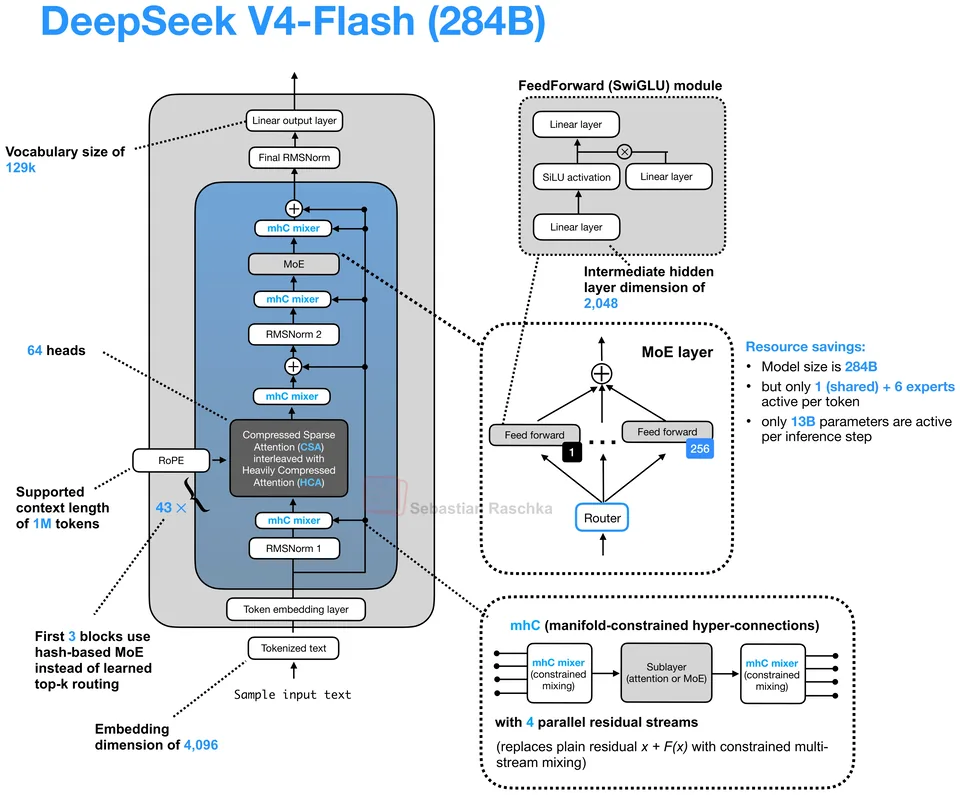
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
Sparse & compressed attention · CSA / HCA
Pool groups of older tokens into fewer KV entries, compressing along the sequence axis.
MLA shrinks each token's cache entry; CSA and HCA reduce how many entries there are. Groups of past tokens are pooled into compressed entries.
CSA compresses moderately and reads a sparse selection of entries; HCA compresses aggressively and reads all of them. DeepSeek V4 combines both to reach million-token contexts.
Models in the atlas using CSA / HCA, per half-year of release.
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

DeepSeek, released 2026-04-24. Sparse MoE decoder, 1.6T total, 49B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
Jump to a model, concept or page