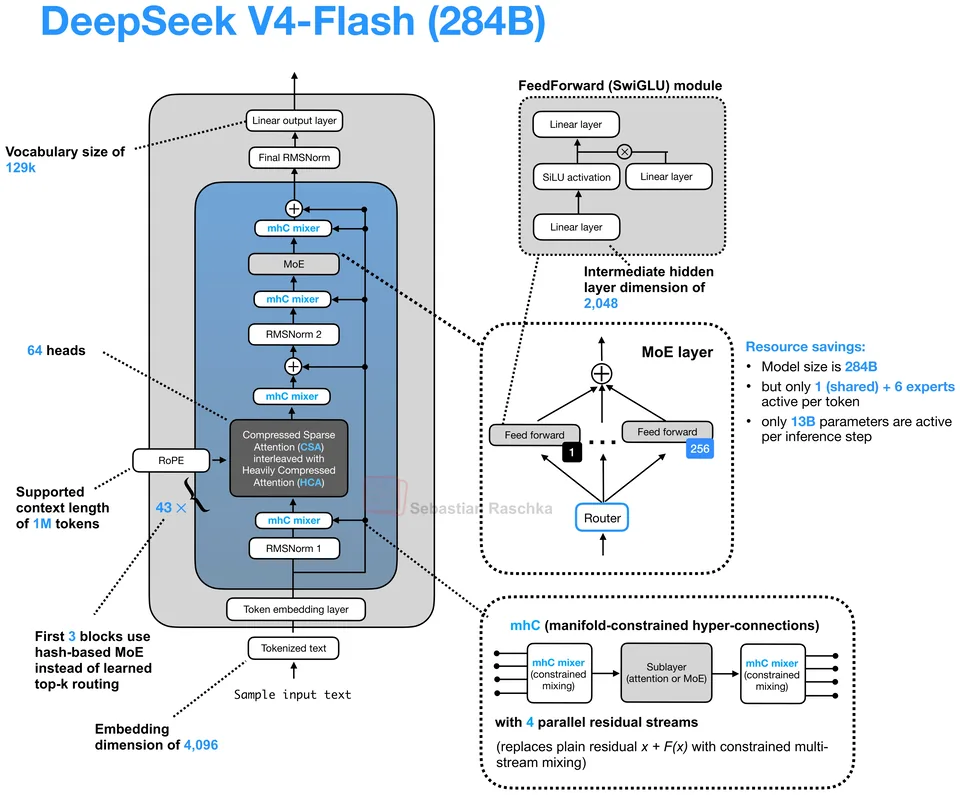
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
DeepSeek's flagship V4 preview scales to 1.6T parameters and introduces compressed sparse attention plus manifold-constrained hyper-connections for million-token contexts.
Key detail
Uses 384 experts, 6 routed plus 1 shared expert per token, hash-based routing, compressed attention caches, and the V4 MTP path.Total params
1.6T
Active / token
49B
Context
1M
Parameters active per token
3.1%
49B of 1.6T weights run for each token.
23.1
Use the ← and → keys to step through releases.
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
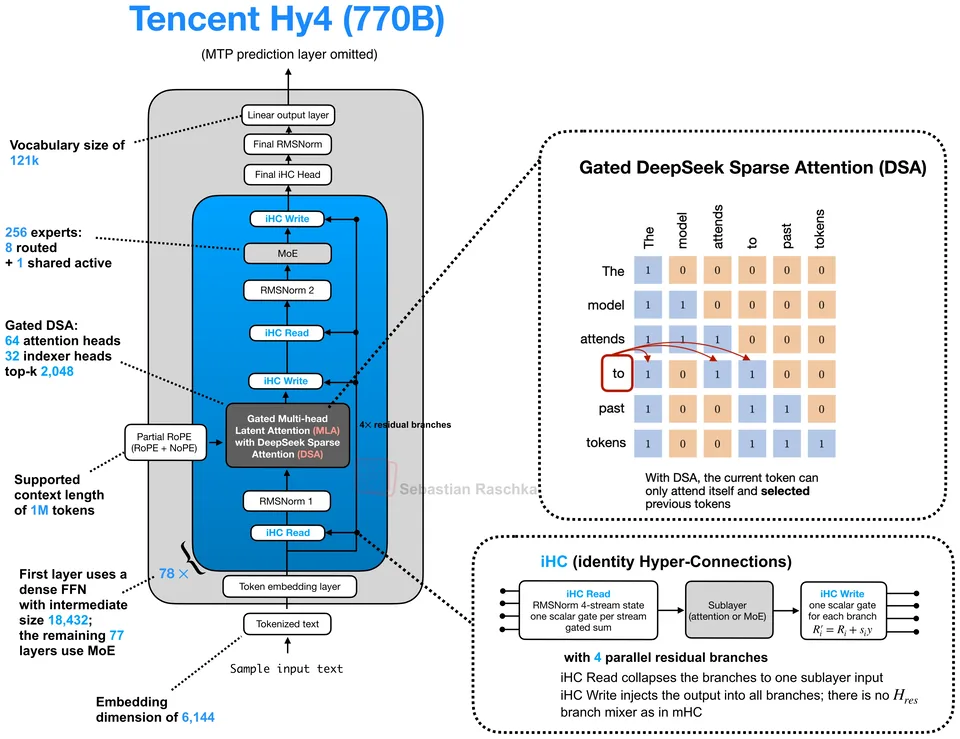
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
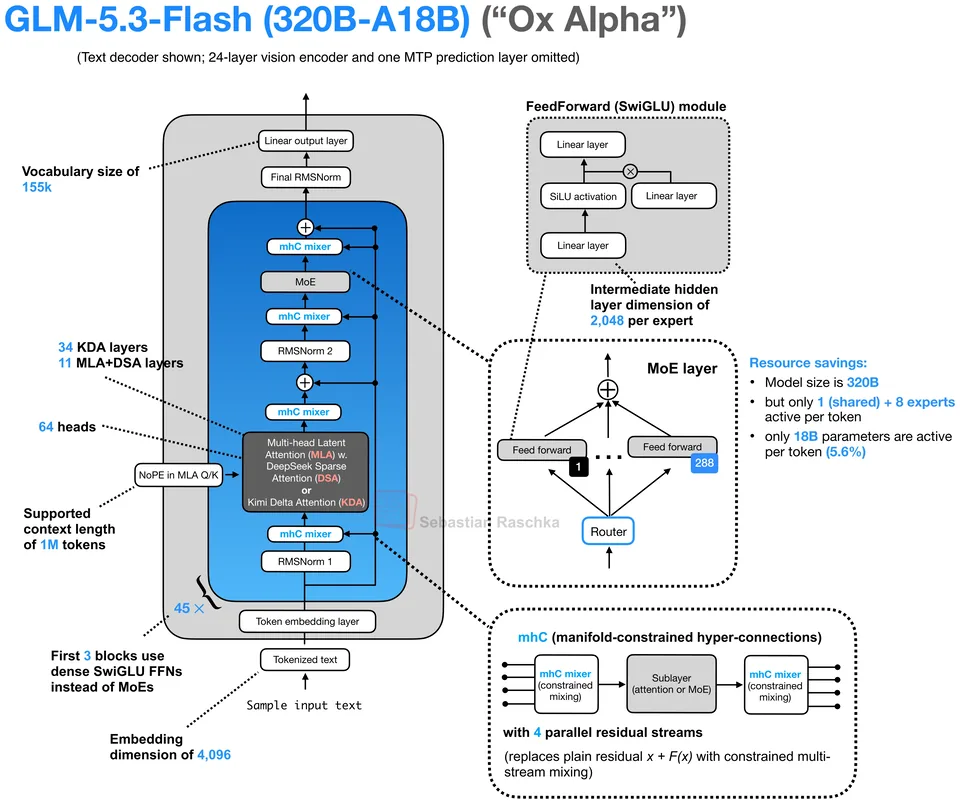
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.
Jump to a model, concept or page