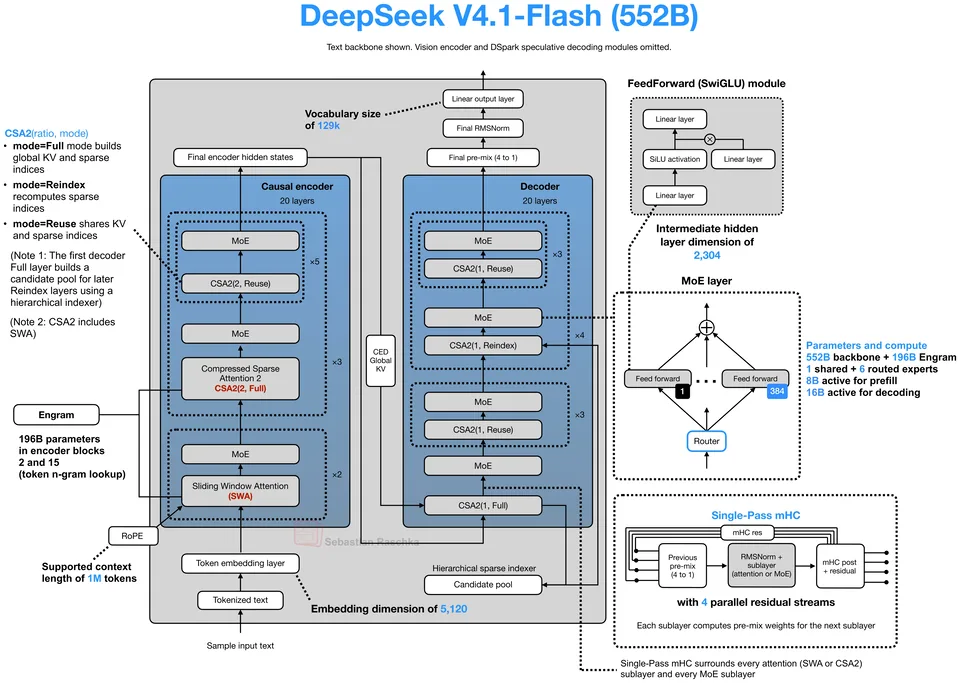
DeepSeek, released 2026-09-10. Sparse MoE decoder, 552B total, 8B active, 1M context. Attention: MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse.
Residual stream · mHC
Several parallel residual streams with learned, constrained mixing between them.
The single residual stream is widened into several streams (four in DeepSeek V4). Learned mappings decide how sublayer inputs are read from, and outputs written back to, these streams.
Unconstrained hyper-connections can amplify signals and destabilise training; mHC constrains the mixing matrix to a well-behaved manifold so information is mixed without blowing up. DeepSeek V4.1 introduced a cheaper single-pass variant.
Models in the atlas using mHC, per half-year of release.
DeepSeek, released 2026-09-10. Sparse MoE decoder, 552B total, 8B active, 1M context. Attention: MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse.
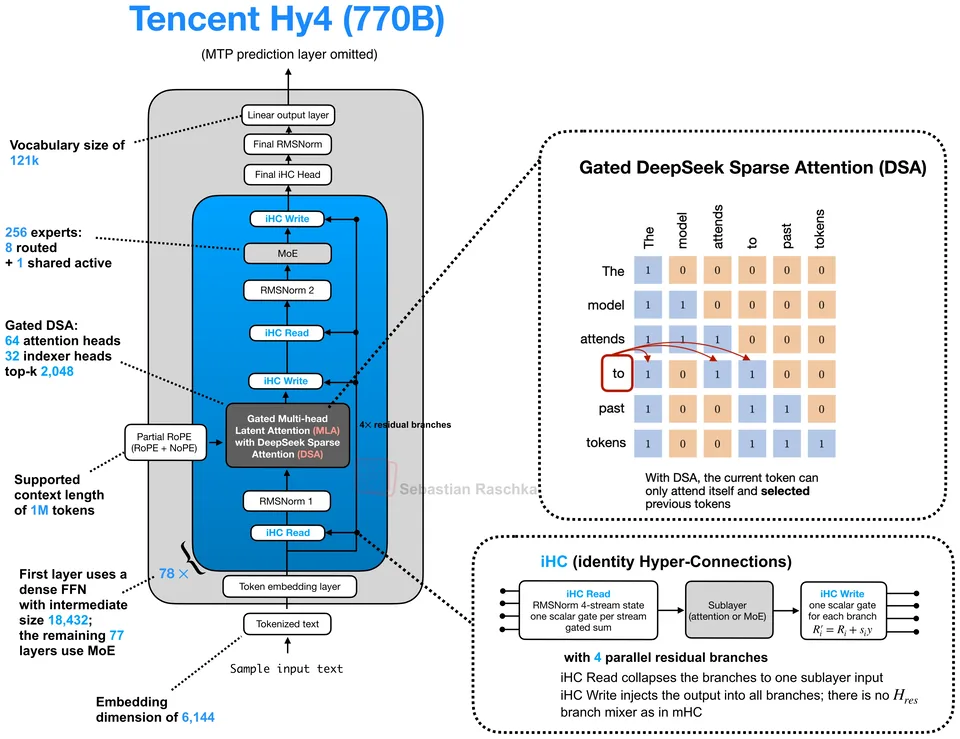
Tencent, released 2026-08-28. Sparse MoE decoder, 770B total, 49B active, 1M context. Attention: Gated MLA with DeepSeek Sparse Attention and IndexCache.
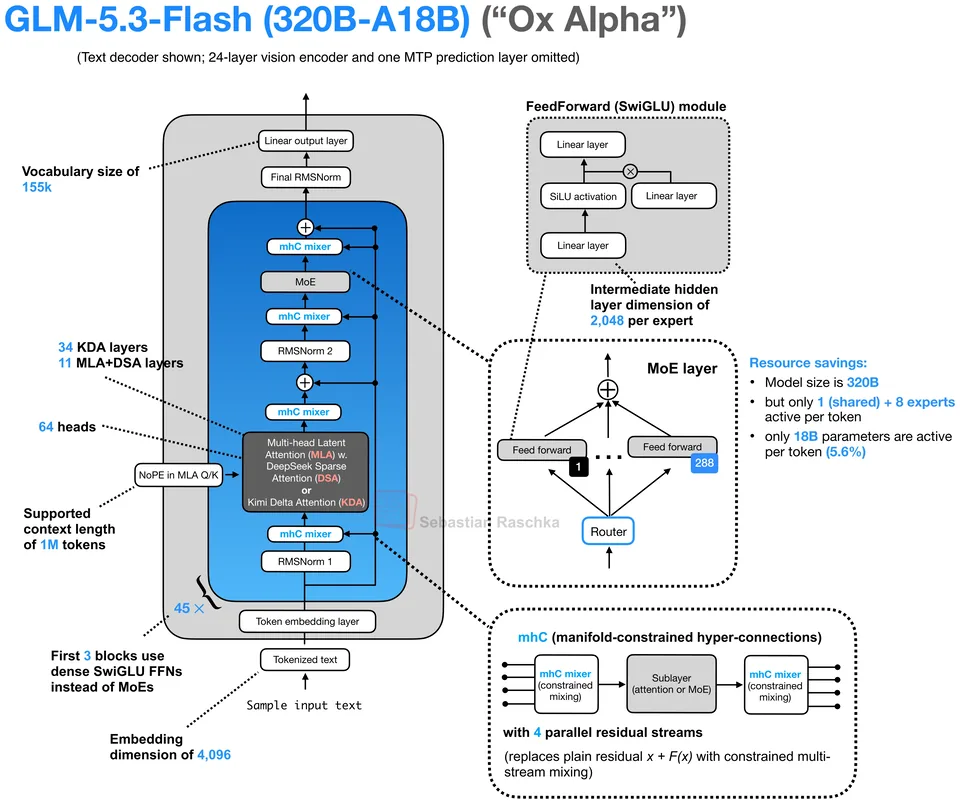
Z.ai, released 2026-08-26. Hybrid MoE decoder, 320B total, 18B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA with DeepSeek Sparse Attention.

Motif Technologies, released 2026-07-21. Sparse MoE decoder, 314B total, 13B active, 256K context. Attention: GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention.
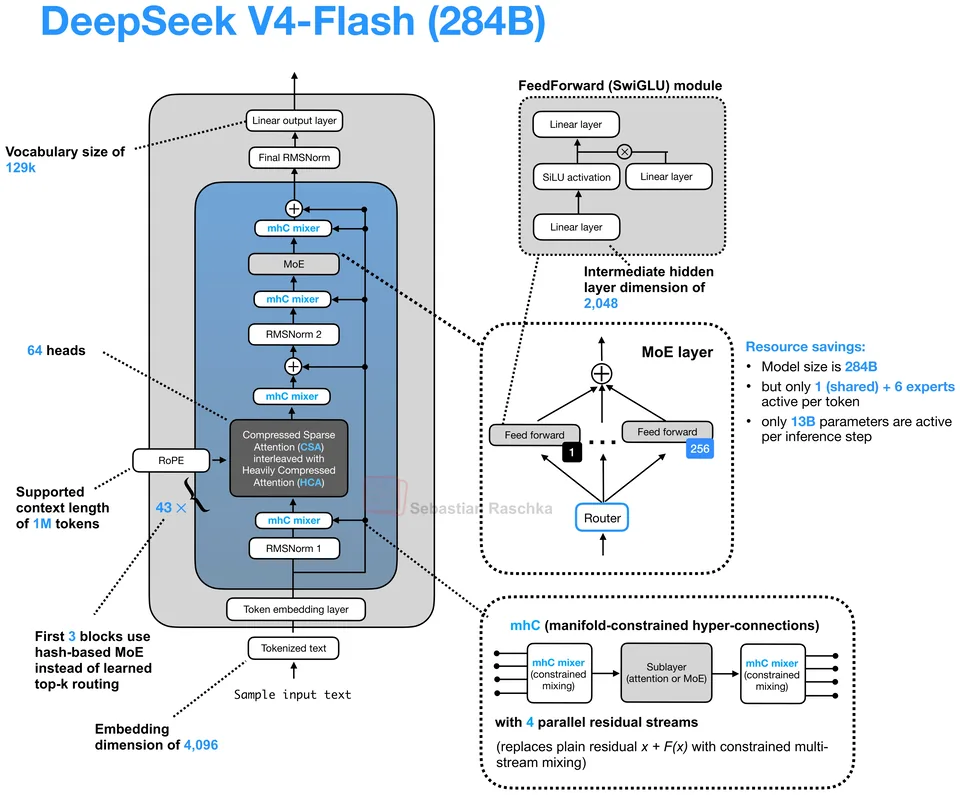
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

DeepSeek, released 2026-04-24. Sparse MoE decoder, 1.6T total, 49B active, 1M context. Attention: MLA-style CSA/HCA with mHC.
Jump to a model, concept or page