
Moonshot AI, released 2026-01-27. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
Trillion-parameter Moonshot model that essentially scales the DeepSeek V3 recipe upward.
Key detail
More experts and fewer MLA heads than DeepSeek V3.Total params
1T
Active / token
32B
Context
128K
Parameters active per token
3.2%
32B of 1T weights run for each token.
12.7
Use the ← and → keys to step through releases.
Moonshot AI, released 2026-01-27. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
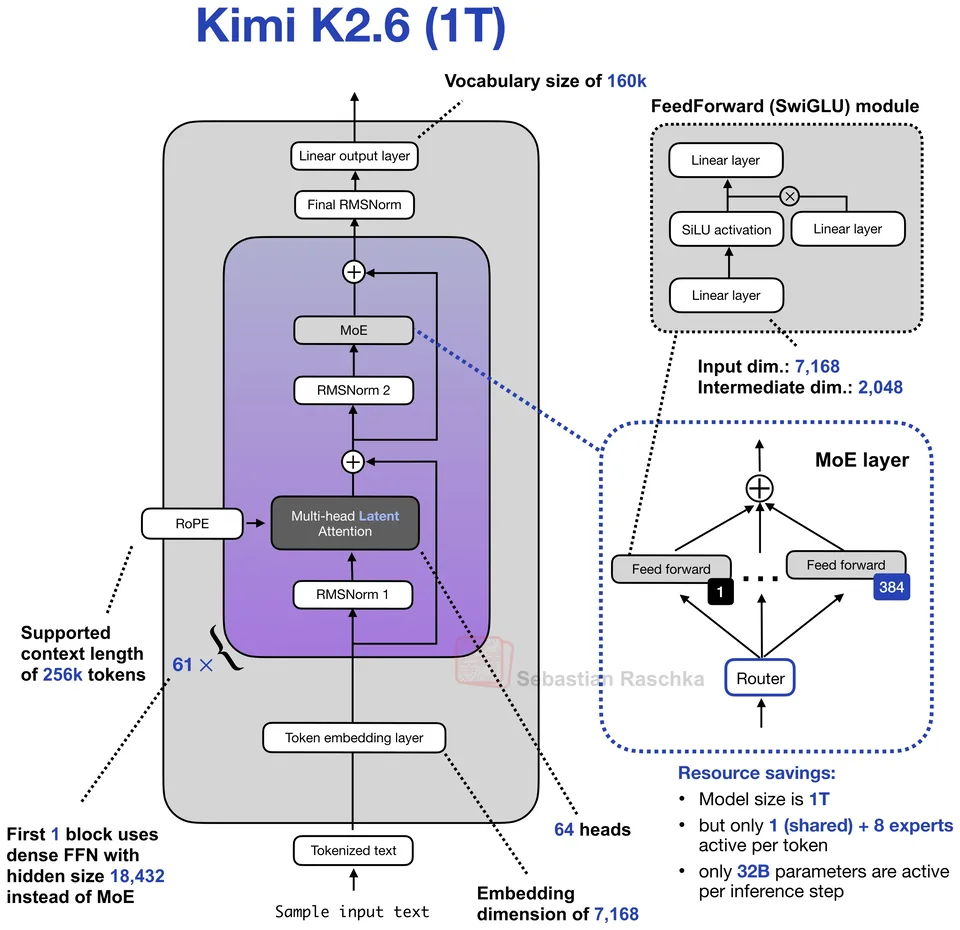
Moonshot AI, released 2026-04-20. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.

Moonshot AI, released 2026-06-12. Sparse MoE decoder, 1T total, 32B active, 256K context. Attention: MLA.
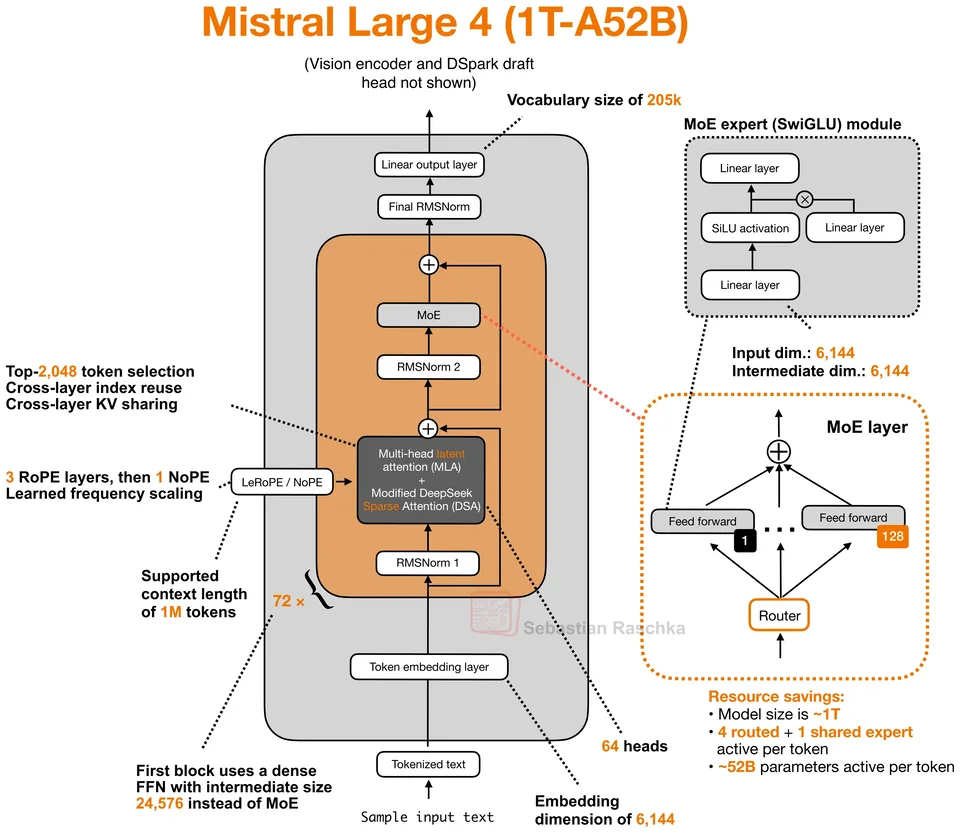
Mistral AI, released 2026-10-29. Sparse MoE decoder, 1T total, 52B active, 1M context. Attention: MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing.
Jump to a model, concept or page