
Sarvam AI, released 2026-03-03. Sparse MoE decoder, 105B total, 10B active, 128K context. Attention: MLA with KV LayerNorm and NoPE + RoPE.
Meituan's LongCat-Next text backbone is a lightweight MoE that shifts a large share of parameters into N-gram embeddings while keeping sparse inference around 3B active parameters.
Key detail
Uses N-gram embedding expansion, Shortcut MoE routing over 256 routed plus 128 zero/identity experts, and top-k 12 expert choices per token.Total params
69B
Active / token
3B
Context
256K
Parameters active per token
4.4%
3B of 69B weights run for each token.
11.5
Use the ← and → keys to step through releases.
Sarvam AI, released 2026-03-03. Sparse MoE decoder, 105B total, 10B active, 128K context. Attention: MLA with KV LayerNorm and NoPE + RoPE.

Mistral AI, released 2026-03-16. Sparse MoE decoder, 119B total, 6.6B active, 256K context. Attention: MLA.
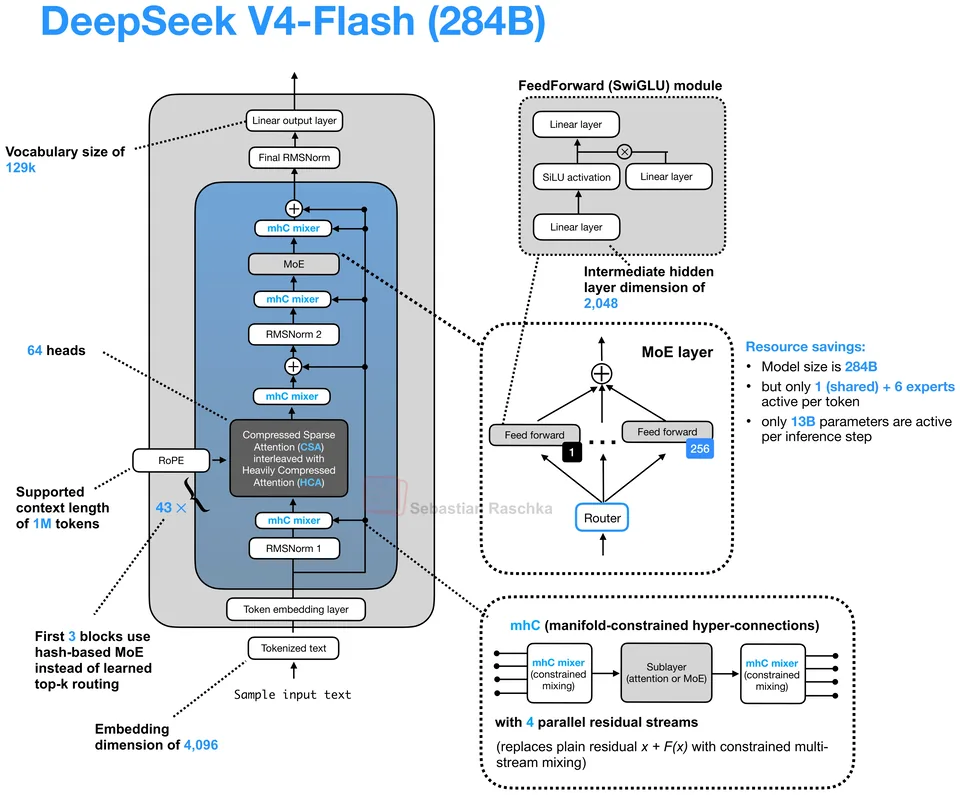
DeepSeek, released 2026-04-24. Sparse MoE decoder, 284B total, 13B active, 1M context. Attention: MLA-style CSA/HCA with mHC.

Motif Technologies, released 2026-07-21. Sparse MoE decoder, 314B total, 13B active, 256K context. Attention: GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention.
Jump to a model, concept or page