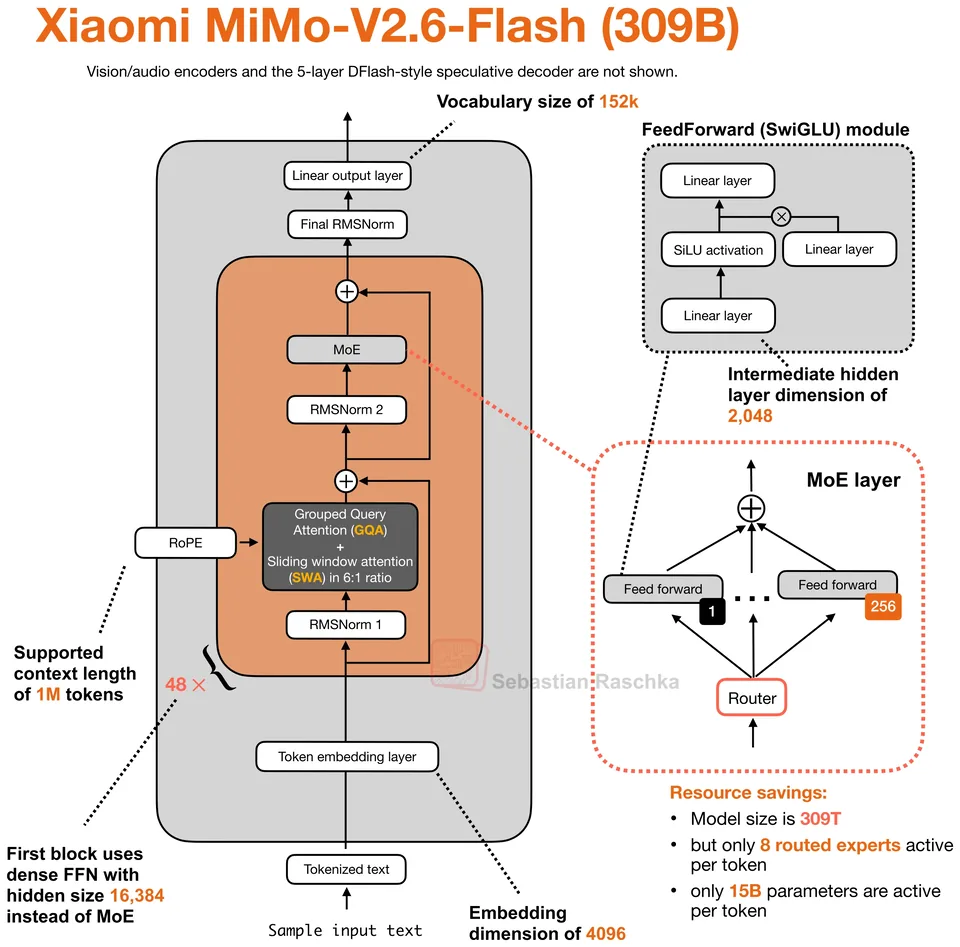
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.
Large MoE model that pushes sliding-window attention harder than most contemporaries.
Key detail
Uses an unusually small 128-token local window plus multi-token prediction.Total params
309B
Active / token
15B
Context
256K
Parameters active per token
4.9%
15B of 309B weights run for each token.
16
Use the ← and → keys to step through releases.
Xiaomi, released 2026-09-21. Sparse MoE decoder, 309B total, 15B active, 1M context. Attention: GQA with sliding-window/global attention.

Xiaomi, released 2026-04-22. Sparse MoE decoder, 310B total, 15B active, 1M context. Attention: 5:1 sliding-window/global attention.

Motif Technologies, released 2026-07-21. Sparse MoE decoder, 314B total, 13B active, 256K context. Attention: GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention.

MiniMax, released 2026-02-12. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page