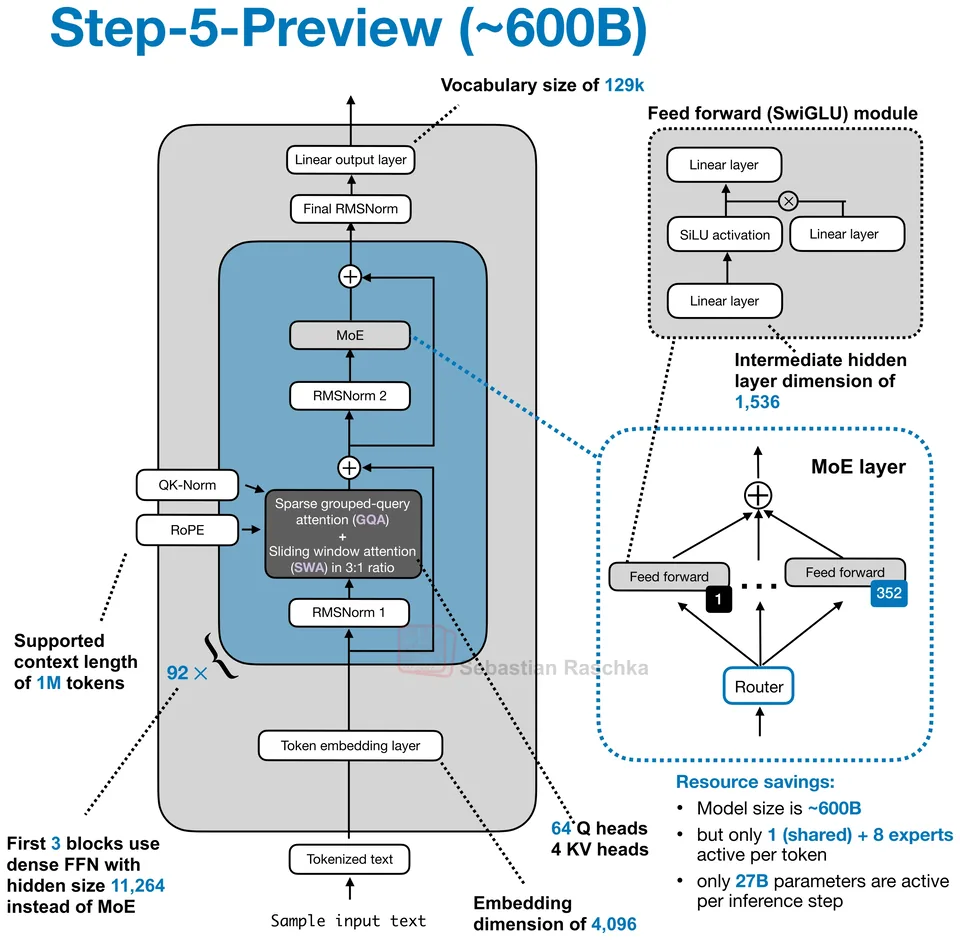
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
Popular 230B coder that opts for a classic architecture instead of the newer hybrid-attention ideas.
Key detail
Deliberately avoids sliding-window or linear-attention hybrids while keeping a 10B active path and three MTP modules.Total params
230B
Active / token
10B
Context
192K
Parameters active per token
4.3%
10B of 230B weights run for each token.
22.8
Use the ← and → keys to step through releases.
StepFun, released 2026-09-20. Sparse MoE decoder, 600B total, 27B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention.
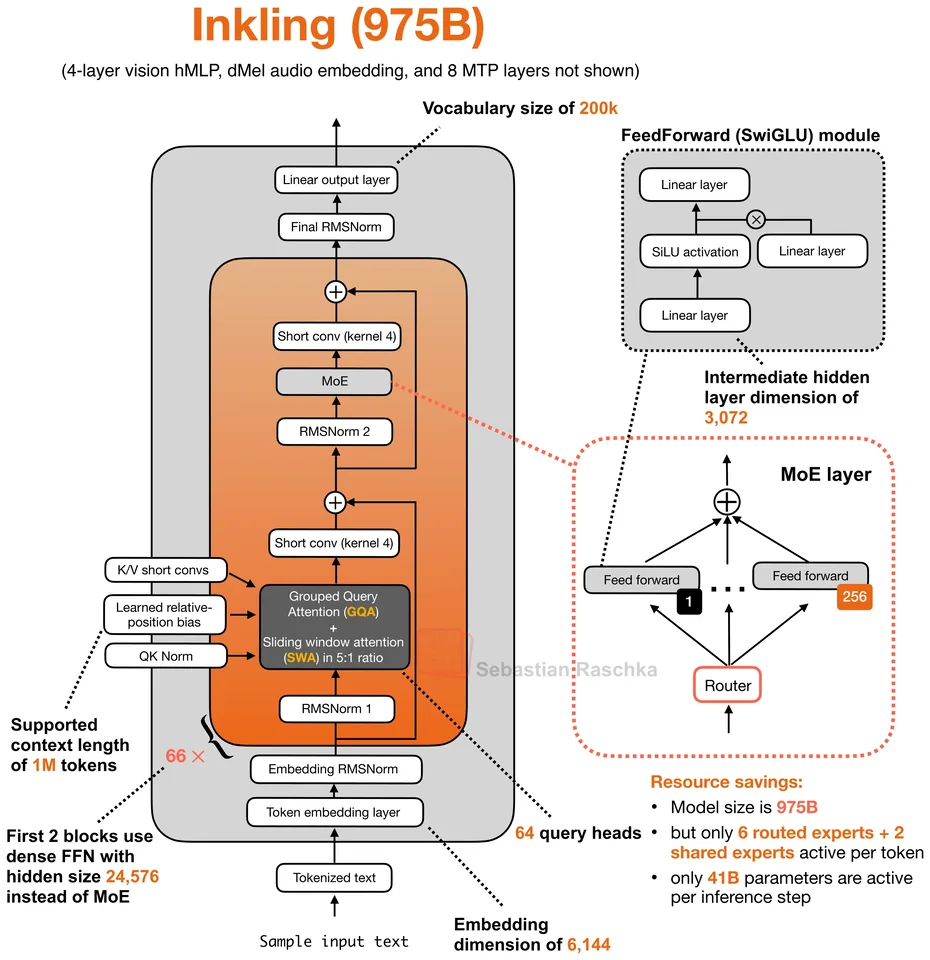
Thinking Machines Lab, released 2026-07-15. Sparse MoE decoder, 975B total, 41B active, 1M context. Attention: GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern.

MiniMax, released 2025-10-23. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm and partial RoPE.

MiniMax, released 2026-03-18. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page