
Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.
Compact multilingual model from Cohere with a rare parallel transformer block.
Key detail
Runs attention and the MLP in parallel while mixing RoPE with NoPE.Parameters
3.4B
Context
8K
KV / token
72 KiB
Parameters active per token
100%
Dense: every weight runs for every token.
4.8
Use the ← and → keys to step through releases.
Meta, released 2026-08-10. Dense decoder, 30B parameters, 128K context. Attention: Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention.

Hugging Face, released 2025-06-19. Dense decoder, 3B parameters, 128K context. Attention: GQA with periodic NoPE layers.
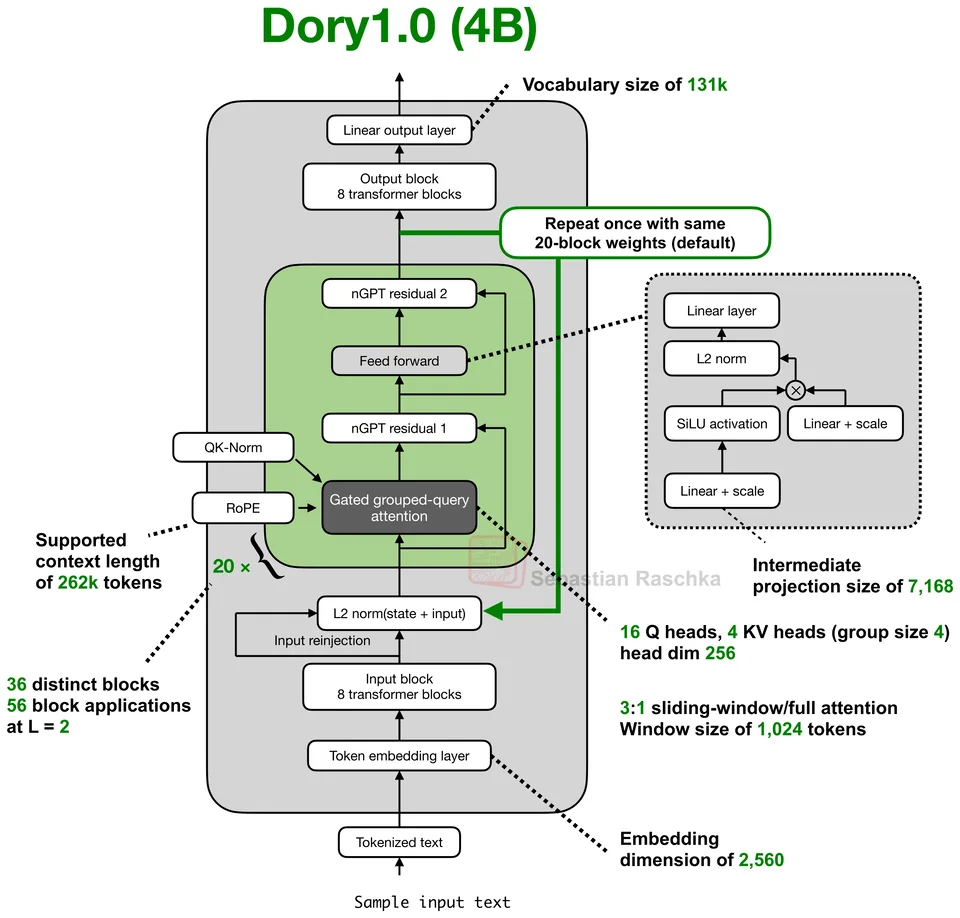
NVIDIA, released 2026-10-16. Dense decoder, 4B parameters, 256K context. Attention: Gated GQA; 3:1 sliding-window/full, RoPE.

Google, released 2026-04-02. Dense decoder, 8B parameters, 128K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.
Jump to a model, concept or page