
Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.
Meta's large MoE follows the DeepSeek V3 playbook but with a more conventional attention stack.
Key detail
Alternates dense and MoE blocks and uses fewer, larger experts than DeepSeek V3.Total params
400B
Active / token
17B
Context
1M
Parameters active per token
4.3%
17B of 400B weights run for each token.
9.3
Use the ← and → keys to step through releases.
Arcee AI, released 2026-01-27. Sparse MoE decoder, 400B total, 13B active, 512K context. Attention: GQA with gated attention and 3:1 sliding-window/global attention.

MiniMax, released 2026-06-13. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.
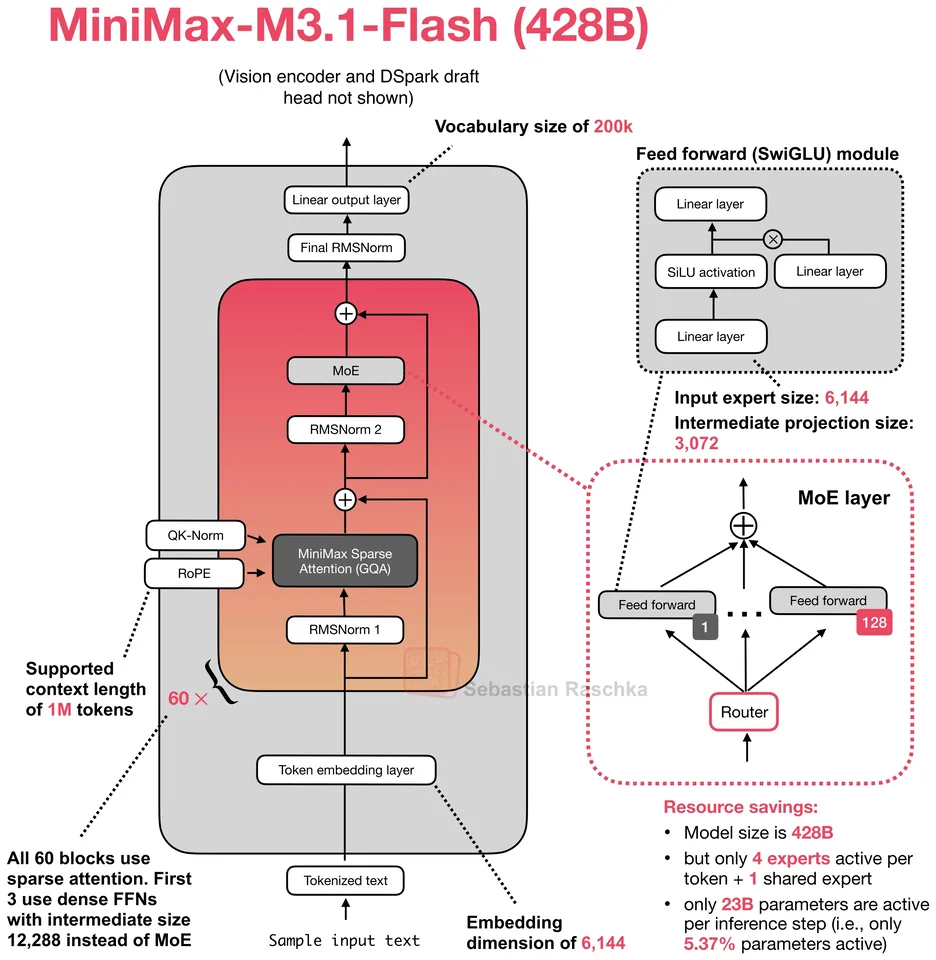
MiniMax, released 2026-10-19. Sparse MoE decoder, 428B total, 23B active, 1M context. Attention: GQA with QK-Norm and MiniMax Sparse Attention.

Z.ai, released 2025-07-28. Sparse MoE decoder, 355B total, 32B active, 128K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page