
Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.
Recurrent 7B language model that replaces self-attention with xLSTM blocks built around matrix memory.
Key detail
Stateful recurrent architecture aimed at fast long-context inference without an explicit context window.Parameters
7B
Context
—
KV / token
0 B
Parameters active per token
100%
Dense: every weight runs for every token.
KV cache per token (bf16)
0 B
Not reported for this model.
Use the ← and → keys to step through releases.
Ai2, released 2024-11-25. Dense decoder, 7B parameters, 4K context. Attention: MHA with QK-Norm.

Ai2, released 2025-11-20. Dense decoder, 7B parameters, 64K context. Attention: MHA with QK-Norm and 3:1 sliding-window/global attention.
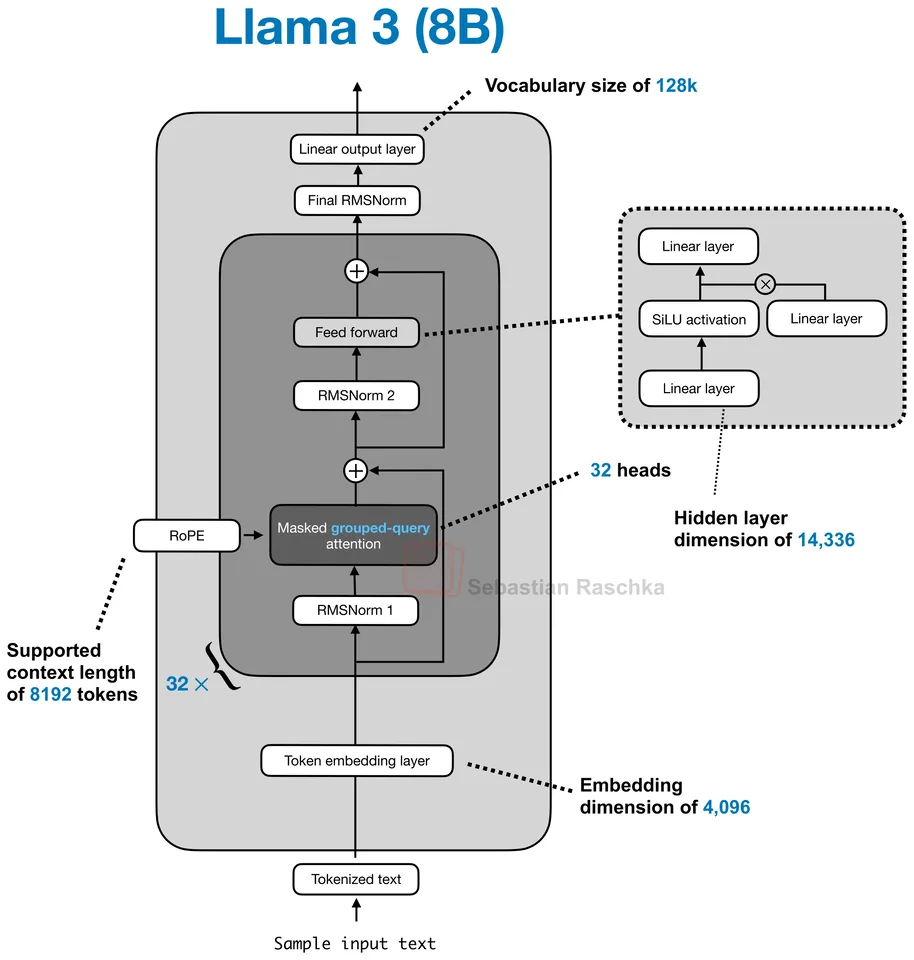
Meta, released 2024-04-18. Dense decoder, 8B parameters, 8K context. Attention: GQA with RoPE.

Alibaba Cloud, released 2025-04-28. Dense decoder, 8B parameters, 128K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page