
Poolside, released 2026-07-02. Sparse MoE decoder, 33B total, 3B active, 256K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
Poolside's open-weight agentic coding MoE uses mixed sliding-window/global attention and activates only 3B of 33B parameters per token.
Key detail
Uses per-layer query-head counts, a 512-token SWA window, sigmoid MoE routing, and one shared expert alongside the top-8 routed experts.Total params
33B
Active / token
3B
Context
128K
Parameters active per token
9.1%
3B of 33B weights run for each token.
Use the ← and → keys to step through releases.
Poolside, released 2026-07-02. Sparse MoE decoder, 33B total, 3B active, 256K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.

Poolside, released 2026-07-21. Sparse MoE decoder, 118B total, 8B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
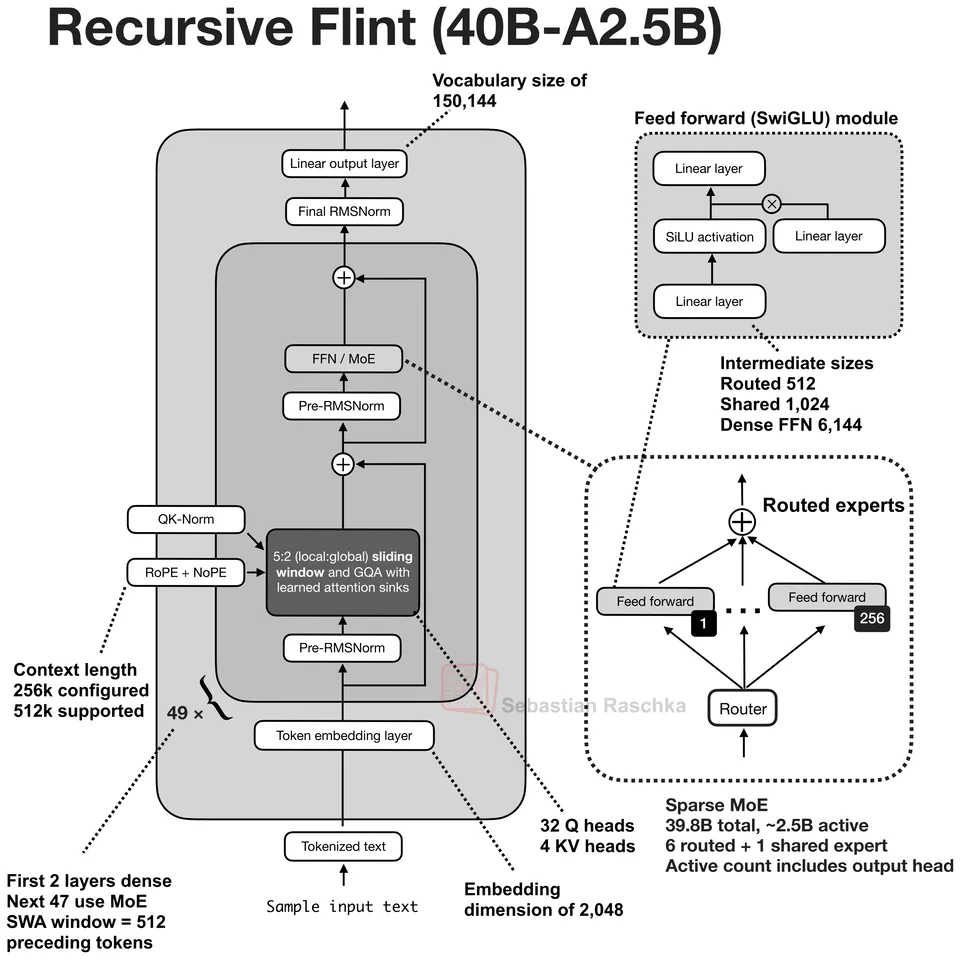
Recursive, released 2026-10-18. Sparse MoE decoder, 40B total, 2.5B active, 256K context. Attention: GQA with QK-Norm, learned attention sinks, and sliding-window/global attention.

Google, released 2026-04-02. Sparse MoE decoder, 25B total, 3.8B active, 256K context. Attention: GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention.
Jump to a model, concept or page