
Poolside, released 2026-04-28. Sparse MoE decoder, 33B total, 3B active, 128K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
Poolside's 118B sparse MoE scales the Laguna XS recipe to 48 layers and 1M context while activating about 8B parameters per token.
Key detail
Uses 256 routed experts with top-10 routing plus one shared expert, a dense first layer, and per-layer query-head counts.Total params
118B
Active / token
8B
Context
1M
Parameters active per token
6.8%
8B of 118B weights run for each token.
Use the ← and → keys to step through releases.
Poolside, released 2026-04-28. Sparse MoE decoder, 33B total, 3B active, 128K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.

Poolside, released 2026-07-02. Sparse MoE decoder, 33B total, 3B active, 256K context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
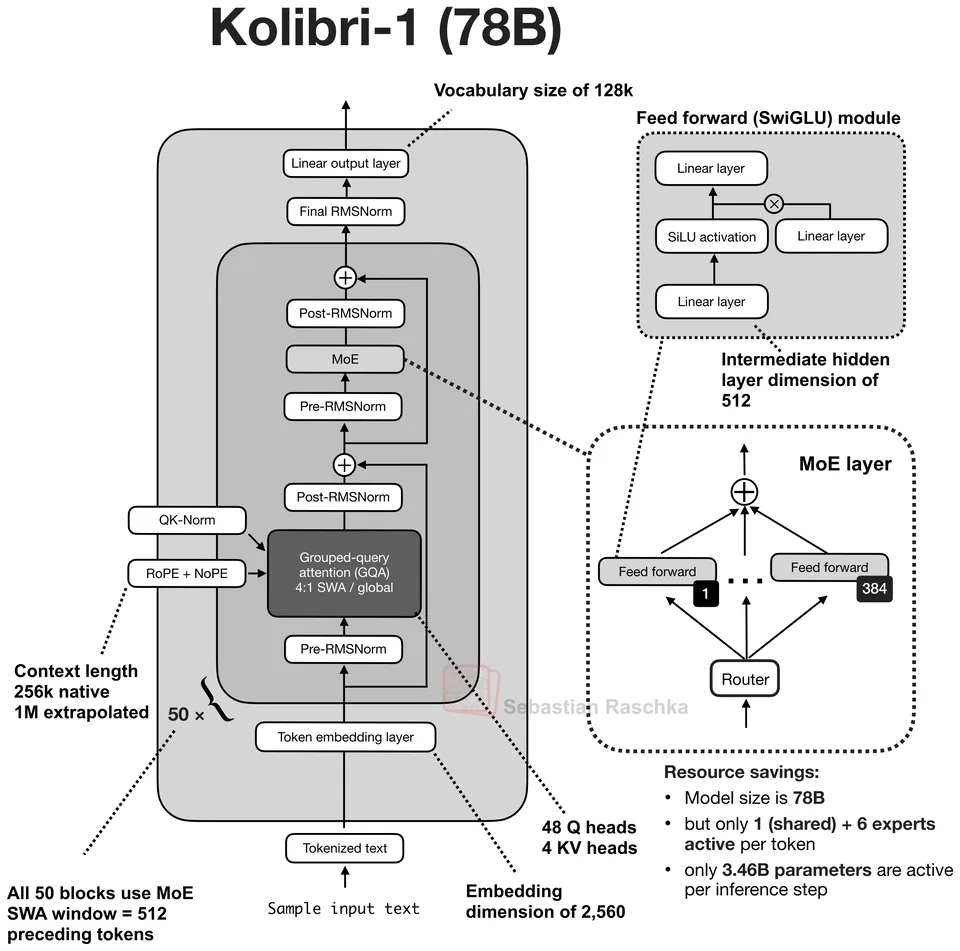
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.

MiniMax, released 2026-02-12. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page