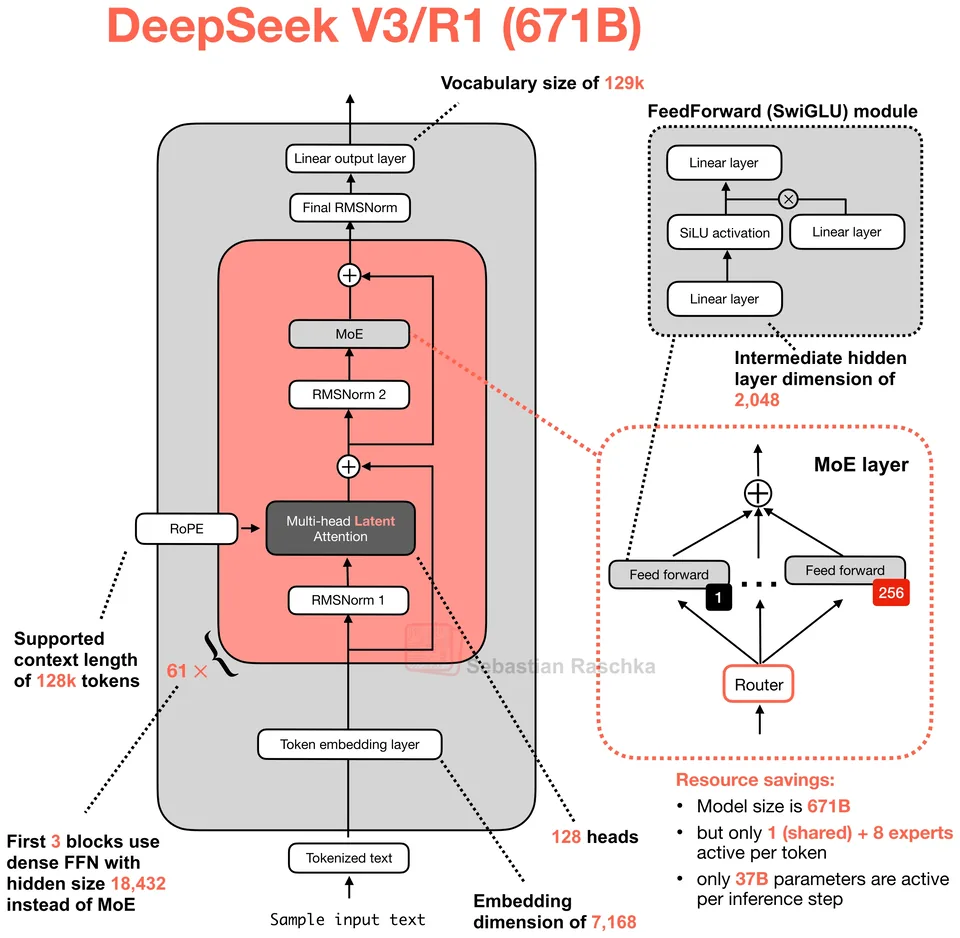
DeepSeek, released 2024-12-26. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.
Reasoning-tuned DeepSeek model built on the V3 architecture rather than a new base design.
Key detail
Architecture matches DeepSeek V3, including the MTP-1 path; the main change is the reasoning-oriented training recipe.Total params
671B
Active / token
37B
Context
128K
Parameters active per token
5.5%
37B of 671B weights run for each token.
11.4
Use the ← and → keys to step through releases.
DeepSeek, released 2024-12-26. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.

DeepSeek, released 2025-12-01. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-04-07. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.
Jump to a model, concept or page