
Poolside, released 2026-07-21. Sparse MoE decoder, 118B total, 8B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
Larger gpt-oss variant keeps the same alternating-attention recipe as the 20B model.
Key detail
Shared architectural template scaled up for OpenAI's flagship open-weight release.Total params
117B
Active / token
5.1B
Context
128K
Parameters active per token
4.4%
5.1B of 117B weights run for each token.
11.6
Use the ← and → keys to step through releases.
Poolside, released 2026-07-21. Sparse MoE decoder, 118B total, 8B active, 1M context. Attention: Gated GQA with QK-Norm and 3:1 sliding-window/global attention.
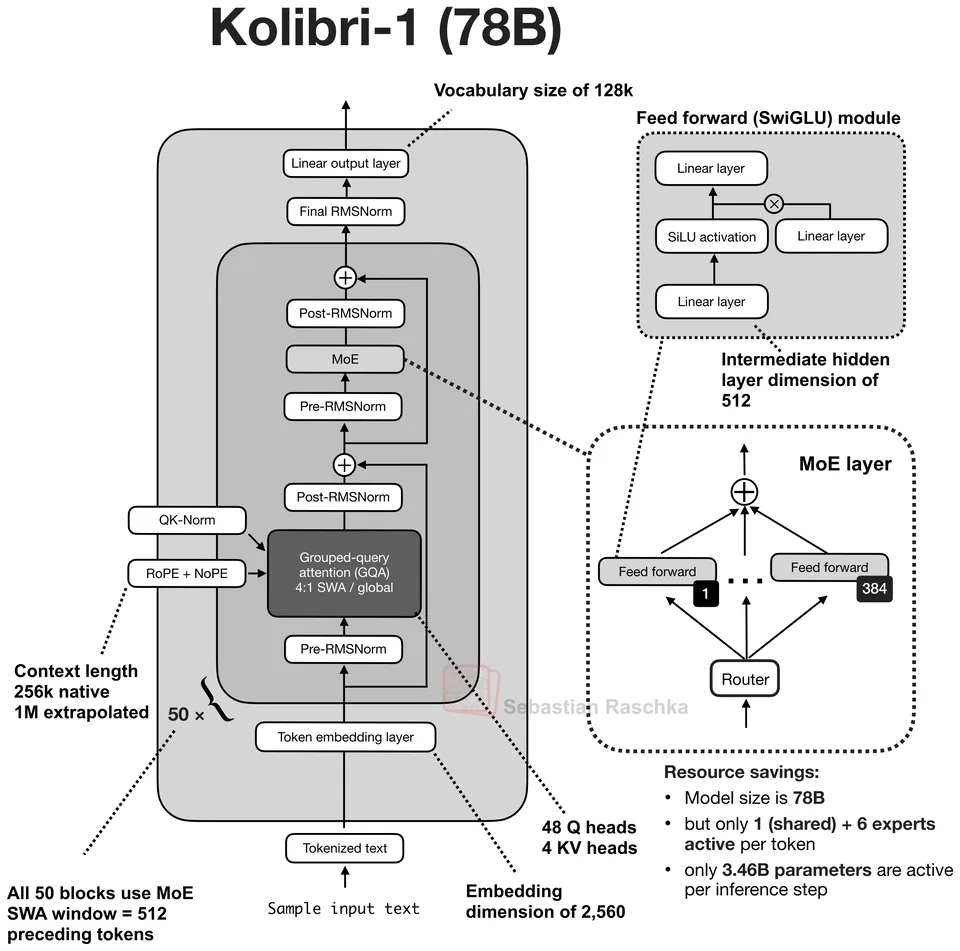
Aleph Alpha, released 2026-10-03. Sparse MoE decoder, 78B total, 3.5B active, 256K context. Attention: GQA with QK-Norm and 4:1 sliding-window/global attention.

StepFun, released 2026-02-01. Sparse MoE decoder, 196B total, 11B active, 256K context. Attention: GQA with 3:1 sliding-window attention.

MiniMax, released 2026-02-12. Sparse MoE decoder, 230B total, 10B active, 192K context. Attention: GQA with QK-Norm.
Jump to a model, concept or page