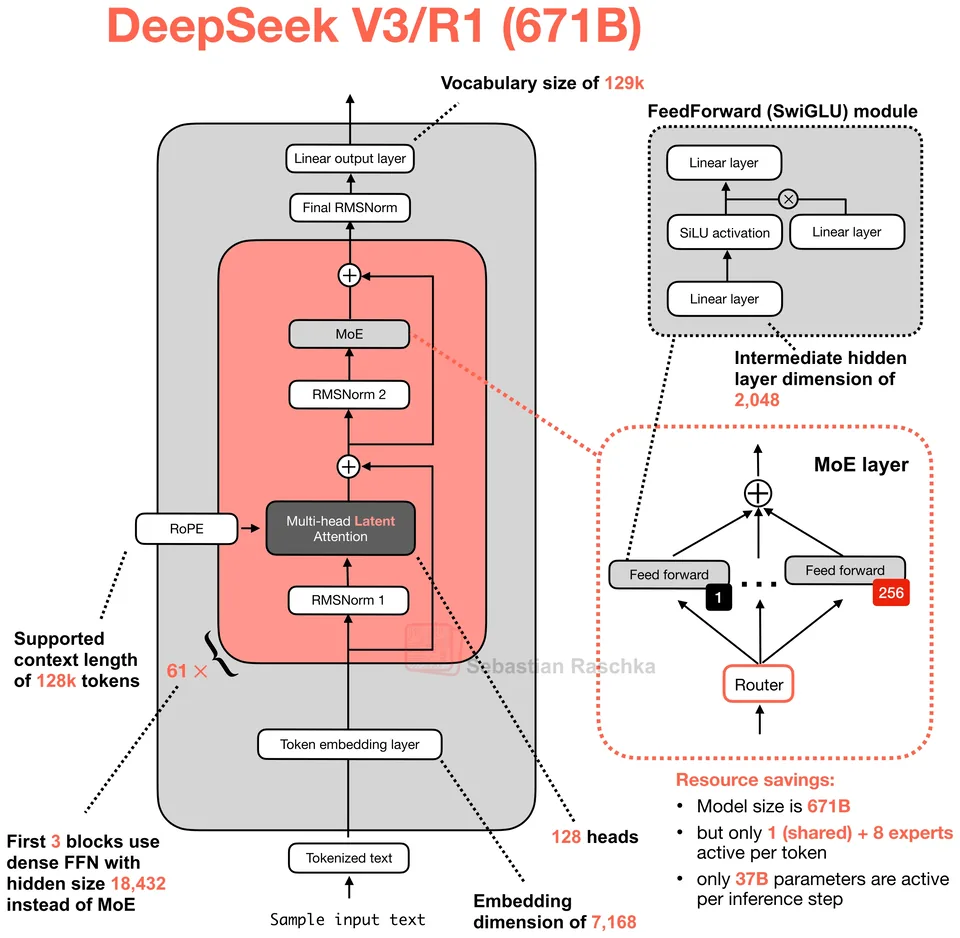
DeepSeek, released 2024-12-26. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.
Mistral's new flagship effectively adopts the DeepSeek architecture and retunes the expert sizes.
Key detail
Near-clone of DeepSeek V3 with larger experts, fewer routed experts, and multimodal support.Total params
673B
Active / token
41B
Context
256K
Parameters active per token
6.1%
41B of 673B weights run for each token.
9.3
Use the ← and → keys to step through releases.
DeepSeek, released 2024-12-26. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.
DeepSeek, released 2025-01-20. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA.

DeepSeek, released 2025-12-01. Sparse MoE decoder, 671B total, 37B active, 128K context. Attention: MLA with DeepSeek Sparse Attention.

Z.ai, released 2026-02-11. Sparse MoE decoder, 744B total, 40B active, 198K context. Attention: MLA with DeepSeek Sparse Attention.
Jump to a model, concept or page