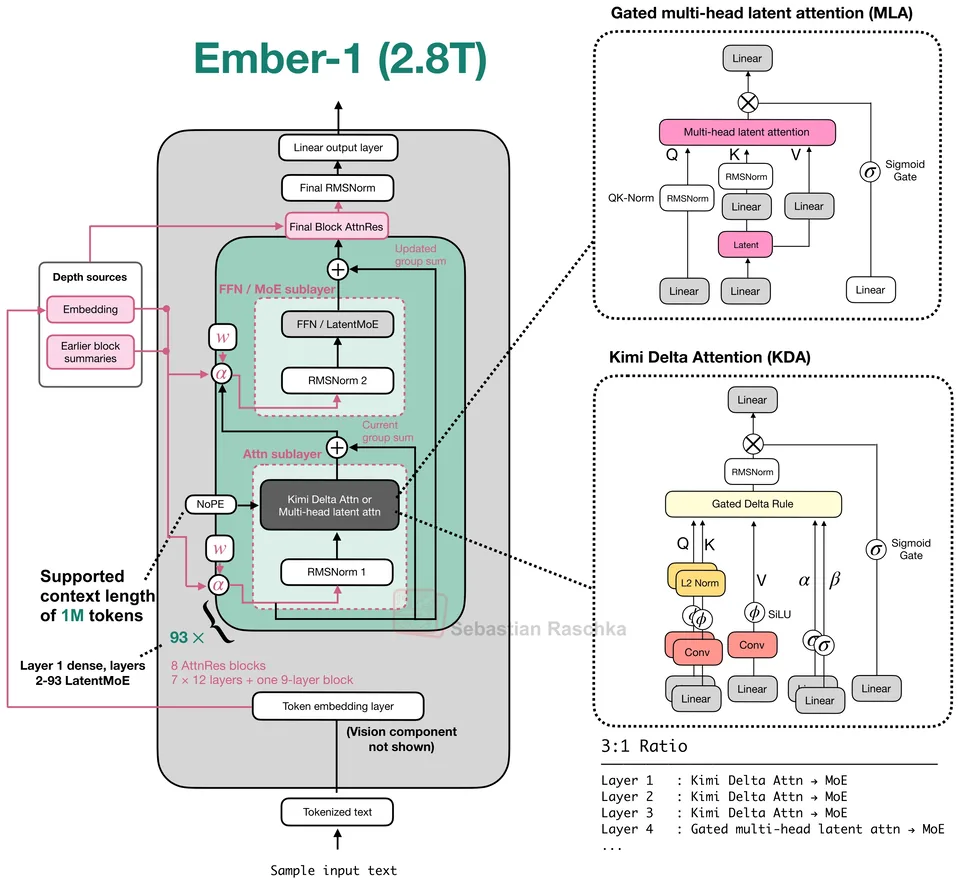
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
Residual stream · AttnRes
Learned, attention-style weights over earlier layer outputs replace the plain residual sum.
A standard residual connection adds every earlier update with weight one. AttnRes lets each layer attend over earlier layer outputs and weight their contributions.
Full and block variants exist; Kimi Linear already used the idea. Reported gains are consistent but modest, for a few percent extra training and inference cost.
Models in the atlas using AttnRes, per half-year of release.
Fireworks AI, released 2026-09-23. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.
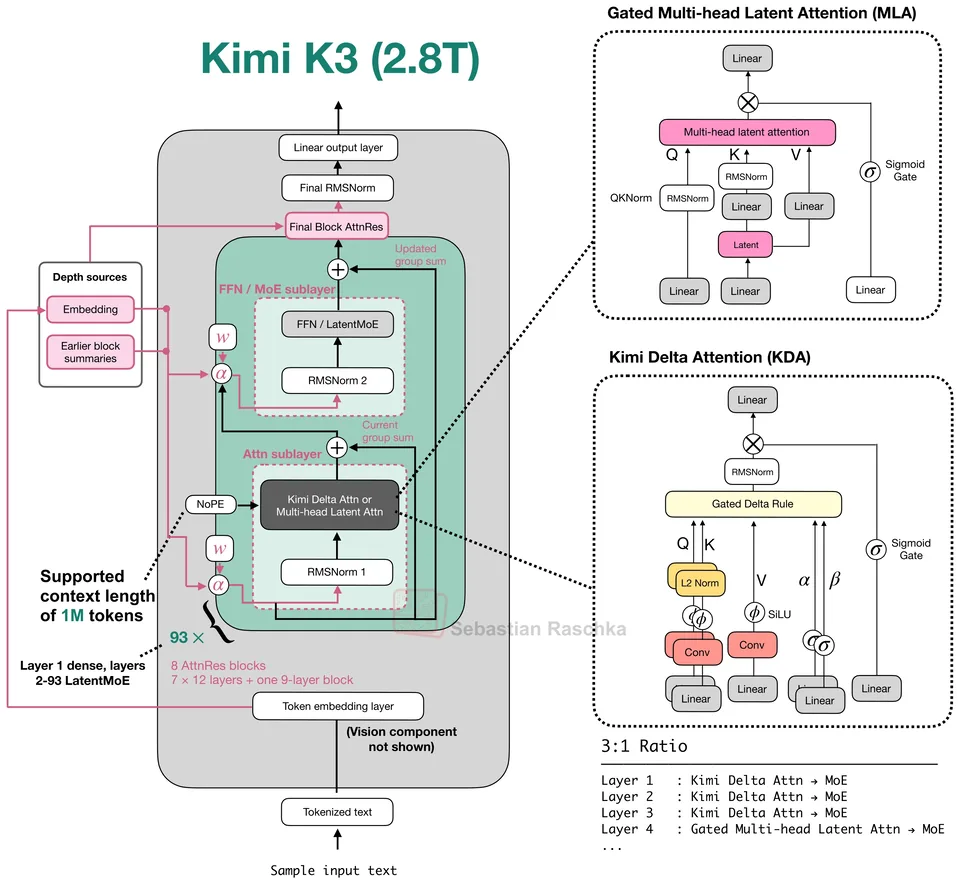
Moonshot AI, released 2026-07-27. Hybrid MoE decoder, 2.8T total, 104B active, 1M context. Attention: 3:1 Kimi Delta Attention and Gated MLA with NoPE.

Moonshot AI, released 2025-10-30. Hybrid MoE decoder, 48B total, 3B active, 1M context. Attention: 3:1 Kimi Delta Attention and MLA.
Jump to a model, concept or page